
爬虫之scrapy简单案例之猫眼
在爬虫py文件下
class TopSpider(scrapy.Spider):

    name = 'top'

    allowed_domains = ['maoyan.com']

    start_urls = ['https://maoyan.com/board/4']

    def parse(self, response):

        dds = response.xpath('//dl/dd')

        for dd in dds:

            dic = MaoyanItem()

            # dic = {}

            dic['name'] = dd.xpath('.//p[@class="name"]//text()').extract_first()

            dic['star'] = dd.xpath('.//p[@class="star"]/text()').extract_first().replace('\n', '').replace(' ', '')

            dic['releasetime'] = dd.xpath('.//p[@class="releasetime"]/text()').extract_first()

            score1 = dd.xpath('.//p[@class="score"]/i[1]/text()').extract_first()

            score2 = dd.xpath('.//p[@class="score"]/i[2]/text()').extract_first()

            dic['score'] = score1 + score2

            # 详情页

            xqy_url = 'https://maoyan.com' + dd.xpath('.//p[@class="name"]/a/@href').extract_first()

            yield scrapy.Request(xqy_url, callback=self.xqy_parse, meta={'dic': dic})

        # 翻页

        next_url = response.xpath('//a[text()="下一页"]/@href').extract_first()

        if next_url:

            url = 'https://maoyan.com/board/4' + next_url

            yield scrapy.Request(url, callback=self.parse)

    def xqy_parse(self,response):

        dic = response.meta['dic']

        dic['type'] = response.xpath('//ul/li[@class="ellipsis"][1]/text()').extract_first()

        dic['area_time'] = response.xpath('//ul/li[@class="ellipsis"][2]/text()').extract_first().replace('\n', '').replace(' ', '')

        yield dic
在items.py 文件中写入要展示的字段
class DoubanItem(scrapy.Item):

    title = scrapy.Field()

    inf = scrapy.Field()

    score = scrapy.Field()

    peo = scrapy.Field()

    brief = scrapy.Field()
在pipelines.py文件写入要打印的文本
class DoubanPipeline(object):

    def open_spider(self, spider):

        self.file = open('douban.txt', 'a', encoding='utf-8')

    def process_item(self, item, spider):

        self.file.write(str(item)+'\n')

    def close_spider(self, spider):

        self.file.close()
pipelines.py文件也可用MongoDB书写
 from pymongo import MongoClient

 class DoubanPipeline(object):

     def open_spider(self,spider):

         # self.file = open('douban.txt','a',encoding='utf8')

         self.client = MongoClient()

         self.collection = self.client['库名']['集合名']

         self.count = 0

     def process_item(self, item, spider):

         # self.file.write(str(item)+'\n')

         item['_id'] = self.count

         self.count += 1

         self.collection.insert_one(item)

         return item

     def close_spider(self, spider):

         # self.file.close()

         self.client.close()
另外,记得在setting.py文件中配置一些信息,如
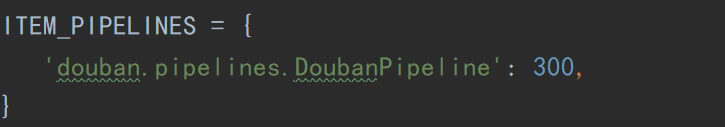
或者ROBOTS协议以及其他
爬虫之scrapy简单案例之猫眼的更多相关文章
- python自动化之爬虫原理及简单案例
[爬虫案例]动态地图里的数据如何抓取:以全国PPP综合信息平台网站为例 http://mp.weixin.qq.com/s/BXWTf5hmq8vp91ZvgaphEw [爬虫案例]动态页面的抓取! ...
- 爬虫框架Scrapy之案例二
新浪网分类资讯爬虫 爬取新浪网导航页所有下所有大类.小类.小类里的子链接,以及子链接页面的新闻内容. 效果演示图: items.py import scrapy import sys reload(s ...
- 爬虫框架Scrapy之案例三图片下载器
items.py class CoserItem(scrapy.Item): url = scrapy.Field() name = scrapy.Field() info = scrapy.Fiel ...
- 爬虫框架Scrapy之案例一
阳光热线问政平台 http://wz.sun0769.com/index.php/question/questionType?type=4 爬取投诉帖子的编号.帖子的url.帖子的标题,和帖子里的内容 ...
- 爬虫之CrawlSpider简单案例之读书网
项目名py文件下 class DsSpider(CrawlSpider): name = 'ds' allowed_domains = ['dushu.com'] start_urls = ['htt ...
- scrapy爬虫学习系列二:scrapy简单爬虫样例学习
系列文章列表: scrapy爬虫学习系列一:scrapy爬虫环境的准备: http://www.cnblogs.com/zhaojiedi1992/p/zhaojiedi_python_00 ...
- Python爬虫框架--Scrapy安装以及简单实用
scrapy框架 框架 -具有很多功能且具有很强通用性的一个项目模板 环境安装: Linux: pip3 install scrapy Windows: ...
- Python 爬虫之Scrapy框架
Scrapy框架架构 Scrapy框架介绍: 写一个爬虫,需要做很多的事情.比如:发送网络请求.数据解析.数据存储.反反爬虫机制(更换ip代理.设置请求头等).异步请求等.这些工作如果每次都要自己从零 ...
- Python逆向爬虫之scrapy框架,非常详细
爬虫系列目录 目录 Python逆向爬虫之scrapy框架,非常详细 一.爬虫入门 1.1 定义需求 1.2 需求分析 1.2.1 下载某个页面上所有的图片 1.2.2 分页 1.2.3 进行下载图片 ...
随机推荐
- 正则表达式在Java中使用
正则表达式 定义 用一组特殊的字符来描述一组字符串的格式 用于验证字符串是否满足格式 不关心字符串的内容是否有效 1. 基本正则表达式所谓正则表达式就是使用一系列预定义的特殊字符来描述一个字符串的格式 ...
- 自动下载zar配置管理
maven 下载: https://maven.apache.org/ 官网 download 下载:Binary zip archive apache-maven-3.6.2-bin.zip 免安装 ...
- Http协议Content-Length详解
前言 http协议是互联网中最重要的协议之一,虽然看上去很简单,但是实际中经常遇到问题,我们就已经遇到好几次了.有长连接相关的,有报文解析相关的.对http协议不能一知半解,必须透彻理解才行.本文通过 ...
- 从0开始学FreeRTOS-(创建任务)-2
# 补充 开始今天的内容之前,先补充一下上篇文章[从单片机到操作系统-1](https://jiejietop.gitee.io/freertos-1/)的一点点遗漏的知识点. ```js BaseT ...
- Flask中的数据连接池
pymsql链接数据库 import pymysql conn = pymysql.connect(host='127.0.0.1', port=3306, user='root', passwd=' ...
- [Mathematics][MIT 18.02]Detailed discussions about 2-D and 3-D integral and their connections
Since it is just a sort of discussion, I will just give the formula and condition without proving th ...
- msf利用- windows内核提权漏洞
windows内核提权漏洞 环境: Kali Linux(攻击机) 192.168.190.141 Windows2003SP2(靶机) 192.168.190.147 0x01寻找可利用的exp 实 ...
- HTML 元素居中的方法
网址:http://www.cnblogs.com/asqq/archive/2012/04/09/2438745.html 1. 元素的定位的方法选择 :absolute . 2. 给定元素的宽和高 ...
- Java自动化测试框架-04 - TestNG之Test Method篇 - 道法自然,法力无边(详细教程)
简介 按照上一篇的计划,这一篇给小伙伴们分享一下测试方法. 一.设置参数 测试方法是可以带有参数的.每个测试方法都可以带有任意数量的参数,并且可以通过使用TestNG的@Parameters向方法传递 ...
- Logstash 入门
一.简介 Logstash 是开源的服务器端数据处理管道,支持从不同来源采集数据,装换数据,并将数据发送到不同的存储库中. Logstash 项目诞生于 2009 年 8 月 2 日.其作者是世界著名 ...