
xgboost调参
The overall parameters have been divided into 3 categories by XGBoost authors:
- General Parameters: Guide the overall functioning
- Booster Parameters: Guide the individual booster (tree/regression) at each step
- Learning Task Parameters: Guide the optimization performed
general parameters
- booster [default=gbtree](基分类器类型)
- Select the type of model to run at each iteration. It has 2 options:
- gbtree: tree-based models
- gblinear: linear models
- Select the type of model to run at each iteration. It has 2 options:
- silent [default=0]:
- Silent mode is activated if set to 1, i.e. no running messages will be printed.
- It’s generally good to keep it 0 as the messages might help in understanding the model.
- nthread [default to maximum number of threads available if not set]
- This is used for parallel processing and number of cores in the system should be entered
- If you wish to run on all cores, value should not be entered and algorithm will detect automatically
booster parameters
Though there are 2 types of boosters, I’ll consider only tree booster here because it always outperforms the linear booster and thus the later is rarely used.
- eta [default=0.3](学习率,非常重要的参数)
- Analogous to learning rate in GBM
- Makes the model more robust by shrinking the weights on each step
- Typical final values to be used: 0.01-0.2
- min_child_weight [default=1](控制过拟合,如果太大会导致欠拟合)
- Defines the minimum sum of weights of all observations required in a child.(叶子节点中实例数 * 叶子节点的score)
- This is similar to min_child_leaf in GBM but not exactly. This refers to min “sum of weights” of observations while GBM has min “number of observations”.
- Used to control over-fitting. Higher values prevent a model from learning relations which might be highly specific to the particular sample selected for a tree.
- Too high values can lead to under-fitting hence, it should be tuned using CV.
- max_depth [default=6](最大深度,一般增加特征,深度变小)
- The maximum depth of a tree, same as GBM.
- Used to control over-fitting as higher depth will allow model to learn relations very specific to a particular sample.
- Should be tuned using CV.
- Typical values: 3-10
- max_leaf_nodes
- The maximum number of terminal nodes or leaves in a tree.
- Can be defined in place of max_depth. Since binary trees are created, a depth of ‘n’ would produce a maximum of 2^n leaves.
- If this is defined, GBM will ignore max_depth.
- gamma [default=0](分裂所需的最小损失减少值)
- A node is split only when the resulting split gives a positive reduction in the loss function. Gamma specifies the minimum loss reduction required to make a split.
- Makes the algorithm conservative. The values can vary depending on the loss function and should be tuned.
- max_delta_step [default=0]
- In maximum delta step we allow each tree’s weight estimation to be. If the value is set to 0, it means there is no constraint. If it is set to a positive value, it can help making the update step more conservative.
- Usually this parameter is not needed, but it might help in logistic regression when class is extremely imbalanced.
- This is generally not used but you can explore further if you wish.
- subsample [default=1](样本采样的比例,防止过拟合)
- Same as the subsample of GBM. Denotes the fraction of observations to be randomly samples for each tree.
- Lower values make the algorithm more conservative and prevents overfitting but too small values might lead to under-fitting.
- Typical values: 0.5-1
- colsample_bytree [default=1](特征采样的比例,防止过拟合)
- Similar to max_features in GBM. Denotes the fraction of columns to be randomly samples for each tree.
- Typical values: 0.5-1
- colsample_bylevel [default=1]
- Denotes the subsample ratio of columns for each split, in each level.
- I don’t use this often because subsample and colsample_bytree will do the job for you. but you can explore further if you feel so.
- lambda [default=1](L2正则化系数)
- L2 regularization term on weights (正则化系数)(analogous to Ridge regression)
- This used to handle the regularization part of XGBoost. Though many data scientists don’t use it often, it should be explored to reduce overfitting.
- alpha [default=0](L1正则化系数)
- L1 regularization term on weight (analogous to Lasso regression)
- Can be used in case of very high dimensionality so that the algorithm runs faster when implemented
- scale_pos_weight [default=1](正例的权重,如果使用对数损失,默认1即可)
- A value greater than 0 should be used in case of high class imbalance as it helps in faster convergence.
learning task parameters
These parameters are used to define the optimization objective the metric to be calculated at each step.
- objective [default=reg:linear](损失函数)
- This defines the loss function to be minimized. Mostly used values are:
- binary:logistic –logistic regression for binary classification, returns predicted probability (not class)
- multi:softmax –multiclass classification using the softmax objective, returns predicted class (not probabilities)
- you also need to set an additional num_class (number of classes) parameter defining the number of unique classes
- multi:softprob –same as softmax, but returns predicted probability of each data point belonging to each class.
- This defines the loss function to be minimized. Mostly used values are:
- eval_metric [ default according to objective ]
- The metric to be used for validation data.
- The default values are rmse for regression and error for classification.
- Typical values are:
- rmse – root mean square error
- mae – mean absolute error
- logloss – negative log-likelihood
- error – Binary classification error rate (0.5 threshold)
- merror – Multiclass classification error rate
- mlogloss – Multiclass logloss
- auc: Area under the curve
- seed [default=0](随机数种子,可指定多个不同的种子,训练不同的模型,然后ensemble)
- The random number seed.
- Can be used for generating reproducible results and also for parameter tuning.
General Approach for Parameter Tuning
- Choose a relatively high learning rate. Generally a learning rate of 0.1 works but somewhere between 0.05 to 0.3 should work for different problems. Determine the optimum number of trees for this learning rate. XGBoost has a very useful function called as “cv” which performs cross-validation at each boosting iteration and thus returns the optimum number of trees required.
- Tune tree-specific parameters ( max_depth, min_child_weight, gamma, subsample, colsample_bytree) for decided learning rate and number of trees. Note that we can choose different parameters to define a tree and I’ll take up an example here.
- Tune regularization parameters (lambda, alpha) for xgboost which can help reduce model complexity and enhance performance.
- Lower the learning rate and decide the optimal parameters .
先初始化一个比较大的学习率,然后利用xgboost自带的cv调整树的数目,其次调整树相关的参数,包括深度、最小孩子节点权重等,最后调整学习率
import pandas as pd

import numpy as np

import xgboost as xgb

from xgboost.sklearn import XGBClassifier

from sklearn import cross_validation, metrics

from sklearn.grid_search import GridSearchCV

'''

xgb is the direct xgboost library.

XGBClassifier is an sklearn wrapper for XGBoost.This allows us to use sklearn's Grid Search with

parallel processing .

'''

train = pd.read_csv("train_modified.csv")

target = "Disbursed"

IDcol = "ID"

def modelfit(alg, dtrain, predictors, useTrainCV = True, cv_folds = 5, early_stopping_rounds = 50):

        if useTrainCV:

                xgb_param = alg.get_xgb_params()

                xgtrain = xgb.DMatrix(dtrain[predictors].values, label = dtrain[target].values)

                cvresult = xgb.cv(xgb_param, xgtrain, num_boost_round = alg.get_params()['n_estimators'],

                        nfold = cv_folds, metrics = 'auc', early_stopping_rounds = early_stopping_rounds)

                alg.set_params(n_estimators = cvresult.shape[0])

        alg.fit(dtrain[predictors], dtrain['Disbursed'], eval_metric = 'auc')

        dtrain_predictions = alg.predict(dtrain[predictors])

        dtrain_predprob = alg.predict_proba(dtrain[predictors])[:,1]

        print "\nModel Report"

        print "Accuracy : %.4g" % metrics.accuracy_score(dtrain['Disbursed'].values, dtrain_predictions)

        print "AUC Score (Train): %f" % metrics.roc_auc_score(dtrain['Disbursed'], dtrain_predprob)

predictors = [x for x in train.columns if x not in [target, IDcol]]

xgb1 = XGBClassifier(learning_rate = 0.1, n_estimators = 1000, max_depth = 5, min_child_weight = 1, gamma = 0, subsample = 0.8,

        colsample_bytree = 0.8, objective = 'binary:logistic', nthread = 4, scale_pos_weight = 1, seed = 27)

modelfit(xgb1, train, predictors)
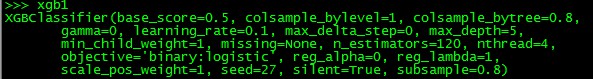
由上图可知,在给定learning_rate = 0.1的情况下,n_estimators = 120是最佳的树的个数
参考:
https://www.analyticsvidhya.com/blog/2016/03/complete-guide-parameter-tuning-xgboost-with-codes-python/
http://xgboost.readthedocs.io/en/latest/parameter.html#general-parameters
https://github.com/dmlc/xgboost/tree/master/demo/guide-python
http://xgboost.readthedocs.io/en/latest/python/python_api.html
xgboost调参的更多相关文章
- Xgboost调参总结
一.参数速查 参数分为三类: 通用参数:宏观函数控制. Booster参数:控制每一步的booster(tree/regression). 学习目标参数:控制训练目标的表现. 二.回归 from xg ...
- xgboost 调参参考
XGBoost的参数 XGBoost的作者把所有的参数分成了三类: 1.通用参数:宏观函数控制. 2.Booster参数:控制每一步的booster(tree/regression). 3.学习目标参 ...
- 机器学习--Xgboost调参
Xgboost参数 'booster':'gbtree', 'objective': 'multi:softmax', 多分类的问题 'num_class':10, 类别数,与 multisoftma ...
- 【转载】XGBoost调参
General Parameters: Guide the overall functioning Booster Parameters: Guide the individual booster ( ...
- xgboost 调参 !
https://jessesw.com/XG-Boost/ http://blog.csdn.net/u010414589/article/details/51153310
- xgboost调参过程
from http://blog.csdn.net/han_xiaoyang/article/details/52665396
- xgboost使用调参
欢迎关注博主主页,学习python视频资源 https://blog.csdn.net/q383700092/article/details/53763328 调参后结果非常理想 from sklea ...
- XGBoost和LightGBM的参数以及调参
一.XGBoost参数解释 XGBoost的参数一共分为三类: 通用参数:宏观函数控制. Booster参数:控制每一步的booster(tree/regression).booster参数一般可以调 ...
- 【新人赛】阿里云恶意程序检测 -- 实践记录10.27 - TF-IDF模型调参 / 数据可视化
TF-IDF模型调参 1. 调TfidfVectorizer的参数 ngram_range, min_df, max_df: 上一篇博客调了ngram_range这个参数,得出了ngram_range ...
随机推荐
- Python 模块和包的概念
模块&包(* * * * *) 模块(modue)的概念: 在计算机程序的开发过程中,随着程序代码越写越多,在一个文件里代码就会越来越长,越来越不容易维护. 为了编写可维护的代码,我们把很多函 ...
- (转)iOS完成学习路线
转自 MJ大神博客 原文地址http://blog.csdn.net/q199109106q/article/details/8596506 晚特地花时间整理出了iOS的完整学习路线图,希望对大家有帮 ...
- PAT Basic 1041
1041 考试座位号 每个 PAT 考生在参加考试时都会被分配两个座位号,一个是试机座位,一个是考试座位.正常情况下,考生在入场时先得到试机座位号码,入座进入试机状态后,系统会显示该考生的考试座位号码 ...
- BRVAH(让RecyclerView变得更高效) (3)
本文来自网易云社区 作者:吴思博 3 实现列表加载动画效果 3.1默认动画 我们只需将自建的 adapter 继承它对应满足需求的 Adapter,然后在 Activity 中实例化,通过ope ...
- Replication and Triggers
参考官网:https://dev.mysql.com/doc/refman/5.7/en/replication-features-triggers.html 需要了解复制和触发器关系的背景: 程序变 ...
- Datatable 生成json格式
public string GetJsonFromDataTable(DataTable dt, int total, bool ShowFooter, string fields, string i ...
- NBOJv2——Problem 1002: 蛤玮的财宝(多线程DP)
Problem 1002: 蛤玮的财宝 Time Limits: 1000 MS Memory Limits: 65536 KB 64-bit interger IO format: %ll ...
- K-D tree入门
久仰K-D tree大名已久,终于在合适的时候遇见了合适的水题入了坑入了门 K-D tree是什么 K-D tree是什么? 按名字上翻译来就是K维的树,就是一个用来维护K维空间的点的平衡二叉树 K- ...
- 阿里 AndFix 热修复框架简介
阿里AndFix热修复框架简介 热修复原理: Android的类加载机制 Android的类加载器分为两种,PathClassLoader和DexClassLoader,两者都继承自BaseDexCl ...
- bzoj3874&2832 [Ahoi2014]宅男计划 模拟退火,三分
[Ahoi2014&Jsoi2014]宅男计划 Time Limit: 1 Sec Memory Limit: 256 MBSubmit: 962 Solved: 371[Submit][ ...