
大数据实战手册-开发篇之spark实战案例:实时日志分析
2.6 spark实战案例:实时日志分析
- 2.6.1 交互流程图
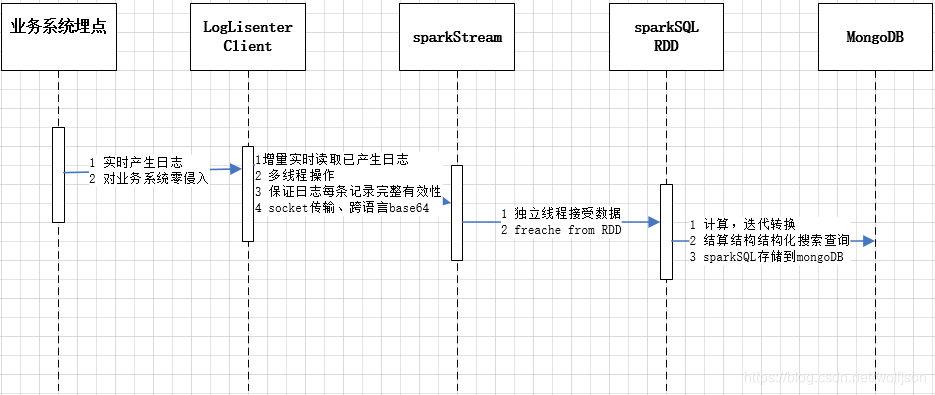
- 2.6.2 客户端监听器(java)
@SuppressWarnings("static-access")

	private void handleSocket() {

		lock.lock();

		Writer writer = null;

		RandomAccessFile raf = null;

		try {

			File file = new File(filepath);

			raf = new RandomAccessFile(file, "r");

			raf.seek(pointer);

			writer = new OutputStreamWriter(socket.getOutputStream(), "UTF-8");

			String line = null;

			while ((line = raf.readLine()) != null) {

				if (Strings.isBlank(line)) {

					continue;

				}

				line = new String(line.getBytes("ISO-8859-1"), "UTF-8");

				writer.write(line.concat("\n"));

				writer.flush();

				logger.info("线程:{}----起始位置:{}----读取文件\n{} :",Thread.currentThread().getName(), pointer, line);

				pointer = raf.getFilePointer();

			}

			Thread.currentThread().sleep(2000);

		} catch (Exception e) {

			logger.error(e.getMessage());

			e.printStackTrace();

		} finally {

			lock.unlock();

			fclose(writer, raf);

		}

	}
- 2.6.3 sparkStream实时数据接收(python)
conf = SparkConf()

conf.setAppName("HIS实时日志分析")

conf.setMaster('yarn') # spark standalone

conf.set('spark.executor.instances', 8) # cluster on yarn

conf.set('spark.executor.memory', '1g')

conf.set('spark.executor.cores', '1')

# conf.set('spark.cores.max', '2')

# conf.set('spark.logConf', True)

conf.set('spark.streaming.blockInterval', 1000*4)  # restart receiver interval

sc = SparkContext(conf = conf)

sc.setLogLevel('ERROR')

sc.setCheckpointDir('hdfs://hadoop01:9000/hadoop/upload/checkpoint/')

ssc = StreamingContext(sc, 30)  # time interval at which splits streaming data into block

lines = ssc.socketTextStream(str(ip), int(port))

# lines.pprint()

lines.foreachRDD(requestLog)

lines.foreachRDD(errorLog)

ssc.start()

ssc.awaitTermination()
- 2.6.4 sparklSQL、RDD结算、结构化搜索、结构存储mongoDB(python)
 def getSparkSessionInstance(sparkConf):

    '''

    :@desc 多个RDD全局共享sparksession

     .config("spark.mongodb.input.uri", "mongodb://127.0.0.1/test.coll") \

     .config("spark.mongodb.output.uri", "mongodb://adxkj:123456@192.168.0.252:27017/") \

    :param sparkConf:

    :return:

    '''

    if ('sparkSessionSingletonInstance' not in globals()):

        globals()['sparkSessionSingletonInstance'] = SparkSession \

            .builder \

            .config(conf=sparkConf) \

            .getOrCreate()

    return globals()['sparkSessionSingletonInstance']

def timeFomate(x):

    '''

    :@desc 处理时间

    :param x:

    :return:

    '''

    if not isinstance(x, list):

        return None

    # filter microsenconds

    x.insert(0, ' '.join(x[0:2]))

    x.pop(1)

    x.pop(1)

    # filter '[]'

    rx = re.compile('([\[\]\',])')

    # text = rx.sub(r'\\\1', text)

    x = [rx.sub(r'', x[i]) for i in range(len(x))]

    # string to time

    x[0] = x[0][: x[0].find('.')]

    x[0] = ''.join(x[0])

    x[0] = datetime.strptime(x[0], '%Y-%m-%d %H:%M:%S')

    return x

def sqlMysql(sqlResult, table, url="jdbc:mysql://192.168.0.252:3306/hisLog", user='root', password=""):

    '''

    :@desc sql结果保存

    :param sqlResult:

    :param table:

    :param url:

    :param user:

    :param password:

    :return:

    '''

    try:

        sqlResult.write \

            .mode('append') \

            .format("jdbc") \

            .option("url", url) \

            .option("dbtable", table) \

            .option("user", user) \

            .option("password", password) \

            .save()

    except:

        excType, excValue, excTraceback = sys.exc_info()

        traceback.print_exception(excType, excValue, excTraceback, limit=3)

        # print(excValue)

        # traceback.print_tb(excTraceback)

def sqlMongodb(sqlResult, table):

    '''

    :@desc sql结果保存

    :param sqlResult:

    :param table:

    :param url:

    :param user:

    :param password:

    :return:

    '''

    try:

        sqlResult.\

            write.\

            format("com.mongodb.spark.sql.DefaultSource"). \

            options(uri="mongodb://adxkj:123456@192.168.0.252:27017/hislog",

                    database="hislog", collection=table, user="adxkj", password="123456").\

            mode("append").\

            save()

    except:

        excType, excValue, excTraceback = sys.exc_info()

        traceback.print_exception(excType, excValue, excTraceback, limit=3)

        # print(excValue)

        # traceback.print_tb(excTraceback)

def decodeStr(x) :

    '''

    :@desc base64解码

    :param x:

    :return:

    '''

    try:

        if x[9].strip() != '' :

            x[9] = base64.b64decode(x[9].encode("utf-8")).decode("utf-8")

            # x[9] = x[9][:5000] #mysql

        if x[11].strip() != '':

            x[11] = base64.b64decode(x[11].encode("utf-8")).decode("utf-8")

            # x[11] = x[11][:5000] #mysql

        if len(x) > 12 and x[12].strip() != '':

            x[12] = base64.b64decode(x[12].encode("utf-8")).decode("utf-8")

    except Exception as e:

        print("不能解码:", x, e)

    return x

def analyMod(x) :

    '''

    :@desc 通过uri匹配模块

    :param x:

    :return:

    '''

    if x[6].strip() == ' ':

        return None

    hasMatch = False

    for k, v in URI_MODULES.items() :

        if x[6].strip().startswith('/' + k) :

            hasMatch = True

            x.append(v)

    if not hasMatch:

        x.append('公共模块')

    return x

def requestLog(time, rdd):

    '''

    :@desc 请求日志分析

    :param time:

    :param rdd:

    :return:

    '''

    logging.info("+++++handle request log:length:%d,获取内容:++++++++++" % (rdd.count()))

    if rdd.isEmpty():

        return None

    logging.info("++++++++++++++++++++++处理requestLog+++++++++++++++++++++++++++++++")

    reqrdd = rdd.map(lambda x: x.split(' ')).\

        filter(lambda x: len(x) > 12 and x[4].find('http-nio-') > 0 and x[2].strip() == 'INFO').\

        filter(lambda x: x[8].strip().upper().startswith('POST') or x[8].strip().upper().startswith('GET')).\

        map(timeFomate).\

        map(decodeStr).\

        map(analyMod)

    reqrdd.cache()

    reqrdd.checkpoint()  # checkpoint先cache避免计算两次,以前的rdd销毁

    sqlRdd = reqrdd.map(lambda x: Row(time=x[0], level=x[1], clz=x[2], thread=x[3], user=x[4], depart=x[5],

                          uri=x[6], method=x[7], ip=x[8], request=x[9], oplen=x[10],

                          respone=x[11], mod=x[12]))

    # rdd持久化,降低内存消耗, cache onliy for StorageLevel.MEMORY_ONLY

    # reqrdd.persist(storageLevel=StorageLevel.MEMORY_AND_DISK_SER)

    if reqrdd.isEmpty():

        return None

    spark = getSparkSessionInstance(rdd.context.getConf())

    df = spark.createDataFrame(sqlRdd)

    df.createOrReplaceTempView(REQUEST_TABLE)

    # 结构化后再分析

    sqlresult = spark.sql("SELECT * FROM " + REQUEST_TABLE)

    sqlresult.show()

    # 保存

    sqlMongodb(sqlresult, REQUEST_TABLE)

def errorLog(time, rdd):

    '''

    :@desc 错误日志分析

    :param time:

    :param rdd:

    :return:

    '''

    logging.info("+++++handle error log:length:%d,获取内容:++++++++++" % (rdd.count()))

    if rdd.isEmpty():

        return None

    logging.info("++++++++++++++++++++++处理errorLog+++++++++++++++++++++++++++++++")

    errorrdd = rdd.map(lambda x: x.split(' ')). \

        filter(lambda x: len(x) > 13 and x[2].strip().upper().startswith('ERROR')). \

        map(timeFomate). \

        map(decodeStr). \

        map(analyMod). \

        map(lambda x: Row(time=x[0], level=x[1], clz=x[2], thread=x[3], user=x[4], depart=x[5],

                          uri=x[6], method=x[7], ip=x[8], request=x[9], oplen=x[10],

                          respone=x[11], stack=x[12], mod=x[13]))

    # rdd持久化,降低内存消耗

    errorrdd.persist(storageLevel=StorageLevel.MEMORY_AND_DISK_SER)

    if errorrdd.isEmpty():

        return None

    spark = getSparkSessionInstance(rdd.context.getConf())

    df = spark.createDataFrame(errorrdd)

    df.createOrReplaceTempView(ERROR_TABLE)

    # 结构化后再分析

    sqlresult = spark.sql("SELECT * FROM " + ERROR_TABLE)

    sqlresult.show()

    # 保存

    sqlMongodb(sqlresult, ERROR_TABLE)
备注:需要完整代码请联系作者@狼
大数据实战手册-开发篇之spark实战案例:实时日志分析的更多相关文章
- 苏宁基于Spark Streaming的实时日志分析系统实践 Spark Streaming 在数据平台日志解析功能的应用
https://mp.weixin.qq.com/s/KPTM02-ICt72_7ZdRZIHBA 苏宁基于Spark Streaming的实时日志分析系统实践 原创: AI+落地实践 AI前线 20 ...
- Spark 实践——基于 Spark Streaming 的实时日志分析系统
本文基于<Spark 最佳实践>第6章 Spark 流式计算. 我们知道网站用户访问流量是不间断的,基于网站的访问日志,即 Web log 分析是典型的流式实时计算应用场景.比如百度统计, ...
- Java,面试题,简历,Linux,大数据,常用开发工具类,API文档,电子书,各种思维导图资源,百度网盘资源,BBS论坛系统 ERP管理系统 OA办公自动化管理系统 车辆管理系统 各种后台管理系统
Java,面试题,简历,Linux,大数据,常用开发工具类,API文档,电子书,各种思维导图资源,百度网盘资源BBS论坛系统 ERP管理系统 OA办公自动化管理系统 车辆管理系统 家庭理财系统 各种后 ...
- GIS+=地理信息+行业+大数据——基于云环境流处理平台下的实时交通创新型app
应用程序已经是近代的一个最重要的IT创新.应用程序是连接用户和数据之间的桥梁,提供即时訪问信息是最方便且呈现的方式也是easy理解的和令人惬意的. 然而,app开发人员.尤其是后端平台能力,一直在努力 ...
- Spark SQL慕课网日志分析(1)--系列软件(单机)安装配置使用
来源: 慕课网 Spark SQL慕课网日志分析_大数据实战 目标: spark系列软件的伪分布式的安装.配置.编译 spark的使用 系统: mac 10.13.3 /ubuntu 16.06,两个 ...
- 大数据项目实践:基于hadoop+spark+mongodb+mysql+c#开发医院临床知识库系统
一.前言 从20世纪90年代数字化医院概念提出到至今的20多年时间,数字化医院(Digital Hospital)在国内各大医院飞速的普及推广发展,并取得骄人成绩.不但有数字化医院管理信息系统(HIS ...
- 大数据核心知识点:Hbase、Spark、Hive、MapReduce概念理解,特点及机制
今天,上海尚学堂大数据培训班毕业的一位学生去参加易普软件公司面试,应聘的职位是大数据开发.面试官问了他10个问题,主要集中在Hbase.Spark.Hive和MapReduce上,基础概念.特点.应用 ...
- 大数据的前世今生【Hadoop、Spark】
一.大数据简介 大数据是一个很热门的话题,但它是什么时候开始兴起的呢? 大数据[big data]这个词最早在UNIX用户协会的会议上被使用,来自SGI公司的科学家在其文章“大数据与下一代基础架构 ...
- 了解大数据的技术生态系统 Hadoop,hive,spark(转载)
首先给出原文链接: 原文链接 大数据本身是一个很宽泛的概念,Hadoop生态圈(或者泛生态圈)基本上都是为了处理超过单机尺度的数据处理而诞生的.你能够把它比作一个厨房所以须要的各种工具. 锅碗瓢盆,各 ...
- 一文教你看懂大数据的技术生态圈:Hadoop,hive,spark
转自:https://www.cnblogs.com/reed/p/7730360.html 大数据本身是个很宽泛的概念,Hadoop生态圈(或者泛生态圈)基本上都是为了处理超过单机尺度的数据处理而诞 ...
随机推荐
- Gartner最新报告,分析超大规模边缘解决方案
当下,酝酿能量的超级边缘. 最近,我们在谈视频化狂飙.谈AIGC颠覆.谈算力动能不足,很少谈及边缘.但"边缘"恰恰与这一切相关,且越发密不可分,它是未来技术发展的极大影响因子. & ...
- HTML、 input;、accept 属性-规定能够通过文件上传进行提交的文件类型
定义和用法 文章地址: http://www.w3school.com.cn/tags/att_input_accept.asp accept 属性规定了可通过文件上传提交的服务器接受的文件类型. 注 ...
- 你真的懂synchronized锁?
1. 前言 synchronized在我们的程序中非常的常见,主要是为了解决多个线程抢占同一个资源.那么我们知道synchronized有多种用法,以下从实践出发,题目由简入深,看你能答对几道题目? ...
- css中文字与图片对齐
css中文字与图片对齐 第一种,使用vertical-align:middle .icon{ background-repeat:no-repeat; background-position:cent ...
- JavaScript基础语法-变量
JavaScript JavaScript - 变量 1. 概念 变量是用于存放数据的容器 通过变量名可以获取数据 并且数据是可修改的 2. 使用 声明变量 只声明不赋值 直接调用 程序会输出unde ...
- 这可能是最全面的MySQL面试八股文了
什么是MySQL MySQL是一个关系型数据库,它采用表的形式来存储数据.你可以理解成是Excel表格,既然是表的形式存储数据,就有表结构(行和列).行代表每一行数据,列代表该行中的每个值.列上的值是 ...
- 【有问必答】搭建uniapp项目流程手把手教学
前言 缘由 博友有问,狗哥必答 前段时间,博友加本狗微信,询问uniapp的学习方法.本狗资历浅薄,没有专门学过uniapp,只能将自己日常开发uniapp的基本流程和步骤进行分享,希望可以略尽绵薄之 ...
- [Pytorch框架] 2.5 循环神经网络
文章目录 2.5 循环神经网络 2.5.1 RNN简介 RNN的起因 为什么需要RNN RNN都能做什么 2.5.2 RNN的网络结构及原理 RNN LSTM GRU 2.5.3 循环网络的向后传播( ...
- 文心一言 VS chatgpt (15)-- 算法导论3.2 4~5题
四.函数 $\lceil \lg n \rceil !$ 多项式有界吗?函数 $\lceil \lg \lg n \rceil !$ 多项式有界吗? 文心一言: chatgpt: 对于第一个问题,函数 ...
- 2022-09-14:以下go语言代码输出什么?A:0 0;B:0 1;C:1 1;D:1 0。 package main func main() { println(f(1)) } func
2022-09-14:以下go语言代码输出什么?A:0 0:B:0 1:C:1 1:D:1 0. package main func main() { println(f(1)) } func f(x ...