
0 MapReduce实现Reduce Side Join操作
一.准备两张表以及对应的数据
(1)m_ys_lab_jointest_a(以下简称表A)
建表语句:
create table if not exists m_ys_lab_jointest_a (

     id bigint,

     name string

)

row format delimited

fields terminated by ''

lines terminated by ''

stored as textfile;
id name |
create table if not exists m_ys_lab_jointest_b (

     id bigint,

     statyear bigint,

     num bigint

)

row format delimited

fields terminated by ''

lines terminated by ''

stored as textfile;
id statyear num |
我们的目的是,以id为key做join操作,得到以下表:m_ys_lab_jointest_ab
| id name statyear num 1 北京 2011 2019 1 北京 2010 1962 2 天津 2011 1355 2 天津 2010 1299 4 山西 2011 3593 4 山西 2010 3574 |
二.计算模型
整个计算过程是:
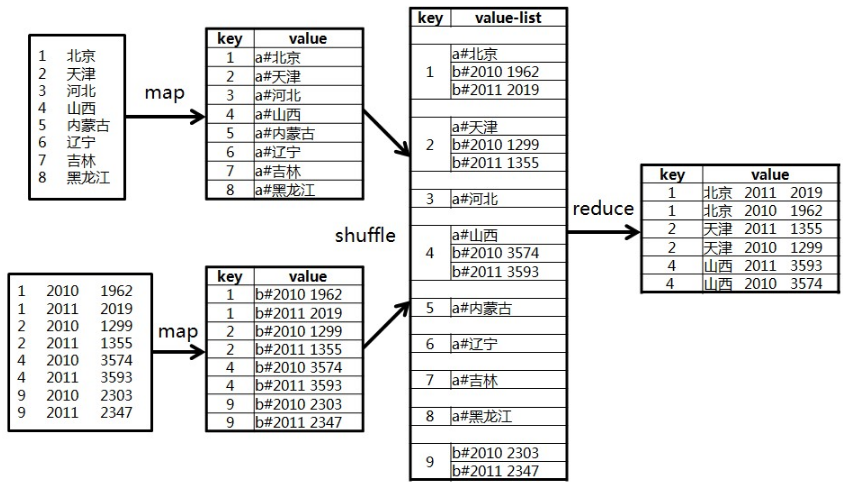
上代码:
import java.io.IOException;

import java.util.ArrayList;

import java.util.Iterator;

import java.util.List;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapred.FileSplit;

import org.apache.hadoop.mapred.JobConf;

import org.apache.hadoop.mapred.MapReduceBase;

import org.apache.hadoop.mapred.Mapper;

import org.apache.hadoop.mapred.OutputCollector;

import org.apache.hadoop.mapred.Reducer;

import org.apache.hadoop.mapred.Reporter;

/**

 * MapReduce实现Join操作

 */

public class MapRedJoin {

    public static final String DELIMITER = "\u0009"; // 字段分隔符

    // map过程

    public static class MapClass extends MapReduceBase implements Mapper<LongWritable, Text, Text, Text> {

        public void configure(JobConf job) {

            super.configure(job);

        }

        public void map(LongWritable key, Text value, OutputCollector<Text, Text> output, Reporter reporter) throws IOException, ClassCastException {

            // 获取输入文件的全路径和名称

            String filePath = ((FileSplit)reporter.getInputSplit()).getPath().toString();

            // 获取记录字符串

            String line = value.toString();

            // 抛弃空记录

            if (line == null || line.equals("")){

                return;

            }

            // 处理来自表A的记录

            if (filePath.contains("m_ys_lab_jointest_a")) {

                String[] values = line.split(DELIMITER); // 按分隔符分割出字段

                if (values.length < 2){

                    return;

                }

                String id = values[0]; // id

                String name = values[1]; // name

                output.collect(new Text(id), new Text("a#"+name));

            } else if (filePath.contains("m_ys_lab_jointest_b")) {// 处理来自表B的记录

                String[] values = line.split(DELIMITER); // 按分隔符分割出字段

                if (values.length < 3){

                    return;

                }

                String id = values[0]; // id

                String statyear = values[1]; // statyear

                String num = values[2]; //num

                output.collect(new Text(id), new Text("b#"+statyear+DELIMITER+num));

            }

        }

    }

    // reduce过程

    public static class Reduce extends MapReduceBase implements Reducer<Text, Text, Text, Text> {

        public void reduce(Text key, Iterator<Text> values, OutputCollector<Text, Text> output, Reporter reporter) throws IOException {

            List<String> listA = new ArrayList<String>(); // 存放来自表A的值

            List<String> listB = new ArrayList<String>(); // 存放来自表B的值

            while (values.hasNext()) {

                String value = values.next().toString();

                if (value.startsWith("a#")) {

                    listA.add(value.substring(2));

                } else if (value.startsWith("b#")) {

                    listB.add(value.substring(2));

                }

            }

            int sizeA = listA.size();

            int sizeB = listB.size();

            // 遍历两个向量

            int i, j;

            for (i = 0; i < sizeA; i ++) {

                for (j = 0; j < sizeB; j ++) {

                    output.collect(key, new Text(listA.get(i) + DELIMITER +listB.get(j)));

                }

            }

        }

    }

    protected void configJob(JobConf conf) {

        conf.setMapOutputKeyClass(Text.class);

        conf.setMapOutputValueClass(Text.class);

        conf.setOutputKeyClass(Text.class);

        conf.setOutputValueClass(Text.class);

        conf.setOutputFormat(ReportOutFormat.class);

    }

}
三.技术细节
0 MapReduce实现Reduce Side Join操作的更多相关文章
- MapReduce的Reduce side Join
1. 简单介绍 reduce side join是全部join中用时最长的一种join,可是这样的方法可以适用内连接.left外连接.right外连接.full外连接和反连接等全部的join方式.r ...
- 使用MapReduce实现join操作
在关系型数据库中,要实现join操作是非常方便的,通过sql定义的join原语就可以实现.在hdfs存储的海量数据中,要实现join操作,可以通过HiveQL很方便地实现.不过HiveQL也是转化成 ...
- MapReduce 实现数据join操作
前段时间有一个业务需求,要在外网商品(TOPB2C)信息中加入 联营自营 识别的字段.但存在的一个问题是,商品信息 和 自营联营标示数据是 两份数据:商品信息较大,是存放在hbase中.他们之前唯一的 ...
- Hadoop基础-MapReduce的Join操作
Hadoop基础-MapReduce的Join操作 作者:尹正杰 版权声明:原创作品,谢绝转载!否则将追究法律责任. 一.连接操作Map端Join(适合处理小表+大表的情况) no001 no002 ...
- Hadoop学习之路(二十一)MapReduce实现Reduce Join(多个文件联合查询)
MapReduce Join 对两份数据data1和data2进行关键词连接是一个很通用的问题,如果数据量比较小,可以在内存中完成连接. 如果数据量比较大,在内存进行连接操会发生OOM.mapredu ...
- 案例-使用MapReduce实现join操作
哈喽-各位小伙伴们中秋快乐,好久没更新新的文章啦,今天分享如何使用mapreduce进行join操作. 在离线计算中,我们常常不只是会对单一一个文件进行操作,进行需要进行两个或多个文件关联出更多数据, ...
- mapreduce join操作
上次和朋友讨论到mapreduce,join应该发生在map端,理由太想当然到sql里面的执行过程了 wheremap端 join在map之前(笛卡尔积),但实际上网上看了,mapreduce的笛卡尔 ...
- Mapreduce中的join操作
一.背景 MapReduce提供了表连接操作其中包括Map端join.Reduce端join还有半连接,现在我们要讨论的是Map端join,Map端join是指数据到达map处理函数之前进行合并的,效 ...
- [MapReduce_add_4] MapReduce 的 join 操作
0. 说明 Map 端 join && Reduce 端 join 1. Map 端 join Map 端 join:大表+小表 => 将小表加入到内存,迭代大表每一行,与之进行 ...
随机推荐
- Alwayson架构下 服务器 各虚拟IP漂移监控告警的功能实现
1.需求概括 我们知道,在SQL Server Alwayson 架构中,有多种虚拟IP,例如 WindowsCluster IP,ListenIP,角色高可用性IP(类似于侦听IP).在某些条件下, ...
- 查看linux系统时间和时区
参考地址:http://lidao.blog.51cto.com/ 一.使用date命令查看系统时间 [root@benbang ~]# date -R Tue, 01 Aug 2017 15:43: ...
- 第四章 .net core做一个简单的登录
项目目标部署环境:CentOS 7+ 项目技术点:.netcore2.0 + Autofac +webAPI + NHibernate5.1 + mysql5.6 + nginx 开源地址:https ...
- Laravel --- Laravel 5.3 发送邮件配置
版本:laravel 5.3 发送邮箱:QQ邮箱 根据官网以及别人的教程配置邮件发送,并且对配置过程中遇到的坑进行填补,做一总结,留待参考. 一.开启stmp 进入QQ邮箱,设置-服务,开启smtp. ...
- Laravel --- 【转】安装调试利器 Laravel Debugbar
[转]http://www.tuicool.com/articles/qYfmmur 1.简介 Laravel Debugbar 在 Laravel 5 中集成了 PHP Debug Bar ,用于显 ...
- SpringBoot从入门到精通十一(SpringBoot文件上传的两种方法)
前言 在企业级项目开发过程中,上传文件是最常用到的功能.SpringBoot集成了SpringMVC,当然上传文件的方式跟SpringMVC没有什么出入. 本章目标 使用SpringBoot项目完成单 ...
- 机器学习-5 支持向量机SVM
一.概念和背景 SVM:Support Vector Machine 支持向量机. 最早是由Vladimir N. Vapnik和Alexey Ya. Chervonenkis在1963年提出的. 目 ...
- 逻辑、集合运算上的卷积一览(FMT、FWT,……)
\oplus=\and,\or,\veebar 简介 对于逻辑\(\oplus\)的卷积,而且你不能N方豹草 \[ A_k=\sum_{i\oplus j=k} B_i\times C_k\\ \] ...
- 深度探索c++对象模型 第二章
1,c++转换函数:显示转换和隐式转换. 隐式转换为程序员提供了很大的变量.比如整形提升,普通类型转换为类类型(operator int())都为程序带来无尽的方便.试想,如果没有整形提升,一个sho ...
- CentOS 7 使用 HP 打印机
通常 hp 打印机应该是直接就能用的,但 centos 7 就一直遇到 printing job stopped 的情况.查看 http://localhost:631/printers/ 并没什么用 ...