
TorchVision 预训练模型进行推断
torchvision.models 里包含了许多模型,用于解决不同的视觉任务:图像分类、语义分割、物体检测、实例分割、人体关键点检测和视频分类。
本文将介绍 torchvision 中模型的入门使用,一起来创建 Faster R-CNN 预训练模型,预测图像中有什么物体吧。
import torch

import torchvision

from PIL import Image
创建预训练模型
model = torchvision.models.detection.fasterrcnn_resnet50_fpn(pretrained=True)
print(model) 可查看其结构:
FasterRCNN(

  (transform): GeneralizedRCNNTransform(

      Normalize(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225])

      Resize(min_size=(800,), max_size=1333, mode='bilinear')

  )

  (backbone): BackboneWithFPN(

    ...

  )

  (rpn): RegionProposalNetwork(

    (anchor_generator): AnchorGenerator()

    (head): RPNHead(

      (conv): Conv2d(256, 256, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1))

      (cls_logits): Conv2d(256, 3, kernel_size=(1, 1), stride=(1, 1))

      (bbox_pred): Conv2d(256, 12, kernel_size=(1, 1), stride=(1, 1))

    )

  )

  (roi_heads): RoIHeads(

    (box_roi_pool): MultiScaleRoIAlign(featmap_names=['0', '1', '2', '3'], output_size=(7, 7), sampling_ratio=2)

    (box_head): TwoMLPHead(

      (fc6): Linear(in_features=12544, out_features=1024, bias=True)

      (fc7): Linear(in_features=1024, out_features=1024, bias=True)

    )

    (box_predictor): FastRCNNPredictor(

      (cls_score): Linear(in_features=1024, out_features=91, bias=True)

      (bbox_pred): Linear(in_features=1024, out_features=364, bias=True)

    )

  )

)
此预训练模型是于 COCO train2017 上训练的,可预测的分类有:
COCO_INSTANCE_CATEGORY_NAMES = [

  '__background__', 'person', 'bicycle', 'car', 'motorcycle', 'airplane', 'bus',

  'train', 'truck', 'boat', 'traffic light', 'fire hydrant', 'N/A', 'stop sign',

  'parking meter', 'bench', 'bird', 'cat', 'dog', 'horse', 'sheep', 'cow',

  'elephant', 'bear', 'zebra', 'giraffe', 'N/A', 'backpack', 'umbrella', 'N/A', 'N/A',

  'handbag', 'tie', 'suitcase', 'frisbee', 'skis', 'snowboard', 'sports ball',

  'kite', 'baseball bat', 'baseball glove', 'skateboard', 'surfboard', 'tennis racket',

  'bottle', 'N/A', 'wine glass', 'cup', 'fork', 'knife', 'spoon', 'bowl',

  'banana', 'apple', 'sandwich', 'orange', 'broccoli', 'carrot', 'hot dog', 'pizza',

  'donut', 'cake', 'chair', 'couch', 'potted plant', 'bed', 'N/A', 'dining table',

  'N/A', 'N/A', 'toilet', 'N/A', 'tv', 'laptop', 'mouse', 'remote', 'keyboard', 'cell phone',

  'microwave', 'oven', 'toaster', 'sink', 'refrigerator', 'N/A', 'book',

  'clock', 'vase', 'scissors', 'teddy bear', 'hair drier', 'toothbrush'

]
指定 CPU or GPU
获取支持的 device:
device = torch.device('cuda') if torch.cuda.is_available() else torch.device('cpu')
模型移到 device:
model.to(device)
读取输入图像
img = Image.open('data/bicycle.jpg').convert("RGB")

img = torchvision.transforms.ToTensor()(img)
准备模型入参 images:
images = [img.to(device)]
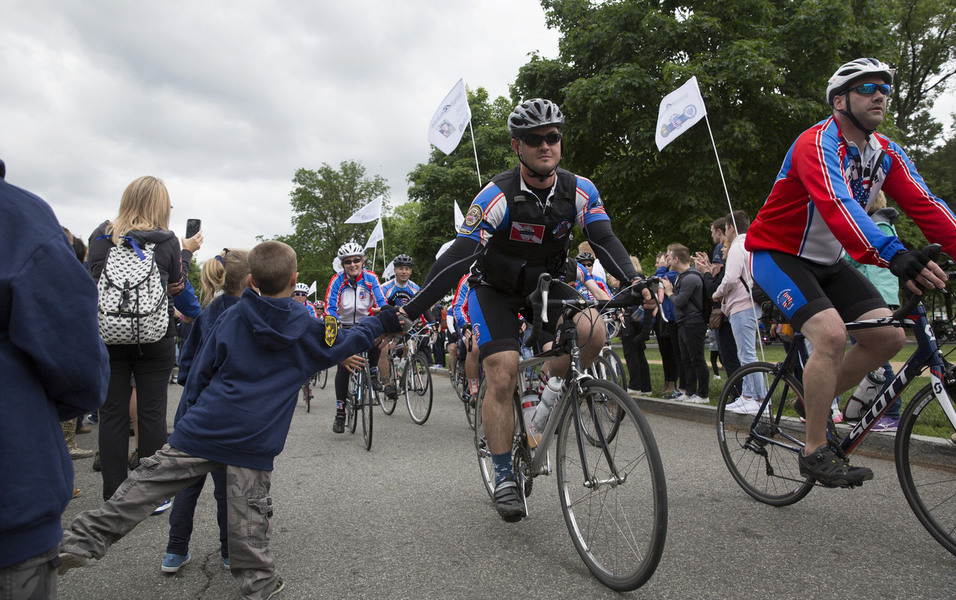
例图 data/bicycle.jpg:
进行模型推断
模型切为 eval 模式:
# For inference

model.eval()
模型在推断时,只需要给到图像数据,不用标注数据。推断后,会返回每个图像的预测结果 List[Dict[Tensor]]。Dict 包含字段有:
- boxes (
FloatTensor[N, 4]): 预测框[x1, y1, x2, y2],x范围[0,W],y范围[0,H] - labels (
Int64Tensor[N]): 预测类别 - scores (
Tensor[N]): 预测评分
predictions = model(images)

pred = predictions[0]

print(pred)
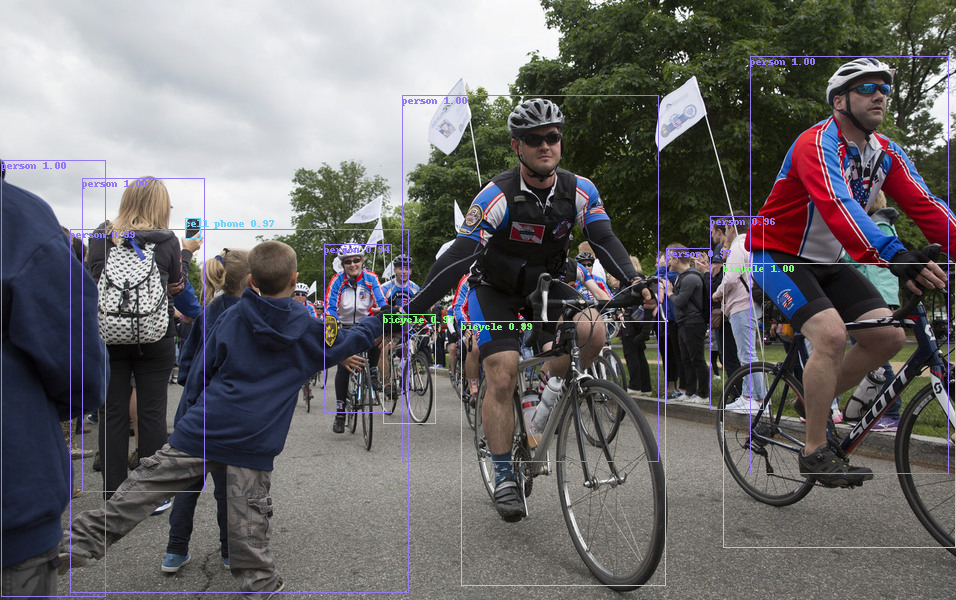
预测结果如下:
{'boxes': tensor([[750.7896,  56.2632, 948.7942, 473.7791],

        [ 82.7364, 178.6174, 204.1523, 491.9059],

        ...

        [174.9881, 235.7873, 351.1031, 417.4089],

        [631.6036, 278.6971, 664.1542, 353.2548]], device='cuda:0',

       grad_fn=<StackBackward>), 'labels': tensor([ 1,  1,  2,  1,  1,  1,  2,  2,  1, 77,  1,  1,  1,  2,  1,  1,  1,  1,

         1,  1, 27,  1,  1, 44,  1,  1,  1,  1, 27,  1,  1, 32,  1, 44,  1,  1,

        31,  2, 38,  2,  2,  1,  1, 31,  1,  1,  1,  1,  2,  1,  1,  1,  1,  1,

         1,  1,  1,  1,  1,  2,  2,  1,  1,  1,  2,  1,  1,  1,  1,  2,  1,  2,

         1,  1,  1,  1,  1,  1, 31,  2, 27,  1,  2,  1,  1, 31,  2, 77,  2,  1,

         2,  2,  2, 44,  2, 31,  1,  1,  1,  1], device='cuda:0'), 'scores': tensor([0.9990, 0.9976, 0.9962, 0.9958, 0.9952, 0.9936, 0.9865, 0.9746, 0.9694,

        0.9679, 0.9620, 0.9395, 0.8984, 0.8979, 0.8847, 0.8537, 0.8475, 0.7865,

        0.7822, 0.6896, 0.6633, 0.6629, 0.6222, 0.6132, 0.6073, 0.5383, 0.5248,

        0.4891, 0.4881, 0.4595, 0.4335, 0.4273, 0.4089, 0.4074, 0.3679, 0.3357,

        0.3192, 0.3102, 0.2797, 0.2655, 0.2640, 0.2626, 0.2615, 0.2375, 0.2306,

        0.2174, 0.2129, 0.1967, 0.1912, 0.1907, 0.1739, 0.1722, 0.1669, 0.1666,

        0.1596, 0.1586, 0.1473, 0.1456, 0.1408, 0.1374, 0.1373, 0.1329, 0.1291,

        0.1290, 0.1289, 0.1278, 0.1205, 0.1182, 0.1182, 0.1103, 0.1060, 0.1025,

        0.1010, 0.0985, 0.0959, 0.0919, 0.0887, 0.0886, 0.0873, 0.0832, 0.0792,

        0.0778, 0.0764, 0.0693, 0.0686, 0.0679, 0.0671, 0.0668, 0.0636, 0.0635,

        0.0607, 0.0605, 0.0581, 0.0578, 0.0572, 0.0568, 0.0557, 0.0556, 0.0555,

        0.0533], device='cuda:0', grad_fn=<IndexBackward>)}
绘制预测结果
获取 score >= 0.9 的预测结果:
scores = pred['scores']

mask = scores >= 0.9

boxes = pred['boxes'][mask]

labels = pred['labels'][mask]

scores = scores[mask]
引入 utils.plots.plot_image 绘制结果:
from utils.colors import golden

from utils.plots import plot_image

lb_names = COCO_INSTANCE_CATEGORY_NAMES

lb_colors = golden(len(lb_names), fn=int, scale=0xff, shuffle=True)

lb_infos = [f'{s:.2f}' for s in scores]

plot_image(img, boxes, labels, lb_names, lb_colors, lb_infos,

           save_name='result.png')
utils.plots.plot_image函数实现可见后文源码,注意其要求torchvision >= 0.9.0/nightly。
源码
utils.colors.golden:
import colorsys

import random

def golden(n, h=random.random(), s=0.5, v=0.95,

           fn=None, scale=None, shuffle=False):

  if n <= 0:

    return []

  coef = (1 + 5**0.5) / 2

  colors = []

  for _ in range(n):

    h += coef

    h = h - int(h)

    color = colorsys.hsv_to_rgb(h, s, v)

    if scale is not None:

      color = tuple(scale*v for v in color)

    if fn is not None:

      color = tuple(fn(v) for v in color)

    colors.append(color)

  if shuffle:

    random.shuffle(colors)

  return colors
utils.plots.plot_image:
from typing import Union, Optional, List, Tuple

import matplotlib.pyplot as plt

import numpy as np

import torch

import torchvision

from PIL import Image

def plot_image(

  image: Union[torch.Tensor, Image.Image, np.ndarray],

  boxes: Optional[torch.Tensor] = None,

  labels: Optional[torch.Tensor] = None,

  lb_names: Optional[List[str]] = None,

  lb_colors: Optional[List[Union[str, Tuple[int, int, int]]]] = None,

  lb_infos: Optional[List[str]] = None,

  save_name: Optional[str] = None,

  show_name: Optional[str] = 'result',

) -> torch.Tensor:

  """

  Draws bounding boxes on given image.

  Args:

    image (Image): `Tensor`, `PIL Image` or `numpy.ndarray`.

    boxes (Optional[Tensor]): `FloatTensor[N, 4]`, the boxes in `[x1, y1, x2, y2]` format.

    labels (Optional[Tensor]): `Int64Tensor[N]`, the class label index for each box.

    lb_names (Optional[List[str]]): All class label names.

    lb_colors (List[Union[str, Tuple[int, int, int]]]): List containing the colors of all class label names.

    lb_infos (Optional[List[str]]): Infos for given labels.

    save_name (Optional[str]): Save image name.

    show_name (Optional[str]): Show window name.

  """

  if not isinstance(image, torch.Tensor):

    image = torchvision.transforms.ToTensor()(image)

  if boxes is not None:

    if image.dtype != torch.uint8:

      image = torchvision.transforms.ConvertImageDtype(torch.uint8)(image)

    draw_labels = None

    draw_colors = None

    if labels is not None:

      draw_labels = [lb_names[i] for i in labels] if lb_names is not None else None

      draw_colors = [lb_colors[i] for i in labels] if lb_colors is not None else None

    if draw_labels and lb_infos:

      draw_labels = [f'{l} {i}' for l, i in zip(draw_labels, lb_infos)]

    # torchvision >= 0.9.0/nightly

    #  https://github.com/pytorch/vision/blob/master/torchvision/utils.py

    res = torchvision.utils.draw_bounding_boxes(image, boxes,

      labels=draw_labels, colors=draw_colors)

  else:

    res = image

  if save_name or show_name:

    res = res.permute(1, 2, 0).contiguous().numpy()

    if save_name:

      Image.fromarray(res).save(save_name)

    if show_name:

      plt.gcf().canvas.set_window_title(show_name)

      plt.imshow(res)

      plt.show()

  return res
参考
GoCoding 个人实践的经验分享,可关注公众号!
TorchVision 预训练模型进行推断的更多相关文章
- 【小白学PyTorch】5 torchvision预训练模型与数据集全览
文章来自:微信公众号[机器学习炼丹术].一个ai专业研究生的个人学习分享公众号 文章目录: 目录 torchvision 1 torchvision.datssets 2 torchvision.mo ...
- 【转载】最强NLP预训练模型!谷歌BERT横扫11项NLP任务记录
本文介绍了一种新的语言表征模型 BERT--来自 Transformer 的双向编码器表征.与最近的语言表征模型不同,BERT 旨在基于所有层的左.右语境来预训练深度双向表征.BERT 是首个在大批句 ...
- pytorch预训练模型的下载地址以及解决下载速度慢的方法
https://github.com/pytorch/vision/tree/master/torchvision/models 几乎所有的常用预训练模型都在这里面 总结下各种模型的下载地址: 1 R ...
- PyTorch保存模型与加载模型+Finetune预训练模型使用
Pytorch 保存模型与加载模型 PyTorch之保存加载模型 参数初始化参 数的初始化其实就是对参数赋值.而我们需要学习的参数其实都是Variable,它其实是对Tensor的封装,同时提供了da ...
- [Pytorch]Pytorch加载预训练模型(转)
转自:https://blog.csdn.net/Vivianyzw/article/details/81061765 东风的地方 1. 直接加载预训练模型 在训练的时候可能需要中断一下,然后继续训练 ...
- 【tf.keras】tf.keras加载AlexNet预训练模型
目录 从 PyTorch 中导出模型参数 第 0 步:配置环境 第 1 步:安装 MMdnn 第 2 步:得到 PyTorch 保存完整结构和参数的模型(pth 文件) 第 3 步:导出 PyTorc ...
- BERT预训练模型的演进过程!(附代码)
1. 什么是BERT BERT的全称是Bidirectional Encoder Representation from Transformers,是Google2018年提出的预训练模型,即双向Tr ...
- XLNet预训练模型,看这篇就够了!(代码实现)
1. 什么是XLNet XLNet 是一个类似 BERT 的模型,而不是完全不同的模型.总之,XLNet是一种通用的自回归预训练方法.它是CMU和Google Brain团队在2019年6月份发布的模 ...
- NLP预训练模型-百度ERNIE2.0的效果到底有多好【附用户点评】
ERNIE是百度自研的持续学习语义理解框架,该框架支持增量引入词汇(lexical).语法 (syntactic) .语义(semantic)等3个层次的自定义预训练任务,能够全面捕捉训练语料中的词法 ...
随机推荐
- AQS简单理解入门---1
这篇文章,我们来聊聊面试时一个比较有杀伤力的问题:聊聊你对AQS的理解? 之前有同学反馈,去互联网公司面试,面试官聊到并发时就问到了这个问题.当时那位同学内心估计受到了一万点伤害... 因为首先,很多 ...
- 正点原子DS100拆解全过程-硬件工程师必备
前言: 之前一篇只针对正点原子DS100手持示波器的使用介绍文章.可作为一个电子工程师,光使用不是我们的风格哈,我们还要拆开看看电路. 开拆 外壳 首先,看下图,DS100不是使用螺母进行固定的,而是 ...
- HDFS查看文件的前几行-后几行-行数
随机返回指定行数的样本数据hadoop fs -cat /test/gonganbu/scene_analysis_suggestion/* | shuf -n 5返回前几行的样本数据hadoop f ...
- Educational Codeforces Round 102 (Rated for Div. 2) B. String LCM (构造,思维)
题意:给你两个字符串\(a\)和\(b\),找出它们的\(lcm\),即构造一个新的字符串\(c\),使得\(c\)可以由\(x\)个\(a\)得到,并且可以由\(y\)个\(b\)得到,输出\(c\ ...
- 【uva 11054】Wine trading in Gergovia(算法效率--等价转换)
题意:N个等距村庄,买(>0)卖(<0)酒,供需平衡,运K则需K劳动力.问所需的最小劳动力. 解法:由于运出或运入1的都需经过2,所以无论如何,都可以等价于从2本身运入或运出.因此可以将1 ...
- python2.* 版本 与 3.* 版本中的区别
目录 Unicode编码 print函数 raw_input() 和 input( ) 不等运算符 数据类型 除法 map 和 filter Unicode编码 python2.x 解释器默认编码格式 ...
- Docker配置文件deamon.json详解
vim /etc/docker/daemon.json { "authorization-plugins": [], "data-root": "&q ...
- ERROR 1045 (28000): Access denied for user 'ODBC'@'localhost' (using password: NO)
cmd mysql -h localhost -u root -p r然后报错 ERROR 1045 (28000): Access denied for user 'ODBC'@'localhost ...
- CodeForces - 13E(分块)
Little Petya likes to play a lot. Most of all he likes to play a game «Holes». This is a game for on ...
- Leetcode(106)-从中序与后序遍历序列构造二叉树
根据一棵树的中序遍历与后序遍历构造二叉树. 注意:你可以假设树中没有重复的元素. 例如,给出 中序遍历 inorder = [9,3,15,20,7] 后序遍历 postorder = [9,15,7 ...