
HDU4323-Magic Number(levenshtein distance-编辑距离)
描述:
There are many magic numbers whose lengths are less than 10. Given some queries, each contains a single number, if the Levenshtein distance (see below) between the number in the query and a magic number is no more than a threshold, we call the magic number is the lucky number for that query. Could you find out how many luck numbers are there for each query?
In information theory and computer science, the Levenshtein distance is a string metric for measuring the amount of difference between two sequences.
The term edit distance is often used to refer specifically to Levenshtein distance.
The Levenshtein distance between two strings is defined as the minimum number of edits needed to transform one string into the other, with the allowable edit operations being insertion, deletion, or substitution of a single character. It is named after Vladimir Levenshtein, who considered this distance in 1965.
For example, the Levenshtein distance between "kitten" and "sitting" is 3, since the following three edits change one into the other, and there is no way to do it with fewer than three edits:
1.kitten → sitten (substitution of 's' for 'k')
2.sitten → sittin (substitution of 'i' for 'e')
3.sittin → sitting (insertion of 'g' at the end).
There are several test cases. The first line contains a single number T shows that there are T cases. For each test case, there are 2 numbers in the first line: n (n <= 1500) m (m <= 1000) where n is the number of magic numbers and m is the number of queries.
In the next n lines, each line has a magic number. You can assume that each magic number is distinctive.
In the next m lines, each line has a query and a threshold. The length of each query is no more than 10 and the threshold is no more than 3.
For each test case, the first line is "Case #id:", where id is the case number. Then output m lines. For each line, there is a number shows the answer of the corresponding query.
代码:
这里提到了levenshtein distance,特去维基百科查阅。In information theory and computer science, the Levenshtein distance is a string metric for measuring the difference between two sequences.Levenshtein distance between two words is the minimum number of single-character edits (i.e. insertions, deletions or substitutions) required to change one word into the other.也就是从一个字符串经过增、删、改变换到另一个字符串所需要的最少操作步骤。
求levenshtein distance有已有的算法:
Mathematically, the Levenshtein distance between two strings  (of length
 and
 respectively) is given by
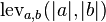 where
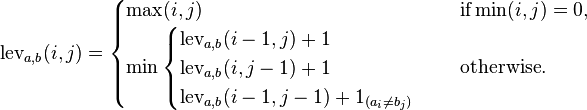
where  is the indicator function equal to 0 when
 and equal to 1 otherwise.
先描述一下算法的原理:
- 如果我们可以使用k个操作数把s[1…i]转换为t[1…j-1],我们只需要把t[j]加在最后面就能将s[1…i]转换为t[1…j],操作数为k+1。
- 如果我们可以使用k个操作数把s[1…i-1]转换为t[1…j],我们只需要把s[i]从最后删除就可以完成转换,操作数为k+1。
- 如果我们可以使用k个操作数把s[1…i-1]转换为t[1…j-1],我们只需要在需要的情况下(s[i] != t[j])把s[i]替换为t[j],所需的操作数为k+cost(cost代表是否需要转换,如果s[i]==t[j],则cost为0,否则为1)。
为了更加清晰的理解,我们用一个二维表来理解:
| b | e | a | u | t | y | ||
| 0 | 1 | 2 | 3 | 4 | 5 | 6 | |
| b | 1 | ||||||
| a | 2 | ||||||
| t | 3 | ||||||
| y | 4 | ||||||
| u | 5 |
初始的时候,第一行与第一列初始化为0-n,代表利用insertion操作从空串依次插入,得到当前的串。
| b | e | a | u | t | y | ||
| 0 | 1 | 2 | 3 | 4 | 5 | 6 | |
| b | 1 | ||||||
| a | 2 | ||||||
| t | 3 | ||||||
| y | 4 | ||||||
| u | 5 |
dp[1][1]的值由左方、上方和左前方的值决定。从左方来,意味着从beauty的空到batyu的b,只需要一次insertion操作,操作数和为1+1;从上方来与从左方来类似,操作数为1+1;从左上方来,由于beauty的b与batyu的b相等,所以不需要进行操作,操作数为0+0。选取最小值0+0位dp值。
| b | e | a | u | t | y | ||
| 0 | 1 | 2 | 3 | 4 | 5 | 6 | |
| b | 1 | ||||||
| a | 2 | ||||||
| t | 3 | ||||||
| y | 4 | ||||||
| u | 5 |
同理,我们可以填出其他值。
根据算法的原理,可以解决这道题。这道题求的是一大堆串与给定串的编辑距离小于等于给定threshold(阈值)的个数。
#include<stdio.h>

#include<string.h>

#include<iostream>

#include<stdlib.h>

#include <math.h>

using namespace std;

#define N 15

#define M 1505

int MIN( int a,int b,int c ){

    if( b<a ) a=b;

    if( c<a ) a=c;

    return a;

}

int main(){

    int T,tc=,count,magic_num,query_num,threshold,dp[N][N],cost;

    char magic[M][N],query[N];

    scanf("%d",&T);

    while( tc<=T ){

        scanf("%d%d",&magic_num,&query_num);

        for( int i=;i<magic_num;i++ )

            scanf("%s",magic[i]);

        for( int i=;i<N;i++ ){

            dp[][i]=i;

            dp[i][]=i;

        }

        printf("Case #%d:\n",tc);

        while( query_num-- ){

            scanf("%s%d",&query,&threshold);

            count=;

            for( int i=;i<magic_num;i++ ){

                for( int j=;j<=strlen(magic[i]);j++ ){

                    for( int k=;k<=strlen(query);k++ ){

                        if( magic[i][j-]==query[k-] )

                            cost=;

                        else

                            cost=;

                        dp[j][k]=MIN(dp[j-][k]+,dp[j][k-]+,dp[j-][k-]+cost);

                    }

                }

                if( dp[strlen(magic[i])][strlen(query)]<=threshold )

                    count++;

            }

            printf("%d\n",count);

        }

        tc++;

    }

    system("pause");

    return ;

}
HDU4323-Magic Number(levenshtein distance-编辑距离)的更多相关文章
- Levenshtein distance 编辑距离算法
这几天再看 virtrual-dom,关于两个列表的对比,讲到了 Levenshtein distance 距离,周末抽空做一下总结. Levenshtein Distance 介绍 在信息理论和计算 ...
- 利用Levenshtein Distance (编辑距离)实现文档相似度计算
1.首先将word文档解压缩为zip /** * 修改后缀名 */ public static String reName(String path){ File file=new File(path) ...
- Levenshtein distance 编辑距离
编辑距离,又称Levenshtein距离,是指两个字串之间,由一个转成另一个所需的最少编辑操作次数.许可的编辑操作包括将一个字符替换成另一个字符,插入一个字符,删除一个字符 实现方案: 1. 找出最长 ...
- Levenshtein Distance (编辑距离) 算法详解
编辑距离即从一个字符串变换到另一个字符串所需要的最少变化操作步骤(以字符为单位,如son到sun,s不用变,将o->s,n不用变,故操作步骤为1). 为了得到编辑距离,我们画一张二维表来理解,以 ...
- Magic Number(Levenshtein distance算法)
Magic Number Time Limit:1000MS Memory Limit:65536KB 64bit IO Format:%I64d & %I64u Submit ...
- HDU 4323——Magic Number——————【dp求编辑距离】2012——MUT——3
Magic Number Time Limit: 2000/1000 MS (Java/Others) Memory Limit: 65536/65536 K (Java/Others)Tota ...
- C#实现Levenshtein distance最小编辑距离算法
Levenshtein distance,中文名为最小编辑距离,其目的是找出两个字符串之间需要改动多少个字符后变成一致.该算法使用了动态规划的算法策略,该问题具备最优子结构,最小编辑距离包含子最小编辑 ...
- Levenshtein Distance算法(编辑距离算法)
编辑距离 编辑距离(Edit Distance),又称Levenshtein距离,是指两个字串之间,由一个转成另一个所需的最少编辑操作次数.许可的编辑操作包括将一个字符替换成另一个字符,插入一个字符, ...
- 字符串相似度算法(编辑距离算法 Levenshtein Distance)(转)
在搞验证码识别的时候需要比较字符代码的相似度用到“编辑距离算法”,关于原理和C#实现做个记录. 据百度百科介绍: 编辑距离,又称Levenshtein距离(也叫做Edit Distance),是指两个 ...
- 扒一扒编辑距离(Levenshtein Distance)算法
最近由于工作需要,接触了编辑距离(Levenshtein Distance)算法.赶脚很有意思.最初百度了一些文章,但讲的都不是很好,读起来感觉似懂非懂.最后还是用google找到了一些资料才慢慢理解 ...
随机推荐
- hadoop中汉字与英文字符混合的keyword做为combine的key的问题
近期,须要将汉字与字符的非常合串作为combine的输出的key, 这样做是希望,利用hadoop的归并来依照key进行分组,然后,在reduce阶段,拿到的都是一个一个组. 可是,发现,这样的,汉字 ...
- memcached-session-manager的一些理解
1.节点分配 粘性规划: Tomcat-1(t1)将session优先备份在运行在令一台机器上的memcached-2(m2)上面,仅当m2失效的时候,t1才会将sessin存储在m1上面(m1是t1 ...
- nginx负载均衡配置(转)
www.s135.com 和 blog.s135.com 域名均指向 Nginx 所在的服务器IP. 用户访问http://www.s135.com,将其负载均衡到192.168.1.2:80.192 ...
- SharedPreferences最佳实践
转:http://blog.csdn.net/xushuaic/article/details/24513599 笔记摘要:该文章是我在Android Weekly中看到的,以前也一直用SharedP ...
- hdu 2604Queuing dp+ 矩阵快速幂
题目链接 给一个长度为n的字符串, 每个字符可以使f或m. 问你不包含子串fmf以及fff的字符串数量有多少. 令0表示mm结尾, 1表示mf, 2表示ff, 3表示fm. 那么 f(n+1, 0) ...
- MVC自学第一课
了解传统的ASP.NET WebForm ASP.NET 在02年问世,给Web开发领域带来了巨大转变.下图描述了当时微软的技术堆栈. ASP.NET WebForm 技术堆栈 (注:此图的含义为,W ...
- 让两个Div并排显示
一.使用display的inline属性 <div style="width:300px; height:auto; float:left; display:inline"& ...
- bash代码
bash代码: #!/bin/bash MySQLSTARTUP="/data/3306/mysql" DbProcessCount=`ps -ef|grep mysql|grep ...
- JSON 解析器。JSON.stringify和JSON.parse
以前用的是JavaScript 的eval. 现在JSON 提供了JSON.stringify和JSON.parse两个函数. JSON.parse用于从一个字符串中解析出json对象. JSON. ...
- iOS6 旋转
iOS 6的rotation改变了很多.先来看看官方的描述 http://www.bgr.com/2012/08/06/ios-6-beta-4-change-log-now-available/ ...