
hadoop深入学习之SequenceFile
的1个byte
3.Key和Value的类名
4.压缩相关的信息
5.其他用户定义的元数据
6.同步标记,sync marker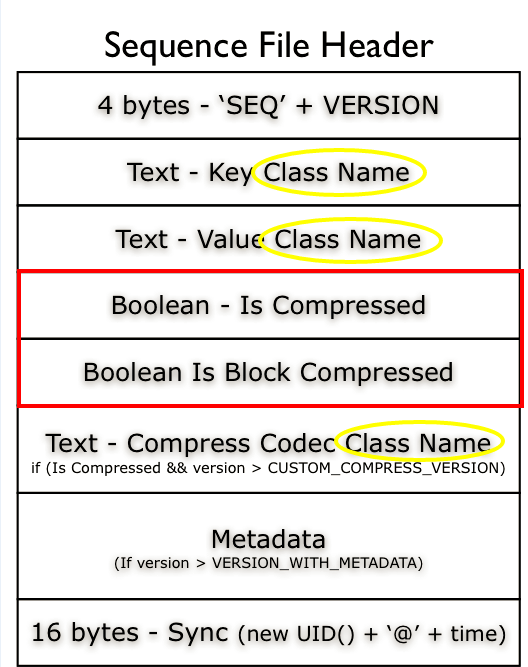
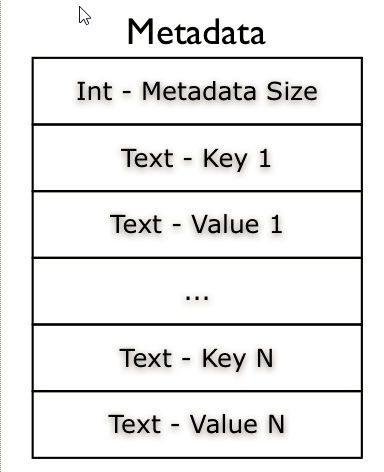
Metadata 在文件创建时就写好了,所以也是不能更改的。条记录存储一个索引映射。当然,记录间隔可人为修改,通过MapFIle.Writer的setIndexInterval()方法,或修改io.map.index.interval属性;
另外,与SequenceFile不同的是,MapFile的KeyClass一定要实现WritableComparable接口,即Key值是可比较的。
FileSystem fs=FileSystem.get(conf); Path mapFile=new Path("mapFile.map");
//Writer内部类用于文件的写操作,假设Key和Value都为Text类型 MapFile.Writer writer=new MapFile.Writer(conf,fs,mapFile.toString(),Text.class,Text.class); //通过writer向文档中写入记录 writer.append(new Text("key"),new Text("value")); IOUtils.closeStream(writer);//关闭write流
//Reader内部类用于文件的读取操作 MapFile.Reader reader=new MapFile.Reader(fs,mapFile.toString(),conf); //通过reader从文档中读取记录 Text key=new Text(); Text value=new Text(); while(reader.next(key,value)){ System.out.println(key); System.out.println(key); } IOUtils.closeStream(reader);//关闭read流
MapFile
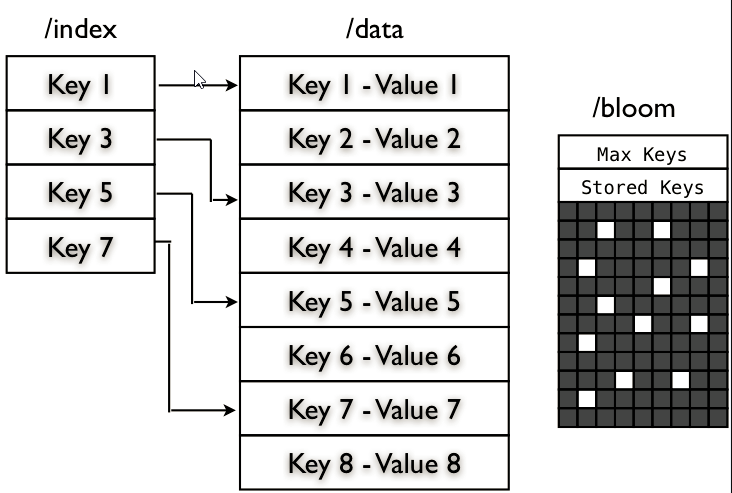
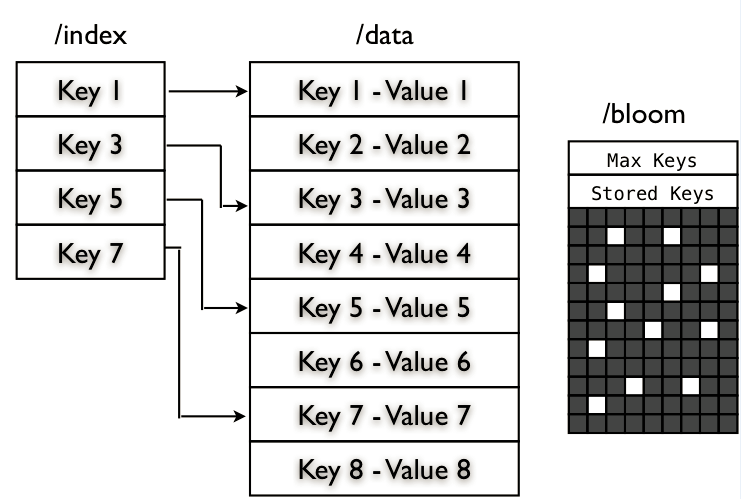
一个key-value 对应的查找数据结构,由数据文件/data 和索引文件 /index 组成,数据文件中包含所有需要存储的key-value对,按key的顺序排列。索引文件包含一部分key值,用以指向数据文件的关键位置。
来源: http://blog.cloudera.com/blog/2011/01/hadoop-io-sequence-map-set-array-bloommap-files/
The MapFile is a directory that contains two SequenceFile: the data file (“/data”) and the index file (“/index”). The data contains all the key, value records but key N + 1 must be greater then or equal to the key N. This condition is checked during the append() operation, if checkKey fail it throws an IOException “Key out of order”.
The Index file is populated with the key and a LongWritable that contains the starting byte position of the record. Index does’t contains all the keys but just a fraction of the keys, you can specify the indexInterval calling setIndexInterval() method. The Index is read enteirely into memory, so if you’ve large map you can set a index skip value that allows you to keep in memory just a fraction of the index keys.
SetFile – 基于 MapFile 实现的,他只有key,value为不可变的数据。SetFile and ArrayFile are based on MapFile, and their implementation are just few lines of code. The SetFile instead of append(key, value) as just the key field append(key) and the value is always the NullWritable instance.
ArrayFile – 也是基于 MapFile 实现,他就像我们使用的数组一样,key值为序列化的数字。The ArrayFile as just the value field append(value) and the key is a LongWritable that contains the record number, count + 1.
BloomMapFile – 他在 MapFile 的基础上增加了一个 /bloom 文件,包含的是二进制的过滤表,在每一次写操作完成时,会更新这个过滤表The BloomMapFile extends the MapFile adding another file, the bloom file “/bloom”, and this file contains a serialization of the DynamicBloomFilter filled with the added keys. The bloom file is written entirely during the close operation.
If you want to play with SequenceFile, MapFile, SetFile, ArrayFile without using Java, I’ve written a naive implementation in python. You can find it, in my github repository python-hadoop.
参考url
--------------------------------
1.Hadoop I/O: Sequence, Map, Set, Array, BloomMap Files - Cloudera Engineering Blog
http://blog.cloudera.com/blog/2011/01/hadoop-io-sequence-map-set-array-bloommap-files/
== 以上 2017/7/6 下午5:29:17
--------------------------------
1.[hadoop源码阅读][4]-org.apache.hadoop.io - 阿笨猫 - 博客园
http://www.cnblogs.com/xuxm2007/archive/2012/06/15/2550986.html
== 以上 2017/7/6 下午5:06:26
http://hadoop.apache.org/common/docs/r0.20.2/api/index.html
http://blog.csdn.net/ludi7125/article/details/7605719
http://www.cloudera.com/blog/2011/01/hadoop-io-sequence-map-set-array-bloommap-files/
http://blog.nosqlfan.com/html/1217.html
http://jerrylead.iteye.com/blog/1181716
http://www.itivy.com/arch/archive/2011/12/12/hadoop-writable-interface-introduction.html
hadoop深入学习之SequenceFile的更多相关文章
- Hadoop入门学习笔记---part4
紧接着<Hadoop入门学习笔记---part3>中的继续了解如何用java在程序中操作HDFS. 众所周知,对文件的操作无非是创建,查看,下载,删除.下面我们就开始应用java程序进行操 ...
- Hadoop入门学习笔记---part3
2015年元旦,好好学习,天天向上.良好的开端是成功的一半,任何学习都不能中断,只有坚持才会出结果.继续学习Hadoop.冰冻三尺,非一日之寒! 经过Hadoop的伪分布集群环境的搭建,基本对Hado ...
- Hadoop入门学习笔记---part2
在<Hadoop入门学习笔记---part1>中感觉自己虽然总结的比较详细,但是始终感觉有点凌乱.不够系统化,不够简洁.经过自己的推敲和总结,现在在此处概括性的总结一下,认为在准备搭建ha ...
- Hadoop入门学习笔记---part1
随着毕业设计的进行,大学四年正式进入尾声.任你玩四年的大学的最后一次作业最后在激烈的选题中尘埃落定.无论选择了怎样的选题,无论最后的结果是怎样的,对于大学里面的这最后一份作业,也希望自己能够尽心尽力, ...
- Hadoop家族学习路线图--转载
原文地址:http://blog.fens.me/hadoop-family-roadmap/ Sep 6, 2013 Tags: Hadoophadoop familyroadmap Comment ...
- Hadoop家族学习路线图
主要介绍Hadoop家族产品,常用的项目包括Hadoop, Hive, Pig, HBase, Sqoop, Mahout, Zookeeper, Avro, Ambari, Chukwa,新增加的项 ...
- [转]Hadoop家族学习路线图
Hadoop家族学习路线图 Hadoop家族系列文章,主要介绍Hadoop家族产品,常用的项目包括Hadoop, Hive, Pig, HBase, Sqoop, Mahout, Zookeeper, ...
- Hadoop家族学习路线图v
主要介绍Hadoop家族产品,常用的项目包括Hadoop, Hive, Pig, HBase, Sqoop, Mahout, Zookeeper, Avro, Ambari, Chukwa,新增加的项 ...
- Hadoop家族学习路线、实践案例
作者:Han Hsiao链接:https://www.zhihu.com/question/19795366/answer/24524910来源:知乎著作权归作者所有.商业转载请联系作者获得授权,非商 ...
随机推荐
- HDU 5289 尺取
Assignment Time Limit: 4000/2000 MS (Java/Others) Memory Limit: 65536/65536 K (Java/Others)Total ...
- asp.net服务器上无法发送邮件的问题
前几天为开发的网站做了个发送邮件的功能,但是部署到服务器上无法发送邮件,提示由于目标机器积极拒绝,无法连接.在网上找到了一个解决办法 如果安装了McAfee杀毒软件(按照“手工安装方法”安装),首先需 ...
- shiro:10个过滤器;10个jsp标签;5个@注解
10个过滤器 过滤器简称 对应的java类 anon org.apache.shiro.web.filter.authc.AnonymousFilter authc org.apache.shiro. ...
- [C#]委托实例分析(附源码)
一直都听说C#中的委托与事件非常重要,都没有什么切身的体会,而这次通过做一个WinForm二次开发的项目才真正感觉到了委托与事件的犀利之处. 1.C#中的事件和委托的作用? 事件代表一个组件能够被关注 ...
- 部署C# ReportViewer遇到的坑
前些天临时给客户做个工具,统计具体时间点各种车型数据的数量及比重,为了显示方便就用C#来做,因为它有现成的reportviwer控件提供了显示,打印,导出功能.原本我以为这个控件是.netframew ...
- linux安装jdk1.6
本来打算安装jdk1.8的 从官网下载来的jdk1.8的tar.gz的jar包. 使用tar命令解压,复制到指定文件夹后,配置完环境变量后一直报错,什么CGLIB2.4的.查询得到结果好像是linux ...
- 在一个机器上获取大量PublicKey后的私钥恢复方法
渗透测试过程中,有时候会在某个未授权访问漏洞中获取authorized_keys文件,里面有大量账户用于免密登录的PublicKey,这个时候如何进行下一步渗透? 可以考虑rsa碰撞的方式,找到公用p ...
- Linux crontab使用及注意事项
渗透测试中,经常会用到crontab来执行计划任务,从而实现后门程序的隐藏,但crontab有几个坑点还是需要记录一下,方便日后使用时及时查询 1.crontab配置格式 # Example of j ...
- 分水岭分割算法(watershed segmentation)的C++实现(法1)
运行环境:ubuntu16.04+Qt+opencv2.4.13 参考链接:http://blog.csdn.net/u010741471/article/details/45193521 water ...
- DBSCAN聚类︱scikit-learn中一种基于密度的聚类方式
一.DBSCAN聚类概述 基于密度的方法的特点是不依赖于距离,而是依赖于密度,从而克服基于距离的算法只能发现"球形"聚簇的缺点. DBSCAN的核心思想是从某个核心点出发,不断向密 ...