
requests库详解 --Python3
本文介绍了requests库的基本使用,希望对大家有所帮助。
requests库官方文档:https://2.python-requests.org/en/master/
一、请求:
1、GET请求
coding:utf8

import requests

response = requests.get('http://www.httpbin.org/get')

print(response.text)
2、POST请求
# coding:utf8

import requests

data = {

    'name': 'Thanlon',

    'age': 22,

    'sex': '男'

}

response = requests.post('http://httpbin.org/post', data=data)

print(response.text)
3、解析json
# coding:utf8

import requests, json

response = requests.get('http://www.httpbin.org/get')

print(type(response.text))

# print(response.text)

print(response.json())  # 等价于json.loads(response.text)

print(type(response.json()))
4、获取二进制数据
# coding:utf8

import requests

response = requests.get('https://www.baidu.com/img/dong_5af13a1a6fd9fb2c587e68ca5038a3c8.gif')

print(type(response.text))

print(type(response.content))

print(response.text)

print(response.content)  # 二进制流
5、保存二进制文件(图片、视频)
# coding:utf8

import requests

response = requests.get('https://www.baidu.com/img/dong_5af13a1a6fd9fb2c587e68ca5038a3c8.gif')

with open('image.gif', 'wb') as f:

    f.write(response.content)

    f.close()
6、添加headers(有需要添加请求头信息,否则请求不到,如“知乎”)
# coding:utf8

# get请求,添加headers

import requests

headers = {

    'user-agent': 'Mouser-agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/72.0.3626.109 Safari/537.36zilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/72.0.3626.109 Safari/537.36'

}

response = requests.get('https://www.zhihu.com/explore', headers=headers)

print(response.text)
#coding:utf8

#post请求,添加headers

import requests

data = {

    'name': 'Thanlon',

    'age': 22,

    'sex': '男'

}

headers = {

    'user-agent': 'Mouser-agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/72.0.3626.109 Safari/537.36zilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/72.0.3626.109 Safari/537.36'

}

response = requests.post('http://httpbin.org/post', data=data, headers=headers)

print(response.text)
二、响应(response)
1、response相关属性
#coding:utf8

import requests

response = requests.get('http://httpbin.org')

print(type(response.status_code), response.status_code)#状态码 <class 'int'>

print(type(response.headers), response.headers)#响应头 <class 'requests.structures.CaseInsensitiveDict'>

print(type(response.cookies), response.cookies)#cookie <class 'requests.cookies.RequestsCookieJar'>

print(type(response.url), response.url)#请求的url <class 'str'>

print(type(response.history), response.history)  # 访问的历史记录 <class 'list'>
2、状态码判断
#coding:utf8

import requests

response = requests.get('http://httpbin.org')

if not response.status_code == requests.codes.ok:#requests.codes.ok等价于200

    pass

else:

    print('Request Successfully')
3、文件上传
#coding:utf8

import requests

files = {

    'file': open('image.gif', 'rb')  # file可自定义

}

response = requests.post('http://httpbin.org/post', files=files)

print(response.text)
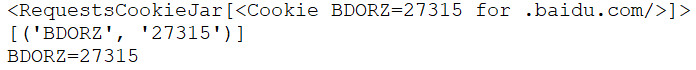
4、获取cookies
#coding:utf8

import requests

response = requests.get('http://www.baidu.com')

print(response.cookies)

print(response.cookies.items())  # [('BDORZ', '27315')]

for key, value in response.cookies.items():

    print(key + '=' + value)
5、会话维持:模拟登录(相当于一个浏览器在请求)
#coding:utf8

import requests

s = requests.Session()

s.get('http://httpbin.org/cookies/set/BDORZ/123456')

response = s.get('http://httpbin.org/cookies')

print(response.text)
6、证书验证
#coding:utf8

import requests

response = requests.get('https://www.12306.cn')

print(response.status_code)
#coding:utf8

import requests, urllib3

urllib3.disable_warnings()  # 消除警报信息

response = requests.get('https://www.12306.cn', verify=False)  # verify默认是True

print(response.status_code)  # 没有进行证书验证,有警报信息,
7、指定证书
#coding:utf8

import requests

response = requests.get('https://www.12306.cn', cert={'/path/server.crt', '/path/key'})

print(response.status_code)
8、代理的设置
#coding:utf8

import requests

proxies = {

    'http': 'http://127.0.0.1:9743',

    'https': 'https://127.0.0.1:9743'

}

response = requests.get('https://www.taobao.com', proxies=proxies)

print(response.status_code)
9、代理的设置(存在用户名和密码的情况下)
#coding:utf8

import requests

proxies = {

    'http': 'http://user:password@127.0.0.1:9743',

    'https': 'https://user:password@127.0.0.1:9743'

}

response = requests.get('https://www.taobao.com', proxies=proxies)

print(response.status_code)
10、socks代理
import requests

proxies = {

    'http': 'socks5://127.0.0.1:9743',

    'https': 'socks5://127.0.0.1:9743'

}

response = requests.get('https://www.taobao.com', proxies=proxies)

print(response.status_code)
11、超时设置
#coding:utf8

import requests

response = requests.get('http://httpbin.org', timeout=1)

print(response.status_code)
12、认证设置
遇到401错误,即:请求被禁止,需要加上auth参数
#coding:utf8

import requests

from requests.auth import HTTPBasicAuth

response = requests.get('https://api.github.com/user', auth=HTTPBasicAuth('user', 'pass'))

#response = requests.get('https://api.github.com/user', auth=('user', 'pass'))

print(response.status_code)
13、异常处理
#coding:utf8

import requests

from requests.exceptions import ReadTimeout, HTTPError, RequestException, ConnectionError

try:

    response = requests.get('http://httpbin.org', timeout=0.3)

    print(response.status_code)

except ReadTimeout:

    print('Timeout')

except HTTPError:

    print('Http Error')

# except ConnectionError:

#     print('Connection Error')

except RequestException:

    print('Request Error ')
requests库详解 --Python3的更多相关文章
- python WEB接口自动化测试之requests库详解
由于web接口自动化测试需要用到python的第三方库--requests库,运用requests库可以模拟发送http请求,再结合unittest测试框架,就能完成web接口自动化测试. 所以笔者今 ...
- Python爬虫:requests 库详解,cookie操作与实战
原文 第三方库 requests是基于urllib编写的.比urllib库强大,非常适合爬虫的编写. 安装: pip install requests 简单的爬百度首页的例子: response.te ...
- python接口自动化测试之requests库详解
前言 说到python发送HTTP请求进行接口自动化测试,脑子里第一个闪过的可能就是requests库了,当然python有很多模块可以发送HTTP请求,包括原生的模块http.client,urll ...
- 爬虫学习--Requests库详解 Day2
什么是Requests Requests是用python语言编写,基于urllib,采用Apache2 licensed开源协议的HTTP库,它比urllib更加方便,可以节约我们大量的工作,完全满足 ...
- Python爬虫学习==>第八章:Requests库详解
学习目的: request库比urllib库使用更加简洁,且更方便. 正式步骤 Step1:什么是requests requests是用Python语言编写,基于urllib,采用Apache2 Li ...
- urllib库详解 --Python3
相关:urllib是python内置的http请求库,本文介绍urllib三个模块:请求模块urllib.request.异常处理模块urllib.error.url解析模块urllib.parse. ...
- Python爬虫系列-Requests库详解
Requests基于urllib,比urllib更加方便,可以节约我们大量的工作,完全满足HTTP测试需求. 实例引入 import requests response = requests.get( ...
- python的requests库详解
快速上手 迫不及待了吗?本页内容为如何入门 Requests 提供了很好的指引.其假设你已经安装了 Requests.如果还没有,去安装一节看看吧. 首先,确认一下: Requests 已安装 Req ...
- requests库详解
import requests #实例引入 # response = requests.get('http://www.baidu.com') # print(type(response)) # pr ...
随机推荐
- PHP filter_var 函数用法
先介绍下PHP Filter PHP手册地址:http://php.net/manual/zh/ref.filter.php PHP 过滤器用于对来自非安全来源的数据(比如用户输入)进行验证和过滤. ...
- C#保存日志文件到txt中,可追加保存,定时删除最后一次操作半年前日志文件
/// <summary> /// 输出指定信息到文本文件 /// </summary> /// <param name="msg">输出信息& ...
- 在绘图的时候import matplotlib.pyplot as plt报错:ImportError: No module named '_tkinter', please install the python-tk package
在绘图的时候import matplotlib.pyplot as plt报错:ImportError: No module named '_tkinter', please install the ...
- 旷视研究院Detection组负责人
http://www.skicyyu.org/ https://zhuanlan.zhihu.com/p/61910297 俞刚,旷视研究院Detection组负责人.2014年博士毕业于新加坡南洋理 ...
- HVP plan
HVP,hier verification plan,建立整个验证的plan,在验证后期,通过vcs的coverage db可以直接进行反标, 包括反标code coverage,function c ...
- (转)批量插入sql语句
为了减少数据库连接的I/O开销,一般会把多条数据插入放在一条SQL语句中一次执行.1.INSERT INTO TABLE(col1, col2) VALUES(val11, val12), (val2 ...
- Java-对象及变量的并发访问小结
1)多线程环境下,方法内的变量是线程安全的 2)多个线程同时处理一个实例,这个实例内的变量是不安全的 3)不同线程中注入同一个类的不同实例,实例中的变量是安全的 4)Synchronized获取到的锁 ...
- 解决SVN提交和更新代码冲突?
解决冲突有三种选择: 1.放弃自己的更新,使用svn revert(回滚),然后提交.在这种方式下不需要使用svn resolved(解决) 2.放弃自己的更新,使用别人的更新.使用最新获取的版本覆盖 ...
- psql 存储过程
--添加人员和虹膜注册信息 CREATE OR REPLACE FUNCTION AddPersonInfoAndIrisEnrollInfo(personName character, workSn ...
- php高精度计算问题
从事金融行业,资金运算频繁,这里说下我遇到的坑....稍不留神,用户资金可能损失几十万,甚至更可怕......直接上实例吧: javascript 0.1 + 0.2 为啥不等于 0.3 ? (正确结 ...