
20.Scrapy日常练手
1.创建爬虫项目:
scrapy startproject tutorial
2.创建 spider
cd tutorial
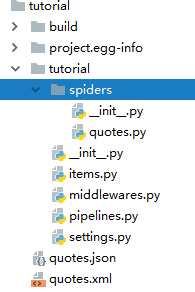
scrapy genspider quotes quotes.toscrape.com
如下图:
3.
quotes.py
___________________________________________________________________________
 # -*- coding: utf-8 -*-

 import scrapy

 from tutorial.items import TutorialItem

 import logging

 class QuotesSpider(scrapy.Spider):

     name = 'quotes'

     allowed_domains = ['quotes.toscrape.com']

     start_urls = ['http://quotes.toscrape.com/']

     def parse(self, response):

         quotes=response.css('.quote')

         for quote in quotes:

             item=TutorialItem()

             #内容

             item['text']=quote.css('.text::text').extract_first()

             #作者

             item['author']=quote.css('.author::text').extract_first()

             #标签

             item['tags']=quote.css('.tags .tag::text').extract_first()

             yield item

         #下一页

         next=response.css('.pager .next a::attr("href")').extract_first()

         url=response.urljoin(next)

         yield scrapy.Request(url=url,callback=self.parse)
items.py
________________________________________________________________________
 # -*- coding: utf-8 -*-

 # Define here the models for your scraped items

 #

 # See documentation in:

 # https://doc.scrapy.org/en/latest/topics/items.html

 import scrapy

 class TutorialItem(scrapy.Item):

     # define the fields for your item here like:

     # name = scrapy.Field()

     text=scrapy.Field()

     author=scrapy.Field()

     tags=scrapy.Field()

 piplines.py
_________________________________________________________________________
 # -*- coding: utf-8 -*-

 # Define your item pipelines here

 #

 # Don't forget to add your pipeline to the ITEM_PIPELINES setting

 # See: https://doc.scrapy.org/en/latest/topics/item-pipeline.html

 from scrapy.exceptions import DropItem

 import pymysql

 class TutorialPipeline(object):

     # def __init__(self):

     #     self.limit=50

     # def process_item(self, item, spider):

     #     if  item['text']:

     #         if len(item['text'])>self.limit:

     #             item['text']=item['text'][0:self.limit].rstrip()+'...'

     #         return item

     #     else:

     #         return DropItem('Missing Text')

     def __init__(self):

         pass

     def open_spider(self, spider):

         self.my_conn = pymysql.connect(

             host = '192.168.113.129',

             port = 3306,

             database = 'datas',

             user = 'root',

             password = '',

             charset = 'utf8'

         )

         self.my_cursor = self.my_conn.cursor()

     def process_item(self,item, spider):

         dict(item)

         insert_sql = "insert into quotes(author,tags,text) values(%s,%s,%s)"

         self.my_cursor.execute(insert_sql,[item['author'],item['tags'],item['text']])

         return  item

     def close_spider(self, spider):

         self.my_conn.commit()

         self.my_cursor.close()

         self.my_conn.close()
setting.py
___________________________________________________________________________
# Obey robots.txt rules

ROBOTSTXT_OBEY = True

ITEM_PIPELINES = {

   'tutorial.pipelines.TutorialPipeline': 200,

}
代码配置完:

保存文件格式
scrapy crawl  quotes -o quotes.xml

scrapy crawl  quotes -o quotes.csv
20.Scrapy日常练手的更多相关文章
- 整理了适合新手的20个Python练手小程序
100个Python练手小程序,学习python的很好的资料,覆盖了python中的每一部分,可以边学习边练习,更容易掌握python. 本文附带基础视频教程:私信回复[基础]就可以获取的 [程序1] ...
- 20个Java练手项目,献给嗜学如狂的人
给大家推荐一条由浅入深的JAVA学习路径,首先完成 Java基础.JDK.JDBC.正则表达式等基础实验,然后进阶到 J2SE 和 SSH 框架学习.最后再通过有趣的练手项目进行巩固. JAVA基础 ...
- 10个Python基础练习项目,你可能不会想到练手教程还这么有趣
美国20世纪最重要的实用主义哲学家约翰·杜威提出一个学习方法,叫做:Learning By Doing,在实践中精进.胡适.陶行知.张伯苓.蒋梦麟等都曾是他的学生,杜威的哲学也影响了蔡元培.晏阳初等人 ...
- Python练手项目:20行爬取全王者全英雄皮肤
引言 王者荣耀大家都玩过吧,没玩过的也应该听说过,作为时下最火的手机MOBA游戏,咳咳,好像跑题了.我们今天的重点是爬取王者荣耀所有英雄的所有皮肤,而且仅仅使用20行Python代码即可完成. ...
- 70个Python练手项目列表(都有完整教程)
前言: 不管学习那门语言都希望能做出实际的东西来,这个实际的东西当然就是项目啦,不用多说大家都知道学编程语言一定要做项目才行. 这里整理了70个Python实战项目列表,都有完整且详细的教程,你可以从 ...
- webpack练手项目之easySlide(三):commonChunks(转)
Hello,大家好. 在之前两篇文章中: webpack练手项目之easySlide(一):初探webpack webpack练手项目之easySlide(二):代码分割 与大家分享了webpack的 ...
- webpack练手项目之easySlide(二):代码分割(转)
在上一篇 webpack练手项目之easySlide(一):初探webpack 中我们一起为大家介绍了webpack的基本用法,使用webpack对前端代码进行模块化打包. 但是乍一看webpack ...
- webpack练手项目之easySlide(一):初探webpack (转)
最近在学习webpack,正好拿了之前做的一个小组件,图片轮播来做了下练手,让我们一起来初步感受下webpack的神奇魅力. webpack是一个前端的打包管理工具,大家可以前往:http:/ ...
- NYOJ 323 Drainage Ditches 网络流 FF 练手
Drainage Ditches 时间限制:1000 ms | 内存限制:65535 KB 难度:4 描述 Every time it rains on Farmer John's fields, ...
随机推荐
- NeighboringCellInfo.aidl
在src下先建立包名为android.telephony(右键src > new > package,create package-info.java打钩),然后右键刚建的android. ...
- matplotlib 双y轴绘制及合并图例
关键函数:twinx() refer to: https://www.cnblogs.com/Atanisi/p/8530693.html
- 无法对 数据库'XXXXX' 执行 删除,因为它正用于复制
无法对 数据库'XXXXX' 执行 删除,因为它正用于复制. (.Net SqlClient Data Provider) 使用以下方式一般可以解决 sp_removedbreplication 'X ...
- 实战:mysql检查物理磁盘中的二进制日志文件是否有丢失
版权声明:日常札记,乐于分享 https://blog.csdn.net/yangzhawen/article/details/32103555 场景:有时候由于磁盘损坏或人为原因错误删除了磁盘中的二 ...
- ImageCollection
https://documentation.devexpress.com/#WindowsForms/clsDevExpressUtilsImageCollectiontopic The collec ...
- Spring Cloud Netflix项目进入维护模式
任何项目都有其生命周期,Spring Could Netflix也不例外,官宣已进入维护模式,如果在新项目开始考虑技术选型时要考虑到这点风险,并考虑绕道的可能性. 原创: itmuch IT牧场 这 ...
- nginx 知识点
全部指令目录(淘宝翻译):http://tengine.taobao.org/nginx_docs/cn/docs/dirindex.html nginx 命令语法: nginx -s [signal ...
- redis 报错及解决
报错: (error) MISCONF Redis is configured to save RDB snapshots, but it is currently not able to persi ...
- JUC集合之 LinkedBlockingQueue
LinkedBlockingQueue介绍 LinkedBlockingQueue是一个单向链表实现的阻塞队列.该队列按 FIFO(先进先出)排序元素,新元素插入到队列的尾部,并且队列获取操作会获得位 ...
- Spring本质-AOP
一.我们在做系统设计的时候,一个非常重要的工作就是把一个大系统做分解, 按业务功能分解成一个个低耦合.高内聚的模块,就像这样: 但是分解以后就会发现有些很有趣的东西, 这些东西是通用的,或者是跨越多个 ...