
SolrServer SolrRequest
SolrServer实现类

HttpSolrServer
HttpSolrServer uses the Apache Commons HTTPClient to connect to solr.
HttpSolrServer is thread-safe and if you are using the following constructor, you must re-use the same instance for all request.
if instances are created on the fly, it can cause a connection leak. The recommended practice is to keep a static instance of HttpSolrServer per solr server url and share it for all requests.
LBHttpSolrServer
LBHttpSolrServer or "LoadBalanced HttpSolrServer" is a load balancing wrapper around org.apache.solr.client.solrj.impl.HttpSolrServer. This is useful when you have multiple SolrServers and the requests need to be Load Balanced among them. Do NOT use this class for indexing in master/slave scenarios since documents must be sent to the correct master; no inter-node routing is done. In SolrCloud (leader/replica) scenarios, this class may be used for updates since updates will be forwarded to the appropriate leader. Also see the wiki page.
It offers automatic failover when a server goes down and it detects when the server comes back up.【容灾】
Load balancing is done using a simple round-robin on the list of servers.【负载均衡】
If a request to a server fails by an IOException due to a connection timeout or read timeout then the host is taken off the list of live servers and moved to a 'dead server list' and the request is resent to the next live server. This process is continued till it tries all the live servers. If at least one server is alive, the request succeeds, and if not it fails.
 SolrServer lbHttpSolrServer = new LBHttpSolrServer("http://host1:8080/solr/","http://host2:8080/solr","http://host2:8080/solr");

 //or if you wish to pass the HttpClient do as follows

 httpClient httpClient =  new HttpClient();

 SolrServer lbHttpSolrServer = new LBHttpSolrServer(httpClient,"http://host1:8080/solr/","http://host2:8080/solr","http://host2:8080/solr");
This detects if a dead server comes alive automatically. The check is done in fixed intervals in a dedicated thread. This interval can be set using setAliveCheckInterval , the default is set to one minute.【容灾,自感知节点复活】
When to use this?
This can be used as a software load balancer when
you do not wish to setup an external load balancer. Alternatives to this code
are to use a dedicated hardware load balancer or using Apache httpd with
mod_proxy_balancer as a load balancer. See Load balancing on
Wikipedia
CloudSolrServer
SolrJ client class to communicate with SolrCloud. Instances of this class communicate with Zookeeper to discover Solr endpoints for SolrCloud collections, and then use the LBHttpSolrServer to issue requests. This class assumes the id field for your documents is called 'id' - if this is not the case, you must set the right name with setIdField(String).
-- SolrJ includes a 'smart' client for SolrCloud, which is ZooKeeper aware. This means that your Java application only needs to know about your Zookeeper instances, and not where your Solr instances are, as this can be derived from Zookeeper.
ConcurrentUpdateSolrServer
ConcurrentUpdateSolrServer buffers all added documents and writes them into open HTTP connections. This class is thread safe. Params from UpdateRequest are converted to http request parameters. When params change between UpdateRequests a new HTTP request is started. Although any SolrServer request can be made with this implementation, it is only recommended to use ConcurrentUpdateSolrServer with /update requests. The class HttpSolrServer is better suited for the query interface.
SolrServer主要方法
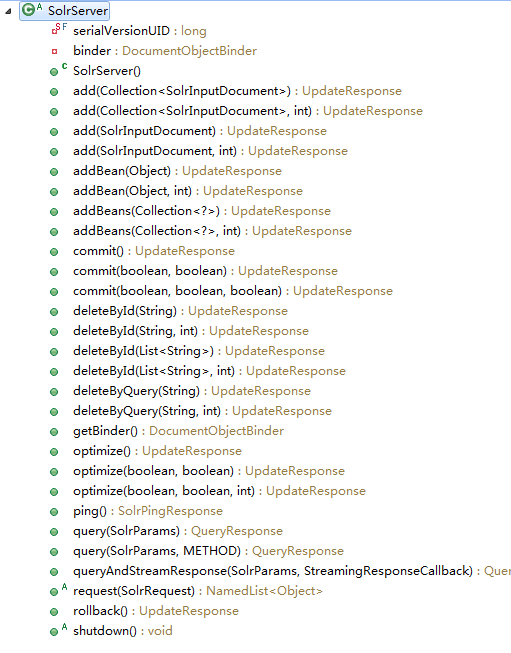
主要方法add、delete、query、commit、optimize等。
这些方法都是根据请求构建对应的SolrRequest,然后执行SolrRequest的process方法。
public abstract SolrResponse process( SolrServer server ) throws SolrServerException, IOException;
SolrRequest的类结构

例如,QueryRequest的process重载:
@Override

  public QueryResponse process( SolrServer server ) throws SolrServerException

  {

    try {

      long startTime = TimeUnit.MILLISECONDS.convert(System.nanoTime(), TimeUnit.NANOSECONDS);

      QueryResponse res = new QueryResponse( server.request( this ), server );

      long endTime = TimeUnit.MILLISECONDS.convert(System.nanoTime(), TimeUnit.NANOSECONDS);

      res.setElapsedTime(endTime - startTime);

      return res;

    } catch (SolrServerException e){

      throw e;

    } catch (SolrException s){

      throw s;

    } catch (Exception e) {

      throw new SolrServerException("Error executing query", e);

    }

  }
-----------------------------
http://wiki.apache.org/solr/Solrj
http://wiki.apache.org/solr/LBHttpSolrServer
SolrServer SolrRequest的更多相关文章
- Solr入门之SolrServer实例化方式
随着solr版本的不断升级, 差异越来越大, 从以前的 solr1.2 到现在的 solr4.3, 无论是类还是功能都有很大的变换, 为了能及时跟上新版本的步伐, 在此将新版本的使用做一个简单的入门说 ...
- solrserver实例化
以下是httpClient实例化方式,需要tomcat运行Solr服务 1.ConcurrentUpdateSolrServer实例化SolrServer,该类实例化多用于更新删除索引操作 Concu ...
- Solr 02 - 最详细的solrconfig.xml配置文件解读
目录 1 luceneMatchVersion - 指定Lucene版本 2 lib - 配置扩展jar包 3 dataDir - 索引数据路径 4 directoryFactory - 索引存储工厂 ...
- solr中facet及facet.pivot理解(整合两篇文章保留参考)
Facet['fæsɪt]很难翻译,只能靠例子来理解了.Solr作者Yonik Seeley也给出更为直接的名字:导航(Guided Navigation).参数化查询(Paramatic Searc ...
- solr中facet及facet.pivot理解
Facet['fæsɪt]很难翻译,只能靠例子来理解了.Solr作者Yonik Seeley也给出更为直接的名字:导航(Guided Navigation).参数化查询(Paramatic Searc ...
- 8.solr学习速成之FacetPivot
什么是Facet.pivot Facet.pivot就是按照多个维度进行分组查询,是Facet的加强,在实际运用中经常用到,一个典型的例子就是商品目录树 NamedList解释: NamedList ...
- solr开发之基本操作
package zr.com.util; import java.io.IOException; import java.util.List; import java.util.Map; import ...
- (三)Solrj4到Solrj5的升级之路
(三)Solrj4到Solrj5的升级之路 Solr5发布了,带来了许多激动人心的新特性,但Solrj的许多接口也发生了变化,升级是痛苦的,但也是必须的,下面就赶紧来看看有哪些代码需要升级吧. 变化1 ...
- Solr分组查询
项目中需要实时的返回一下统计的东西,因此就要进行分组,在获取一些东西,代码拿不出来,因此分享一篇,还是很使用的. facet搜索 /** * * 搜索功能优化-关键词搜索 * 搜索范围:商品名称.店 ...
随机推荐
- PTA——输出各位数字
PTA 7-37 输出整数各位数字 方法1: #include <stdio.h> #define N 10000 int main(){ long n, temp; ; scanf(&q ...
- Windows共享设置
Windows文件共享默认是开启的,任何用户都可以方便的设置共享目录.那么如何关闭并禁止呢. ====打开或关闭网上邻居的网络发现:1. 右键单击,网上邻居,弹出菜单选择:属性,打开网络和共享中心界面 ...
- Python基础-使用paramiko
一:简介 paramiko是用python语言写的一个模块,遵循SSH2协议,支持以加密和认证的方式,进行远程服务器的连接. 由于使用的是python这样的能够跨平台运行的语言,所以所有python支 ...
- hihocoder1490 Tree Restoration 模拟
There is a tree of N nodes which are numbered from 1 to N. Unfortunately, its edges are missing so w ...
- initrd in linux 2.6.32.27
2.6.32.27可以不指定initrd选项 如果指定initrd选项,则自动调用initrd内的linuxrc或init进行一切必要的初始化.Kernel启动参数全部会作为变量传递给这两个脚本.如r ...
- day 31 进程的其他方法 进程锁 进程队列
一.进程的其他方法 1. .name 进程名 (可指定) 2. .pid 进程号 3. os.getpid 在什么位置就是什么的进程号 4. .is ...
- Host does not support domain type kvm for virtualization type 'hvm' arch 'x86_64'
kvm创建虚拟机报错: qemu-img create -f qcow2 /tmp/centos.qcow2 10G virt-install --virt-type kvm --name cento ...
- IDEA各个版本激活(亲测有效,永久有效)(转)
之前使用的license server 老是失效,今天又失效了,于是乎,在强大的网上找到了永久激活的方式,有个网站专门提供注册码,但是很这激活码有一定的期限,到期之后再获取一次即可,灰常方便. 激活方 ...
- unicodedata.normalize()/使用strip()、rstrip()和lstrip()/encode和decode 笔记(具体可看 《Python Cookbook》3rd Edition 2.9~2.11)
unicodedata.normalize()清理字符串 # normalize()的第一个参数指定字符串标准化的方式,分别有NFD/NFC >>> s1 = 'Spicy Jala ...
- grep 正则问题 this version of PCRE is compiled without UTF support
问题 在使用grep -P,出现如下报错: grep: this version of PCRE is compiled without UTF support 原因 有些系统支持的正则规范不同. 解 ...