
es之分页
导入测试数据:
POST /_bulk
{ "create": { "_index": "us", "_type": "user", "_id": "1" }}
{ "email" : "john@smith.com", "name" : "John Smith", "username" : "@john" }
{ "create": { "_index": "us", "_type": "user", "_id": "2" }}
{ "email" : "mary@jones.com", "name" : "Mary Jones", "username" : "@mary" }
{ "create": { "_index": "us", "_type": "tweet", "_id": "3" }}
{ "date" : "2014-09-13", "name" : "Mary Jones", "tweet" : "Elasticsearch means full text search has never been so easy", "user_id" : 2 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "4" }}
{ "date" : "2014-09-14", "name" : "John Smith", "tweet" : "@mary it is not just text, it does everything", "user_id" : 1 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "5" }}
{ "date" : "2014-09-15", "name" : "Mary Jones", "tweet" : "However did I manage before Elasticsearch?", "user_id" : 2 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "6" }}
{ "date" : "2014-09-16", "name" : "John Smith", "tweet" : "The Elasticsearch API is really easy to use", "user_id" : 1 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "7" }}
{ "date" : "2014-09-17", "name" : "Mary Jones", "tweet" : "The Query DSL is really powerful and flexible", "user_id" : 2 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "8" }}
{ "date" : "2014-09-18", "name" : "John Smith", "user_id" : 1 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "9" }}
{ "date" : "2014-09-19", "name" : "Mary Jones", "tweet" : "Geo-location aggregations are really cool", "user_id" : 2 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "10" }}
{ "date" : "2014-09-20", "name" : "John Smith", "tweet" : "Elasticsearch surely is one of the hottest new NoSQL products", "user_id" : 1 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "11" }}
{ "date" : "2014-09-21", "name" : "Mary Jones", "tweet" : "Elasticsearch is built for the cloud, easy to scale", "user_id" : 2 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "12" }}
{ "date" : "2014-09-22", "name" : "John Smith", "tweet" : "Elasticsearch and I have left the honeymoon stage, and I still love her.", "user_id" : 1 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "13" }}
{ "date" : "2014-09-23", "name" : "Mary Jones", "tweet" : "So yes, I am an Elasticsearch fanboy", "user_id" : 2 }
{ "create": { "_index": "us", "_type": "tweet", "_id": "14" }}
{ "date" : "2014-09-24", "name" : "John Smith", "tweet" : "How many more cheesy tweets do I have to write?", "user_id" : 1 }
1:size+from浅分页
按照一般的查询流程来说,如果我想查询前10条数据:
· 1 客户端请求发给某个节点
· 2 节点转发给个个分片,查询每个分片上的前10条
· 3 结果返回给节点,整合数据,提取前10条
· 4 返回给请求客户端
那么当我想要查询第10条到第20条的数据该怎么办呢?这个时候就用到分页查询了。
浅分页可以理解为简单意义上的分页。它的原理很简单,就是查询前20条数据,然后截断前10条,只返回10-20的数据。
列子:查找第5条到第10条的数据:
GET /us/_search?pretty
{
"from" : 5 , "size" : 5
}
from**定义了目标数据的偏移值,size定义当前返回的事件数目**
"from" : 5 , "size" : 5意思就是说:从第5条开始,一直查询到第10条
【注意】这种浅分页只适合少量数据,因为随from增大,查询的时间就会越大,而且数据量越大,查询的效率指数下降
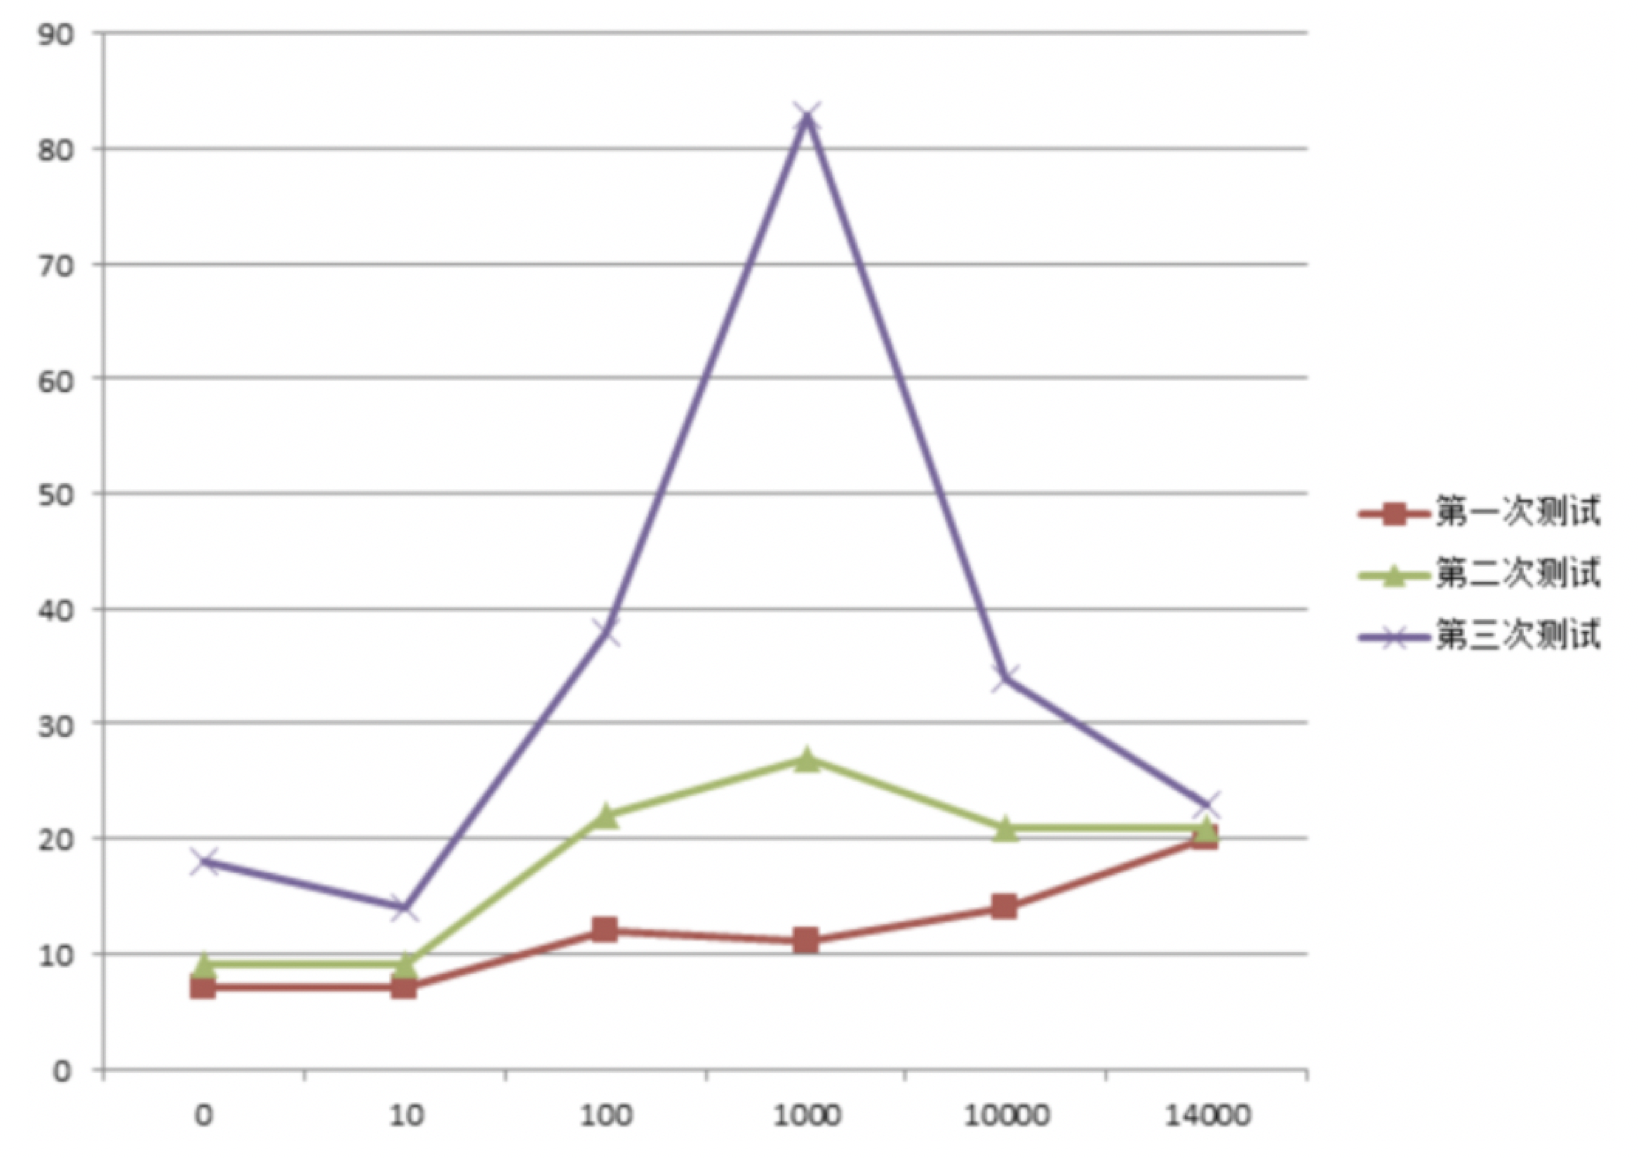
优点:from+size在数据量不大的情况下,效率比较高
缺点:在数据量非常大的情况下,from+size分页会把全部记录加载到内存中,这样做不但运行速递特别慢,而且容易让es出现内存不足而挂掉
2:scroll“深”分页
对于上面介绍的浅分页,当Elasticsearch响应请求时,它必须确定docs的顺序,排列响应结果。
如果请求的页数较少(假设每页20个docs), Elasticsearch不会有什么问题;
但是如果页数较大时,比如请求第20页,Elasticsearch不得不取出第1页到第20页的所有docs,再去除第1页到第19页的docs,得到第20页的docs。
解决的方式就是使用scroll,scroll就是维护了当前索引段的一份快照信息--缓存(这个快照信息是你执行这个scroll查询时的快照)。
可以把 scroll 分为初始化和遍历两步: 1、初始化时将所有符合搜索条件的搜索结果缓存起来,可以想象成快照; 2、遍历时,从这个快照里取数据;
例子:
1):初始化
GET us/_search?scroll=3m
{
"query": {"match_all": {}},
"size": 3
}
初始化的时候就像是普通的search一样 其中的scroll=3m代表当前查询的数据缓存3分钟 Size:3 代表当前查询3条数据
2):遍历
在遍历时候,拿到上一次遍历中的_scroll_id,然后带scroll参数,重复上一次的遍历步骤,知道返回的数据为空,就表示遍历完成
GET /_search/scroll
{
"scroll" : "1m",
"scroll_id" : "DnF1ZXJ5VGhlbkZldGNoBQAAAAAAADiVFmc0QlJqSzhnUUhXT3ZiQjl2c2h5N3cAAAAAAAA71RZyNFJxSU1vOFJZQ2VRcVBHLXJvb29nAAAAAAAAOJQWZzRCUmpLOGdRSFdPdmJCOXZzaHk3dwAAAAAAADiTFmc0QlJqSzhnUUhXT3ZiQjl2c2h5N3cAAAAAAAA4lhZnNEJSaks4Z1FIV092YkI5dnNoeTd3"
}

【注意】:每次都要传参数scroll,刷新搜索结果的缓存时间,另外不需要指定index和type
(不要把缓存的时时间设置太长,占用内存)
es之分页的更多相关文章
- ES学习之分片路由
本文主要内容: 1.路由一个文档到一个分片 2.新建.索引和删除请求 3.取回单个文档 4.局部单个文档 5.多文档模式 6.理解一下ES深度分页(from-size)的劣势 路由一个文档到一个分片 ...
- ES代码总结2
本文部分转载于: http://www.cnblogs.com/luxiaoxun/p/4869509.html ElasticSearch的基本用法与集群搭建 一.简介 ElasticSearch ...
- ES权威指南1
Elasticsearch学习笔记 一 本文版权归博客园和作者吴双本人共同所有 转载和爬虫请注明原文地址 www.cnblogs.com/tdws. 本文参考和学习资料 <ES权威指南> ...
- SpringBoot操作ES进行各种高级查询
SpringBoot整合ES 创建SpringBoot项目,导入 ES 6.2.1 的 RestClient 依赖和 ES 依赖.在项目中直接引用 es-starter 的话会报容器初始化异常错误,导 ...
- ES 调优查询亿级数据毫秒级返回!怎么做到的?--文件系统缓存
一道面试题的引入: 如果面试的时候碰到这样一个面试题:ElasticSearch(以下简称ES) 在数据量很大的情况下(数十亿级别)如何提高查询效率? 这个问题说白了,就是看你有没有实际用过 ES,因 ...
- es操作手册
0 _search查询数据时可以指定多个index和type GET /index1,index2/type1,type2/_search GET /_all/type1/_search 相当于查询全 ...
- es相关
1.es在数据量很大的情况下(数十亿级别)如何提高查询性能啊? 2.es生产集群的部署架构是什么?每个索引的数据量大概有多少?每个索引大概有多少个分片? 3.es的分布式架构原理能说一下么(es是如何 ...
- 面试系列九 es 提高查询效率
,es性能优化是没有什么银弹的,啥意思呢?就是不要期待着随手调一个参数,就可以万能的应对所有的性能慢的场景.也许有的场景是你换个参数,或者调整一下语法,就可以搞定,但是绝对不是所有场景都可以这样. 一 ...
- java整合Elasticsearch,实现crud以及高级查询的分页,范围,排序功能,泰文分词器的使用,分组,最大,最小,平均值,以及自动补全功能
//为index创建mapping,index相当于mysql的数据库,数据库里的表也要给各个字段创建类型,所以index也要给字段事先设置好类型: 使用postMan或者其他工具创建:(此处我使用p ...
随机推荐
- Ajax提交数据后,清空form表单
按钮不同,页面相同,还需要显示的数据不同,这里会由于页面的缓存问题,导致,每次点开这个页面显示的数据相同. 这不是我们想要的.这就需要清楚表单数据了. 如下: $('#myform')[0].rese ...
- CF1090H Linearization
传送门 先考虑什么样的串才符合条件.\(s_i=P(x\&i)\oplus b\),其实这里的\(b\)只能使得整体是否取反,所以可以先不管.然后考虑\(x\)的每个二进制位的对\(s_0\) ...
- win7系统下MongoDB 4.0.1的安装
环境: win7 - 64位系统 MongoDB下载地址: https://www.mongodb.com/download-center#community 版本: 4.0.1 安装步骤: 选择cu ...
- React-native 底部导航栏(二)
1.组件安装:npm install react-native-router-flux --save 2.定义菜单图片和文字: import React, { Component } from 're ...
- python实现观察者模式
python实现观察者模式 前言 有时,我们希望在一个对象的状态改变时更新另外一组对象.在MVC模式中有这样一个非 常常见的例子,假设在两个视图(例如,一个饼图和一个电子表格)中使用同一个模型的数据, ...
- java 过滤器filter使用案例
主要需要 过滤器类 和配置文件 1.过滤器类 SessionFilter package com.service; import javax.servlet.*; import javax.serv ...
- redis常见问题和解决方案
转载:https://www.cnblogs.com/aspirant/p/6820262.html [原创]那些年用过的Redis集群架构(含面试解析) redis常见问题和解决方案 持久化.主从问 ...
- MySQL8连接数据库
spring.datasource.driver-class-name=com.mysql.cj.jdbc.Driver spring.datasource.url=jdbc:mysql://127. ...
- Scala Nothing 从官方DOC翻译
Nothing is - together with scala.Null - at the bottom of Scala's type hierarchy. Scala中的Nothing和Null ...
- puppet工简介一
puppet简介一 puppet工作原理 puppet 是一个配置管理工具, 典型的, puppet 是一个 C/S 结构, 当然,这里的 C 可以有很多,因 此,也可以说是一个星型结构. 所有的 p ...