
But what exactly do we mean by "gets closer to"?
https://rdipietro.github.io/friendly-intro-to-cross-entropy-loss/
【将输入转化为输出:概率分布】
When we develop a model for probabilistic classification, we aim to map the model's inputs to probabilistic predictions, and we often train our model by incrementally adjusting the model's parameters so that our predictions get closer and closer to ground-truth probabilities.
In this post, we'll focus on models that assume that classes are mutually exclusive. For example, if we're interested in determining whether an image is best described as a landscape or as a house or as something else, then our model might accept an image as input and produce three numbers as output, each representing the probability of a single class.
During training, we might put in an image of a landscape, and we hope that our model produces predictions that are close to the ground-truth class probabilities y=(1.0,0.0,0.0)Ty=(1.0,0.0,0.0)T. If our model predicts a different distribution, say y^=(0.4,0.1,0.5)Ty^=(0.4,0.1,0.5)T, then we'd like to nudge the parameters so that y^y^ gets closer to yy.
【cross entropy 交叉熵 提供了一种量化的解决办法】
But what exactly do we mean by "gets closer to"? In particular, how should we measure the difference between y^y^ and yy?
This post describes one possible measure, cross entropy, and describes why it's reasonable for the task of classification.
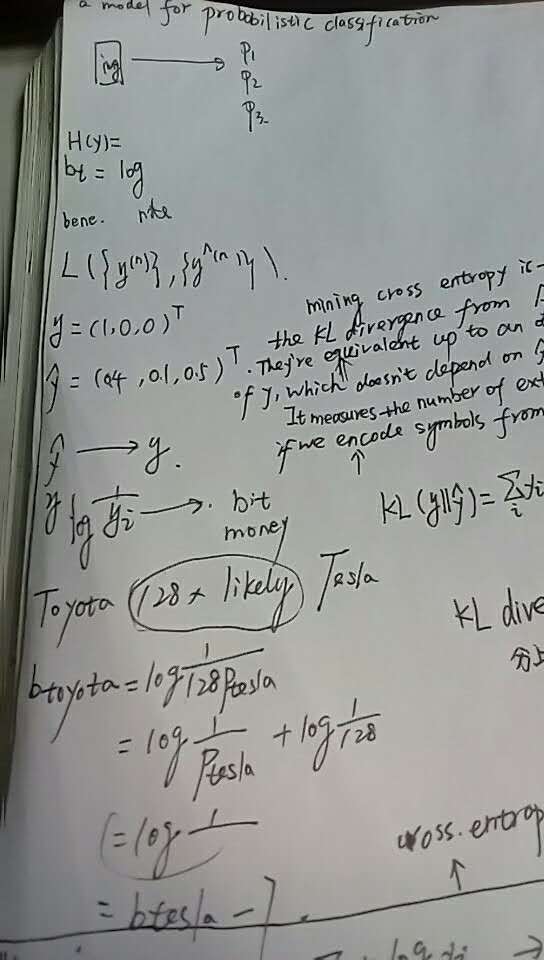
https://rdipietro.github.io/friendly-intro-to-cross-entropy-loss/

zh.wikipedia.org/wiki/相对熵
KL散度是两个概率分布P和Q差别的非对称性的度量。 KL散度是用来 度量使用基于Q的编码来编码来自P的样本平均所需的额外的位元数。 典型情况下,P表示数据的真实分布,Q表示数据的理论分布,模型分布,或P的近似分布。
en.wikipedia.org/wiki/Kullback–Leibler_divergence
In the context of machine learning, DKL(P‖Q) is often called the information gain achieved if P is used instead of Q. By analogy with information theory, it is also called the relative entropy of P with respect to Q. In the context of coding theory, DKL(P‖Q) can be constructed as measuring the expected number of extra bits required to codesamples from P using a code optimized for Q rather than the code optimized for P.
https://rdipietro.github.io/friendly-intro-to-cross-entropy-loss/
When we develop a probabilistic model over mutually exclusive classes, we need a way to measure the difference between predicted probabilities y^y^ and ground-truth probabilities yy, and during training we try to tune parameters so that this difference is minimized.
But what exactly do we mean by "gets closer to"?的更多相关文章
- CSS——关于z-index及层叠上下文(stacking context)
以下内容根据CSS规范翻译. z-index 'z-index'Value: auto | <integer> | inheritInitial: autoApplies to: posi ...
- 基于Ubuntu Hadoop的群集搭建Hive
Hive是Hadoop生态中的一个重要组成部分,主要用于数据仓库.前面的文章中我们已经搭建好了Hadoop的群集,下面我们在这个群集上再搭建Hive的群集. 1.安装MySQL 1.1安装MySQL ...
- Java
2016-12-17 21:10:28 吉祥物:Duke(公爵) Logo:咖啡(爪哇岛盛产咖啡) An overview of the software development proce ...
- Netty实现高性能RPC服务器优化篇之消息序列化
在本人写的前一篇文章中,谈及有关如何利用Netty开发实现,高性能RPC服务器的一些设计思路.设计原理,以及具体的实现方案(具体参见:谈谈如何使用Netty开发实现高性能的RPC服务器).在文章的最后 ...
- 基于Netty打造RPC服务器设计经验谈
自从在园子里,发表了两篇如何基于Netty构建RPC服务器的文章:谈谈如何使用Netty开发实现高性能的RPC服务器.Netty实现高性能RPC服务器优化篇之消息序列化 之后,收到了很多同行.园友们热 ...
- Netty构建分布式消息队列实现原理浅析
在本人的上一篇博客文章:Netty构建分布式消息队列(AvatarMQ)设计指南之架构篇 中,重点向大家介绍了AvatarMQ主要构成模块以及目前存在的优缺点.最后以一个生产者.消费者传递消息的例子, ...
- Fedora 24中的日志管理
Introduction Log files are files that contain messages about the system, including the kernel, servi ...
- [Mahout] 完整部署过程
概述 Mahout底层依赖Hadoop,部署Mahout过程中最困难的就是Hadoop的部署 本文假设用户本身没有进行Hadoop的部署,记述部署Mahout的过程 ...
- 【java】jstack
介绍 jstack用于打印出给定的java进程ID或core file或远程调试服务的Java堆栈信息,如果是在64位机器上,需要指定选项"-J-d64",Windows的jsta ...
- Underscore.js
概述 Underscore.js是一个很精干的库,压缩后只有4KB.它提供了几十种函数式编程的方法,弥补了标准库的不足,大大方便了JavaScript的编程.MVC框架Backbone.js就将这个库 ...
随机推荐
- 【转】Understanding Inversion of Control, Dependency Injection and Service Locator Print
原文:https://www.dotnettricks.com/learn/dependencyinjection/understanding-inversion-of-control-depende ...
- Nginx include和Nginx指令的使用
Nginx include和Nginx指令的使用 1.nginx include 主配置文件nginx.conf中指定包含其他扩展配置文件,从而简化nginx主配置文件,实现多个站点功能 [root@ ...
- ECSHOP生成缩略图模糊
原因是因为ECSHOP生成缩略图时,用到的函数 imagejpeg() 没有设置质量参数.注释:质量参数为可选项,范围从 0(最差质量,文件更小)到 100(最佳质量,文件最大).如果没有设置质量参 ...
- spring 配置多数据源 (案例)
*.properties配置: <!--数据连接配置一--> jdbc.type=mysqljdbc.driver=com.mysql.jdbc.Driverjdbc.url=jdbc:m ...
- Windows远程CentOS桌面
Windows远程CentOS桌面 1.VNC 服务器配置 1) 安装vncserver yum install -y vnc-server 2) 修改配置 vi /etc/sysconfig/vnc ...
- 【Scala-ML】怎样利用Scala构建并行机器学习系统
引言 在学习Scala的过程中,我发现其在构建大规模分布式计算系统上有与生俱来的特质. 其丰富的类型系统能够帮助编程设计提供非常好的信息隐藏和抽象,其monoids和monads概念利用Scala高阶 ...
- 【Excle数据透视表】如何重复显示行字段的项目标签
前提:该数据透视表以表格形式显示 解决办法: 通过报表布局设置"重复所有项目标签" 修改前样式 步骤 单击数据透视表中任意单元格→设计→报表布局→重复所有项目标签 修改后样式
- 【VBA】隐藏正在使用的工作簿
正在使用的工作簿,嫌窗口太多,不利于操作,想把窗口隐藏,该怎么做呢? Public Sub 隐藏正在使用的工作簿() Application.Visible = False MsgBox " ...
- kvo&kvc
Key Value Coding Key Value Coding是cocoa的一个标准组成部分,它能让我们可以通过name(key)的方式访问property, 不必调用明确的property ac ...
- MySQL 数据库备份种类以及经常使用备份工具汇总
mysql> flush tables with read lock; Query OK, 0 rows affected (0.00 sec) mysql> show master st ...