
hive
Hive Documentation
https://cwiki.apache.org/confluence/display/Hive/Home
2016-12-22 14:52:41
ANTLR (ANother Tool for Language Recognition)
2017-03-22 16:15:48
Hive Anatomy(解剖):https://www.slideshare.net/nzhang/hive-anatomy
Hive SQL的编译过程:http://tech.meituan.com/hive-sql-to-mapreduce.html
YSmart: Yet Another SQL-to-MapReduce Translator
http://web.cse.ohio-state.edu/hpcs/WWW/HTML/publications/papers/TR-11-7.pdf
https://github.com/YSmart/YSmart
2017-05-24 19:23:27
Add/Replace Columns Cascade
ALTER TABLE table_name [PARTITION partition_spec] -- (Note: Hive 0.14.0 and later) ADD|REPLACE COLUMNS (col_name data_type [COMMENT col_comment], ...) [CASCADE|RESTRICT] -- (Note: Hive 1.1.0 and later)The CASCADE|RESTRICT clause is available in Hive 1.1.0. ALTER TABLE ADD|REPLACE COLUMNS with CASCADE command changes the columns of a table's metadata, and cascades the same change to all the partition metadata. RESTRICT is the default, limiting column changes only to table metadata.
问题:hive分区表增加字段后,历史分区再重新插入数据,这些增加的字段在HDFS文件中有数据,但查询时仍然为空的问题。
问题的原因就是hive元数据没有更新,加上cascade参数,可以解决该问题。
2017-04-24 19:10:51
hive -v -e ""
-v,--verbose Verbose mode (echo executed SQL to the console) 冗长的/啰嗦的模式;在控制台打印被执行的SQL。
2017-01-21 10:37:40
Windowing and Analytics Functions
https://cwiki.apache.org/confluence/display/Hive/LanguageManual+WindowingAndAnalytics
Enhanced Aggregation, Cube, Grouping and Rollup
https://cwiki.apache.org/confluence/display/Hive/Enhanced+Aggregation%2C+Cube%2C+Grouping+and+Rollup
2017-02-24 09:13:10
public static enum ConfVars {

HIVE_WAREHOUSE_SUBDIR_INHERIT_PERMS("hive.warehouse.subdir.inherit.perms", true,

        "Set this to false if the table directories should be created\n" +

        "with the permissions derived from dfs umask instead of\n" +

        "inheriting the permission of the warehouse or database directory.")

}
2017-01-16 21:31:02
hive null 比较的问题
《Why NULL never compares false to anything in SQL》:https://www.xaprb.com/blog/2006/05/18/why-null-never-compares-false-to-anything-in-sql/
《Null (SQL)》:https://en.wikipedia.org/wiki/Null_(SQL)
1、where col <> '1.2' -- 会把null过滤掉

2、select

     case when '1.0.8' < null then '1.0.8' else null end as min_value -- null

    ,case when '1.0.8' > null then '1.0.8' else null end as max_value -- null

    ,case when '1.0.8' < null then null else '1.0.8' end as min_value -- '1.0.8'

    ,case when '1.0.8' > null then null else '1.0.8' end as max_value -- '1.0.8'

    ,case when null < '1.0.8' then null else '1.0.8' end as min_value -- '1.0.8'

    ,case when null > '1.0.8' then null else '1.0.8' end as max_value -- '1.0.8'

    ,case when null < '1.0.8' then '1.0.8' else null end as min_value -- null

    ,case when null > '1.0.8' then '1.0.8' else null end as max_value -- null

from temp.dual

;

3、select

     '1.0.8' < null -- null

    ,'1.0.8' > null -- null

    ,null < '1.0.8' -- null

    ,null > '1.0.8' -- null

from temp.dual

;

4、where col in ('','-',null) -- null不会被查出来

5、case when min_value in (null) then 'null_value' else min_value end -- null
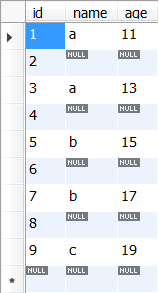
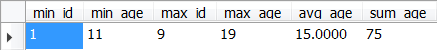
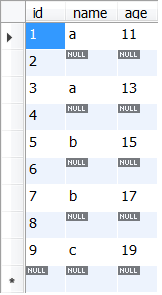
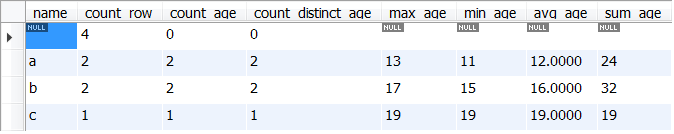
6、注意:count(col), min(col), max(col), avg(col), sum(col) 会忽略空置,count(*) 除外、count(*) 统计行数,例子如下:
SELECT * FROM temp.temp_test_table;
SELECT
COUNT(*) AS count_all,
COUNT(id) AS count_id,
COUNT(name) AS count_name,
COUNT(DISTINCT id) AS count_distinct_id,
COUNT(DISTINCT name) AS count_distinct_name,
COUNT(DISTINCT id, name) AS count_distinct_all
FROM
temp.temp_test_table;

SELECT
MIN(id) AS min_id,
MIN(age) AS min_age,
MAX(id) AS max_id,
MAX(age) AS max_age,
AVG(age) AS avg_age,
SUM(age) AS sum_age
FROM
temp.temp_test_table;
SELECT
id, name, age
FROM
temp.temp_test_table
GROUP BY id , name , age;
SELECT
name,
COUNT(*) AS count_row,
COUNT(age) AS count_age,
COUNT(DISTINCT age) AS count_distinct_age,
MAX(age) AS max_age,
MIN(age) AS min_age,
AVG(age) AS avg_age,
SUM(age) AS sum_age
FROM
temp.temp_test_table
GROUP BY name;
2016-12-15 22:59:16
UDF
《LanguageManual UDF》:https://cwiki.apache.org/confluence/display/Hive/LanguageManual+UDF
import java.net.MalformedURLException;

import java.net.URL;

import java.util.regex.Matcher;

import java.util.regex.Pattern;

public class TestUDFParseUrl {

    public static void main(String[] args) {

        try {

            URL url = new URL("http://le.com?a=1&b=2&c=3");

            String query = url.getQuery();

            System.out.println(query);//a=1&b=2&c=3

            Pattern p = Pattern.compile("(&|^)c=([^&]*)");

            System.out.println(p);//(&|^)c=([^&]*)

            Matcher m = p.matcher(query);

            if (m.find()) {

              System.out.println(m);//java.util.regex.Matcher[pattern=(&|^)c=([^&]*) region=0,11 lastmatch=&c=3]

              System.out.println(m.group(0));//&c=3

              System.out.println(m.group(1));//&

              System.out.println(m.group(2));//

            }

        } catch (MalformedURLException e) {

            e.printStackTrace();

        }

    }

}
2016-12-11 15:12:34
SerDe
问题:MapReduce写出的Hive Map类型字段,使用 hive SQL 查询时报错,但使用 hive --rcfilecat 命令可以查看。
经测试发现是hive表SerDe设置的问题,
当SerDe为 org.apache.hadoop.hive.serde2.columnar.LazyBinaryColumnarSerDe 时,使用 hive SQL 查询报错如下:
org.apache.hadoop.hive.ql.metadata.HiveException: java.lang.ArrayIndexOutOfBoundsException
当SerDe为 org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe 时,使用 hive SQL 查询报错如下:
java.lang.ClassCastException: org.apache.hadoop.hive.serde2.columnar.BytesRefArrayWritable cannot be cast to org.apache.hadoop.io.BinaryComparable
当SerDe为 'org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe' 时,使用 hive SQL 查询正常;
set;

/*

输出结果中关于SerDe的部分

hive.default.fileformat=TextFile

hive.default.rcfile.serde=org.apache.hadoop.hive.serde2.columnar.LazyBinaryColumnarSerDe

hive.default.serde=org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe

hive.fetch.output.serde=org.apache.hadoop.hive.serde2.DelimitedJSONSerDe

hive.script.serde=org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe

hive.serdes.using.metastore.for.schema=org.apache.hadoop.hive.ql.io.orc.OrcSerde,

                                       org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe,

                                       org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe,

                                       org.apache.hadoop.hive.serde2.dynamic_type.DynamicSerDe,

                                       org.apache.hadoop.hive.serde2.MetadataTypedColumnsetSerDe,

                                       org.apache.hadoop.hive.serde2.columnar.LazyBinaryColumnarSerDe,

                                       org.apache.hadoop.hive.ql.io.parquet.serde.ParquetHiveSerDe,

                                       org.apache.hadoop.hive.serde2.lazybinary.LazyBinarySerDe

system:java.class.path=/usr/local/hive/lib/hive-serde-1.2.1.jar

*/
--在以上的环境下测试

drop table if exists temp.temp_map_column_test_table

;

create table temp.temp_map_column_test_table

(

 props map<string,string>

)

STORED AS RCFile

;

desc formatted temp.temp_map_column_test_table

;

--SerDe Library: org.apache.hadoop.hive.serde2.columnar.LazyBinaryColumnarSerDe

drop table if exists temp.temp_map_column_test_table2

;

create table temp.temp_map_column_test_table2

(

 props map<string,string>

)

ROW FORMAT DELIMITED

  COLLECTION ITEMS TERMINATED BY ','

  MAP KEYS TERMINATED BY ':'

  LINES TERMINATED BY '\n'

STORED AS RCFile

;

desc formatted temp.temp_map_column_test_table2

;

--SerDe Library: org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe

drop table if exists temp.temp_map_column_test_table3

;

create table temp.temp_map_column_test_table3

(

 props map<string,string>

)

ROW FORMAT SERDE 'org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe'

STORED AS RCFile

;

desc formatted temp.temp_map_column_test_table3

;

--SerDe Library: org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe
--1、在建表语句中指定SerDe

ROW FORMAT SERDE 'org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe'

--2、修改环境变量

set hive.default.rcfile.serde=org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe

;

--3、修改表

alter table temp.temp_map_column_test_table

set serde 'org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe'

WITH SERDEPROPERTIES ('collected.delim' = ',', 'mapkey.delim' = ':', 'line.delim' = '\n' );

--or

alter table temp.temp_map_column_test_table

set serde 'org.apache.hadoop.hive.serde2.columnar.ColumnarSerDe';

alter table temp.temp_map_column_test_table

set SERDEPROPERTIES ('collected.delim' = ',', 'mapkey.delim' = ':', 'line.delim' = '\n' );
What is a SerDe?
- SerDe is a short name for "Serializer and Deserializer."
- Hive uses SerDe (and FileFormat) to read and write table rows.
- HDFS files --> InputFileFormat --> <key, value> --> Deserializer --> Row object
- Row object --> Serializer --> <key, value> --> OutputFileFormat --> HDFS files
Note that the "key" part is ignored when reading, and is always a constant when writing. Basically row object is stored into the "value".
One principle of Hive is that Hive does not own the HDFS file format. Users should be able to directly read the HDFS files in the Hive tables using other tools or use other tools to directly write to HDFS files that can be loaded into Hive through "CREATE EXTERNAL TABLE" or can be loaded into Hive through "LOAD DATA INPATH," which just move the file into Hive's table directory.
Note that org.apache.hadoop.hive.serde is the deprecated old SerDe library. Please look at org.apache.hadoop.hive.serde2 for the latest version.
https://cwiki.apache.org/confluence/display/Hive/DeveloperGuide#DeveloperGuide-HiveSerDe
2016-12-10 22:34:31
问题:分隔符和ASCII码控制字符导致 串列,串行
1、替换hive默认分隔符
regexp_replace(columnName,'\001|\n','')
2、替换ASCII码控制字符
控制字符:[\x00-\x1F\x7F]
regexp_replace(columnName, '[\\x00-\\x1F\\x7F]','')
0~31及127(共33个)是控制字符或通信专用字符(其余为可显示字符),如控制符:LF(换行)、CR(回车)、FF(换页)、DEL(删除)、BS(退格)、BEL(响铃)等;通信专用字符:SOH(文头)、EOT(文尾)、ACK(确认)等;ASCII值为8、9、10 和13 分别转换为退格、制表、换行和回车字符。它们并没有特定的图形显示,但会依不同的应用程序,而对文本显示有不同的影响。
hive默认分隔符
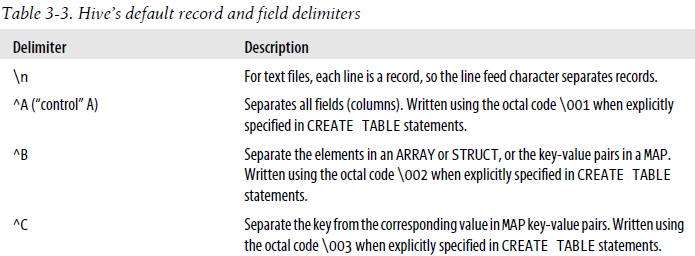
2016-10-11 21:59:01
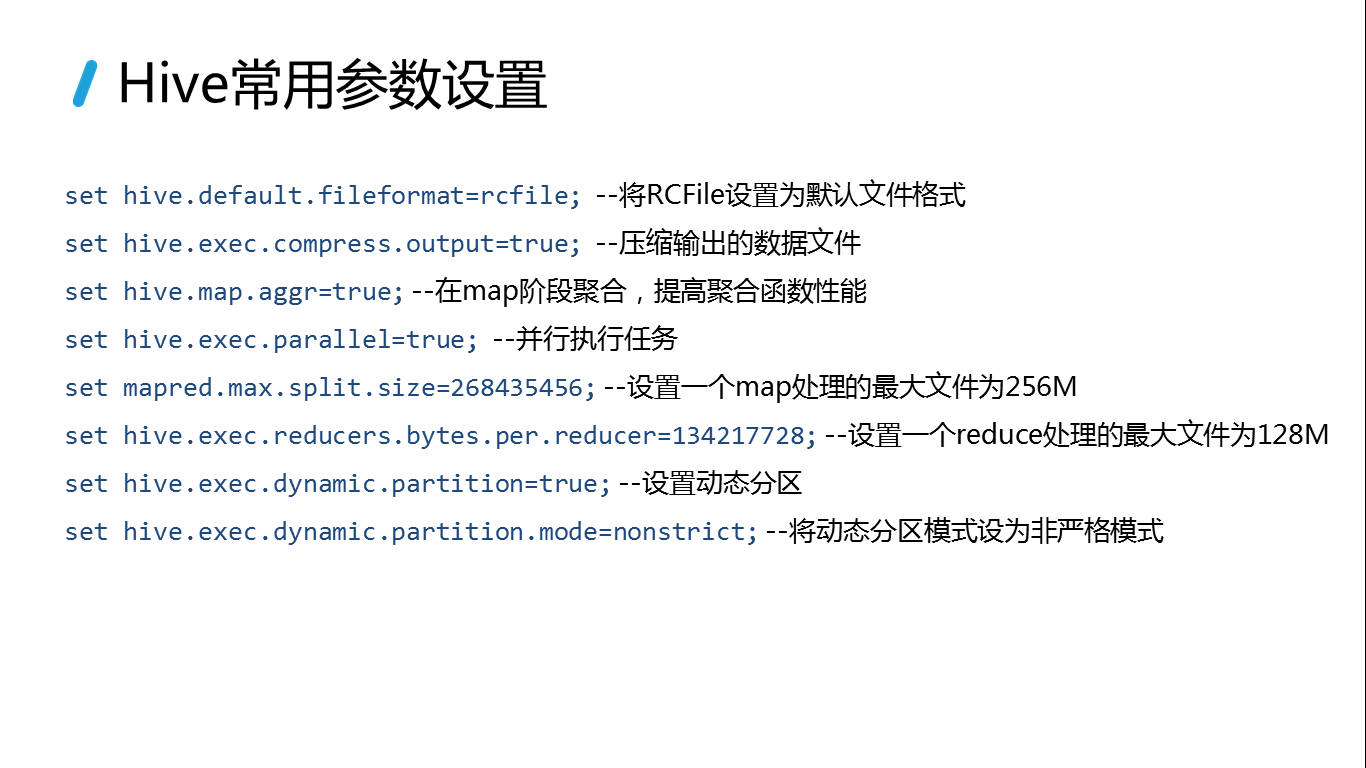
Hive常用参数设置
set hive.default.fileformat=rcfile; --将RCFile设置为默认文件格式

set hive.exec.compress.output=true; --压缩输出的数据文件

set hive.map.aggr=true; --在map阶段聚合,提高聚合函数性能

set hive.exec.parallel=true; --并行执行任务

set mapred.max.split.size=268435456; --设置一个map处理的最大文件为256M

set hive.exec.reducers.bytes.per.reducer=134217728; --设置一个reduce处理的最大文件为128M

set hive.exec.dynamic.partition=true; --设置动态分区

set hive.exec.dynamic.partition.mode=nonstrict; --将动态分区模式设为非严格模式

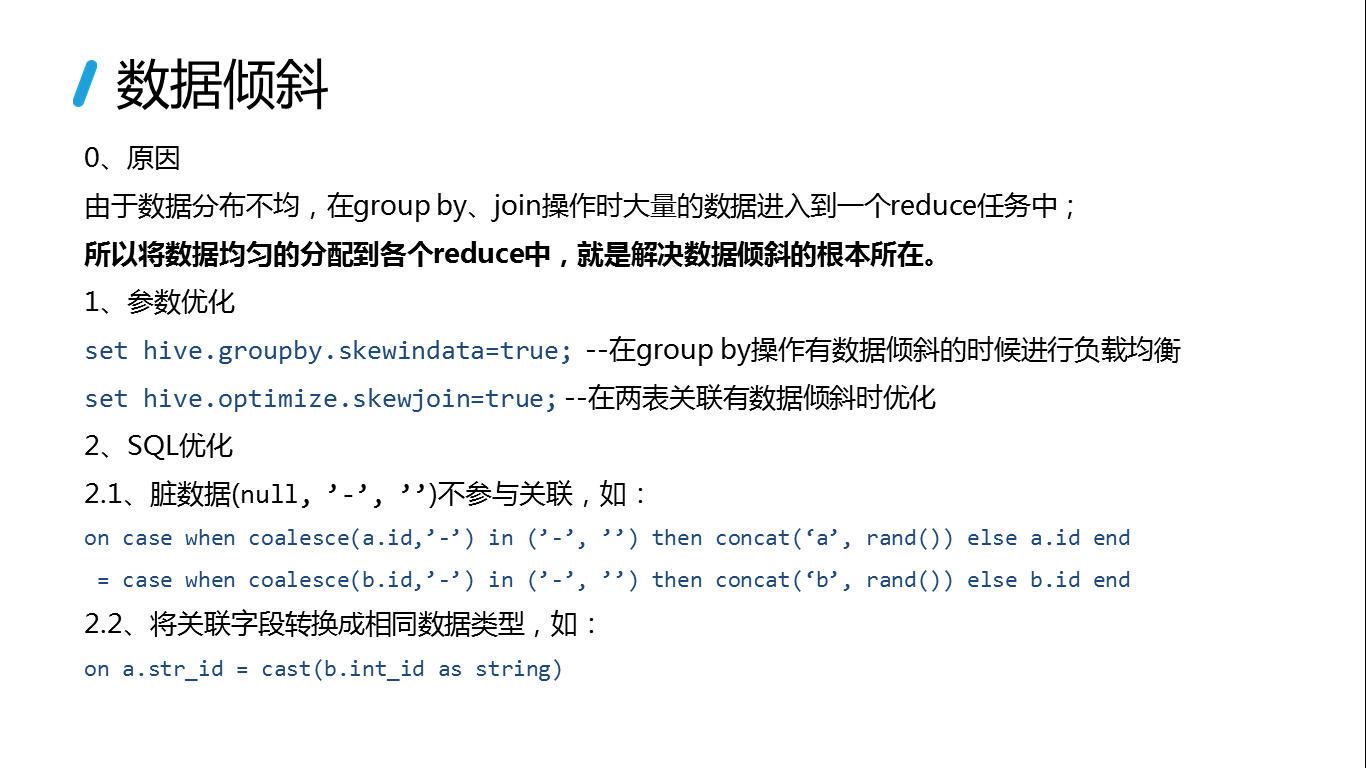
set hive.groupby.skewindata=true; --在group by操作有数据倾斜的时候进行负载均衡

set hive.optimize.skewjoin=true; --在两表关联有数据倾斜时优化
2016-11-13 20:06:57
Hive培训资料
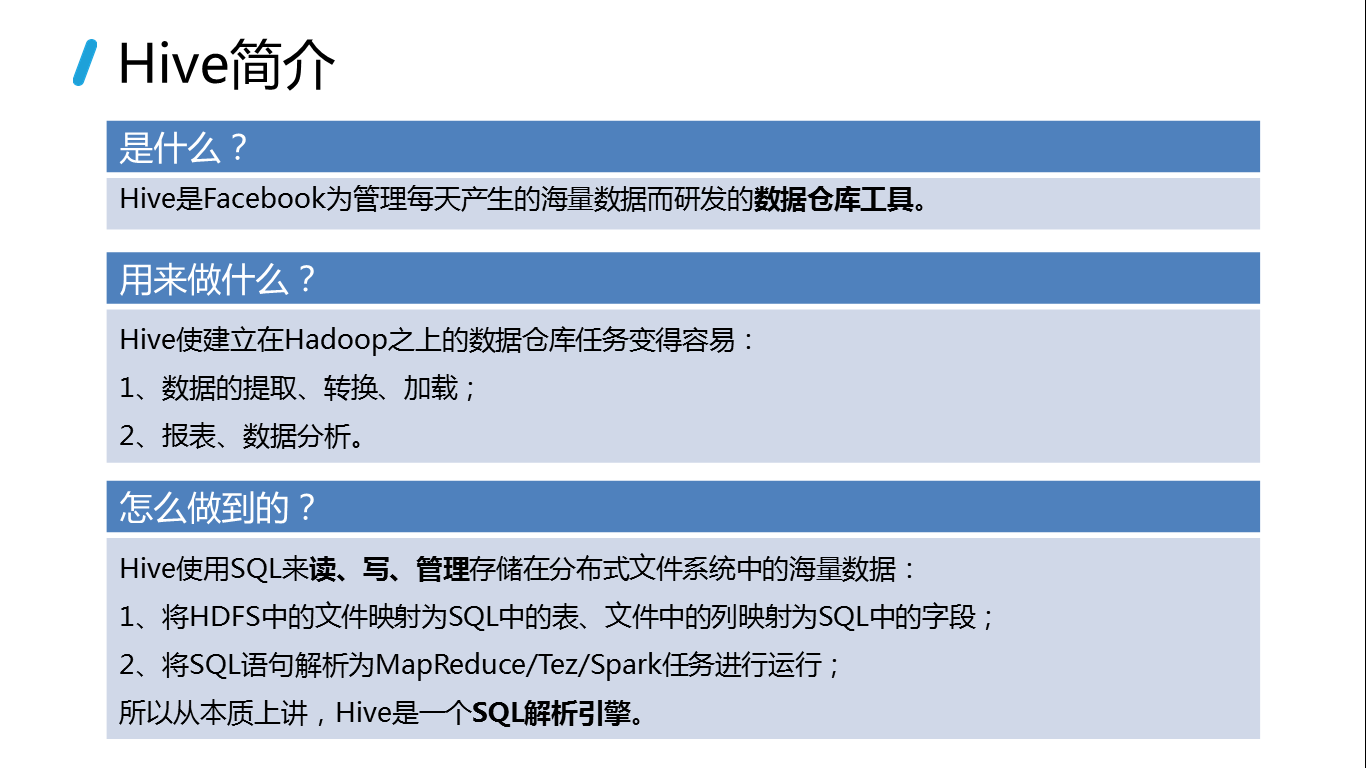
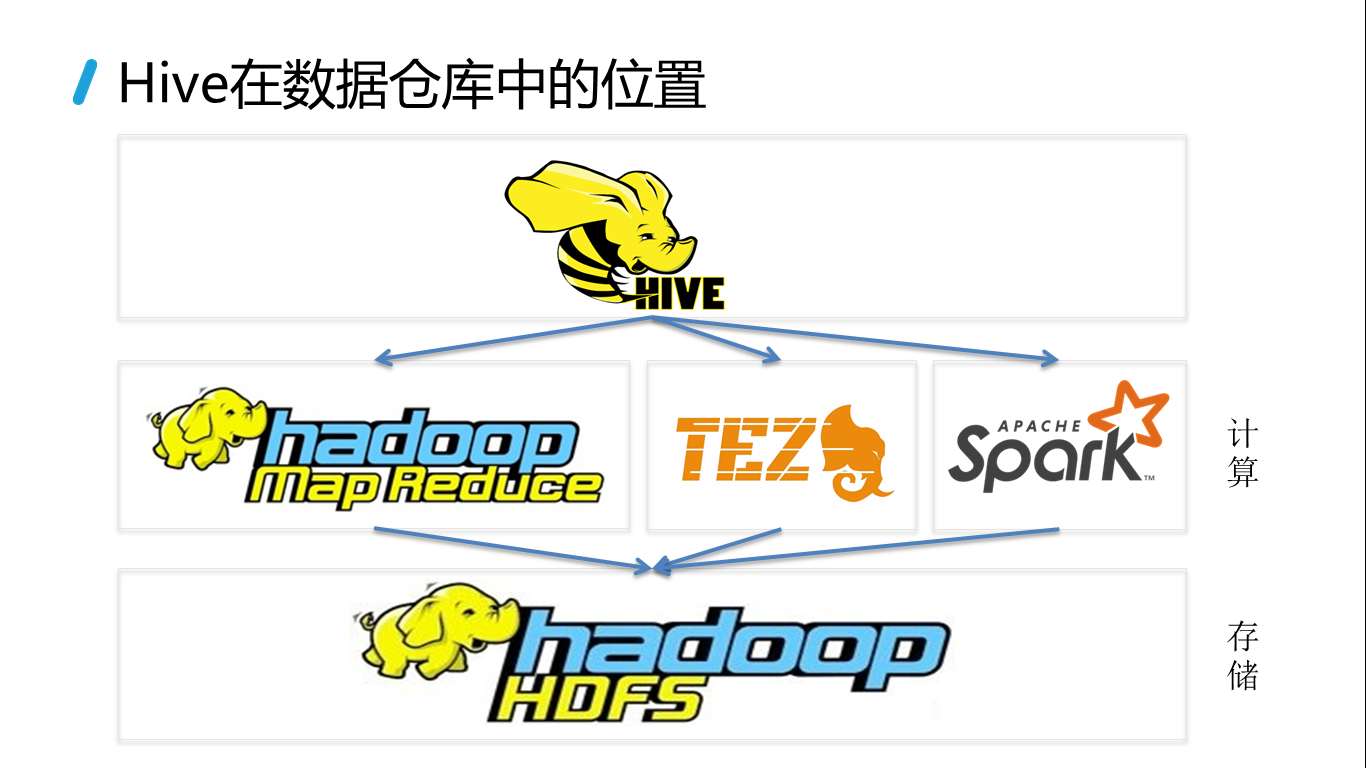
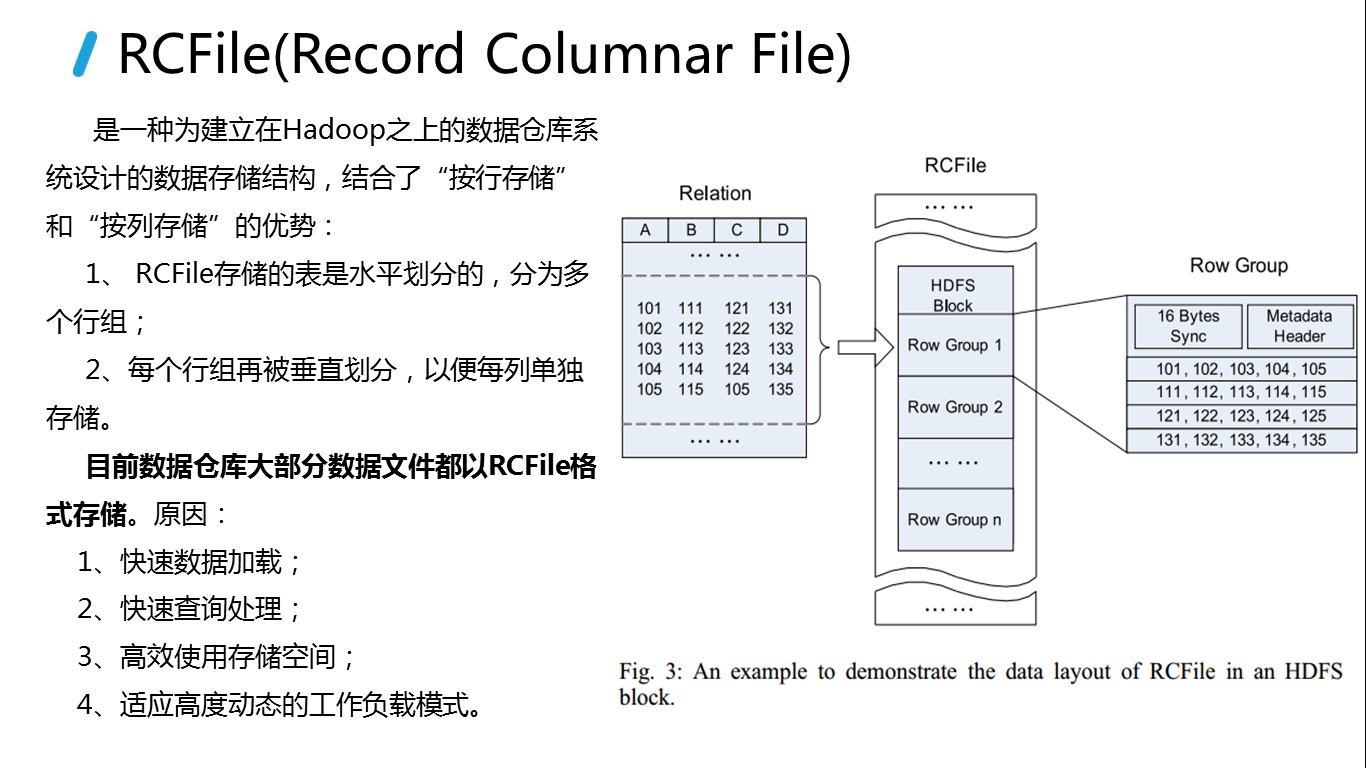
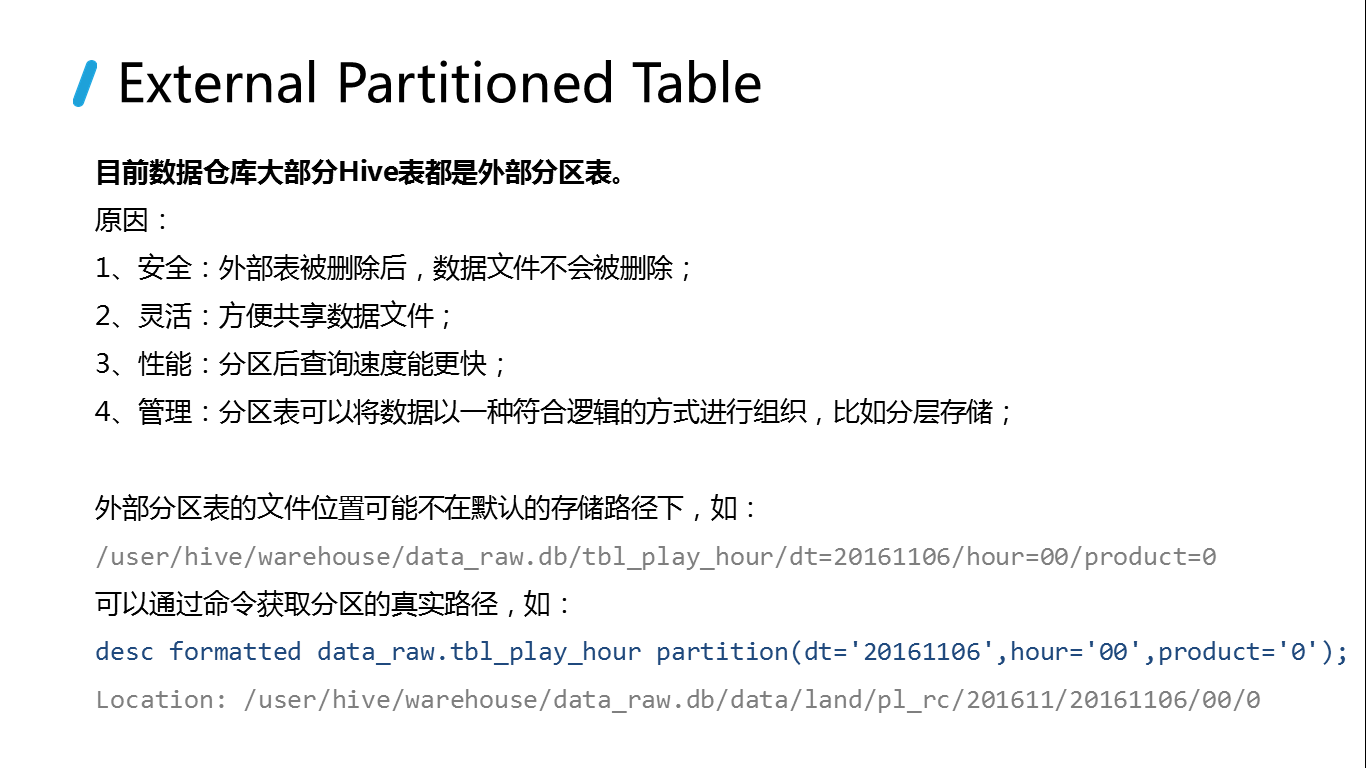
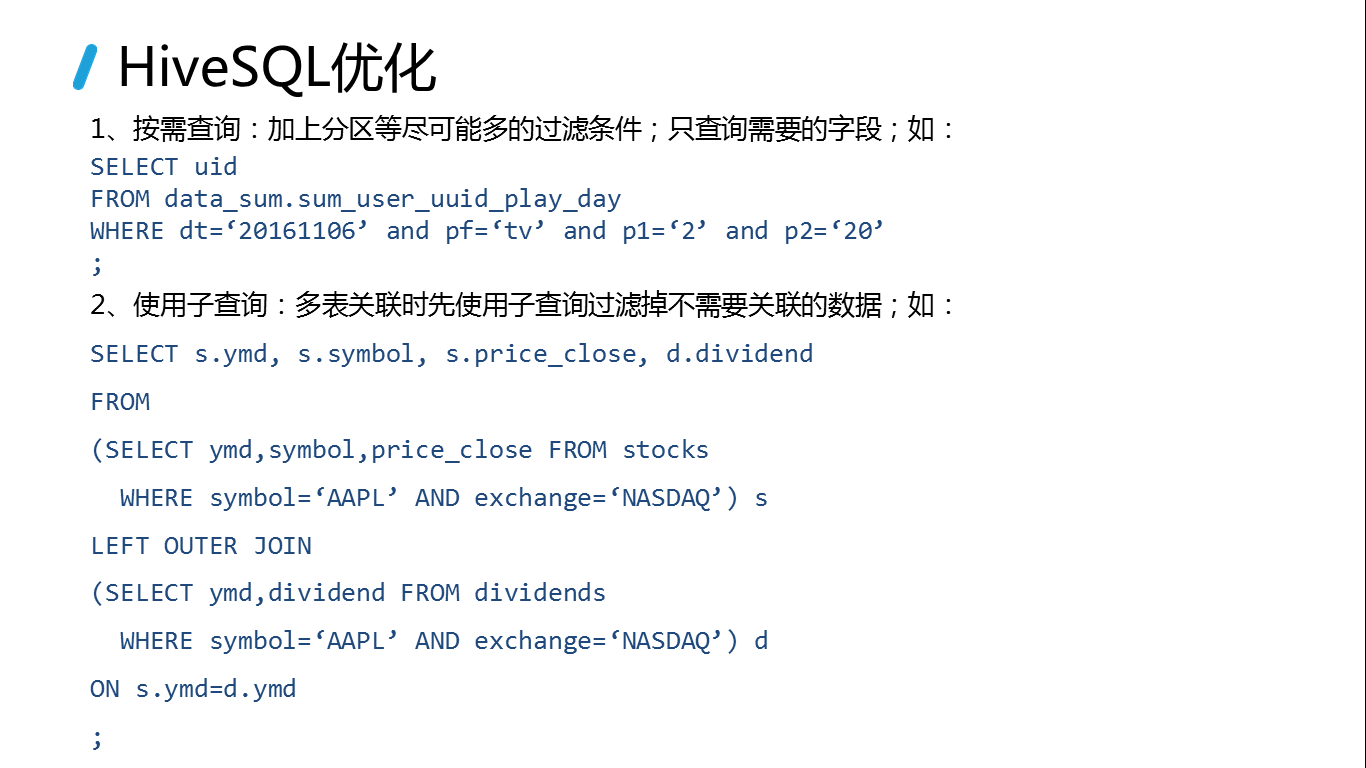
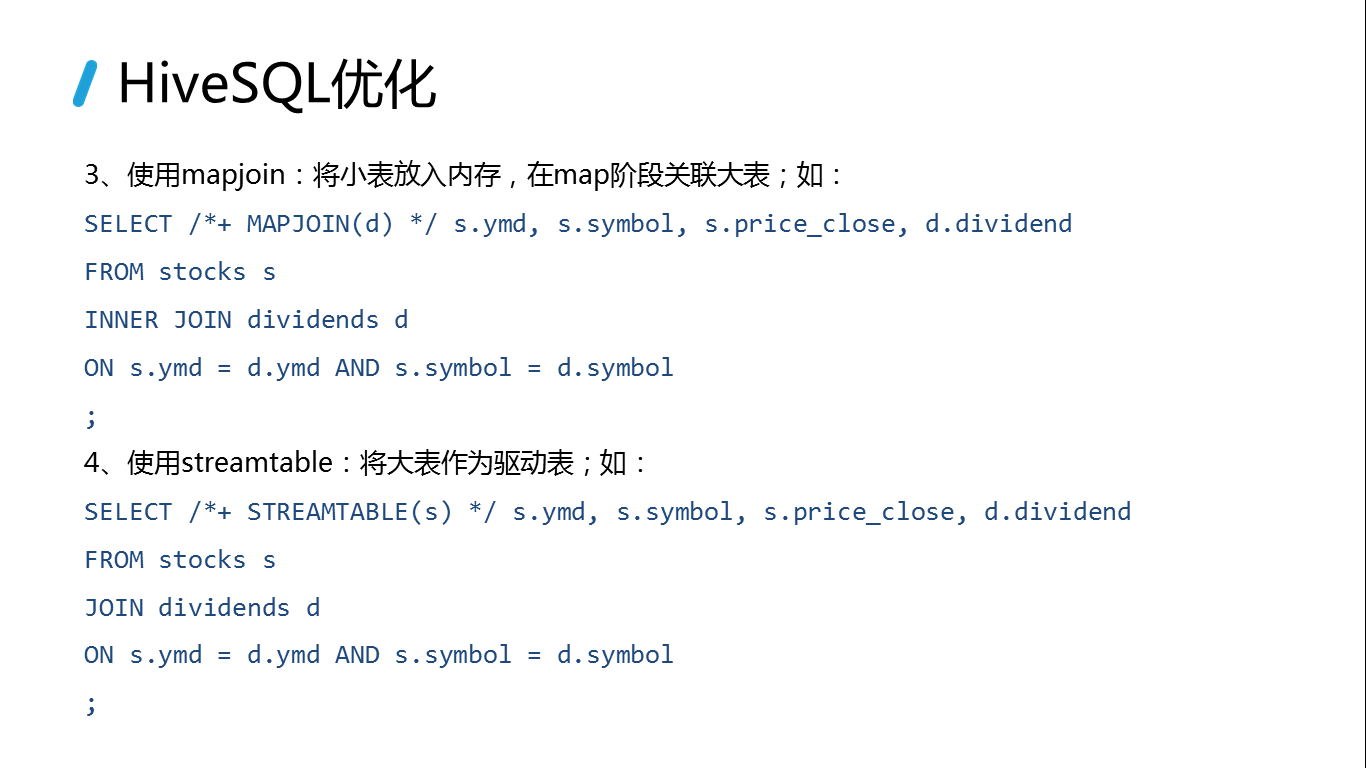


2016-11-27 22:37:24
Hive调优以及发展趋势
http://dongxicheng.org/mapreduce-nextgen/hive-tuning/
hive的更多相关文章
- 初识Hadoop、Hive
2016.10.13 20:28 很久没有写随笔了,自打小宝出生后就没有写过新的文章.数次来到博客园,想开始新的学习历程,总是被各种琐事中断.一方面确实是最近的项目工作比较忙,各个集群频繁地上线加多版 ...
- Hive安装配置指北(含Hive Metastore详解)
个人主页: http://www.linbingdong.com 本文介绍Hive安装配置的整个过程,包括MySQL.Hive及Metastore的安装配置,并分析了Metastore三种配置方式的区 ...
- Hive on Spark安装配置详解(都是坑啊)
个人主页:http://www.linbingdong.com 简书地址:http://www.jianshu.com/p/a7f75b868568 简介 本文主要记录如何安装配置Hive on Sp ...
- HIVE教程
完整PDF下载:<HIVE简明教程> 前言 Hive是对于数据仓库进行管理和分析的工具.但是不要被“数据仓库”这个词所吓倒,数据仓库是很复杂的东西,但是如果你会SQL,就会发现Hive是那 ...
- 基于Ubuntu Hadoop的群集搭建Hive
Hive是Hadoop生态中的一个重要组成部分,主要用于数据仓库.前面的文章中我们已经搭建好了Hadoop的群集,下面我们在这个群集上再搭建Hive的群集. 1.安装MySQL 1.1安装MySQL ...
- 深入浅出数据仓库中SQL性能优化之Hive篇
转自:http://www.csdn.net/article/2015-01-13/2823530 一个Hive查询生成多个Map Reduce Job,一个Map Reduce Job又有Map,R ...
- Hive读取外表数据时跳过文件行首和行尾
作者:Syn良子 出处:http://www.cnblogs.com/cssdongl 转载请注明出处 有时候用hive读取外表数据时,比如csv这种类型的,需要跳过行首或者行尾一些和数据无关的或者自 ...
- Hive索引功能测试
作者:Syn良子 出处:http://www.cnblogs.com/cssdongl 转载请注明出处 从Hive的官方wiki来看,Hive0.7以后增加了一个对表建立index的功能,想试下性能是 ...
- 轻量级OLAP(二):Hive + Elasticsearch
1. 引言 在做OLAP数据分析时,常常会遇到过滤分析需求,比如:除去只有性别.常驻地标签的用户,计算广告媒体上的覆盖UV.OLAP解决方案Kylin不支持复杂数据类型(array.struct.ma ...
随机推荐
- ABP文档 - Javascript Api
文档目录 本节内容: AJAX Notification Message UI Block & Busy Event Bus Logging Other Utility Functions A ...
- Centos 下 mysql root 密码重置
重置mysql密码的方法有很多,官网也提供了很方便的快捷操作办法,可参考资料 resetting permissions .本文重置密码的具体步骤如下: 一.停止MySQL(如果处于运行状态) #se ...
- X86和X86_64和X64有什么区别?
x86是指intel的开发的一种32位指令集,从386开始时代开始的,一直沿用至今,是一种cisc指令集,所有intel早期的cpu,amd早期的cpu都支持这种指令集,ntel官方文档里面称为&qu ...
- HTML5新特性有哪些,你都知道吗
一.画布(Canvas) 画布是网页中的一块区域,可所以用JavaScript在上面绘图.下面我们来创建一个画布并在上面绘制一个坦克(后面将用HTML5做一个坦克大战游戏),代码如下: <!DO ...
- 苹果强制使用HTTPS传输了怎么办?——关于HTTPS,APP开发者必须知道的事
WeTest 导读 2017年1月1日起,苹果公司将强制使用HTTPS协议传输.本文通过对HTTPS基础原理和通信过程内容的讲解,介绍APP开发者在这个背景下的应对办法. 几周前,我们在<htt ...
- Discuz论坛黑链清理教程
本人亲测有效,原创文章哦~~~ 论坛黑链非常的麻烦,如果你的论坛有黑链,那么对不起,百度收录了你的黑链,不会自动删除,需要你手动去清理. 什么是黑链 黑链,顾名思义,就是一些赌博网站的外链,这些黑链相 ...
- 神技!微信小程序(应用号)抢先入门教程(附最新案例DEMO-豆瓣电影)持续更新
微信小程序 Demo(豆瓣电影) 由于时间的关系,没有办法写一个完整的说明,后续配合一些视频资料,请持续关注 官方文档:https://mp.weixin.qq.com/debug/wxadoc/de ...
- BPM嵌入式流程解决方案分享
一.需求分析由于企业业务的独特性或者企业高层独特的管理思想,很多客户选择了自行开发业务系统的方式来实现独有的竞争力. 这类信息系统通常经过了多年的开发,伴随着企业的发展一直在不断优化,与企业的业务非常 ...
- MongoDB学习笔记二—Shell操作
数据类型 MongoDB在保留JSON基本键/值对特性的基础上,添加了其他一些数据类型. null null用于表示空值或者不存在的字段:{“x”:null} 布尔型 布尔类型有两个值true和fal ...
- CSS笔记
初级篇===========================选择器============================元素选择器css:h1{color: red}html:<h1> ...