
Stylized Image Caption论文笔记
Neural Storyteller (Krios et al. 2015)
: NST breaks down the task into two steps, which first generate unstylish captions than apply style shift techniques to generate stylish descriptions.
SentiCap: Generating Image Descriptions with Sentiments (AAAI 2016)
代码和数据都有公布. (代码用的是比较老的框架,没有读。)
Supervised Image Caption
Style: Positive, Negtive
Datasets:
MSCOCO
SentiCap Dataset:作者自己收集的一个数据集 (数据量不大,Positive: 998 images/2873 captions for train, 673 images/2019 captions for test, Negtive: 997 images/2468 captions for train, 503 images/ 1509 captions for test) 3 positive and 3 negative captions per image
This is done in a caption re-writing task based upon objective captions from MSCOCO by asking AMT workers to choose among ANPs of the desired sentiment, and incorporate one or more of them into any one of the five existing captions.
Evaluation Metrics:
Automatic metrics: BLEU, ROUGEL, METEOR, CIDEr
Human evaluation
Model


Shortcomings: requires paired image-sentiment caption data, but also world-level supervison to emphsize the sentiment words(e.g., sentiment strengths of each word in the sentiment caption), which makes the approach very expensive and difficult to scale up.(StyleNet)
StyleNet: Generating Attractive Visual Captions with Styles (CVPR2017)
代码没有公布,有第三方Pytorch实现,数据集公布了FlickrStyle9K(1k测试数据没有公开)
Unsupervised(without using supervised style-specific image-caption paired data): factual image caption pairs + stylized language corpus(only text)
Produce attractive visual captions with styles only using monolingual stylized language corpus(without paired images) and standard factual image/video-caption pairs.
Style:Romantic, Humorous
Datasets:
FlickrStyle10K(built on Flickr 30K image caption dataset, show a standard factual caption for a image, to revise the caption to make it romantic or humorous)(这里虽然有image-stylized caption pairs,但训练的时候作者并没有用这些成对的数据,而是用image-factual caption pairs + stylized text corpora,在evaluate的时候会用到image-stylized caption pairs,用作Ground Truth.)
Evaluation Metrics:
Automatic Metrics:BLEU, METEOR, ROUGE, CIDEr
Human evaluation
Model
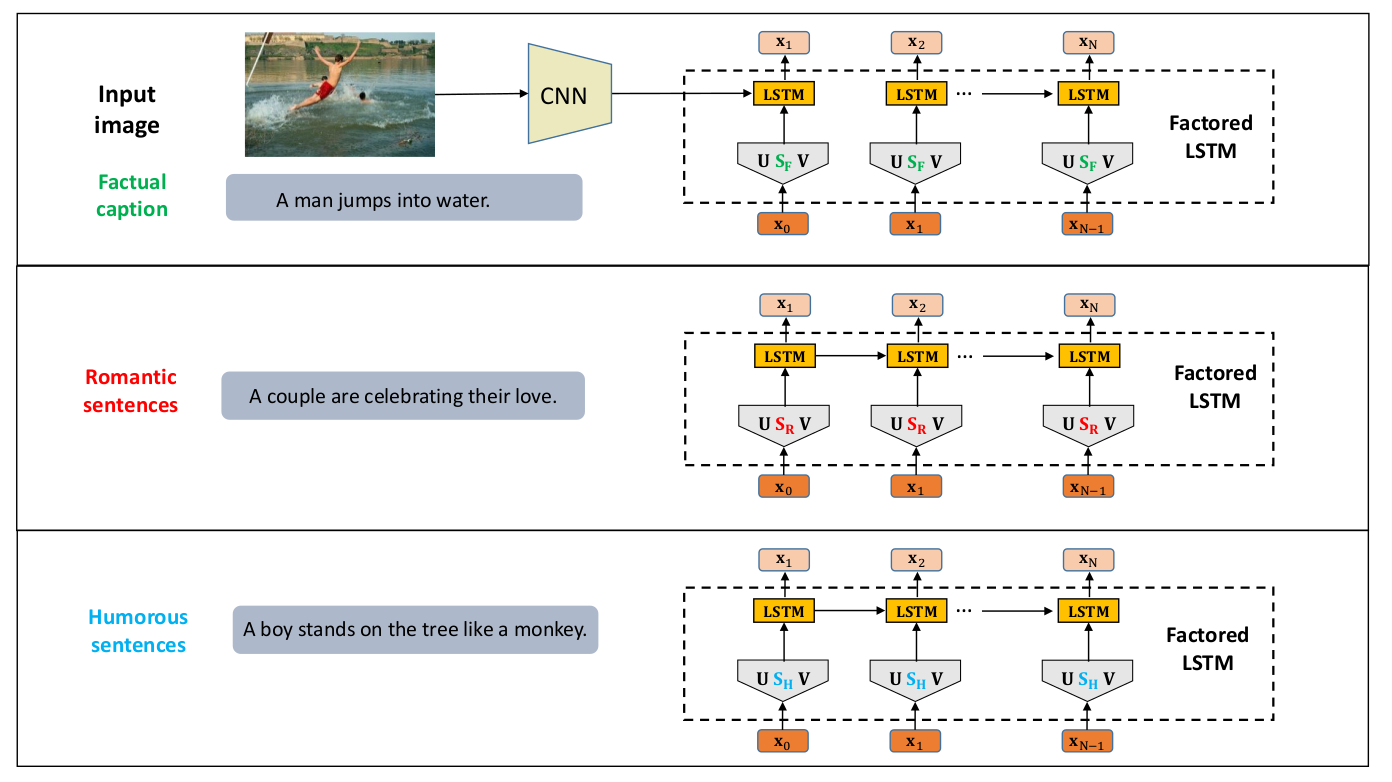
关键点:
1.将LSTM中参数Wx拆分成3项,Ux,Sx,Vx,模型中所有的LSTM网络除S之外的参数都是共享的,参数S用来记忆特定的风格。
2.类似于Multi-task sequence to sequence training. First task, train to generate factual captions given the paired images,更新所有的参数. Second, factored LSTM is trained as a language model,只更新SR或者SH.
“Factual” and “Emotional”: Stylized Image Captioning with Adaptive Learning and Attention (ECCV 2018)
Style-factual LSTM block: Sx, Sh and gxt, ght
Two-stage learning strategy
MLE loss + KL divergence
Image Captioning at Will: A Versatile Scheme for Effectively Injecting Sentiments into Image Descriptions (Preprint 30 Jan 2018)
SENTI-ATTEND: Image Captioning using Sentiment and Attention (Preprint 24 Nov 2018)
这篇文章可以看作是SentiCap的后续工作,采用的是Supervised的方式。
Datasets
MS COCO: 用于生成generic image captions
SentiCap dataset:
Evaluation Metrics
standard image caption evaluation metrics: BLEU, ROUGE-L, METEOR, CIDEr, SPICE
Entropy

Model
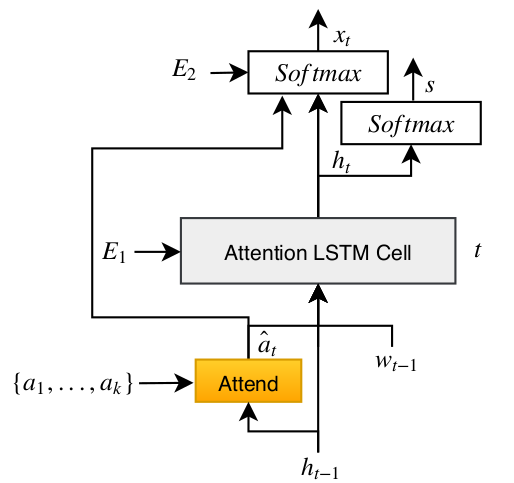

损失函数:
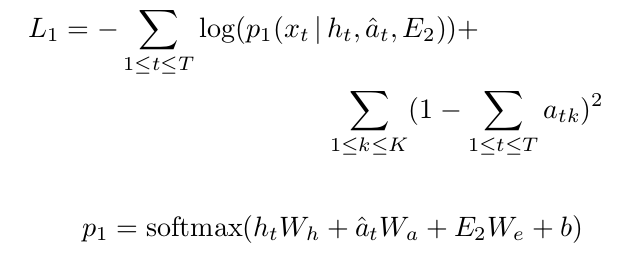
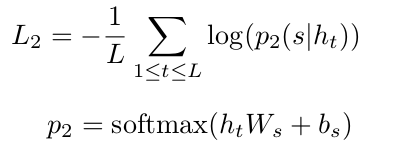
文章没有公布代码,实验部分对比的是SentiCap以及Image Caption at Will
疑问: SentiCap数据集很小,利用image-caption pairs来Cross entropy loss训练会有效果吗???
LSTM多加了E1和E2两个输入,每一步LSTM拿ht来预测s这个操作在SentiCap里也有,然后文章一直处于PrePrint状态。
SemStyle: Learning to Generate Stylised Image Captions using Unaligned Text (CVPR 2018)
公布了部分代码和数据
Style: Story
Learns on existing image caption datasets with only factual descriptions + a large set of styled texts without aligned images
Two-stage training strategy for the term generator and language generator
Dataset:
Descriptive Image Captions: MSCOCO
The Styled Text: bookcorpus
Evaluation:
Automatic relevance metrics: Widely-used captioning metrics (BLEU, METEOR, CIDEr, SPICE)
Automatic style metrics: 作者自己提出的LM(4-gram model)、GRULM(GRU language model)、CLF(binary classifier)
Human evaluations of relevance and style
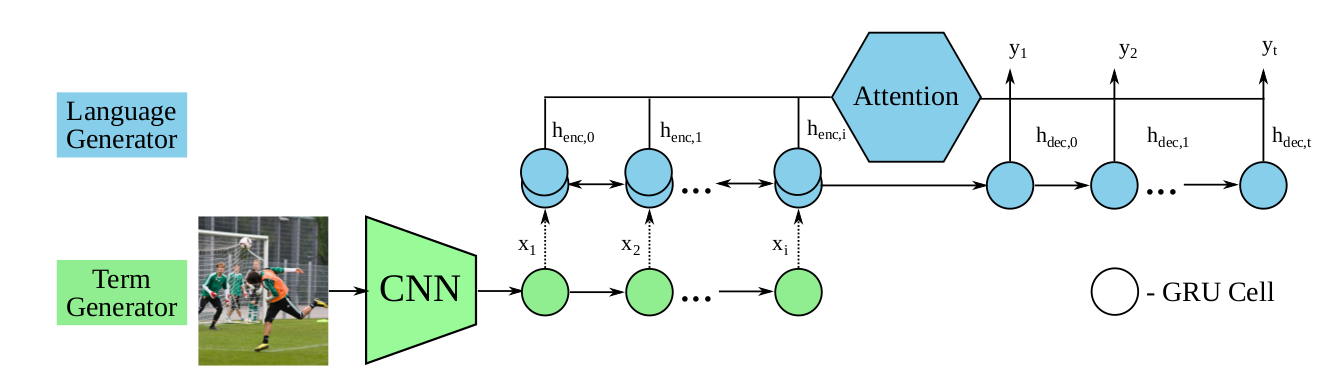
Unsupervised Stylish Image Description Generation via Domain Layer Norm (AAAI 2019)
Unsupervised Image Caption
Four different styles: fairy tale, romance, humor, country song lyrics(lyrics)
Our model is jointly trained with a paired unstylish image description corpus(source domain) and a monolingual corpus of the specific style(target domain)
代码和数据集均未公开
Datasets:
Source Domain:VG-Para(Krause et al. 2017)
Target: BookCorpus(humor and romance), 作者自己收集的country song lyrics and fairy tale
Evaluation Metircs:
Metrics of Semantic Relevance: 作者自己提出的p和r,SPICE
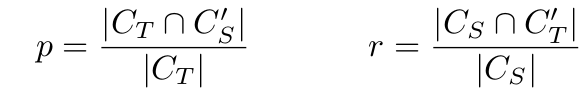
Metrics of Stylishness: transfer accuracy
Human evaluation
Approach Key Point
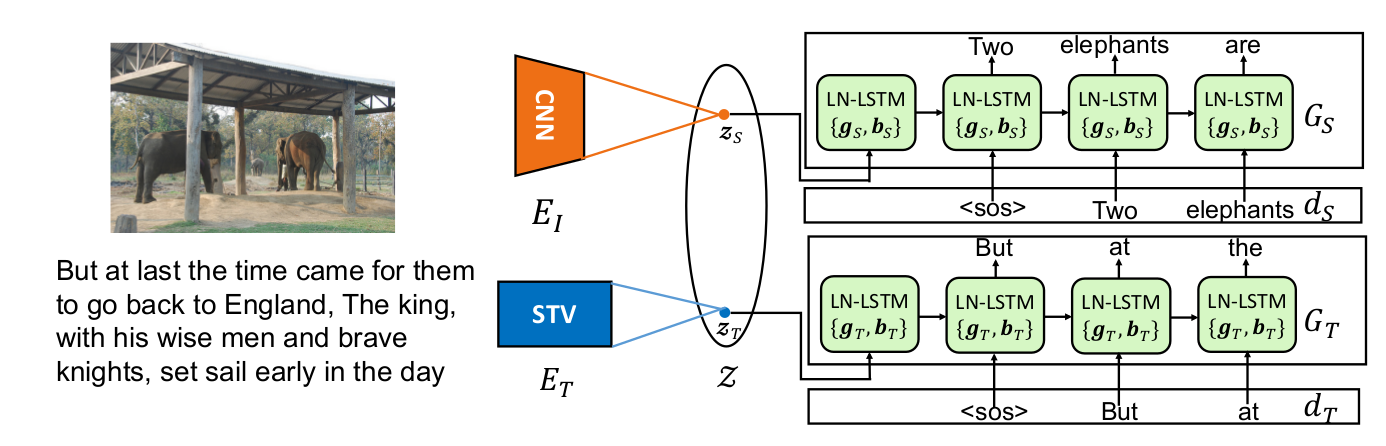
EI和ET分别将图片和目标风格的描述映射到同一个隐空间,Gs用来生成非风格化的描述,即Source domain里的句子,EI和GS组合起来就是传统的Image Caption的Encoder-Decoder模型,训练数据是有监督的Image-Caption对。GT用来生成风格化的描述,ET将风格化的句子编码到隐空间Z,GT则根据隐空间内的编码zT重新生成风格化的句子(Reconstruction),训练数据是风格化的句子。模型训练完成之后,将EI和GT组合,就可以生成风格化的图像描述。
关键点1:作者假设存在一个隐空间Z使得可以将图片, 不带风格的源描述以及带风格的目标描述映射到这个空间。
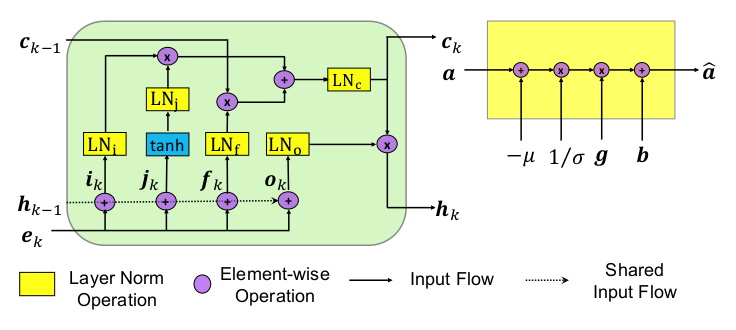
关键点2:GS和GT只在层规范化的参数不同,其他参数是共享的。即GS和GT的LN-LSTM是共享的,其中只有参数{gS,bS}和{gT,bT}不同,作者将这种机制称为Domain Layer Norm(DLN)。层规范化操作(layer norm operation)作用在LSTM的每一个Gate(input gate,forget gate, output gate)上。
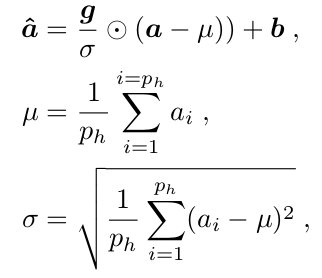
Stylized Image Caption论文笔记的更多相关文章
- Multimodal —— 看图说话(Image Caption)任务的论文笔记(一)评价指标和NIC模型
看图说话(Image Caption)任务是结合CV和NLP两个领域的一种比较综合的任务,Image Caption模型的输入是一幅图像,输出是对该幅图像进行描述的一段文字.这项任务要求模型可以识别图 ...
- 论文笔记:Towards Diverse and Natural Image Descriptions via a Conditional GAN
论文笔记:Towards Diverse and Natural Image Descriptions via a Conditional GAN ICCV 2017 Paper: http://op ...
- 论文笔记之:Natural Language Object Retrieval
论文笔记之:Natural Language Object Retrieval 2017-07-10 16:50:43 本文旨在通过给定的文本描述,在图像中去实现物体的定位和识别.大致流程图如下 ...
- Deep Learning论文笔记之(四)CNN卷积神经网络推导和实现(转)
Deep Learning论文笔记之(四)CNN卷积神经网络推导和实现 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些论文, ...
- 论文笔记之:Visual Tracking with Fully Convolutional Networks
论文笔记之:Visual Tracking with Fully Convolutional Networks ICCV 2015 CUHK 本文利用 FCN 来做跟踪问题,但开篇就提到并非将其看做 ...
- Deep Learning论文笔记之(八)Deep Learning最新综述
Deep Learning论文笔记之(八)Deep Learning最新综述 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些论文,但老感觉看完 ...
- Twitter 新一代流处理利器——Heron 论文笔记之Heron架构
Twitter 新一代流处理利器--Heron 论文笔记之Heron架构 标签(空格分隔): Streaming-process realtime-process Heron Architecture ...
- Deep Learning论文笔记之(六)Multi-Stage多级架构分析
Deep Learning论文笔记之(六)Multi-Stage多级架构分析 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些 ...
- 论文笔记(1):Deep Learning.
论文笔记1:Deep Learning 2015年,深度学习三位大牛(Yann LeCun,Yoshua Bengio & Geoffrey Hinton),合作在Nature ...
随机推荐
- 2019-10-26-dotnet-core-发布只有一个-exe-的方法
title author date CreateTime categories dotnet core 发布只有一个 exe 的方法 lindexi 2019-10-26 8:42:7 +0800 2 ...
- TIJ——Chapter Four:Controlling Execution
同上一章,本章依然比较简单.基础,因此只是做一些总结性的笔记. 1. 不像C和C++那样(0是假,非零为真),Java不允许用一个数字作为boolean值. 2. C中,为了给变量分配空间,所有变量的 ...
- 分享 KubeCon 2019 (上海)关于 Serverless 及 Knative 相关演讲会议
有幸参加了 KubeCon 2019 上海大会,并参加了 Knative 及 Serverless 相关的几场分享会,收获满满.这里简单介绍一下各个演讲主题的主要内容.详细的演讲主题文档可以在Kube ...
- java代码简单实现栈
1. 基于数组简单实现 /** * @author <a herf="mailto:yanwu0527@163.com">XuBaofeng</a> * @ ...
- Audio Session Programming Guide
http://www.cocoachina.com/ios/20150615/12119.html
- Flask学习之十三 日期和时间
英文博客地址:http://blog.miguelgrinberg.com/post/the-flask-mega-tutorial-part-xiii-dates-and-times 中文翻译地址: ...
- python selenium 测试浏览器(IE,FF,Chrome)
browser_engine.py # coding=utf-8 from selenium import webdriver class BrowserEngine(object): "& ...
- 只要是使用函数file_get_contents访问 https 的网站都要开启
使用file_get_contents();报错failed to open stream: Unable to find the socket transport "ssl" - ...
- html--多媒体文件
添加多媒体文件 1.添加多媒体文件标记 <embed src="" width="" height=""></embed& ...
- 排他网关(ExclusiveGateWay)
网关(ExclusiveGateWay) 作者:邓家海2018年3月11日 00:13:25 情景:某一家公司最近在给一个单位做一个财务审批的OA.具体需求是这样的:当部门申请的金额小于一万块的时候, ...