
Secondary Namenode - What it really do?
原文链接:http://blog.madhukaraphatak.com/secondary-namenode---what-it-really-do/
Secondary Namenode is one of the poorly named component in Hadoop. By its name, it gives a sense that its a backup for the Namenode.But in reality its not. Lot of beginners in Hadoop get confused about what exactly SecondaryNamenode does and why its present in HDFS.So in this blog post I try to explain the role of secondary namenode in HDFS.
By its name, you may assume that it has something to do with Namenode and you are right. So before we dig into Secondary Namenode lets see what exactly Namenode does.
Namenode
Namenode holds the meta data for the HDFS like Namespace information, block information etc. When in use, all this information is stored in main memory. But these information also stored in disk for persistence storage.
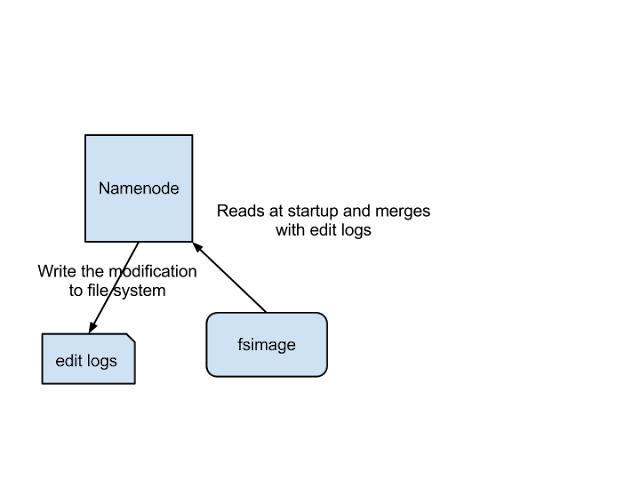
The above image shows how Name Node stores information in disk.
Two different files are
- fsimage - Its the snapshot of the filesystem when namenode started
- Edit logs - Its the sequence of changes made to the filesystem after namenode started
Only in the restart of namenode , edit logs are applied to fsimage to get the latest snapshot of the file system. But namenode restart are rare in production clusters which means edit logs can grow very large for the clusters where namenode runs for a long period of time. The following issues we will encounter in this situation.
- Editlog become very large , which will be challenging to manage it
- Namenode restart takes long time because lot of changes has to be merged
- In the case of crash, we will lost huge amount of metadata since fsimage is very old
So to overcome this issues we need a mechanism which will help us reduce the edit log size which is manageable and have up to date fsimage ,so that load on namenode reduces . It’s very similar to Windows Restore point, which will allow us to take snapshot of the OS so that if something goes wrong , we can fallback to the last restore point.
So now we understood NameNode functionality and challenges to keep the meta data up to date.So what is this all have to with Seconadary Namenode?
Secondary Namenode
Secondary Namenode helps to overcome the above issues by taking over responsibility of merging editlogs with fsimage from the namenode.
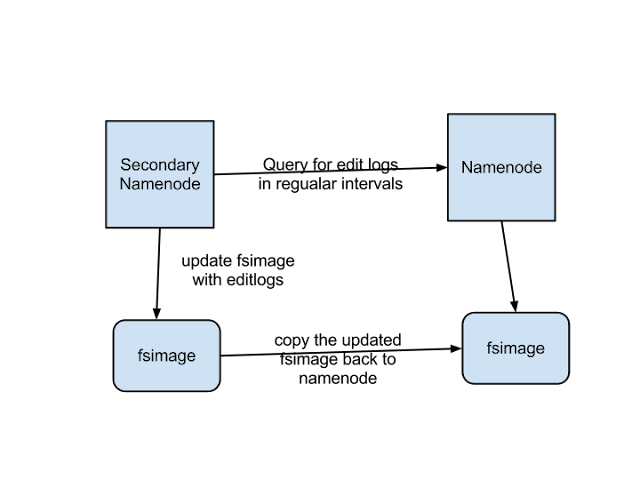
The above figure shows the working of Secondary Namenode
- It gets the edit logs from the namenode in regular intervals and applies to fsimage
- Once it has new fsimage, it copies back to namenode
- Namenode will use this fsimage for the next restart,which will reduce the startup time
Secondary Namenode whole purpose is to have a checkpoint in HDFS. Its just a helper node for namenode.That’s why it also known as checkpoint node inside the community.
So we now understood all Secondary Namenode does puts a checkpoint in filesystem which will help Namenode to function better. Its not the replacement or backup for the Namenode. So from now on make a habit of calling it as a checkpoint node.
Secondary Namenode - What it really do?的更多相关文章
- Secondary NameNode:的作用?
前言 最近刚接触Hadoop, 一直没有弄明白NameNode和Secondary NameNode的区别和关系.很多人都认为,Secondary NameNode是NameNode的备份,是为了防止 ...
- Hadoop之Secondary NameNode
NameNode存储文件系统的变化作为log追加在本地的一个文件里:这个文件是edits.当一个NameNode启动时,它从一个映像文件:FsImage,读取HDFS的状态,使用来自edits日志文件 ...
- 解读Secondary NameNode的功能
1.概述 最近有朋友问我Secondary NameNode的作用,是不是NameNode的备份?是不是为了防止NameNode的单点问题?确实,刚接触Hadoop,从字面上看,很容易会把Second ...
- Secondary NameNode 的作用
https://blog.csdn.net/xh16319/article/details/31375197 很多人都认为,Secondary NameNode是NameNode的备份,是为了防止Na ...
- (转)Secondary NameNode的作用
在Hadoop中,有一些命名不好的模块,Secondary NameNode是其中之一.从它的名字上看,它给人的感觉就像是NameNode的备份.但它实际上却不是.很多Hadoop的初学者都很疑惑,S ...
- 010 secondary namenode(同步元数据和日志)
1.格式化 首先格式化之后只剩下一个根目录. 格式化后会出现元数据 集群启动之后,元数据放在内存中的(消耗内存中) 格式化后会产生镜像文件fsimage,元数据存储 启动的时候namenode会读取镜 ...
- Secondary NameNode究竟是做什么的
Secondary NameNode:它究竟有什么作用? 在hadoop中,有一些命名不好的模块,Secondary NameNode是其中之一.从它的名字上看,它给人的感觉就像是NameNode的备 ...
- Hadoop- NameNode和Secondary NameNode元数据管理机制
元数据的存储机制 A.内存中有一份完整的元数据(内存meta data) B.磁盘有一个“准完整”的元数据镜像(fsimage)文件(在namenode的工作目录中) C.用于衔接内存metadata ...
- NameNode && Secondary NameNode工作机制
NameNode && Secondary NameNode工作机制 1)工作流程 2) fsimage和edits NameNode是HDFS的大脑,它维护着整个文件系统的目录树, ...
随机推荐
- 【转】视差滚动(Parallax Scrolling)效果的原理和实现
原文:http://www.cnblogs.com/JoannaQ/archive/2013/02/08/2909111.html 视差滚动(Parallax Scrolling)是指让多层背景以不同 ...
- 数据结构队列的java实现,包括线性和链式两种方式
实现的思路为: 采用泛型的方式,首先定义了一个Queue的接口,然后通过实现该接口实现了线性和链式的两种形式的队列: 接口代码如下: package com.peter.java.dsa.interf ...
- MVC ValidationAttribute 服务器端自定义验证
MVC ValidationAttribute 服务器端自定义验证 客户端验证 上文只说了客户端的自定义验证,这样对于用户的输入还是不够可靠,用户完全可以绕过我们定义的客户端验证.所以仅有客户端的验证 ...
- IOS UI 第八篇:基本UI
实现图片的滚动,并且自动停止在每张图片上 - (void)viewDidLoad{ [super viewDidLoad]; UIScrollView *scrollView = [[U ...
- WebApi HttpMsgHanler的执行顺序
原来忘记在哪个大牛的博客上看到的,说添加顺序与执行顺序是相反的,事实在下边:直接上代码: //STEP10,不论如何先记录下来请求信息 if (msgHandlerSettings.LoggingHa ...
- IIS Express添加MIME映射
最近在使用fontawesome字体时,在浏览器控制台看到 fontawesome-webfont.woff2?v=4.3.0 无法访问的错误,检查了一下文件确实存在并且路径也对,这就奇怪了! 在控制 ...
- [转]Use the IDA and LLDB explore WebCore C + + class inheritance
原文:http://www.phonesdevelopers.com/1781016/ The surgery class named PluginWidgetIOS use lldb can get ...
- [转]Introduction to Core Bluetooth: Building a Heart Rate Monitor
ref:http://www.raywenderlich.com/52080/introduction-core-bluetooth-building-heart-rate-monitor The C ...
- 字符串拼接 strcat ;数组和指针的区别
问题:字符串拼接 strcat 方法1: 开辟新空间,存放结果: #include <stdio.h> #include <stdlib.h> #include <str ...
- c语言,字符串原地翻转
实现字符串的原地翻转: #include<stdlib.h> #include<stdio.h> #include<assert.h> #define SWAP(a ...