
R formulas in Spark and un-nesting data in SparklyR: Nice and handy!
Intro
In an earlier post I talked about Spark and sparklyR and did some experiments. At my work here at RTL Nederland we have a Spark cluster on Amazon EMR to do some serious heavy lifting on click and video-on-demand data. For an R user it makes perfectly sense to use Spark through the sparklyRinterface. However, using Spark through the pySparkinterface certainly has its benefits. It exposes much more of the Spark functionality and I find the concept of ML Pipelinesin Spark very elegant.
In using Spark I like to share two little tricks described below with you.
The RFormula feature selector
As an R user you have to get used to using Spark through pySpark, moreover, I had to brush up some of my rusty Python knowledge. For training machine learning models there is some help though by using an RFormula
R users know the concept of model formulae in R, it can be handy way to formulate predictive models in a concise way. In Spark you can also use this concept, only a limited set of R operators are available (+, – , . and :) , but it is enough to be useful. The two figures below show a simple example.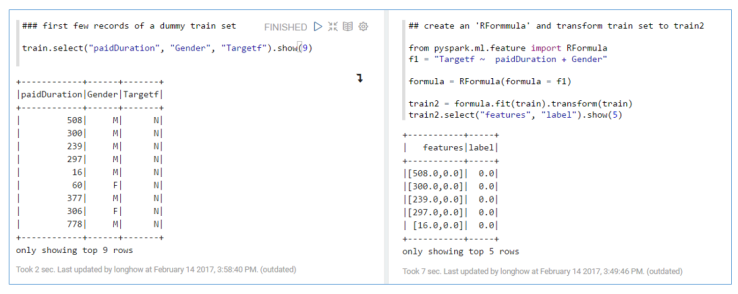
|
1
2
3
4
|
from pyspark.ml.feature import RFormulaf1 = "Targetf ~ paidDuration + Gender "formula = RFormula(formula = f1)train2 = formula.fit(train).transform(train) |
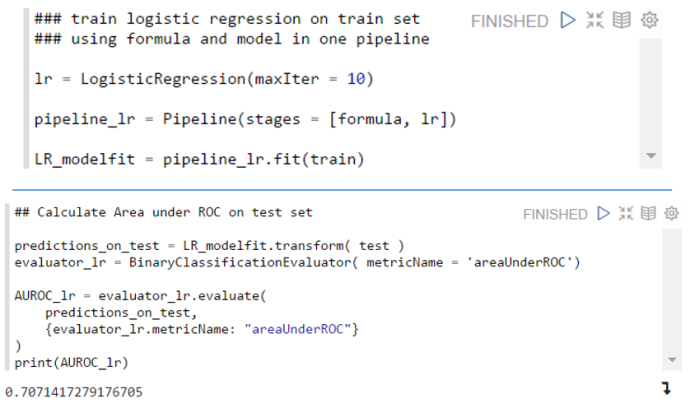
A handy thing about an RFormula in Spark is (just like using a formula in R in lm and some other modeling functions) that string features used in an RFormula will be automatically onehot encoded, so that they can be used directly in the Spark machine learning algorithms.
Nested (hierarchical) data in sparklyR
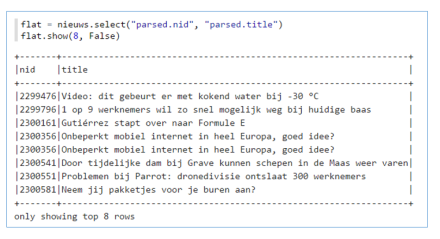
Sometimes you may find your self with nested hierarchical data. In pySpark you can flatten this hierarchy if needed. A simple example, suppose you read in a parquet file and it has the following structure: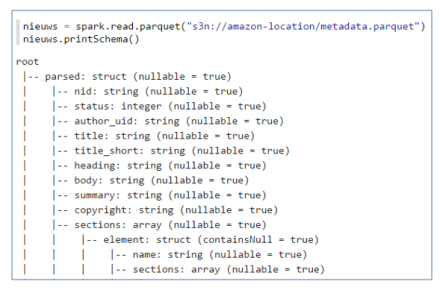 Then to flatten the data you could use:
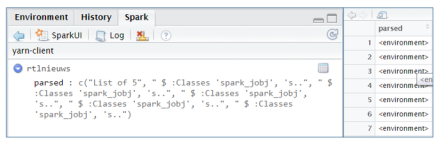
 In SparklyR however, reading the same parquet file results in something that isn’t useful to work with at first sight. If you open the table viewer to see the data, you will see rows with: <environment>.
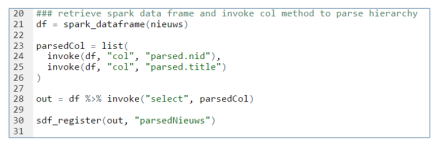
 Fortunately, the facilities used internally by sparklyR to call Spark are available to the end user. You can invoke more methods in Spark if needed. So we can invoke the select and col method our self to flatten the hierarchy.
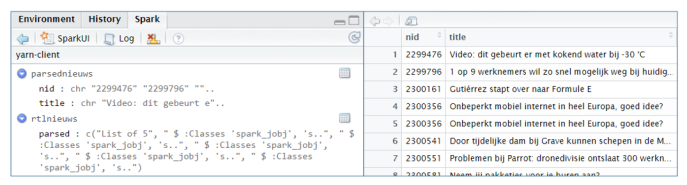
 After registering the output object, it is visible in the Spark interface and you can view the content.
Thanks for reading my two tricks. Cheers, Longhow.
转自:https://longhowlam.wordpress.com/2017/02/15/r-formulas-in-spark-and-un-nesting-data-in-sparklyr-nice-and-handy/
R formulas in Spark and un-nesting data in SparklyR: Nice and handy!的更多相关文章
- Introducing DataFrames in Apache Spark for Large Scale Data Science(中英双语)
文章标题 Introducing DataFrames in Apache Spark for Large Scale Data Science 一个用于大规模数据科学的API——DataFrame ...
- 大数据工具比较:R 语言和 Spark 谁更胜一筹?
本文有两重目的,一是在性能方面快速对比下R语言和Spark,二是想向大家介绍下Spark的机器学习库 背景介绍 由于R语言本身是单线程的,所以可能从性能方面对比Spark和R并不是很明智的做法.即使这 ...
- Using Apache Spark and MySQL for Data Analysis
What is Spark Apache Spark is a cluster computing framework, similar to Apache Hadoop. Wikipedia has ...
- 【译】Using .NET for Apache Spark to Analyze Log Data
.NET for Spark可用于处理成批数据.实时流.机器学习和ad-hoc查询.在这篇博客文章中,我们将探讨如何使用.NET for Spark执行一个非常流行的大数据任务,即日志分析. 1 什么 ...
- Spark性能优化之道——解决Spark数据倾斜(Data Skew)的N种姿势
原创文章,同步首发自作者个人博客转载请务必在文章开头处注明出处. 摘要 本文结合实例详细阐明了Spark数据倾斜的几种场景以及对应的解决方案,包括避免数据源倾斜,调整并行度,使用自定义Partitio ...
- R class of subset of matrix and data.frame
a = matrix( c(2, 4, 3, 1, 5, 7), # the data elements nrow=2, # number of rows ...
- Spark性能调优之道——解决Spark数据倾斜(Data Skew)的N种姿势
原文:http://blog.csdn.net/tanglizhe1105/article/details/51050974 背景 很多使用Spark的朋友很想知道rdd里的元素是怎么存储的,它们占用 ...
- Spark SQL is a Spark module for structured data processing.
http://spark.apache.org/docs/latest/sql-programming-guide.html
- Managing Spark data handles in R
When working with big data with R (say, using Spark and sparklyr) we have found it very convenient t ...
随机推荐
- JVM初探之类文件结构
java 的 .class 文件字节码如图:Class 文件是一组以8字节为基础单位的二进制流,各个数据项目有着严格的结构.下面我们介绍下class文件的结构. 魔数 class文件的头4个字节是魔数 ...
- Oracle wm_concat()函数
oracle wm_concat(column)函数使我们经常会使用到的,下面就教您如何使用oraclewm_concat(column)函数实现字段合并 如: shopping: ------- ...
- JavaScript运算符优先级
图片引用自:http://www.cnblogs.com/xxcanghai/p/5189353.html
- 什么是javascript中的静态方法?一个例子让你懂~!
function Foo(){ this.age = 28};var a = new Foo();alert(a.age);//28alert(a.name);//undifined Foo.name ...
- 实现全局同一编码:Filter
request.setCharacterEncoding("UTF-8");只对POST方式提交有用 对于GET方式 ,可以有装饰模式和适配器模式,对获取参数的函数进行重写. 对所 ...
- 移动设备真机调试本地程序的Node.js【无需连wifi】
前提: 在某些场景下,我们需要调试我们的Node.js,这很简单,很多编辑器都集成了debug模式,但是某些场景下,我们想在移动设备上运行,在本地debug,这也行,只需要链接在同一个内网,通过ip ...
- jQuery的工作原理
jQuery是为了改变javascript的编码方式而设计的. jQuery本身并不是UI组件库或其他的一般AJAX类库. 那么它是如何实现它的声明的呢? 先看一段简短的使用流程: (1).查找(创建 ...
- 保证Android后台不被杀死的几种方法
由于各种原因,在开发Android应用时会提出保证自己有一个后台一直运行的需求,如何保证后台始终运行,不被系统因为内存低杀死,不被任务管理器杀死,不被软件管家等软件杀死等等还是一个比较困难的问题.网上 ...
- MD5加密。
MD5 是把文件用open打开,然后对内容hash后的值,所以和文件名无关,和位置无关,和修改时间无关,只与文件内容有关.
- 微坑---微信小程序ios上时间字符串转换为时间戳时,在开发工具上和安卓手机上运行成功
给定一个时间字符串 var time="2017-02-27 16:42:53" js有三种转换为时间戳的方法:1.var timestamp = Date.parse(time ...