
网络爬虫-获取infoq里的测试新闻保存至html
用java+webdriver+testng实现获取infoq里的测试新闻,获取文章标题和内容,保存至html文件
前提条件:
已安装好java环境,工程导入了webdriver的jar包和testng的jar包
代码如下:
第一:新建PublicModel类,该类中实现了写入html的文件功能和初始化方法
 package com.ustc.publics;

 import java.io.BufferedWriter;

 import java.io.File;

 import java.io.FileOutputStream;

 import java.io.IOException;

 import java.io.OutputStreamWriter;

 import java.text.SimpleDateFormat;

 import java.util.ArrayList;

 import java.util.Date;

 import java.util.HashMap;

 import org.openqa.selenium.WebDriver;

 import org.openqa.selenium.ie.InternetExplorerDriver;

 public class PublicModel {

     public static WebDriver driver;

     /**

      * 初始化方法

      */

     public static void initModel() {

         driver = new InternetExplorerDriver();

          /*driver.manage().timeouts().implicitlyWait(3, TimeUnit.SECONDS);*/

         driver.manage().window().maximize();

     }

     /**

      * 写入html文件方法数组

      *

      * @param hotTopics

      *            hashmap的数组内容

      * @param file

      *            文件名称

      * @throws IOException

      */

     public static void writeHtmlContent(ArrayList<HashMap<String, String>> hotTopics, String file, String title1,

             String title2) {

         FileOutputStream fis = null;

         BufferedWriter bfr = null;

         String css = "table.gridtable {" + "font-family: verdana,arial,sans-serif;" + "font-size:11px;"

                 + "color:#333333;" + "border-width: 1px;" + "border-color: #666666;" + "border-collapse: collapse;"

                 + "}" + "table.gridtable th {" + "border-width: 1px;" + "padding: 8px;" + "border-style: solid;"

                 + "border-color: #666666;" + "background-color: #dedede;" + "}" + "table.gridtable td {"

                 + "border-width: 1px;" + "padding: 8px;" + "border-style: solid;" + "border-color: #666666;"

                 + "background-color: #ffffff;" + "}";

         try {

             /* 文件名:当前工程路径+result+20160607_file.html */

             Date currentTime = new Date();

             SimpleDateFormat formatter = new SimpleDateFormat("yyyyMMdd");

             String dateString = formatter.format(currentTime);

             String filename = System.getProperty("user.dir") + File.separator + "result" + File.separator + dateString

                     + "_" + file + ".html";

             fis = new FileOutputStream(filename);

             bfr = new BufferedWriter(new OutputStreamWriter(fis));

             /* 遍历arrayList的hashMap内容,按行写入html文件 */

             bfr.append("<html>");

             bfr.append("<head>");

             bfr.append("<title>数据写入html展示</title>");

             bfr.append("<meta http-equiv=\"Content-Type\" content=\"text/html; charset=utf-8\" />");

             bfr.append("</head>");

             bfr.append("<style type=\"text/css\">");

             bfr.append(css);

             bfr.append("</style>");

             bfr.append("<body>");

             bfr.append("<table class=\"gridtable\" >");

             bfr.append("<tr><th>序号</th><th>" + title1 + "</th><th>" + title2 + "</th>");

             bfr.append("<tbody>");

             for (int i = 0; i < hotTopics.size(); i++) {

                 bfr.append("<tr>");

                 String que = hotTopics.get(i).get("que").toString();

                 String ans = hotTopics.get(i).get("ans").toString();

                 bfr.append("<td>" + i + "</td>");

                 bfr.append("<td>" + que + "</td>");

                 bfr.append("<td>" + ans + "</td>");

                 bfr.append("</tr>");

             }

             bfr.append("</tbody>");

             bfr.append("</table>");

             bfr.append("</body>");

             bfr.append("</html>");

         } catch (Exception e) {

             e.printStackTrace();

         } finally {

             try {

                 bfr.close();

             } catch (Exception e) {

                 e.printStackTrace();

             }

             try {

                 fis.close();

             } catch (Exception e) {

                 e.printStackTrace();

             }

         }

     }

 }
第二:新建InfoqArticle类,该类继承了PublicModel类,获取infoq里的测试新闻,获取文章标题和内容,保存至html文件
 package com.ustc.base;

 import java.util.ArrayList;

 import java.util.HashMap;

 import java.util.List;

 import org.openqa.selenium.By;

 import org.openqa.selenium.WebElement;

 import org.testng.annotations.AfterClass;

 import org.testng.annotations.BeforeClass;

 import org.testng.annotations.Test;

 import com.ustc.publics.PublicModel;

 public class InfoqArticle extends PublicModel{

     @BeforeClass

     public void setUp() {

         initModel();

     }

     /**

      * 获取infoq里的测试新闻,获取文章标题和内容,保存至html文件

      * @throws Exception

      */

     @Test

     public void getInfoqMsg() throws Exception{

         String url = "http://www.infoq.com/cn/testing/?utm_source=infoq&utm_medium=header_graybar&utm_campaign=topic_clk";

         driver.get(url);

         /* 获取infoq测试文章根节点 */

         WebElement rootNode = driver.findElement(By.cssSelector("div[class~='articles']"));

         List<WebElement> nodes = rootNode.findElements(By.tagName("p"));

         ArrayList<HashMap<String, String>> infoqMsgs = new ArrayList<HashMap<String, String>>();

         ArrayList<String> titles = new ArrayList<String>();

         /*获取所有测试文章的链接*/

         for (WebElement node : nodes) {

             titles.add(node.findElement(By.cssSelector("a.art_title")).getAttribute("href"));

         }

         /* 遍历添加infoq文章标题、内容到数组中 */

         for(String title : titles){

             HashMap<String, String> topic = new HashMap<String, String>();

             driver.get(title);

             /*文章标题*/

             topic.put("que", driver.findElement(By.cssSelector("div.title_canvas > h1")).getText());

             /*文章链接*/

             topic.put("ans",title);

             /*文章内容,文章内容已经获取到,因为内容太多所以没有往html中写入,只写入了该文章的链接*/

             infoqMsgs.add(topic);

         }

         /*数组数据写入html*/

         writeHtmlContent(infoqMsgs,"infoq_article","文章标题","文章内容");

     }

     @AfterClass

     public void quit() {

         driver.quit();

     }

 }
第三:配置testng.xml文件
 <?xml version="1.0" encoding="UTF-8"?>

 <!DOCTYPE suite SYSTEM "http://testng.org/testng-1.0.dtd">

 <suite name="Suite" parallel="false">

   <test name="Test">

     <classes>

       <class name="com.ustc.base.InfoqArticle09"/> <!--9:抓取infoq的测试新闻  -->

     </classes>

   </test> <!-- Test -->

 </suite> <!-- Suite -->
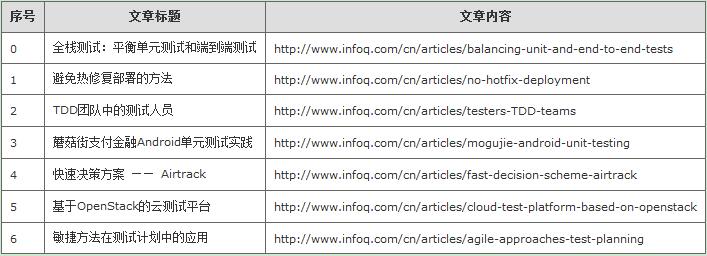
运行testng.xml结果为:
项目路径result目录下生成了一个文件:20160615_infoq_article09.html,内容如下
网络爬虫-获取infoq里的测试新闻保存至html的更多相关文章
- Selenium实战脚本集(3)--抓取infoq里的测试新闻
描述 打开infoq页面,抓取最新的一些测试文章 需要抓取文章的标题和内容 如果你有个人blog的话,可以将这些文章转载到自己的blog 要求 不要在新窗口打开文章 自行了解最新的测试思潮与实践
- Java 网络爬虫获取网页源代码原理及实现
Java 网络爬虫获取网页源代码原理及实现 1.网络爬虫是一个自动提取网页的程序,它为搜索引擎从万维网上下载网页,是搜索引擎的重要组成.传统爬虫从一个或若干初始网页的URL开始,获得初始网页上的URL ...
- 一篇文章教会你利用Python网络爬虫获取电影天堂视频下载链接
[一.项目背景] 相信大家都有一种头疼的体验,要下载电影特别费劲,对吧?要一部一部的下载,而且不能直观的知道最近电影更新的状态. 今天小编以电影天堂为例,带大家更直观的去看自己喜欢的电影,并且下载下来 ...
- Java 网络爬虫获取页面源代码
原博文:http://www.cnblogs.com/xudong-bupt/archive/2013/03/20/2971893.html 1.网络爬虫是一个自动提取网页的程序,它为搜索引擎从万维网 ...
- 手把手教你用Python网络爬虫获取网易云音乐歌曲
前天给大家分享了用Python网络爬虫爬取了网易云歌词,在文尾说要爬取网易云歌曲,今天小编带大家一起来利用Python爬取网易云音乐,分分钟将网站上的音乐down到本地. 跟着小编运行过代码的筒子们将 ...
- 【Python网络爬虫三】 爬去网页新闻
学弟又一个自然语言处理的项目,需要在网上爬一些文章,然后进行分词,刚好牛客这周的是从一个html中找到正文,就实践了一下.写了一个爬门户网站新闻的程序 需求: 从门户网站爬取新闻,将新闻标题,作者,时 ...
- 【Python网络爬虫三】 爬取网页新闻
学弟又一个自然语言处理的项目,需要在网上爬一些文章,然后进行分词,刚好牛客这周的是从一个html中找到正文,就实践了一下.写了一个爬门户网站新闻的程序 需求: 从门户网站爬取新闻,将新闻标题,作者,时 ...
- 手把手教你使用Python网络爬虫获取招聘信息
1.前言 现在在疫情阶段,想找一份不错的工作变得更为困难,很多人会选择去网上看招聘信息.可是招聘信息有一些是错综复杂的.而且不能把全部的信息全部罗列出来,以外卖的58招聘网站来看,资料整理的不清晰. ...
- python从网络摄像头获取rstp视频流并截取图片保存
import cv2 def get_img_from_camera_net(folder_path): cap = cv2.VideoCapture("rtsp://admin:a ...
随机推荐
- 基于.NET打造IP智能网络视频监控系统
开源倾情奉献:基于.NET打造IP智能网络视频监控系统(一)开放源代码 开源倾情奉献系列链接 开源倾情奉献:基于.NET打造IP智能网络视频监控系统(一)开放源代码 开源倾情奉献:基于.NET打造 ...
- HTML文档类型
在HMTL5中页面的最顶端代码就是: <!DOCTYPE html> 为何要如此定义.书写呢? 首先引入一个概念:文档类型,英译为:Document type,缩写成:doctype. 文 ...
- Router
backbone库学习-Router backbone库的结构http://www.cnblogs.com/nuysoft/archive/2012/03/19/2404274.html 本文的例子来 ...
- Unicode(UTF&UCS)深度历险
Unicode(UTF&UCS)深度历险 计算机网络诞生后,大家慢慢地发现一个问题:一个字节放不下一个字符了!因为需要交流,本地化的文字需要能够被支持. 最初的字符集使用7bit来存储字符,因 ...
- CodeFirst 初恋
CodeFirst 初恋 原著:Prorgamming Entity Framework Entitywork Code First 大家好! 我是AaronYang,这本书我也挺喜欢的,看了一半了, ...
- QzzmServer v2.0正式版发布
V2.1升级程序已发布,具体见下文 首先,感谢网友的热情的测评及反馈,现Qzzm ...
- SSH整合之_架构的历史序列图
只用jsp最原始的架构 jsp+DB的2层架构 jsp+DB+_Entity的2层架构 jsp+DB+_Entity3_+Service的三层架构 jsp+DB+_Entity3_+Service_H ...
- WCFRESTFul服务搭建及实现增删改查
WCFRESTFul服务搭建及实现增删改查 RESTful Wcf是一种基于Http协议的服务架构风格, RESTful 的服务通常是架构层面上的考虑. 因为它天生就具有很好的跨平台跨语言的集成能力 ...
- Dragon Balls(hdu3635带权并查集)
题意:n个城市有n个龙珠,T a,b 代表将龙珠a移动到b城市,Q a代表查询龙珠a所在城市,该城市有多少颗龙珠,该龙珠移动了多少次. 注意:移动时是将龙珠所在该城市所有龙珠都移动,每个龙珠不会再回 ...
- 异常:failed for object com.sdu.crm.pojo.Customer@136a986 [java.lang.NullPointerException]
异常: failed for object com.sdu.crm.pojo.Customer@136a986 [java.lang.NullPointerException] 大家好,如果大家看到了 ...