
SqlServer性能优化索引(五)
导入表结构:
select * into ProductCategory from AdventureWorksDW2014.dbo.DimProductCategory

select * into Product from AdventureWorksDW2014.dbo.DimProduct
开启磁盘io:
set statistics io on

select EnglishProductName,StandardCost,Color,Size,Weight from Product

where size>'M'--0.189 io:251

set statistics io off

非聚簇索引:
创建的语句:
create nonclustered index nc_product_size on product(size)
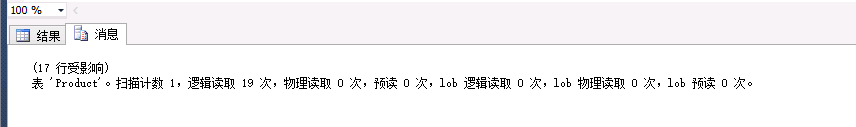
再次执行上面的查询代码(提高了三倍):
set statistics io on

select EnglishProductName,StandardCost,Color,Size,Weight from Product

where size>'M'   --0.054 io:19

set statistics io off
建立覆盖索引:
create nonclustered index nc_product_size1 on product(size) include(EnglishProductName,

StandardCost,Color,Weight)
再次执行上述语句:
set statistics io on

select EnglishProductName,StandardCost,Color,Size,Weight from Product

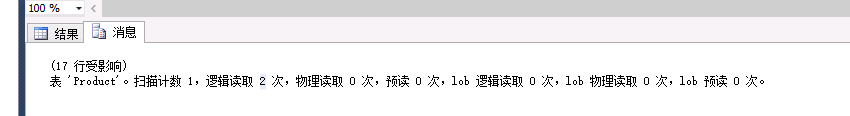
where size>'M'   --0.003 io:2

set statistics io off
数据库会自动选择索引:

没有创建索引的情况:
set statistics io on

select c.EnglishProductCategoryName,p.EnglishProductName,p.Color,p.Size

from product as p inner join ProductCategory as c on p.ProductSubcategoryKey=c.ProductCategoryKey

where c.ProductCategoryKey=1 --0.1928

set statistics io off
创建索引:
create nonclustered index nc_productcategory_key on ProductCategory(ProductcategoryKey) include

(EnglishProductCategoryName)
在次查询:
set statistics io on

select c.EnglishProductCategoryName,p.EnglishProductName,p.Color,p.Size

from product as p inner join ProductCategory as c on p.ProductSubcategoryKey=c.ProductCategoryKey

where c.ProductCategoryKey=1 --0.1928     io:c 2 p 251

set statistics io off
IO情况:
由此可见 Product表影响比较严重 251
建立一个非聚簇索引:(做一个物理排序)
create nonclustered index nc_product_categorykey on product(productsubcategorykey) include

(englishproductname,color,size)
执行语句:
set statistics io on

select c.EnglishProductCategoryName,p.EnglishProductName,p.Color,p.Size

from product as p inner join ProductCategory as c on p.ProductSubcategoryKey=c.ProductCategoryKey

where c.ProductCategoryKey=1      --4.29 od 1497 oh 783 c 155

set statistics io off

导入三张表:
select * into Customer from AdventureWorks2014.Sales.Customer

select * into OrderHeader from AdventureWorks2014.Sales.SalesOrderHeader

select * into OrderDetail from AdventureWorks2014.Sales.SalesOrderDetail
实现一些业务:
set statistics io on

select c.CustomerID,SUM(od.LineTotal) from OrderDetail as od inner join

 orderheader as oh  on od.SalesOrderID=oh.SalesOrderID  inner join customer as c

 on oh.CustomerID =c.CustomerID group by(c.CustomerID)   --4.29

 set statistics io off

优化的第一步:
1.查看sql语句写法是否有问题(进行改造)
set statistics io on

select oh.CustomerID,sum(od.LineTotal) from OrderDetail as od inner join

OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID) --3.77 od 1497 oh 783

set statistics io off

创建索引:
create nonclustered index nc_OrderDetail_SalesOrderID on OrderDetail(SalesOrderID) include

(linetotal)
创建另外一个索引:针对group by 的列
create nonclustered index nc_OrderHeader_CustomerID on OrderHeader(CustomerID)
在次执行上述语句:
set statistics io on

select oh.CustomerID,sum(od.LineTotal) from OrderDetail as od inner join

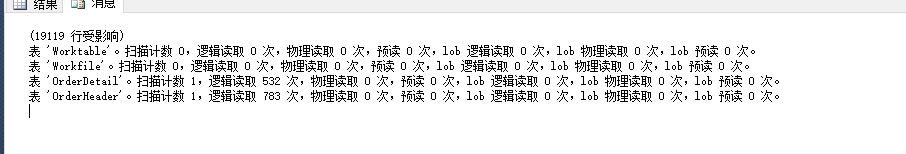
OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID) --3.10 od 533 oh 783

set statistics io off
采用索引视图的方式:
create view v_Order_Total

as

select oh.CustomerID,sum(od.LineTotal) as 总额 from OrderDetail as od inner join

OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID)
效果差不多:
set statistics io on

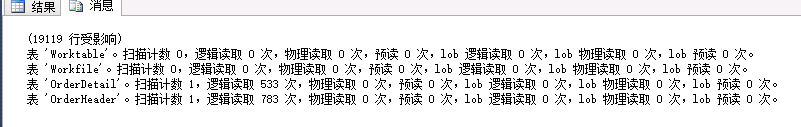
select * from v_Order_Total --3.10 od 533 oh 783

set statistics io off
修改:
alter view v_Order_Total

as

select oh.CustomerID as 客户ID, sum(od.LineTotal) as 总额 from OrderDetail as od inner join

OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID)
对唯一列做聚集索引:
create clustered index c_vordertotal_customerid on v_order_total(客户ID)
直接运行报错:
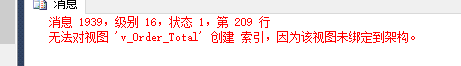
解决方案:
在次执行:
alter view v_Order_Total

with schemabinding

as

select oh.CustomerID as 客户ID, sum(od.LineTotal) as 总额 from OrderDetail as od inner join

OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID)
报错:

解决方法:
alter view v_Order_Total

with schemabinding

as

select oh.CustomerID as 客户ID, sum(od.LineTotal) as 总额 from dbo.OrderDetail as od inner join

dbo.OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID)
在次创建:
create clustered index c_vordertotal_customerid on v_order_total(客户ID)
报错:

办法:
create unique clustered index c_vordertotal_customerid on v_order_total(客户ID)
报错:

方法:
alter view v_Order_Total

with schemabinding

as

select oh.CustomerID as 客户ID, sum(od.LineTotal) as 总额,COUNT_BIG(*) as 计数 from dbo.OrderDetail as od inner join

dbo.OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID)
执行创建索引:
create unique clustered index c_vordertotal_customerid on v_order_total(客户ID)
成功
set statistics io on

select * from v_Order_Total --0.09 io:92

set statistics io off
执行计划:
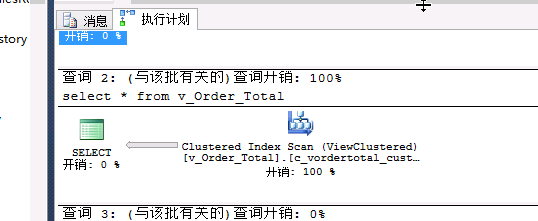

会自动进行值的更新,不用关心
对语句的访问会用到刚才的架构:
set statistics io on

select oh.CustomerID,sum(od.LineTotal) from OrderDetail as od inner join

OrderHeader as oh on od.SalesOrderID=oh.SalesOrderID group by(oh.CustomerID) --0.09 io:92

set statistics io off
SqlServer性能优化索引(五)的更多相关文章
- 03.SQLServer性能优化之---存储优化系列
汇总篇:http://www.cnblogs.com/dunitian/p/4822808.html#tsql 概 述:http://www.cnblogs.com/dunitian/p/60413 ...
- PLSQL_性能优化索引Index介绍(概念)
2014-06-01 BaoXinjian
- 01.SQLServer性能优化之----强大的文件组----分盘存储
汇总篇:http://www.cnblogs.com/dunitian/p/4822808.html#tsql 文章内容皆自己的理解,如有不足之处欢迎指正~谢谢 前天有学弟问逆天:“逆天,有没有一种方 ...
- 02.SQLServer性能优化之---牛逼的OSQL----大数据导入
汇总篇:http://www.cnblogs.com/dunitian/p/4822808.html#tsql 上一篇:01.SQLServer性能优化之----强大的文件组----分盘存储 http ...
- SQLServer性能优化专题
SQLServer性能优化专题 01.SQLServer性能优化之----强大的文件组----分盘存储(水平分库) http://www.cnblogs.com/dunitian/p/5276431. ...
- SQLServer性能优化之---数据库级日记监控
上节回顾:https://www.cnblogs.com/dotnetcrazy/p/11029323.html 4.6.6.SQLServer监控 脚本示意:https://github.com/l ...
- JAVA性能优化的五种方式
一,JAVA性能优化之设计优化 设计优化处于性能优化手段的上层.它往往须要在软件开发之前进行.在软件开发之前,系统架构师应该就评估系统可能存在的各种潜在问题和技术难点,并给出合理的设计方案,因为软件设 ...
- SqlServer性能优化(一)
一:数据存储的方式: 1.数据文件:.mdf或.ndf 2.日志文件:.ldf 二:事务日志的工作步骤: 1.数据修改由应用程序发出(在缓冲区进行缓存) 2.数据页位于缓存区缓冲中,或者读入缓冲区缓存 ...
- SqlServer性能优化 查询和索引优化(十二)
查询优化的过程: 查询优化: 功能:分析语句后最终生成执行计划 分析:获取操作语句参数 索引选择 Join算法选择 创建测试的表: select * into EmployeeOp from Adve ...
随机推荐
- HDMI之CEC DDC学习笔记(可能有误)
1 HDMI的音视频通路,有待学习: 2 DDC通路,大致是个IIC接口,读取上游器件的EDID或者E-EDID数据: EDID的前128字节数据格式如下:(可能有不同版本,格式可能有区别)
- 每天一个percona 工具 --- pt-kill
主要用途:pt-kill是用来kill MySQL连接的一个工具,在MySQL中因为空闲连接较多导致超过最大连接数,或某个有问题的sql导致mysql负载很高时,需要将其KILL掉来保证服务器正常运行 ...
- html/css小练习1
aaarticlea/png;base64,iVBORw0KGgoAAAANSUhEUgAAAywAAAFgCAIAAADW6Wr0AAAgAElEQVR4nOzdd1xT5+L48bJlhUAGCY
- Excel函数汇总:
/** *D1—要查找的目标值 *G:G—查找的单元格范围,G:G表示G列 *1—查找第一个匹配 *FALSE—找到结果即返回 */ VLOOKUP(D1,G:G,1,FALSE):返回查找到的单元格 ...
- FZU 2150 Fire Game
Fire Game Time Limit:1000MS Memory Limit:32768KB 64bit IO Format:%I64d & %I64u Submit St ...
- 【仿真】Lattice_Diamond_调用Modelsim_仿真
仿真前的准备工作:在modelsim中添加lattice仿真库:1.去除modelsim安装目录下modelsim.ini的只读属性.2.打开modelsim,更改目录File>Change d ...
- hammer.js实现背景图手势缩放调整位置
<!DOCTYPE html> <html> <head> <script> function getxy(e){ var a=new Array() ...
- java的Spring
歇了一年都没有写过自己博客了,在学习新东西的时候 ,应该把它们记下来,学了.net 去了公司没有多久就转成了java虽然都在做,还是觉得.net好,不过东西还是应该学习下去,这样才是正解! 首先学习的 ...
- asp.net自己创建的app_code文件夹中的类不能访问的解决办法
在Web应用程序中不能通过右键项目-〉”添加“-〉”添加ASP.NET文件夹“方式添加 .因为Web应用程序中App_Code就不存在 .不过可以通过手动的方式创建,添加一个文件夹命名为App_Cod ...
- HTML中强大的input标签属性
用了许久的html,<input>这个标签是最常用的标签之一. <input type="">标签中type属性是必不可少的,以往我最常用的有 type=& ...