
Splunk Enterprise architecture——转发器本质上是日志收集client附加负载均衡,indexer是分布式索引,外加一个集中式管理协调的中心节点
Splunk Enterprise architecture and processes
This topic discusses the internal architecture and processes of Splunk Enterprise at a high level. If you're looking for information about third-party components used in Splunk Enterprise, see the credits section in the Release notes.
Splunk Enterprise Processes
A Splunk Enterprise server installs a process on your host, splunkd.
splunkd is a distributed C/C++ server that accesses, processes and indexes streaming IT data. It also handles search requests. splunkd processes and indexes your data by streaming it through a series of pipelines, each made up of a series of processors.
- Pipelines are single threads inside the
splunkdprocess, each configured with a single snippet of XML. - Processors are individual, reusable C or C++ functions that act on the stream of IT data that passes through a pipeline. Pipelines can pass data to one another through queues.
Architecture diagram
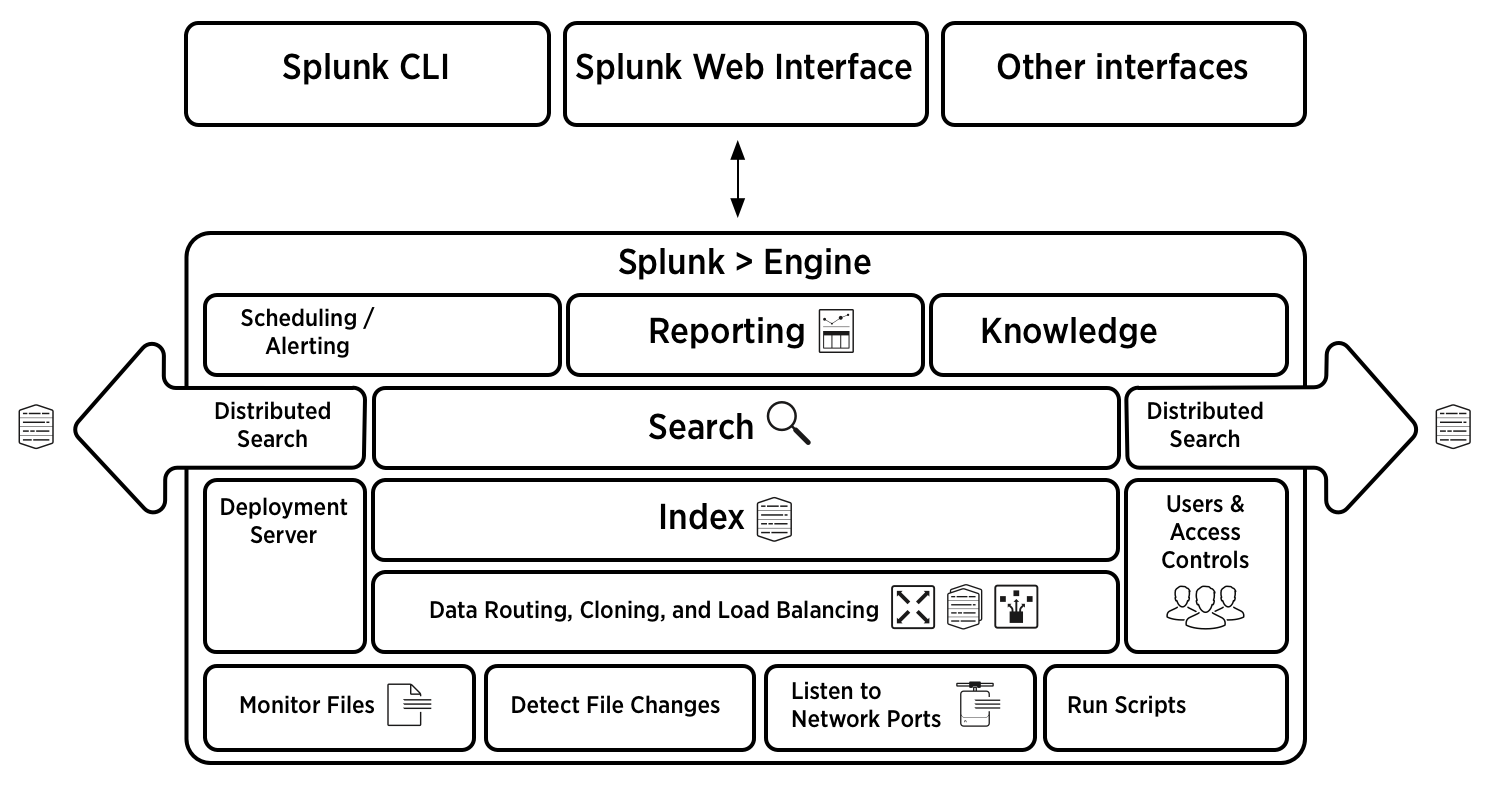
注意:负载均衡,副本!
Splunk Architecture
A Bit About Architecture
Splunk is a high performance, scalable software server written in C/C++ and Python. It indexes and searches logs and other IT data in real time. Splunk works with data generated by any application, server or device. The Splunk Developer API is accessible via REST, SOAP or the command line. After downloading, installing and starting Splunk, you'll find two Splunk Server processes running on your host, splunkd and splunkweb.
- splunkd is a distributed C/C++ server that accesses, processes and indexes streaming IT data and also handles search requests. splunkd processes and indexes your data by streaming it through a series of pipelines, each made up of a series of processors. Pipelines are single threads inside the splunkd process, each configured with a single snippet of XML. Processors are individual, reusable C/C++ or Python functions that act on the stream of IT data passing through a pipeline. Pipelines can pass data to one another via queues. splunkd supports a command line interface for searching and viewing results.
- splunkweb is a Python-based application server providing the Splunk Web user interface. It allows users to search and navigate IT data stored by Splunk servers and to manage your Splunk deployment through the browser interface. splunkweb communicates with your web browser via REST and communicates with splunkd via SOAP.

- Splunk's Data Store manages the original raw data in compressed format as well as the indexes into the data. Data can be deleted or archived based on retention period or maximum data store size.
- Splunk Servers can communicate with one another via Splunk-2-Splunk, a TCP-based protocol, to forward data from one server to another and to distribute searches across multiple servers.
- Bundles are files that contain configuration settings including, user accounts, Splunks, Live Splunks, Data Inputs and Processing Properties to easily create specific Splunk environments.
- Modules are files that add new functionality to Splunk by adding to or modifying existing processors and pipelines.
About forwarding and receiving
You can forward data from one Splunk instance to another Splunk server or even to a non-Splunk system. The Splunk instance that performs theforwarding is typically a smaller footprint version of Splunk, called a forwarder.
A Splunk instance that receives data from one or more forwarders is called a receiver. The receiver is usually a Splunk indexer, but can also be another forwarder, as described here.
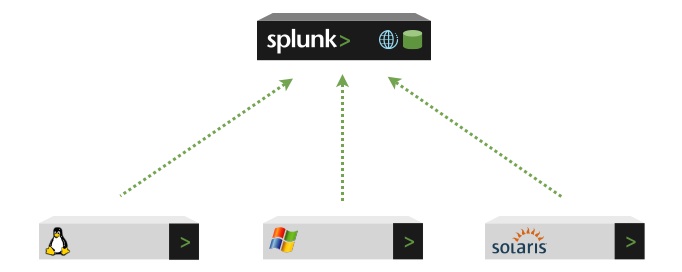
This diagram shows three forwarders sending data to a single Splunk receiver (an indexer), which then indexes the data and makes it available for searching:
Splunk Enterprise architecture——转发器本质上是日志收集client附加负载均衡,indexer是分布式索引,外加一个集中式管理协调的中心节点的更多相关文章
- Jexus是一款Linux平台上的高性能WEB服务器和负载均衡网关
什么是Jexus Jexus是一款Linux平台上的高性能WEB服务器和负载均衡网关,以支持ASP.NET.ASP.NET CORE.PHP为特色,同时具备反向代理.入侵检测等重要功能.可以这样说,J ...
- 动态DNS——本质上是IP变化,将任意变换的IP地址绑定给一个固定的二级域名。不管这个线路的IP地址怎样变化,因特网用户还是可以使用这个固定的域名 这样看的话,p2p可以用哇
动态域名是因应网络远程访问的需要而产生的一项应用技术.因为没有固定IP,只能运用二级域名来应对经常变化的IP,动态域名的由来因此而产生. 它当前主要应用在:路由器.网络摄像机.带网络监控的硬盘录像机. ...
- Linux下Rsyslog日志远程集中式管理
Rsyslog简介 Rsyslog的全称是 rocket-fast system for log,它提供了高性能,高安全功能和模块化设计.rsyslog能够接受从各种各样的来源,将其输入,输出的结果到 ...
- Dubbo入门到精通学习笔记(二十):MyCat在MySQL主从复制的基础上实现读写分离、MyCat 集群部署(HAProxy + MyCat)、MyCat 高可用负载均衡集群Keepalived
文章目录 MyCat在MySQL主从复制的基础上实现读写分离 一.环境 二.依赖课程 三.MyCat 介绍 ( MyCat 官网:http://mycat.org.cn/ ) 四.MyCat 的安装 ...
- Centos7搭建集中式日志系统
在CentOS7中,Rsyslong是一个集中式的日志收集系统,可以运行在TCP或者UDP的514端口上. 目录 开始之前 配置接收日志的主机 配置发送日志的主机 日志回滚 附件:创建日志接收模板 ...
- flume集群日志收集
一.Flume简介 Flume是一个分布式的.高可用的海量日志收集.聚合和传输日志收集系统,支持在日志系统中定制各类数据发送方(如:Kafka,HDFS等),便于收集数据.其核心为agent,agen ...
- ELK日志收集平台部署
需求背景 由于公司的后台服务有三台,每当后台服务运行异常,需要看日志排查错误的时候,都必须开启3个ssh窗口进行查看,研发们觉得很不方便,于是便有了统一日志收集与查看的需求. 这里,我用ELK集群,通 ...
- 理解OpenShift(6):集中式日志处理
理解OpenShift(1):网络之 Router 和 Route 理解OpenShift(2):网络之 DNS(域名服务) 理解OpenShift(3):网络之 SDN 理解OpenShift(4) ...
- SpringBoot+kafka+ELK分布式日志收集
一.背景 随着业务复杂度的提升以及微服务的兴起,传统单一项目会被按照业务规则进行垂直拆分,另外为了防止单点故障我们也会将重要的服务模块进行集群部署,通过负载均衡进行服务的调用.那么随着节点的增多,各个 ...
随机推荐
- Arduino使用HC05蓝牙模块与手机连接
Arduino使用HC05蓝牙模块与手机连接 一切都是最好的选择 首先是线路连接,一定不要接错了 Arduino 代码 #include <SoftwareSerial.h> // Pin ...
- 简单的Django实现图片上传,并存储进MySQL数据库 案例——小白
目标:通过网页上传一张图片到Django后台,后台接收并存储进数据库 真是不容易!!这个案例的代码网上太乱,不适合我,自己摸索着写,终于成功了,记录一下,仅供自己参考,有的解释可能不对,自己明白就好, ...
- 20145127《java程序设计》第二周学习总结
本周我又对java程序进行了更进一步的学习.相比与上一周的学习内容的宏观,这一周的所学更加的系统和调理明确. 本周是对java基础语法的学习.首先,我先是认识类型与变量. Java可区分为基本类型和类 ...
- Visual Studio 2012 编译错误【error C4996: 'scanf': This function or variable may be unsafe. 】的解决方案(转载)
转载:http://www.th7.cn/Program/c/201303/127343.shtml 原因是Visual C++ 2012 使用了更加安全的 run-time library rout ...
- java画流程图【思路】
java计算整数输入 <样例 画的第一张流程图 把脑子里的东西能清晰的表现出来 学编程必备
- [Pytorch]深度模型的显存计算以及优化
原文链接:https://oldpan.me/archives/how-to-calculate-gpu-memory 前言 亲,显存炸了,你的显卡快冒烟了! torch.FatalError: cu ...
- 04_kafka python客户端_Producer模拟
使用的python库: kafka-python 安装方式: pip install kafka-python 简单的模拟Producer """ Kafka Produ ...
- 在django restful framework中设置django model的property
众所周知,在django的model中,可以某些字段设置@property和setter deleter getter,这样就可以在存入数据的时候进行一些操作,具体原理请参见廖雪峰大神的博客https ...
- 【Mac常用shell】
1. 杀掉占用某端口的进程: lsof -i:9000 -> 确认PID kill PID 2. 环境变量: 直接用{PATH}:路径 的办法,经常不好用,我的解决办法: vi ~/.bas ...
- go变量赋初值
package main import "fmt" func variableinitial(){ , var s string="abc" fmt.Print ...