
【odoo】【知识点】生成pdf文件时缺少样式的问题
欢迎转载,但需标注出处,谢谢!
背景
近期在客户的项目中发现在自定义报表样式的时候,存在渲染为html正常,但是在生成pdf的时候,缺少样式的情况。
分析
涉及到的odoo源码中的ir_actions_report.py文件中的代码
    def _prepare_html(self, html):

        '''Divide and recreate the header/footer html by merging all found in html.

        The bodies are extracted and added to a list. Then, extract the specific_paperformat_args.

        The idea is to put all headers/footers together. Then, we will use a javascript trick

        (see minimal_layout template) to set the right header/footer during the processing of wkhtmltopdf.

        This allows the computation of multiple reports in a single call to wkhtmltopdf.

        :param html: The html rendered by render_qweb_html.

        :type: bodies: list of string representing each one a html body.

        :type header: string representing the html header.

        :type footer: string representing the html footer.

        :type specific_paperformat_args: dictionary of prioritized paperformat values.

        :return: bodies, header, footer, specific_paperformat_args

        '''

        IrConfig = self.env['ir.config_parameter'].sudo()

        base_url = IrConfig.get_param('report.url') or IrConfig.get_param('web.base.url')

        # Return empty dictionary if 'web.minimal_layout' not found.

        layout = self.env.ref('web.minimal_layout', False)

        if not layout:

            return {}

        layout = self.env['ir.ui.view'].browse(self.env['ir.ui.view'].get_view_id('web.minimal_layout'))

        root = lxml.html.fromstring(html)

        match_klass = "//div[contains(concat(' ', normalize-space(@class), ' '), ' {} ')]"

        header_node = etree.Element('div', id='minimal_layout_report_headers')

        footer_node = etree.Element('div', id='minimal_layout_report_footers')

        bodies = []

        res_ids = []

        body_parent = root.xpath('//main')[0]

        # Retrieve headers

        for node in root.xpath(match_klass.format('header')):

            body_parent = node.getparent()

            node.getparent().remove(node)

            header_node.append(node)

        # Retrieve footers

        for node in root.xpath(match_klass.format('footer')):

            body_parent = node.getparent()

            node.getparent().remove(node)

            footer_node.append(node)

        # Retrieve bodies

        for node in root.xpath(match_klass.format('article')):

            layout_with_lang = layout

            # set context language to body language

            if node.get('data-oe-lang'):

                layout_with_lang = layout_with_lang.with_context(lang=node.get('data-oe-lang'))

            body = layout_with_lang._render(dict(subst=False, body=lxml.html.tostring(node), base_url=base_url))

            bodies.append(body)

            if node.get('data-oe-model') == self.model:

                res_ids.append(int(node.get('data-oe-id', 0)))

            else:

                res_ids.append(None)

        if not bodies:

            body = bytearray().join([lxml.html.tostring(c) for c in body_parent.getchildren()])

            bodies.append(body)

        # Get paperformat arguments set in the root html tag. They are prioritized over

        # paperformat-record arguments.

        specific_paperformat_args = {}

        for attribute in root.items():

            if attribute[0].startswith('data-report-'):

                specific_paperformat_args[attribute[0]] = attribute[1]

        header = layout._render(dict(subst=True, body=lxml.html.tostring(header_node), base_url=base_url))

        footer = layout._render(dict(subst=True, body=lxml.html.tostring(footer_node), base_url=base_url))

        return bodies, res_ids, header, footer, specific_paperformat_args
- 我们可以看到在
base_url = IrConfig.get_param('report.url') or IrConfig.get_param('web.base.url')中取了系统参数中的report.url或web.base.url中的地址。 - 在
body = layout_with_lang._render(dict(subst=False, body=lxml.html.tostring(node), base_url=base_url))中渲染了我们必要的样式,若这里的url出错,那么这里我们将缺少样式内容。当然,若是全部都通过html原生去实现样式,那么也是可以避免如上的问题。
解决方案
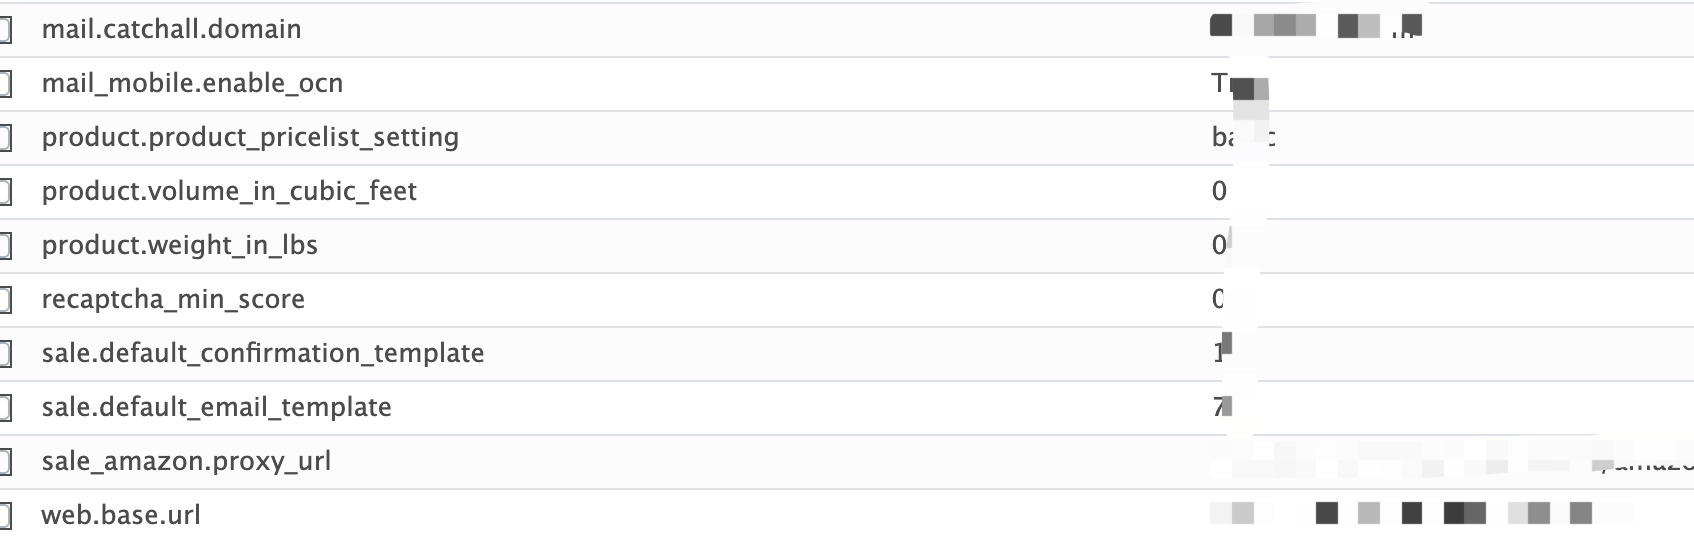
在系统参数添加report.url或者web.base.url的值为http://127.0.0.1:8069(填写本机的地址)
【odoo】【知识点】生成pdf文件时缺少样式的问题的更多相关文章
- 在js内生成PDF文件并下载的功能实现(不调用后端),以及生成pdf时换行的格式不被渲染,word-break:break-all
在js内生成PDF文件并下载的功能实现(不调用后端),以及生成pdf时换行的格式不被渲染,word-break:break-all 前天来了个新需求, 有一个授权书的文件要点击下载, 需要在前端生成, ...
- Itext生成pdf文件
来源:https://my.oschina.net/lujianing/blog/894365 1.背景 在某些业务场景中,需要提供相关的电子凭证,比如网银/支付宝中转账的电子回单,签约的电子合同等. ...
- Java 动态生成 PDF 文件
每片文章前来首小诗: 今日夕阳伴薄雾,印着雪墙笑开颜.我心仿佛出窗前,浮在半腰望西天. --泥沙砖瓦浆木匠 需求: 项目里面有需要java动态生成 PDF 文件,提供下载.今天我找了下有关了,系 ...
- JavaWeb项目生成PDF文件添加水印图片并导出
一.前言 首先需要在Maven中添加相应的jar包依赖,若项目没用到Maven,也可自行下载相应所需的jar包(itextpdf.jar 与 itext-asian.jar),如下图所示.点此下载 M ...
- Java生成PDF文件(转)
原文地址:https://www.cnblogs.com/shuilangyizu/p/5760928.html 一.前言 前几天,做ASN条码收货模块,需要实现打印下载收货报表,经一番查找,选定iT ...
- [itext]Java生成PDF文件
一.前言 最近在做也导出试卷的功能,刚开始是导出为doc,可是导出来格式都有变化,最后说直接将word转为pdf,可是各种不稳定,各种报错.最后想到直接将文件写入pdf(参考:http://www.c ...
- springMVC生成pdf文件
pom.xml文件配置=== <!-- https://mvnrepository.com/artifact/com.itextpdf/itextpdf --> <dependenc ...
- [轉載]史上最强php生成pdf文件,html转pdf文件方法
之前有个客户需要把一些html页面生成pdf文件,然后我就找一些用php把html页面围成pdf文件的类.方法是可谓是找了很多很多,什么html2pdf,pdflib,FPDF这些都试过了,但是都没有 ...
- 怎么用PHP在HTML中生成PDF文件
原文:Generate PDF from html using PHP 译文:使用PHP在html中生成PDF 译者:dwqs 利用PHP编码生成PDF文件是一个非常耗时的工作.在早期,开发者使用PH ...
随机推荐
- flyway实现java 自动升级SQL脚本
flyway实现java 自动升级SQL脚本 为什么要用Flyway 在日常开发中,我们经常会遇到下面的问题: 自己写的SQL忘了在所有环境执行: 别人写的SQL我们不能确定是否都在所有环境执行过了: ...
- PE文件头格式解析
前言: 昨天写了一题de1ctf的题,发现要脱壳,手脱之后发现要iat修复,我就发现自己在这块知识缺失了,win逆向,好像一直都是打ctf,然后用逆向方法论去肝的 其他方面倒是没有很深入学习,但实际上 ...
- diff -u:内核开发的新项目
译至:http://www.linuxjournal.com/content/diff-u-whats-new-kernel-development-1 Linux的一个问题是它的系统调用实现 . 正 ...
- NTP配置(广播模式并且无认证)
1.服务器端 1.1服务器本地同步自己的时钟,否则无法对外提供NTP服务 [NTP]ntp refclock-master 3 [NTP]ntp refclock-master 127.127.1.1 ...
- 从sql2008导入表结构及数据到mysql
打开navicat for mysql连接mysqlcreate database lianxi刷新,双击lianxi,双击"表"点击右边的"导入向导"选择&q ...
- .netcore第三方登录授权:10分钟急速接入
前言 很多对外应用的开发都考虑接入第三方登录来提高用户的体验感,避免用户进行繁琐的注册登录(登录后的完善资料必不可免). 而QQ.微信.支付宝.淘宝.微博等应用就是首选目标(无他,用户群体大,支持发开 ...
- Java核心基础第5篇-Java面向对象_类和对象
Java面向对象之类和对象 一.面向对象概述 Java是完全的面向对象编程(Object Oriented Programming),简称OOP. 面向对象编程的思维方式更加符合大家的日常生活,因为我 ...
- Unittest方法 -- 测试分离
一.下面是it.py 脚本,把浏览器前置和后置条件分离了"""套件公用测试类可进行分离"""import unittestfrom sele ...
- 足不出户,一探古今,打造线上3D数字博物馆!
随着3D技术的不断革新,为了让更多的用户领略历史之美,越来越多的博物馆开始举办线上展览.通过模拟不同的环境.灯光投影.360°无死角放大缩小展品,观众可以享受到身临其境的沉浸体验.不仅如此,给展品加上 ...
- Python将字符串转化为对应类名的两种方法
way first: 1 from django.utils.module_loading import import_string 2 ValidationError = import_string ...