
58.fetch phbase
1、fetch phbase工作流程
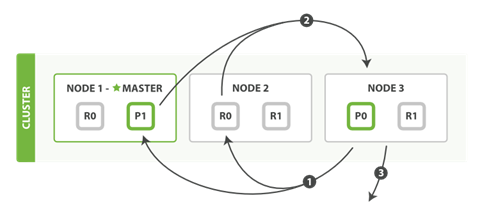
- The coordinating node identifies which documents need to be fetched and issues a multi GETrequest to the relevant shards.
- Each shard loads the documents and enriches them, if required, and then returns the documents to the coordinating node.
- Once all documents have been fetched, the coordinating node returns the results to the client.
The coordinating node first decides which documents actually need to be fetched. For instance, if our query specified { "from": 90, "size": 10 }, the first 90 results would be discarded and only the next 10 results would need to be retrieved. These documents may come from one, some, or all of the shards involved in the original search request.
The coordinating node builds a multi-get request for each shard that holds a pertinent document and sends the request to the same shard copy that handled the query phase.
The shard loads the document bodies—the _source field—and, if requested, enriches the results with metadata and search snippet highlighting. Once the coordinating node receives all results, it assembles them into a single response that it returns to the client.
(1)各个shard 返回的只是各文档的id和排序值( IDs and sort values ,coordinate node根据这些id&sort values 构建完priority queue之后,然后把程序需要的document 的id发送mget请求去所有shard上获取对应的document
(2)各个shard将document返回给coordinate node
(3)coordinate node将合并后的document结果返回给client客户端
2、一般搜索,如果不加from和size,就默认搜索前10条,按照_score排序
延伸阅读
The query-then-fetch process supports pagination with the from and size parameters, but within limits. Remember that each shard must build a priority queue of length from + size, all of which need to be passed back to the coordinating node. And the coordinating node needs to sort through number_of_shards * (from + size) documents in order to find the correct size documents.
Depending on the size of your documents, the number of shards, and the hardware you are using, paging 10,000 to 50,000 results (1,000 to 5,000 pages) deep should be perfectly doable. But with big-enough from values, the sorting process can become very heavy indeed, using vast amounts of CPU, memory, and bandwidth. For this reason, we strongly advise against deep paging.
In practice, "deep pagers" are seldom human anyway. A human will stop paging after two or three pages and will change the search criteria. The culprits are usually bots or web spiders that tirelessly keep fetching page after page until your servers crumble at the knees.
If you do need to fetch large numbers of docs from your cluster, you can do so efficiently by disabling sorting with the scroll query, which we discuss later in this chapter.
58.fetch phbase的更多相关文章
- ES--06
第51.初识搜索引擎_上机动手实战多搜索条件组合查询 课程大纲 GET /website/article/_search{ "query": { "bool": ...
- Swift - 后台获取数据(Background Fetch)的实现
前面讲了如何让程序申请后台短时运行.但这个额外延长的时间毕竟有限.所以从iOS7起又引入两种在后台运行任务的方式:后台获取和后台通知. 1,后台获取介绍 后台获取(Background Fetch)是 ...
- FW: How to use Hibernate Lazy Fetch and Eager Fetch Type – Spring Boot + MySQL
原帖 https://grokonez.com/hibernate/use-hibernate-lazy-fetch-eager-fetch-type-spring-boot-mysql In the ...
- python 读写西门子PLC 包含S7协议和Fetch/Write协议,s7支持200smart,300PLC,1200PLC,1500PLC
本文将使用一个gitHub开源的组件技术来读写西门子plc数据,使用的是基于以太网的TCP/IP实现,不需要额外的组件,读取操作只要放到后台线程就不会卡死线程,本组件支持超级方便的高性能读写操作 nu ...
- kafka启动失败错误:: replica.fetch.max.bytes should be equal or greater than message.max.bytes
1 详细异常 2019-10-14 14:38:21,260 FATAL kafka.Kafka$: java.lang.IllegalArgumentException: requirement f ...
- Git 少用 Pull 多用 Fetch 和 Merge
本文有点长而且有点乱,但就像Mark Twain Blaise Pascal的笑话里说的那样:我没有时间让它更短些.在Git的邮件列表里有很多关于本文的讨论,我会尽量把其中相关的观点列在下面. 我最常 ...
- git提示:Fatal:could not fetch refs from ....
在git服务器上新建项目提示: Fatal:could not fetch refs from git..... 百度搜索毫无头绪,最后FQgoogle,找到这篇文章http://www.voidcn ...
- sublime 插件推荐: Nettuts+ Fetch
Nettuts+ Fetch github地址:Nettuts-Fetch 在sublime中直接用 ctrl+shift+P -> pci -> Nettuts-Fetch 即可下载 这 ...
- git pull和git fetch的区别
Git中从远程的分支获取最新的版本到本地有这样2个命令:1. git fetch:相当于是从远程获取最新版本到本地,不会自动merge Git fetch origin master git log ...
随机推荐
- rac_grid自检无法正常进行报PRVF-4007
原创作品,出自 "深蓝的blog" 博客.欢迎转载,转载时请务必注明下面出处.否则追究版权法律责任. 深蓝的blog:http://blog.csdn.net/huangyanlo ...
- rnnlm源代码分析(八)
系列前言 參考文献: RNNLM - Recurrent Neural Network Language Modeling Toolkit(点此阅读) Recurrent neural networ ...
- xpath元素查找提示is not clickable
1.用xpath可以在chrome找到 $x("//mandatory-config-dialog[@is-show='isShowMandatoryConfig']/div/div[2]/ ...
- Hadop使用Partitioner后,结果还是一个文件,怎样解决??
近期看了一下partitioner.于是照着写了一个列子.最后发现程序并没有将结果分开写入对应的文件,结果还是一个文件,于是乎感觉是不是没实用集群去执行程序,发现control中还是本地执行的代码: ...
- android.os.Process.killProcess(android.os.Process.myPid())与Activity生命周期的影响
如果通过finish方法结束了一个Activity,那么根据Activity的生命周期,则会自动调用Activity的销毁方法onDestory(),但是在项目中遇到这样的一个问题,就是Activi ...
- C#可定制的数据库备份和恢复程序 (讲解流程)
可定制的数据库备份和恢复程序 tashanzhishi [原作] 关键字 数据库 备份 恢复 出处 在我们做数据库系统的程序时,经常需要为客户做一个数据库的备份和恢复程序,特别是对于一些非专业的数据库 ...
- 曼哈顿距离 C++
template <class T1, class T2>double ManhattanDistance(std::vector<T1> &inst1, std::v ...
- 267C
二分+高斯消元 我们利用物理里的势能来表示,每个点有一个势能h,再由流量守恒可以得到deg[x]*h[x]=sigma(h[y]) 如果x,y之间有边.这个式子是由流量守恒推出的,所以当x=1或n是不 ...
- iOS中的数据库—使用FMDB
一.回顾 iOS中的数据存储方式 1.XML属性列表(plist) 写入OC的一些基本数据类型,不是所有对象都可以写入 2.Preference(偏好设置) 本质还是通过“plist”来存储数据,但是 ...
- Android网络连接监听
接收系统网络服务的广播接收者 public class NetStateReceiver extends BroadcastReceiver { private Handler handler; pu ...