
Flink(四) —— 数据流编程模型
分层抽象
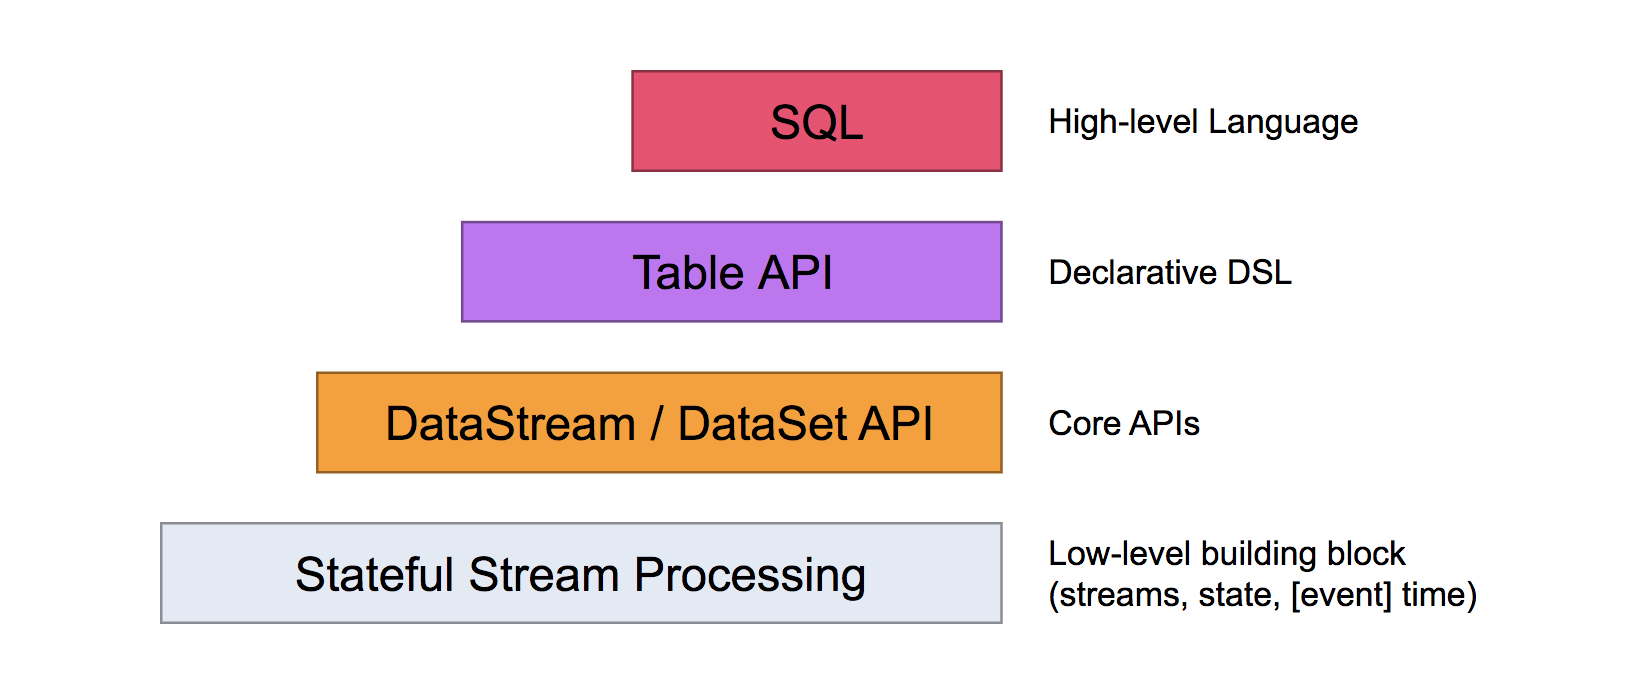
The lowest level abstraction simply offers stateful streaming. It is embedded into the DataStream API via the Process Function. It allows users freely process events from one or more streams, and use consistent fault tolerant state. In addition, users can register event time and processing time callbacks, allowing programs to realize sophisticated computations.
最低层次的抽象仅提供有状态流。它通过Process函数嵌入到DataStream API中。它允许用户自由地处理来自一个或多个流的事件,并使用一致的容错状态。此外,用户可以注册事件时间和处理时间回调,允许程序实现复杂的计算。
In practice, most applications would not need the above described low level abstraction, but would instead program against the Core APIs like the DataStream API (bounded/unbounded streams) and the DataSet API (bounded data sets). These fluent APIs offer the common building blocks for data processing, like various forms of user-specified transformations, joins, aggregations, windows, state, etc. Data types processed in these APIs are represented as classes in the respective programming languages.
在实践中,大多数应用程序不需要上面描述的低级抽象,而是对核心API进行编程,比如DataStream API(有界或无界数据流)和DataSet API(有界数据集)。这些API提供了用于数据处理的通用构建块,比如由用户定义的多种形式的转换、连接、聚合、窗口、状态等。在这些api中处理的数据类型以类(class)的形式由各自的编程语言所表示。
The low level Process Function integrates with the DataStream API, making it possible to go the lower level abstraction for certain operations only. The DataSet API offers additional primitives on bounded data sets, like loops/iterations.
低级流程函数与DataStream API集成,使得只对某些操作进行低级抽象成为可能。DataSet API为有界数据集提供了额外的原语,比如循环或迭代。
The Table API is a declarative DSL centered around tables, which may be dynamically changing tables (when representing streams). The Table API follows the (extended) relational model: Tables have a schema attached (similar to tables in relational databases) and the API offers comparable operations, such as select, project, join, group-by, aggregate, etc. Table API programs declaratively define what logical operation should be done rather than specifying exactly how the code for the operation looks. Though the Table API is extensible by various types of user-defined functions, it is less expressive than the Core APIs, but more concise to use (less code to write). In addition, Table API programs also go through an optimizer that applies optimization rules before execution.
Table API是一个以表为中心的声明性DSL,其中表可以动态地改变(当表示流数据时)。表API遵循(扩展)关系模型:表有一个附加模式(类似于关系数据库表)和API提供了类似的操作,如select, project, join, group-by, aggregate 等。Table API 程序以声明的方式定义逻辑操作应该做什么而不是指定操作的代码看起来如何。虽然Table API可以通过各种用户定义函数进行扩展,但它的表达性不如核心API,但使用起来更简洁(编写的代码更少)。此外,Table API程序还可以在执行之前通过应用优化规则的优化器。
One can seamlessly convert between tables and DataStream/DataSet, allowing programs to mix Table API and with the DataStream and DataSet APIs.
可以无缝地在Table API和DataStream/DataSet API之间进行切换,允许程序将Table API和DataStream和DataSet API进行混合使用。
The highest level abstraction offered by Flink is SQL. This abstraction is similar to the Table API both in semantics and expressiveness, but represents programs as SQL query expressions. The SQL abstraction closely interacts with the Table API, and SQL queries can be executed over tables defined in the Table API.
Flink提供的最高级别抽象是SQL。这种抽象在语义和表示方面都类似于Table API,但将程序表示为SQL查询表达式。SQL抽象与表API密切交互,SQL查询可以在表API中定义的表上执行。
参考文档
Flink Dataflow Programming Model
Flink(四) —— 数据流编程模型的更多相关文章
- [Note] Apache Flink 的数据流编程模型
Apache Flink 的数据流编程模型 抽象层次 Flink 为开发流式应用和批式应用设计了不同的抽象层次 状态化的流 抽象层次的最底层是状态化的流,它通过 ProcessFunction 嵌入到 ...
- flink原理介绍-数据流编程模型v1.4
数据流编程模型 抽象级别 程序和数据流 并行数据流 窗口 时间 有状态操作 检查点(checkpoint)容错 批量流处理 下一步 抽象级别 flink针对 流式/批处理 应用提供了不同的抽象级别. ...
- Flink入门(四)——编程模型
flink是一款开源的大数据流式处理框架,他可以同时批处理和流处理,具有容错性.高吞吐.低延迟等优势,本文简述flink的编程模型. 数据集类型: 无穷数据集:无穷的持续集成的数据集合 有界数据集:有 ...
- Apache Flink 数据流编程模型
抽象等级(Levels of Abstraction) Flink提供不同级别的抽象来开发流/批处理应用程序. Statefule Stream Processing: 是最低级别(底层)的抽象,只提 ...
- 第03讲:Flink 的编程模型与其他框架比较
Flink系列文章 第01讲:Flink 的应用场景和架构模型 第02讲:Flink 入门程序 WordCount 和 SQL 实现 第03讲:Flink 的编程模型与其他框架比较 本课时我们主要介绍 ...
- 五十四、linux 编程——TCP 编程模型
54.1 编程模型介绍 54.1.1 TCP 客户端服务器编程模型 客户端调用序列 调用 socket 函数创建套接字 调用 connect 连接服务器端 调用 I/O 函数(read/write) ...
- spark概念、编程模型和模块概述
http://blog.csdn.net/pipisorry/article/details/50931274 spark基本概念 Spark一种与 Hadoop 相似的通用的集群计算框架,通过将大量 ...
- DataFlow编程模型与Spark Structured streaming
流式(streaming)和批量( batch):流式数据,实际上更准确的说法应该是unbounded data(processing),也就是无边界的连续的数据的处理:对应的批量计算,更准确的说法是 ...
- MapReduce编程模型及其在Hadoop上的实现
转自:https://www.zybuluo.com/frank-shaw/note/206604 MapReduce基本过程 关于MapReduce中数据流的传输过程,下图是一个经典演示: 关于上 ...
随机推荐
- 锤子科技向OpenBSD基金会捐款195 万
导读 专注于提供 OpenBSD 资讯的网站 OpenBSD Journal 昨日报道了锤子科技成为 OpenBSD 基金会 2019 年首位铱金捐赠者的消息. 根据 OpenBSD Journal ...
- 如何创建一个Asp .Net Web Api项目
1.点击文件=>新建=>项目 2.创建一个Asp .NET Web项目 3.选择Empty,然后选中下面的MVC和Web Api,也可以直接选择Web Api选项,注意将身份验证设置为无身 ...
- codeforces 594
D 给你一个长度为n的括号序列,然后你可以选择交换两个位置,你需要使得能够变成 合法括号序列的起点最多. 题解 人尽皆知的东西:合法的括号序列是,令'('为1,')'为-1,那么前缀和需要>=0 ...
- C#无边框应用
引用using System.Runtime.InteropServices; 在窗体的全局模式下输入 [DllImport("user32.dll")] public stati ...
- 用Git管理项目进行版本控制
一.安装 1.1windows 要在Windows系统中安装Git,请访问http://msysgit.github.io/,并单击Download.安装. 1.2 在 Linux 系统中安装 Git ...
- TRUNC()函数——oracle
使用trunc()函数获取不同的日期: select trunc(sysdate) from dual; --今天的日期 select trunc(sysdate,'dd') from dual; - ...
- bash 内嵌命令 printf 用于进制转换
printf - 格式化并显示数据 printf "%d" 0x10 printf "%x" 16
- 【转】selenium技巧 - 通过js来控制滚动条,通过xpath定位最上层的div层
http://blog.csdn.net/iceryan/article/details/8162703 业务流程: 1.打开此网页 http://nanjing.xiaomishu.com/sh ...
- UVA - 11212 Editing a Book(IDA*算法+状态空间搜索)
题意:通过剪切粘贴操作,将n个自然段组成的文章,排列成1,2,……,n.剪贴板只有一个,问需要完成多少次剪切粘贴操作可以使文章自然段有序排列. 分析: 1.IDA*搜索:maxn是dfs的层数上限,若 ...
- 每天一点点之vue框架开发 - vue坑-input 的checked渲染问题
选中radio或者checkbox需要注意的是: 不管<input type='radio checked='true''> 你的checked属性值是true或者false,他都会选中 ...