
三.hadoop mapreduce之WordCount例子
目录:
这个案列完成对单词的计数,重写map,与reduce方法,完成对mapreduce的理解。
Mapreduce初析
Mapreduce是一个计算框架,既然是做计算的框架,那么表现形式就是有个输入(input),mapreduce操作这个输入(input),通过本身定义好的计算模型,得到一个输出(output),这个输出就是我们所需要的结果。
我们要学习的就是这个计算模型的运行规则。在运行一个mapreduce计算任务时候,任务过程被分为两个阶段:map阶段和reduce阶段,每个阶段都是用键值对(key/value)作为输入(input)和输出(output)。而程序员要做的就是定义好这两个阶段的函数:map函数和reduce函数。
1.准备 w.txt 文件,用于当测试数据
yaojiale hahaha

yaojiale llllll
2.构建maven项目,将WordCount类打包成mrtest.jar.丢到hadoop所在服务器上
pom.xml
<!-- https://mvnrepository.com/artifact/org.apache.hadoop/hadoop-common -->

        <dependency>

            <groupId>org.apache.hadoop</groupId>

            <artifactId>hadoop-common</artifactId>

            <version>2.7.3</version>

        </dependency>

        <!-- https://mvnrepository.com/artifact/org.apache.hadoop/hadoop-mapreduce-client-core -->

        <dependency>

            <groupId>org.apache.hadoop</groupId>

            <artifactId>hadoop-mapreduce-client-core</artifactId>

            <version>2.7.3</version>

        </dependency>

        <!-- 加上这个就不报本地某错了 Cannot initialize Cluster

  https://mvnrepository.com/artifact/org.apache.hadoop/hadoop-mapreduce-client-common -->

        <dependency>

            <groupId>org.apache.hadoop</groupId>

            <artifactId>hadoop-mapreduce-client-common</artifactId>

            <version>2.6.4</version>

        </dependency>
WordCount.java 代码:
package org.apache.hadoop.examples;

import java.io.IOException;

import java.util.StringTokenizer;

import org.apache.hadoop.conf.Configuration;

import org.apache.hadoop.fs.Path;

import org.apache.hadoop.io.IntWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.Job;

import org.apache.hadoop.mapreduce.Mapper;

import org.apache.hadoop.mapreduce.Reducer;

import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import org.apache.hadoop.util.GenericOptionsParser;

public class WordCount {

//WordCOuntMap方法接收LongWritable,Text的参数,返回<Text, IntWriatable>键值对。

  public static class TokenizerMapper extends Mapper<Object, Text, Text, IntWritable>{

    private final static IntWritable one = new IntWritable(1);

    private Text word = new Text();

    public void map(Object key, Text value, Context context) throws IOException, InterruptedException {

      StringTokenizer itr = new StringTokenizer(value.toString());

      while (itr.hasMoreTokens()) {

        word.set(itr.nextToken());

        context.write(word, one);

      }

    }

  }

  public static class IntSumReducer extends Reducer<Text,IntWritable,Text,IntWritable> {

    private IntWritable result = new IntWritable();

    public void reduce(Text key, Iterable<IntWritable> values,Context context) throws IOException, InterruptedException {

      int sum = 0;

      for (IntWritable val : values) {

        sum += val.get();

      }

      result.set(sum);

      context.write(key, result);

    }

  }

  public static void main(String[] args) throws Exception {

    Configuration conf = new Configuration();

    String[] otherArgs = new GenericOptionsParser(conf, args).getRemainingArgs();

    if (otherArgs.length != 2) {

      System.err.println("Usage: wordcount <in> <out>");

      System.exit(2);

    }

    Job job = new Job(conf, "word count");

    job.setJarByClass(WordCount.class);

    job.setMapperClass(TokenizerMapper.class);

    job.setCombinerClass(IntSumReducer.class);

    job.setReducerClass(IntSumReducer.class);

    job.setOutputKeyClass(Text.class);

    job.setOutputValueClass(IntWritable.class);

    FileInputFormat.addInputPath(job, new Path(otherArgs[0]));

    FileOutputFormat.setOutputPath(job, new Path(otherArgs[1]));

    System.exit(job.waitForCompletion(true) ? 0 : 1);

  }

}
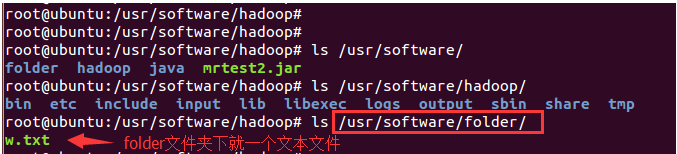
2.将w.txt放到hdfs下(folder下有w.txt文件)
bin/hdfs dfs -put /usr/software/folder input
然后查看
root@ubuntu:/usr/software/hadoop# bin/hdfs dfs -ls

Found 1 items

drwxr-xr-x   - root supergroup          0 2018-07-16 21:50 input //内有w.txt文件
3.运行程序统计WordCount
bin/hadoop jar /usr/software/mrtest2.jar input output
然后查看可得
root@ubuntu:/usr/software/hadoop# bin/hdfs dfs -ls
Found 2 items
drwxr-xr-x - root supergroup 0 2018-07-16 21:50 input
drwxr-xr-x - root supergroup 0 2018-07-16 22:18 output
root@ubuntu:/usr/software/hadoop# bin/hdfs dfs -cat output/*
hahaha 1
llllll 1
yaojiale 2
完毕。
附录:附上一个hadoop自带的例子:
计算圆周率
 bin/hadoop jar share/hadoop/mapreduce/hadoop-mapreduce-examples-2.7..jar pi  1000

result:
Estimated value of Pi is 3.14000000000000000000
参考文章:
Hadoop之MapReduce的HelloWorld(七)
三.hadoop mapreduce之WordCount例子的更多相关文章
- hadoop学习第三天-MapReduce介绍&&WordCount示例&&倒排索引示例
一.MapReduce介绍 (最好以下面的两个示例来理解原理) 1. MapReduce的基本思想 Map-reduce的思想就是“分而治之” Map Mapper负责“分”,即把复杂的任务分解为若干 ...
- hadoop安装与WordCount例子
1.JDK安装 下载网址: http://www.oracle.com/technetwork/java/javase/downloads/jdk-6u29-download-513648.html ...
- Hadoop Mapreduce 案例 wordcount+统计手机流量使用情况
mapreduce设计思想 概念:它是一个分布式并行计算的应用框架它提供相应简单的api模型,我们只需按照这些模型规则编写程序,即可实现"分布式并行计算"的功能. 案例一:word ...
- RedHat 安装Hadoop并运行wordcount例子
1.安装 Red Hat 环境 2.安装JDK 3.下载hadoop2.8.0 http://mirrors.tuna.tsinghua.edu.cn/apache/hadoop/common/had ...
- Hadoop Mapreduce中wordcount 过程解析
将文件split 文件1: 分割结果: hello world ...
- Hadoop实战3:MapReduce编程-WordCount统计单词个数-eclipse-java-ubuntu环境
之前习惯用hadoop streaming环境编写python程序,下面总结编辑java的eclipse环境配置总结,及一个WordCount例子运行. 一 下载eclipse安装包及hadoop插件 ...
- hadoop的wordcount例子运行
可以通过一个简单的例子来说明MapReduce到底是什么: 我们要统计一个大文件中的各个单词出现的次数.由于文件太大.我们把这个文件切分成如果小文件,然后安排多个人去统计.这个过程就是”Map”.然后 ...
- 大数据技术 - 通俗理解MapReduce之WordCount(三)
上一章我们编写了简单的 MapReduce 程序,掌握这些就能编写大多数数据处理的代码.但是 MapReduce 框架提供给用户的能力并不止如此,本章我们仍然以上一章 word count 为例,继续 ...
- Hadoop化繁为简(三)—探索Mapreduce简要原理与实践
目录-探索mapreduce 1.Mapreduce的模型简介与特性?Yarn的作用? 2.mapreduce的工作原理是怎样的? 3.配置Yarn与Mapreduce.演示Mapreduce例子程序 ...
随机推荐
- MySQL绿色版安装整套流程
https://www.cnblogs.com/LiuChunfu/p/6426918.html
- gradle记录
set-env.bat set "JAVA_HOME=G:\jdk" set "CLASSPATH=%JAVA_HOME%\lib\dt.jar;%JAVA_HOME%\ ...
- Netty源码学习笔记
1.ByteBuf
- 在Linux环境下使用Jexus部署ASP.NET Core
关于如何在Linux中添加ASP.NET Core运行时环境请参考我的上一篇文章,本文章将不再做赘述. 本文章运行环境如下: (1) 安装独立版Jexus 本教程安装的是独立版的Jexus,独立版的 ...
- 【C++】一篇文章,让你不再害怕指针
在C++中,比较难以理解的就是指针,最常用的也是指针.这篇文章,结合我的所学,所看,来谈谈C++中的指针 指针是什么 指针是一个特殊的变量,指向内存中的一个地址.它具有四个要素: 指针类型:即指针本身 ...
- dubbo的本地存根(Stub)
dubbo的本地存根的原理是:远程服务后,客户端通常只剩下接口,而实现全在服务器端,但提供方有些时候想在客户端也执行部分逻辑,那么就在服务消费者这一端提供了一个Stub类,然后当消费者调用provid ...
- python3+selenium入门14-上传下载文件
上传文件一种方式是通过定位input标签,然后使用send_keys()方法传入需要上传文件的路径.另一种是使用第三方插件去上传文件.下面看下imput标签的方式.工具可以自己查下. <!DOC ...
- UPS不间断电源工作原理简述
原文地址:https://blog.csdn.net/uamix/article/details/52776297 一.定义 UPS即不间断电源,是将蓄电池(多为铅酸免维护蓄电池)与主机相连接,通过主 ...
- 在VS解决方案资源管理器中自动定位当前编辑中的文件
依次点击 [工具]- [选项] - [项目和解决方案]-[常规]- 勾选[在解决方案资源管理器中跟踪活动项]
- web@css盒模型详解
Margin(外边距) - 清除边框外的区域,外边距是透明的./*上 右 下 左*/ 上 左右 下 /*上下 左右*/ 四方 /Border(边框) - 围绕在内边距和内容外的边框. 可以用 ...