
Hadoop源码篇--Reduce篇
一。前述
Reduce文件会从Mapper任务中拉取很多小文件,小文件内部有序,但是整体是没序的,Reduce会合并小文件,然后套个归并算法,变成一个整体有序的文件。
二。代码
ReduceTask源码:
 public void run(JobConf job, final TaskUmbilicalProtocol umbilical)

    throws IOException, InterruptedException, ClassNotFoundException {

    job.setBoolean(JobContext.SKIP_RECORDS, isSkipping());

    if (isMapOrReduce()) {

      copyPhase = getProgress().addPhase("copy");

      sortPhase  = getProgress().addPhase("sort");

      reducePhase = getProgress().addPhase("reduce");

    }

    // start thread that will handle communication with parent

    TaskReporter reporter = startReporter(umbilical);

    boolean useNewApi = job.getUseNewReducer();

    initialize(job, getJobID(), reporter, useNewApi);

    // check if it is a cleanupJobTask

    if (jobCleanup) {

      runJobCleanupTask(umbilical, reporter);

      return;

    }

    if (jobSetup) {

      runJobSetupTask(umbilical, reporter);

      return;

    }

    if (taskCleanup) {

      runTaskCleanupTask(umbilical, reporter);

      return;

    }

    // Initialize the codec

    codec = initCodec();

    RawKeyValueIterator rIter = null;

    ShuffleConsumerPlugin shuffleConsumerPlugin = null;

    Class combinerClass = conf.getCombinerClass();

    CombineOutputCollector combineCollector =

      (null != combinerClass) ?

     new CombineOutputCollector(reduceCombineOutputCounter, reporter, conf) : null;

    Class<? extends ShuffleConsumerPlugin> clazz =

          job.getClass(MRConfig.SHUFFLE_CONSUMER_PLUGIN, Shuffle.class, ShuffleConsumerPlugin.class);

    shuffleConsumerPlugin = ReflectionUtils.newInstance(clazz, job);

    LOG.info("Using ShuffleConsumerPlugin: " + shuffleConsumerPlugin);

    ShuffleConsumerPlugin.Context shuffleContext =

      new ShuffleConsumerPlugin.Context(getTaskID(), job, FileSystem.getLocal(job), umbilical,

                  super.lDirAlloc, reporter, codec,

                  combinerClass, combineCollector,

                  spilledRecordsCounter, reduceCombineInputCounter,

                  shuffledMapsCounter,

                  reduceShuffleBytes, failedShuffleCounter,

                  mergedMapOutputsCounter,

                  taskStatus, copyPhase, sortPhase, this,

                  mapOutputFile, localMapFiles);

    shuffleConsumerPlugin.init(shuffleContext);

    rIter = shuffleConsumerPlugin.run();//按顺序迭代

    // free up the data structures

    mapOutputFilesOnDisk.clear();

    sortPhase.complete();                         // sort is complete

    setPhase(TaskStatus.Phase.REDUCE);

    statusUpdate(umbilical);

    Class keyClass = job.getMapOutputKeyClass();

    Class valueClass = job.getMapOutputValueClass();

    RawComparator comparator = job.getOutputValueGroupingComparator();//分组比较 对应解析源码1

    if (useNewApi) {

      runNewReducer(job, umbilical, reporter, rIter, comparator, //对应解析源码2

                    keyClass, valueClass);

    } else {

      runOldReducer(job, umbilical, reporter, rIter, comparator,

                    keyClass, valueClass);

    }

    shuffleConsumerPlugin.close();

    done(umbilical, reporter);

  }

 源码1:分组比较器的源码

public RawComparator getOutputValueGroupingComparator() {

    Class<? extends RawComparator> theClass = getClass(

      JobContext.GROUP_COMPARATOR_CLASS, null, RawComparator.class);//用户没有设置分组比较器的时候,用默认的

    if (theClass == null) {

      return getOutputKeyComparator();//对应解析源码1.1

    }

    return ReflectionUtils.newInstance(theClass, this);

  }
源码1.1排序比较器,当用户不设置的时候取排序比较器实现,此时如果用户配置排序比较器,用排序比较器,没有的话用默认的Key的比较器
  public RawComparator getOutputKeyComparator() {

    Class<? extends RawComparator> theClass = getClass(

      JobContext.KEY_COMPARATOR, null, RawComparator.class);

    if (theClass != null)

      return ReflectionUtils.newInstance(theClass, this);

    return WritableComparator.get(getMapOutputKeyClass().asSubclass(WritableComparable.class), this);

  }
总结:
在Map端是真正改变(调整)Key的顺序的,在Reduce端是不会真正改变(调整)拉过来的其顺序的,Reduce不会重新排序,Reduce端强依赖Map端的输出。
解析源码2:runNewReduce的实现
void runNewReducer(JobConf job,

                     final TaskUmbilicalProtocol umbilical,

                     final TaskReporter reporter,

                     RawKeyValueIterator rIter,

                     RawComparator<INKEY> comparator,

                     Class<INKEY> keyClass,

                     Class<INVALUE> valueClass

                     ) throws IOException,InterruptedException,

                              ClassNotFoundException {

    // wrap value iterator to report progress.

    final RawKeyValueIterator rawIter = rIter;//真正的迭代器

    rIter = new RawKeyValueIterator() {

      public void close() throws IOException {

        rawIter.close();

      }

      public DataInputBuffer getKey() throws IOException {

        return rawIter.getKey();

      }

      public Progress getProgress() {

        return rawIter.getProgress();

      }

      public DataInputBuffer getValue() throws IOException {

        return rawIter.getValue();

      }

      public boolean next() throws IOException {

        boolean ret = rawIter.next();

        reporter.setProgress(rawIter.getProgress().getProgress());

        return ret;

      }

    };

    // make a task context so we can get the classes

    org.apache.hadoop.mapreduce.TaskAttemptContext taskContext =

      new org.apache.hadoop.mapreduce.task.TaskAttemptContextImpl(job,

          getTaskID(), reporter);

    // make a reducer

    org.apache.hadoop.mapreduce.Reducer<INKEY,INVALUE,OUTKEY,OUTVALUE> reducer =

      (org.apache.hadoop.mapreduce.Reducer<INKEY,INVALUE,OUTKEY,OUTVALUE>)

        ReflectionUtils.newInstance(taskContext.getReducerClass(), job);

    org.apache.hadoop.mapreduce.RecordWriter<OUTKEY,OUTVALUE> trackedRW =

      new NewTrackingRecordWriter<OUTKEY, OUTVALUE>(this, taskContext);

    job.setBoolean("mapred.skip.on", isSkipping());

    job.setBoolean(JobContext.SKIP_RECORDS, isSkipping());

    org.apache.hadoop.mapreduce.Reducer.Context

         reducerContext = createReduceContext(reducer, job, getTaskID(),

                                               rIter, reduceInputKeyCounter, //构建上下文的时候把迭代器传进来

                                               reduceInputValueCounter,

                                               trackedRW,

                                               committer,

                                               reporter, comparator, keyClass,//比较器  解析源码2.1

                                               valueClass);

    try {

      reducer.run(reducerContext);//构建完上下文之后运行Redude的Run方法 解析源码Reduce2.2

    } finally {

      trackedRW.close(reducerContext);

    }

  }
解析源码2.1: createReduceContext实现构建上下文的源码
public ReduceContextImpl(Configuration conf, TaskAttemptID taskid,

                           RawKeyValueIterator input, //把迭代器传给输入对象Input

                           Counter inputKeyCounter,

                           Counter inputValueCounter,

                           RecordWriter<KEYOUT,VALUEOUT> output,

                           OutputCommitter committer,

                           StatusReporter reporter,

                           RawComparator<KEYIN> comparator,

                           Class<KEYIN> keyClass,

                           Class<VALUEIN> valueClass

                          ) throws InterruptedException, IOException{

    super(conf, taskid, output, committer, reporter);

    this.input = input;

    this.inputKeyCounter = inputKeyCounter;

    this.inputValueCounter = inputValueCounter;

    this.comparator = comparator;

    this.serializationFactory = new SerializationFactory(conf);

    this.keyDeserializer = serializationFactory.getDeserializer(keyClass);

    this.keyDeserializer.open(buffer);

    this.valueDeserializer = serializationFactory.getDeserializer(valueClass);

    this.valueDeserializer.open(buffer);

    hasMore = input.next();

    this.keyClass = keyClass;

    this.valueClass = valueClass;

    this.conf = conf;

    this.taskid = taskid;

  }
/** Start processing next unique key. */
  public boolean nextKey() throws IOException,InterruptedException {//实际上Reduce中run方法中的contect.netKey调用的逻辑
    while (hasMore && nextKeyIsSame) {//第一次假 放空
      nextKeyValue();
    }
    if (hasMore) {
      if (inputKeyCounter != null) {
        inputKeyCounter.increment(1);
      }
      return nextKeyValue();
    } else {
      return false;
    }
  }

  /**
   * Advance to the next key/value pair.
   */
  @Override
  public boolean nextKeyValue() throws IOException, InterruptedException {
    if (!hasMore) {
      key = null;
      value = null;
      return false;
    }
    firstValue = !nextKeyIsSame;
    DataInputBuffer nextKey = input.getKey();
    currentRawKey.set(nextKey.getData(), nextKey.getPosition(),
                      nextKey.getLength() - nextKey.getPosition());
    buffer.reset(currentRawKey.getBytes(), 0, currentRawKey.getLength());
    key = keyDeserializer.deserialize(key);
    DataInputBuffer nextVal = input.getValue();
    buffer.reset(nextVal.getData(), nextVal.getPosition(), nextVal.getLength()
        - nextVal.getPosition());
    value = valueDeserializer.deserialize(value);

    currentKeyLength = nextKey.getLength() - nextKey.getPosition();
    currentValueLength = nextVal.getLength() - nextVal.getPosition();

    if (isMarked) {
      backupStore.write(nextKey, nextVal);
    }

    hasMore = input.next();
    if (hasMore) {
      nextKey = input.getKey();
      nextKeyIsSame = comparator.compare(currentRawKey.getBytes(), 0,
                                     currentRawKey.getLength(),
                                     nextKey.getData(),
                                     nextKey.getPosition(),
                                     nextKey.getLength() - nextKey.getPosition()
                                         ) == 0;//判断当前key和下一个Key是否相等。
    } else {
      nextKeyIsSame = false;
    }
    inputValueCounter.increment(1);
    return true;
  }

  public KEYIN getCurrentKey() {
    return key;
  }

  @Override
  public VALUEIN getCurrentValue() {
    return value;
  }
解析源码2.2 Reduce
/**

 * Licensed to the Apache Software Foundation (ASF) under one

 * or more contributor license agreements.  See the NOTICE file

 * distributed with this work for additional information

 * regarding copyright ownership.  The ASF licenses this file

 * to you under the Apache License, Version 2.0 (the

 * "License"); you may not use this file except in compliance

 * with the License.  You may obtain a copy of the License at

 *

 *     http://www.apache.org/licenses/LICENSE-2.0

 *

 * Unless required by applicable law or agreed to in writing, software

 * distributed under the License is distributed on an "AS IS" BASIS,

 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.

 * See the License for the specific language governing permissions and

 * limitations under the License.

 */

package org.apache.hadoop.mapreduce;

import java.io.IOException;

import org.apache.hadoop.classification.InterfaceAudience;

import org.apache.hadoop.classification.InterfaceStability;

import org.apache.hadoop.conf.Configuration;

import org.apache.hadoop.mapreduce.task.annotation.Checkpointable;

import java.util.Iterator;

 * public class IntSumReducer<Key> extends Reducer<Key,IntWritable,

 *                                                 Key,IntWritable> {

 *   private IntWritable result = new IntWritable();

 *

 *   public void reduce(Key key, Iterable<IntWritable> values,

 *                      Context context) throws IOException, InterruptedException {

 *     int sum = 0;

 *     for (IntWritable val : values) {

 *       sum += val.get();

 *     }

 *     result.set(sum);

 *     context.write(key, result);

 *   }

 * }

 * </pre></blockquote></p>

 *

 * @see Mapper

 * @see Partitioner

 */

@Checkpointable

@InterfaceAudience.Public

@InterfaceStability.Stable

public class Reducer<KEYIN,VALUEIN,KEYOUT,VALUEOUT> {

  /**

   * The <code>Context</code> passed on to the {@link Reducer} implementations.

   */

  public abstract class Context

    implements ReduceContext<KEYIN,VALUEIN,KEYOUT,VALUEOUT> {

  }

  /**

   * Called once at the start of the task.

   */

  protected void setup(Context context

                       ) throws IOException, InterruptedException {

    // NOTHING

  }

  /**

   * This method is called once for each key. Most applications will define

   * their reduce class by overriding this method. The default implementation

   * is an identity function.

   */

  @SuppressWarnings("unchecked")

  protected void reduce(KEYIN key, Iterable<VALUEIN> values, Context context

                        ) throws IOException, InterruptedException {

    for(VALUEIN value: values) {

      context.write((KEYOUT) key, (VALUEOUT) value);

    }

  }

  /**

   * Called once at the end of the task.

   */

  protected void cleanup(Context context

                         ) throws IOException, InterruptedException {

    // NOTHING

  }

  /**

   * Advanced application writers can use the

   * {@link #run(org.apache.hadoop.mapreduce.Reducer.Context)} method to

   * control how the reduce task works.

   */

  public void run(Context context) throws IOException, InterruptedException {

    setup(context);

    try {

      while (context.nextKey()) {//实际上在这一步里实际上调用了NextKeyValue的值更新了 hasmore,nextKeyisSame,Key,Value的值

        reduce(context.getCurrentKey(), context.getValues(), context);//解析源码2.2.1

        // If a back up store is used, reset it

        Iterator<VALUEIN> iter = context.getValues().iterator();

        if(iter instanceof ReduceContext.ValueIterator) {

          ((ReduceContext.ValueIterator<VALUEIN>)iter).resetBackupStore();

        }

      }

    } finally {

      cleanup(context);

    }

  }

}
源码2.2.1context.getValues的最终实现是一个迭代器
protected class ValueIterator implements ReduceContext.ValueIterator<VALUEIN> {

    private boolean inReset = false;

    private boolean clearMarkFlag = false;

    @Override

    public boolean hasNext() {

      try {

        if (inReset && backupStore.hasNext()) {

          return true;

        }

      } catch (Exception e) {

        e.printStackTrace();

        throw new RuntimeException("hasNext failed", e);

      }

      return firstValue || nextKeyIsSame;

    }

    @Override

    public VALUEIN next() {

      if (inReset) {

        try {

          if (backupStore.hasNext()) {

            backupStore.next();

            DataInputBuffer next = backupStore.nextValue();

            buffer.reset(next.getData(), next.getPosition(), next.getLength()

                - next.getPosition());

            value = valueDeserializer.deserialize(value);

            return value;

          } else {

            inReset = false;

            backupStore.exitResetMode();

            if (clearMarkFlag) {

              clearMarkFlag = false;

              isMarked = false;

            }

          }

        } catch (IOException e) {

          e.printStackTrace();

          throw new RuntimeException("next value iterator failed", e);

        }

      }

      // if this is the first record, we don't need to advance

      if (firstValue) {

        firstValue = false;

        return value;

      }

      // if this isn't the first record and the next key is different, they

      // can't advance it here.

      if (!nextKeyIsSame) {

        throw new NoSuchElementException("iterate past last value");

      }

      // otherwise, go to the next key/value pair

      try {

        nextKeyValue();//这个迭代器自身是没有数据的,在Next中调用的还是 nextKeyValue,在这个NextKeyValue中调用的是Input的输入数据

        return value;

      } catch (IOException ie) {

        throw new RuntimeException("next value iterator failed", ie);

      } catch (InterruptedException ie) {

        // this is bad, but we can't modify the exception list of java.util

        throw new RuntimeException("next value iterator interrupted", ie);

      }

    }
总结:以上说明一个流程。Reduce会拉回一个数据集,然后封装一个迭代器,真迭代器,ReduceContext会基于这个迭代器给我们封装一个方法,其中包括NextKeyValue这个方法,通过这个方法简介更新Key,Value的值,然后再Reduce方法的Run中有一个While循环,调用的是NextKey方法,底层调用的还是netxkeyValue方法,然后调用Reduce方法,传进去context.getCurrentKey(), context.getValues()两个方法,然后基于Value方法迭代,里面有HasNext和Next方法,Next方法实际上调用的还是真正的迭代器,最终数据时从镇迭代器中迭代出来的,在真正迭代器中有一个重要的标识NextKeyisSame,这个标识会被hasNext方法用到然后判断下一个key是否 相同,直到一组数据。
PS:补充一个知识点:

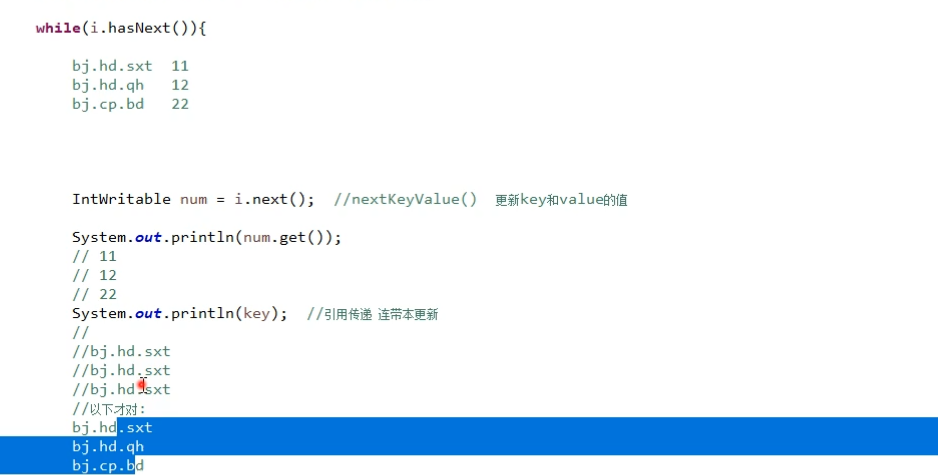
next调用的是NextKeyValue的方法,会把KeyValue真正改变,所以这块传的是引用传递。会改变同一块内存中的数据。
持续更新中。。。。,欢迎大家关注我的公众号LHWorld.
Hadoop源码篇--Reduce篇的更多相关文章
- [Hadoop源码解读](六)MapReduce篇之MapTask类
MapTask类继承于Task类,它最主要的方法就是run(),用来执行这个Map任务. run()首先设置一个TaskReporter并启动,然后调用JobConf的getUseNewAPI()判断 ...
- jQuery2.x源码解析(缓存篇)
jQuery2.x源码解析(构建篇) jQuery2.x源码解析(设计篇) jQuery2.x源码解析(回调篇) jQuery2.x源码解析(缓存篇) 缓存是jQuery中的又一核心设计,jQuery ...
- jQuery2.x源码解析(构建篇)
jQuery2.x源码解析(构建篇) jQuery2.x源码解析(设计篇) jQuery2.x源码解析(回调篇) jQuery2.x源码解析(缓存篇) 笔者阅读了园友艾伦 Aaron的系列博客< ...
- jQuery2.x源码解析(设计篇)
jQuery2.x源码解析(构建篇) jQuery2.x源码解析(设计篇) jQuery2.x源码解析(回调篇) jQuery2.x源码解析(缓存篇) 这一篇笔者主要以设计的角度探索jQuery的源代 ...
- jQuery2.x源码解析(回调篇)
jQuery2.x源码解析(构建篇) jQuery2.x源码解析(设计篇) jQuery2.x源码解析(回调篇) jQuery2.x源码解析(缓存篇) 通过艾伦的博客,我们能看出,jQuery的pro ...
- JDK源码学习--String篇(二) 关于String采用final修饰的思考
JDK源码学习String篇中,有一处错误,String类用final[不能被改变的]修饰,而我却写成静态的,感谢CTO-淼淼的指正. 风一样的码农提出的String为何采用final的设计,阅读JD ...
- Android事件传递机制详解及最新源码分析——ViewGroup篇
版权声明:本文出自汪磊的博客,转载请务必注明出处. 在上一篇<Android事件传递机制详解及最新源码分析--View篇>中,详细讲解了View事件的传递机制,没掌握或者掌握不扎实的小伙伴 ...
- Shiro源码解析-Session篇
上一篇Shiro源码解析-登录篇中提到了在登录验证成功后有对session的处理,但未详细分析,本文对此部分源码详细分析下. 1. 分析切入点:DefaultSecurityManger的login方 ...
- jedis的源码理解-基础篇
[jedis的源码理解-基础篇][http://my.oschina.net/u/944165/blog/127998] (关注实现关键功能的类) 基于jedis 2.2.0-SNAPSHOT ...
- linux0.11内核源码剖析:第一篇 内存管理、memory.c【转】
转自:http://www.cnblogs.com/v-July-v/archive/2011/01/06/1983695.html linux0.11内核源码剖析第一篇:memory.c July ...
随机推荐
- CF 552 Neko does Maths
给出两个数a,b 求k 使得 a+k b+k有最小公倍数 a,b同时加上一个非负整数k,使得,a+k,b+k的最小公倍数最小 因为最小公公倍数=x*y / gcd(x,y),所以肯定离不开最大 ...
- CF1013B And
There is an array with n elements a1, a2, ..., an and the number x. In one operation you can select ...
- Android Studio之回退Gradle版本方法
Android Studio之回退Gradle版本方法 (Minimum supported Gradle version is 4.10.1. Current version is 4.6.) ...
- 1. Linux系统介绍
1. 什么是操作系统? 定义:操作系统是计算机系统中必不可少的基础系统软件,它的作用是负责管理和控制计算机系统中的硬件和软件资源,合理地组织计算机系统的工作流程,以便有效地利用资源为使用者提供一个功能 ...
- iOS 获取app进程被杀死事件
程序被用户双击上滑杀死后,就对app做一些特殊的处理 下面的方法可以获取到用户双击上滑杀死的事件 - (void)applicationDidEnterBackground:(UIApplicatio ...
- RSP小组——团队冲刺博客五
RSP小组--团队冲刺博客五 冲刺日期:2018年12月17日 前言 周末的结束,我们并没有完全的休息,对于这个项目,以我们的实力还是需要花费更多的时间. 各成员今日(12.17)完成的任务 马瑞蕃由 ...
- ubuntu 14.04 安装 rabbitmq
1. sudo apt-get update 安装rabbitmq 2. sudo apt-get install rabbitmq-server 添加用户 3. sudo rabbitmqctl a ...
- vue-cli跳转到新页面的顶部
我这里有两种方法都是可以用的 1,利用vue-router的默认模式hash,可以记录上一页的位置,如果需要点话,如果没有记录,在进入新页面的时候是返回到新页面的最顶部的 scrollBehavior ...
- vue 源码学习二 实例初始化和挂载过程
vue 入口 从vue的构建过程可以知道,web环境下,入口文件在 src/platforms/web/entry-runtime-with-compiler.js(以Runtime + Compil ...
- java代码的编译、执行过程
Java代码编译是由Java源码编译器来完成,流程图如下所示: Java字节码的执行是由JVM执行引擎来完成,流程图如下所示: Java代码编译和执行的整个过程包含了以下三个重要的机制: Java源码 ...