
Centos7__Scrapy + Scrapy_redis 用Docker 实现分布式爬虫
原理:其实就是用到redis的优点及特性,好处自己查---
1,scrapy 分布式爬虫配置:
settings.py
BOT_NAME = 'first'

SPIDER_MODULES = ['first.spiders']

NEWSPIDER_MODULE = 'first.spiders'

# Crawl responsibly by identifying yourself (and your website) on the user-agent

#USER_AGENT = 'first (+http://www.yourdomain.com)'

# Obey robots.txt rules

ROBOTSTXT_OBEY = False

# Configure a delay for requests for the same website (default: 0)

# See https://docs.scrapy.org/en/latest/topics/settings.html#download-delay

# See also autothrottle settings and docs

#DOWNLOAD_DELAY = 3

# The download delay setting will honor only one of:

#CONCURRENT_REQUESTS_PER_DOMAIN = 16

#CONCURRENT_REQUESTS_PER_IP = 16

# Disable cookies (enabled by default)

#COOKIES_ENABLED = False

ITEM_PIPELINES = {

   # 'first.pipelines.FirstPipeline': 300,

   'scrapy_redis.pipelines.RedisPipeline':300,

   'first.pipelines.VideoPipeline': 100,

}

#分布式爬虫

#指定redis数据库的连接参数

REDIS_HOST = '172.17.0.2'

REDIS_PORT = 15672

REDIS_ENCODING = 'utf-8'

# REDIS_PARAMS ={

#     'password': '123456',  # 服务器的redis对应密码

# }

#使用了scrapy_redis的调度器,在redis里分配请求

SCHEDULER = "scrapy_redis.scheduler.Scheduler"

# # 确保所有爬虫共享相同的去重指纹

DUPEFILTER_CLASS = "scrapy_redis.dupefilter.RFPDupeFilter"

# Requests的调度策略,默认优先级队列

SCHEDULER_QUEUE_CLASS = 'scrapy_redis.queue.PriorityQueue'

#(可选). 在redis中保持scrapy-redis用到的各个队列,从而允许暂停和暂停后恢复,也就是不清理redis queues

SCHEDULER_PERSIST = True
spider.py
# -*- coding: utf-8 -*-

import scrapy

import redis

from ..items import Video

from scrapy.http import Request

from scrapy_redis.spiders import RedisSpider

class VideoRedis(RedisSpider):

    name = 'video_redis'

    allowed_domains = ['zuidazy2.net']

    # start_urls = ['http://zuidazy2.net/']

    redis_key = 'zuidazy2:start_urls'

    def parse(self, response):

        item = Video()

        res= response.xpath('//div[@class="xing_vb"]/ul/li/span[@class="xing_vb4"]/a/text()').extract_first()

        url = response.xpath('//div[@class="xing_vb"]/ul/li/span[@class="xing_vb4"]/a/@href').extract_first()

        v_type = response.xpath('//div[@class="xing_vb"]/ul/li/span[@class="xing_vb5"]/text()').extract_first()

        u_time  = response.xpath('//div[@class="xing_vb"]/ul/li/span[@class="xing_vb6"]/text()').extract_first()

        if res is not None:

            item['name'] = res

            item['v_type'] = v_type

            item['u_time'] = u_time

            url = 'http://www.zuidazy2.net' + url

            yield scrapy.Request(url, callback=self.info_data,meta={'item': item},dont_filter=True)

        next_link =  response.xpath('//div[@class="xing_vb"]/ul/li/div[@class="pages"]/a[last()-1]/@href').extract_first()

        if next_link:

            yield scrapy.Request('http://www.zuidazy2.net'+next_link,callback=self.parse,dont_filter=True)

    def info_data(self,data):

        item = data.meta['item']

        res = data.xpath('//div[@id="play_2"]/ul/li/text()').extract()

        if res:

            item['url'] = res

        else:

            item['url'] = ''

        yield item
items.py
import scrapy

class FirstItem(scrapy.Item):

    # define the fields for your item here like:

    content = scrapy.Field()

class Video(scrapy.Item):

    name = scrapy.Field()

    url = scrapy.Field()

    v_type = scrapy.Field()

    u_time = scrapy.Field()
pipelines.py
from pymysql import *

import aiomysql

class FirstPipeline(object):

    def process_item(self, item, spider):

        print('*'*30,item['content'])

        return item

class VideoPipeline(object):

    def __init__(self):

        self.conn = connect(host="39.99.37.85",port=3306,user="root",password="",database="queyou")

        self.cur = self.conn.cursor()

    def process_item(self, item, spider):

        # print(item)

        try:

            # insert_sql = f"insert into video values(0,'{item['name']}','{item['url']}','{item['v_type']}','{item['u_time']}')"

            # self.cur.execute(insert_sql)

            # # self.cur.execute("insert into video values(0,'"+item['name']+"','"+item['url']+"','"+item['v_type']+"','"+item['u_time']+"')")

            self.cur.execute("insert into video values(0,'"+item['name']+"','"+item['v_type']+"')")

            self.conn.commit()

        except Exception as e:

            print(e)

        finally:

            return item

    def close_spider(self, spider):

        self.conn.commit()  # 提交数据

        self.cur.close()

        self.conn.close()
2,Docker 安装和pull centos7 及安装依赖 (跳过)
3,cp 宿主机项目到 Centos7 容器中
docker cp /root/first 35fa:/root
4,安装redis 及 开启远程连接服务
具体在 /etc/redis.conf 中设置和开启redis服务
redis-server /etc/redis.conf
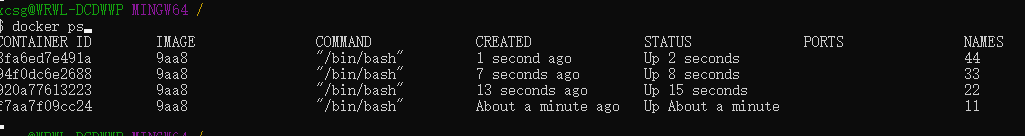
5,Docker虚拟主机多个及建立通信容器
运行容器

docker run -tid --name 11  CONTAINER_ID

建立通信容器

docker run  -tid --name 22 --link 11 CONTAINER_ID

进入容器  docker attach CONTAINER_ID

退出容器,不kill掉容器(通常exit会kill掉的) ctrl+q+p

查看网络情况 cat /etc/hosts
5,开启所有容器的spider 及定义start_url

完工!
附上打包好的镜像:链接: https://pan.baidu.com/s/1Sj244da0pOZvL3SZ_qagUg 提取码: qp23
Centos7__Scrapy + Scrapy_redis 用Docker 实现分布式爬虫的更多相关文章
- 分布式爬虫scrapy-redis
第一步 下载scrapy模块: pip install scrapy-redis 第二步 创建项目 在终端/cmd进入创建项目的目录: cd 路径: scrapy startproject douba ...
- scrapy分布式爬虫scrapy_redis二篇
=============================================================== Scrapy-Redis分布式爬虫框架 ================ ...
- scrapy分布式爬虫scrapy_redis一篇
分布式爬虫原理 首先我们来看一下scrapy的单机架构: 可以看到,scrapy单机模式,通过一个scrapy引擎通过一个调度器,将Requests队列中的request请求发给下载器,进行页 ...
- 使用Docker Swarm搭建分布式爬虫集群
https://mp.weixin.qq.com/s?__biz=MzIxMjE5MTE1Nw==&mid=2653195618&idx=2&sn=b7e992da6bd1b2 ...
- scrapy_redis分布式爬虫
文章来源:https://github.com/rmax/scrapy-redis Scrapy-Redis Documentation: https://scrapy-redis.readthedo ...
- python3下scrapy爬虫(第十三卷:scrapy+scrapy_redis+scrapyd打造分布式爬虫之配置)
之前我们的爬虫都是单机爬取,也是单机维护REQUEST队列, 看一下单机的流程图: 一台主机控制一个队列,现在我要把它放在多机执行,会产生一个事情就是做重复的爬取,毫无意义,所以分布式爬虫的第一个难点 ...
- 利用scrapy_redis实现分布式爬虫
介绍 Scrapy框架不支持分布式,所以需要将一些关键代码进行修改使之支持分布式.scrapy-redis相当于一个插件,用来替换scrapy中的一些模块,使得scrapy支持分布式.github地址 ...
- python3 分布式爬虫
背景 部门(东方IC.图虫)业务驱动,需要搜集大量图片资源,做数据分析,以及正版图片维权.前期主要用node做爬虫(业务比较简单,对node比较熟悉).随着业务需求的变化,大规模爬虫遇到各种问题.py ...
- scrapy-redis 分布式爬虫
为什么要学? Scrapy_redis在scrapy的基础上实现了更多,更强大的功能. 有哪些功能体现? request去重.爬虫持久化.实现分布式爬虫.断点续爬(带爬取的request存在redis ...
随机推荐
- docker和k8s的概念-IaaS、PaaS、SaaS 的区别
docker和k8s 参考: 什么是Docker? Kubernetes概述 openstack,docker,mesos,k8s什么关系? IaaS.PaaS.SaaS的概念 SaaS:软件服务,S ...
- T - Permutation 题解(思维+dp)
题目链接 题目大意 给你一个数字n和长为n-1个字符串 字符串包含'<','>' 若s[i]='<' 则代表a[i]<a[i+1] 若s[i]='>' 则代表a[i]&g ...
- 牛客练习赛71 数学考试 题解(dp)
题目链接 题目大意 要你求出有多少个长度为n的排列满足m个限制条件 第i个限制条件 p[i]表示前 p[i]个数不能是1-p[i]的排列 题目思路 这个感觉是dp但是不知道怎么dp 首先就是要明白如果 ...
- 牛客练习赛69 火柴排队 题解(dp)
题目链接 题目大意 给你一个长为n(n<=5e3)的数组a.随机使得k个元素增加d.要你求多大的概率使得,这些数组元素的相对大小不发生改变 输出 n 行每行一个整数,第 i 行的整数表示 k=i ...
- 配置Nginx 扩展实现图片剪裁
在此之前需要安装ngx_http_image_filter_module,如果是采用的Docker的话可以看看我历史文章. 然后修改配置文件,增加几个location模块,配置如下,仅供参考 serv ...
- CARDS主题 & 导航栏样式修改
每个人对于主题样式的感觉是不一样的,譬如字体大小,间距,高宽,距离,颜色等,我们可以一定程度内很直观地去修改主题的某些样式. 首先,在浏览器中利用开发者工具进行调试,找到我们所要改动的那部分结构,写入 ...
- sharding调试setAutoCommit
emmm应该是有manager的 因为指定了@Primary 不然容器启动的时候创建sessionFactory就因为多个DataSource异常了,后面会滚的时候manager为null也会有运行时 ...
- dubbo起停之服务消费
ReferenceAnnotationBeanPostProcessor继承了AnnotationInjectedBeanPostProcessors其实现了InstantiationAwareBea ...
- MindSpore手写数字识别初体验,深度学习也没那么神秘嘛
摘要:想了解深度学习却又无从下手,不如从手写数字识别模型训练开始吧! 深度学习作为机器学习分支之一,应用日益广泛.语音识别.自动机器翻译.即时视觉翻译.刷脸支付.人脸考勤--不知不觉,深度学习已经渗入 ...
- LeetCode 019 Remove Nth Node From End of List
题目描述:Remove Nth Node From End of List Given a linked list, remove the nth node from the end of list ...