
Policy Improvement and Policy Iteration
From the last post, we know how to evaluate a policy. But that's not enough, because the purpose of policy evaluation is to improve policies so that finally get the optimal policy. So in this post, we will discuss about how to improve a given policy, and how to from a given policy get to the optimal policy.
Firstly, when you have an evaluated policy, the Action-Value function is known for every state. That is, at a certain state s, we known which action can give the system the largest reward.
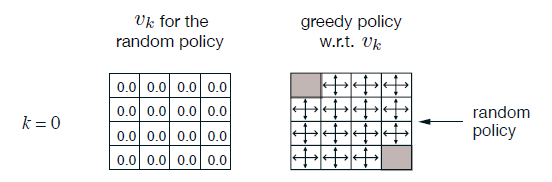
In the puzzle wandering example, we evaluate the random policy. However,the State-Value functions can be used for policy improvement. After 1 step calculating,we can conclude at the circled location, moving left is better than randomly picking a direction because left side has more reward.
After three steps, we've got a much better intuition about the map. We can change the random policy to a new better one.

The way to improve the current policy is to greedyly pick actions for every state. It is worth noting that greedily picking actions does not means it only consider one step (too greedy to consider multiple steps). Instead, when k=3, the algorithm can foresee three steps, and the greedy picking algorithm will select the best action for k steps.
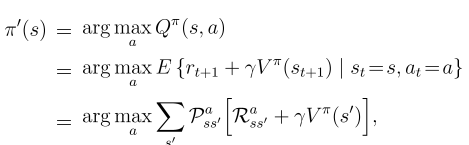
The Policy Iteration Algorithm is keep doing evaluation and improvement tasks untill the policy becomes stable,
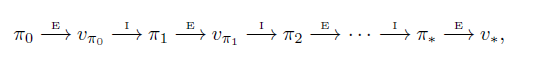

This process means Action-Value function of the improved policy picking the best return from a single action:
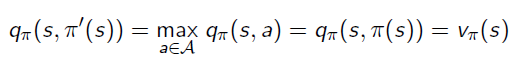
The algorithm is:

Policy Improvement and Policy Iteration的更多相关文章
- Provider Policy与Consumer Policy在bnd中的区别
首先需要了解的是bnd的相关知识: 1. API(也就是接口), 2. API Provider(接口的实现) 3. API Consumer( 接口的使用者) OSGi中的一个版本有4个部分: ...
- Reinforcement Learning Index Page
Reinforcement Learning Posts Step-by-step from Markov Property to Markov Decision Process Markov Dec ...
- Policy Gradient Algorithms
Policy Gradient Algorithms 2019-10-02 17:37:47 This blog is from: https://lilianweng.github.io/lil-l ...
- Deep Learning专栏--强化学习之从 Policy Gradient 到 A3C(3)
在之前的强化学习文章里,我们讲到了经典的MDP模型来描述强化学习,其解法包括value iteration和policy iteration,这类经典解法基于已知的转移概率矩阵P,而在实际应用中,我们 ...
- 使用 SecurityManager 和 Policy File 管理 Java 程序的权限
参考资料 该文中的内容来源于 Oracle 的官方文档.Oracle 在 Java 方面的文档是非常完善的.对 Java 8 感兴趣的朋友,可以从这个总入口 Java SE 8 Documentati ...
- Utility2:Appropriate Evaluation Policy
UCP收集所有Managed Instance的数据的机制,是通过启用各个Managed Instances上的Collection Set:Utility information(位于Managem ...
- trait与policy模板应用简单示例
trait与policy模板应用简单示例 accumtraits.hpp // 累加算法模板的trait // 累加算法模板的trait #ifndef ACCUMTRAITS_HPP #define ...
- trait与policy模板技术
trait与policy模板技术 我们知道,类有属性(即数据)和操作两个方面.同样模板也有自己的属性(特别是模板参数类型的一些具体特征,即trait)和算法策略(policy,即模板内部的操作逻辑). ...
- Network Policy - 每天5分钟玩转 Docker 容器技术(171)
Network Policy 是 Kubernetes 的一种资源.Network Policy 通过 Label 选择 Pod,并指定其他 Pod 或外界如何与这些 Pod 通信. 默认情况下,所有 ...
随机推荐
- Educational Codeforces Round 68 (Rated for Div. 2) D. 1-2-K Game (博弈, sg函数,规律)
D. 1-2-K Game time limit per test2 seconds memory limit per test256 megabytes inputstandard input ou ...
- 10年前文章_mysql 中文设置
下面的设置针对GB2312, 1 创建数据库时使用 GBK 字符集 CREATE DATABASE `orange` DEFAULT CHARACTER SET gbk COLLATE gbk_ch ...
- man(2) V
vfork(2) #include <sys/types.h> #include <unistd.h> pid_t vfork(void); 功能:创建子进程并阻塞父进 --- ...
- C#基础知识之依赖注入
目录 1 IGame游戏公司的故事 1.1 讨论会 1.2 实习生小李的实现方法 1.3 架构师的建议 1.4 小李的小结 2 探究依赖注入 2.1 故事的启迪 2.2 正式定义依赖注入 3 依赖注入 ...
- lambda匿名函数sorted排序函数filter过滤函数map映射函数
lambda函数:表示匿名函数,不需要def来声明,一句话就能搞定. 语法:函数名=lamda 参数:返回值 求10的10次方 f=lambda n:n**n print(f(10)) 注意: 函数名 ...
- H5 FileReader对象
前言:FileReader是一种异步文件读取机制,结合input:file可以很方便的读取本地文件. input:file 在介绍FileReader之前,先简单介绍input的file类型. < ...
- App 区别
本文的结构主要分为以下部分: 1.app的分类 2.每类app的定义,明确各类app具体是什么 3.各类app的优缺点 4.具体开发过程中,到底该采用哪种类型的app 1.app的分类 大致可以分为这 ...
- win10如何设置软件开机启动
想要实现应用程序在所有的用户登录系统后都能自动启动,就把该应用程序的快捷方式放到“系统启动文件夹”里C:\ProgramData\Microsoft\Windows\Start Menu\Progra ...
- 浙大PAT CCCC L3-013 非常弹的球 ( 高中物理题 )
题目链接 题意 : 刚上高一的森森为了学好物理,买了一个“非常弹”的球.虽然说是非常弹的球,其实也就是一般的弹力球而已.森森玩了一会儿弹力球后突然想到,假如他在地上用力弹球,球最远能弹到多远去呢?他不 ...
- SpringBoot整合knife4j
官网说明及用法: 简介 swagger-bootstrap-ui是springfox-swagger的增强UI实现,为Java开发者在使用Swagger的时候,能拥有一份简洁.强大的接口文档体验 核心 ...