
[CVPR 2017] Semantic Autoencoder for Zero-Shot Learning论文笔记
Semantic Autoencoder for Zero-Shot Learning,Elyor Kodirov Tao Xiang Shaogang Gong,Queen Mary University of London, UK,{e.kodirov, t.xiang, s.gong}@qmul.ac.uk
亮点
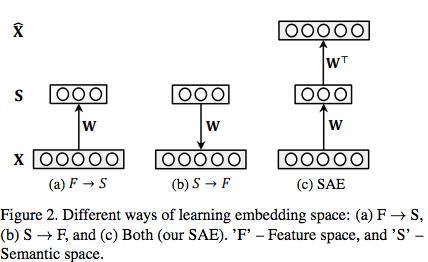
- 通过对耦学习提升零次学习系统的性能(类似CycleGan)
- 结构非常简洁,且可直接求解,速度非常快
- 有效应用到其他相关任务(监督聚类)上,证明了范化性能
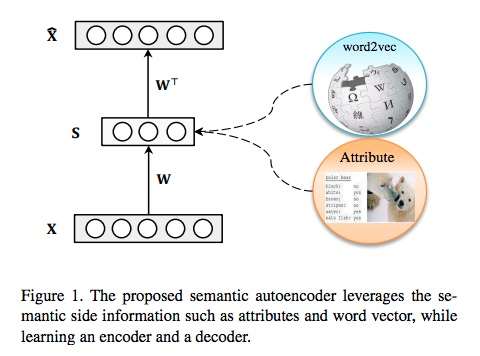
方法
Linear autoencoder
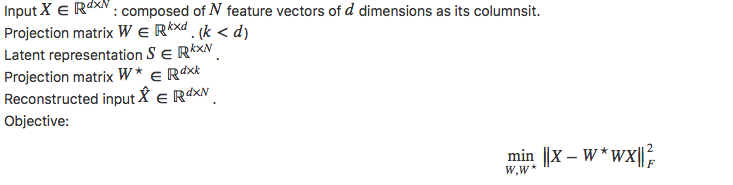
Model Formulation

which is a well-known Sylvester equation which can be solved efficiently by the Bartels-Stewart algorithm (matlab sylvester).
零次学习:基于以上算法有两种测试的方法:
- 将一个未知的类别特征样本xi通过W映射到语义空间(属性)si,通过比较语义空间的距离找到离它最近的类别(无训练样本),即为它的标签
- 将所有无训练数据类别的语义特征S通过WT映射到特征空间X,通过比较一个未知类别的样本xi和映射到特征空间的类别中心X的距离,找到离它最近的类别,即为它的标签
- 以上两种算法得到结果的准确度基本相同。
监督聚类:在这个问题中,语义空间即为类别标签空间(one-hot class label)。所有测试数据被影射到训练类别标签空间,然后使用k-means聚合
与已有模型的关系:零度学习已有模型一般学习一个满足以下条件的影射:
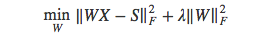
或者,在[54]中将属性影射到特征空间,学习目标变为,
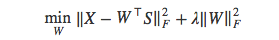
文中的算法结合了这两者,而且由于W*=WT,在对耦学习中W不可能太大(否则,x乘以两个范数很大的的矩阵无法恢复原来的初始值),正则化项可以被忽略。
实验
零次学习
数据集:Semantic word vector representation is used for large-scale datasets (ImNet-1 and ImNet-2). We train a skip-gram text model on a corpus of 4.6M Wikipedia documents to obtain the word2vec2 [38, 37] word vectors.
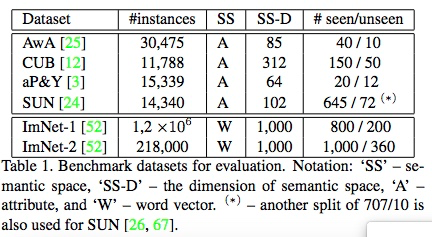
特征:除 ImNet-1用AlexNet提取外,其他均使用了GoogleNet
结果:
- Our SAE model achieves the best results on all 6 datasets.
- On the smallscale datasets, the gap between our model’s results to the strongest competitor ranges from 3.5% to 6.5%.
- On the large-scale datasets, the gaps are even bigger: On the largest ImNet-2, our model improves over the state-of-the-art SS-Voc [22] by 8.8%.
- Both the encoder and decoder projection functions in our SAE model (SAE (W) and SAE (WT) respectively) can be used for effective ZSL.
- The encoder projection function seems to be slightly better overall.
- Measures how well a zero-shot learning method can trade-off between recognising data from seen classes and that of unseen classes
- Holding out 20% of the data samples from the seen classes and mixing them with the samples from the unseen classes.
- On AwA, our model is slightly worse than the SynCstruct [13].
- However, on the more challenging CUB dataset, our method significantly outperforms the competitors.
聚类
数据集: A synthetic dataset and Oxford Flowers-17 (848 images)
结果:
- On computational cost, our model (93s) is more expensive than MLCA (39%) but much better than all others (hours~days).
- Achieves the best clustering accuracy
p.p1 { margin: 0.0px 0.0px 0.0px 0.0px; font: 14.0px "Helvetica Neue"; color: #042eee }
p.p2 { margin: 0.0px 0.0px 0.0px 0.0px; font: 16.0px "Helvetica Neue"; color: #323333 }
p.p3 { margin: 0.0px 0.0px 0.0px 0.0px; font: 14.0px "Helvetica Neue"; color: #323333 }
p.p4 { margin: 0.0px 0.0px 0.0px 0.0px; font: 14.0px "Helvetica Neue"; color: #323333; min-height: 16.0px }
p.p5 { margin: 0.0px 0.0px 0.0px 0.0px; font: 17.0px STIXGeneral; color: #323333 }
p.p6 { margin: 0.0px 0.0px 0.0px 0.0px; font: 12.0px STIXGeneral; color: #323333 }
p.p7 { margin: 0.0px 0.0px 0.0px 0.0px; font: 9.0px STIXGeneral; color: #323333 }
p.p8 { margin: 0.0px 0.0px 0.0px 0.0px; text-align: center; font: 17.0px STIXGeneral; color: #323333 }
p.p9 { margin: 0.0px 0.0px 0.0px 0.0px; text-align: center; font: 17.0px "Helvetica Neue"; color: #323333; min-height: 20.0px }
p.p10 { margin: 0.0px 0.0px 0.0px 0.0px; text-align: center; font: 19.0px STIXSizeOneSym; color: #323333 }
p.p11 { margin: 0.0px 0.0px 0.0px 0.0px; font: 14.0px "Helvetica Neue"; color: #323333; min-height: 17.0px }
li.li3 { margin: 0.0px 0.0px 0.0px 0.0px; font: 14.0px "Helvetica Neue"; color: #323333 }
span.s1 { text-decoration: underline }
span.s2 { }
span.s3 { font: 19.0px STIXSizeOneSym }
ul.ul1 { list-style-type: disc }
ul.ul2 { list-style-type: circle }
[CVPR 2017] Semantic Autoencoder for Zero-Shot Learning论文笔记的更多相关文章
- Spectral Norm Regularization for Improving the Generalizability of Deep Learning论文笔记
Spectral Norm Regularization for Improving the Generalizability of Deep Learning论文笔记 2018年12月03日 00: ...
- Deep Learning论文笔记之(四)CNN卷积神经网络推导和实现(转)
Deep Learning论文笔记之(四)CNN卷积神经网络推导和实现 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些论文, ...
- Deep Learning论文笔记之(八)Deep Learning最新综述
Deep Learning论文笔记之(八)Deep Learning最新综述 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些论文,但老感觉看完 ...
- Deep Learning论文笔记之(六)Multi-Stage多级架构分析
Deep Learning论文笔记之(六)Multi-Stage多级架构分析 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些 ...
- Deep Learning论文笔记之(一)K-means特征学习
Deep Learning论文笔记之(一)K-means特征学习 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些论文,但老感 ...
- Deep Learning论文笔记之(三)单层非监督学习网络分析
Deep Learning论文笔记之(三)单层非监督学习网络分析 zouxy09@qq.com http://blog.csdn.net/zouxy09 自己平时看了一些论文,但老感 ...
- PredNet --- Deep Predictive coding networks for video prediction and unsupervised learning --- 论文笔记
PredNet --- Deep Predictive coding networks for video prediction and unsupervised learning ICLR 20 ...
- Correlation Filter in Visual Tracking系列二:Fast Visual Tracking via Dense Spatio-Temporal Context Learning 论文笔记
原文再续,书接一上回.话说上一次我们讲到了Correlation Filter类 tracker的老祖宗MOSSE,那么接下来就让我们看看如何对其进一步地优化改良.这次要谈的论文是我们国内Zhang ...
- Deep Learning论文笔记之(四)CNN卷积神经网络推导和实现
https://blog.csdn.net/zouxy09/article/details/9993371 自己平时看了一些论文,但老感觉看完过后就会慢慢的淡忘,某一天重新拾起来的时候又好像没有看过一 ...
随机推荐
- 从"按层次输出二叉树"到"求解二叉树深度"的总结
本文是在学习中的总结,欢迎转载但请注明出处:http://write.blog.csdn.net/postedit/41964669 最近在刷LeetCode上的算法题,发现好多题目的解题思路大体是一 ...
- 1.Linux下libevent和memcached安装
1 下载libevent-2.0.22-stable.tar.gz,下载地址是:http://libevent.org/ 2 下载memcached,下载地址是:http://memcached ...
- hadoop学习视频
杨尚川的视频 http://www.tudou.com/plcover/EvJCo2zl9hQ/ 酷6视频 http://v.ku6.com/show/8PkgqGcarHKndyP3rl_pUw.. ...
- Using Integrated SOA Gateway in Oracle EBS
FROM:http://blog.csdn.net/pan_tian/article/details/10159935 Oracle EBS如何与第三方系统相集成?比如这样的需求,X系统知道物料编码, ...
- [Err] ORA-00923: FROM keyword not found where expected 与rownum
关于oracle的nownum 如果我想查询表的全部信息,并且前面加上行号,sql如下 select ROWNUM,* from tableA 会报下面的错误 [Err] ORA-00923: FR ...
- 【Java编程】Java学习笔记<一>
1. 高级语言的编译和执行方法可以归为两大基本技术:编译执行和解释执行.C/C++/Delphi是编译执行,basic/java/matlab是解释执行. 2. 尽管Java是解释执行的,也需 ...
- android 高斯模糊实现
高斯模糊 高斯模糊就是将指定像素变换为其与周边像素加权平均后的值,权重就是高斯分布函数计算出来的值. 一种实现 点击打开链接<-这里是一片关于高斯模糊算法的介绍,我们需要首先根据高斯分布函数计算 ...
- 未能加载文件或程序集“file:///C:\Program Files (x86)\SAP BusinessObjects\Crystal Reports for .NET Framework 4.0
未能加载文件或程序集"file:///C:\Program Files (x86)\SAP BusinessObjects\Crystal Reports for .NET Framewor ...
- 【Android 应用开发】BluetoothDevice详解
一. BluetoothDevice简介 1. 继承关系 public static Class BluetoothDevice extends Object implement Parcelable ...
- 提高HBase写性能
以下为使用hbase一段时间的三个思考,由于在内存充足的情况下hbase能提供比较满意的读性能,因此写性能是思考的重点.希望读者提出不同意见讨论 1 autoflush=false的影响 无论是官方还 ...