
《The Python Standard Library》——http模块阅读笔记1
官方文档:https://docs.python.org/3.5/library/http.html
偷个懒,截图如下:
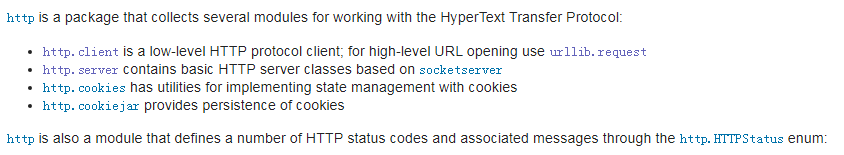
即,http客户端编程一般用urllib.request库(主要用于“在这复杂的世界里打开各种url”,包括:authentication、redirections、cookies and more.)。
1. urllib.request—— Extensible library for opening URLs
使用手册,结合代码写的很详细:HOW TO Fetch Internet Resources Using The urllib Package
该模块提供的函数:
urllib.request.urlopen(url, data=None, [timeout, ]*, cafile=None, capath=None, cadefault=False, context=None)
urllib.request.install_opener(opener)
urllib.request.build_opener([handler, ...])
urllib.request.pathname2url(path)
urllib.request.url2pathname(path)
urllib.request.getproxies()
该模块提供的类:
class urllib.request.Request(url, data=None, headers={}, origin_req_host=None, unverifiable=False, method=None)
class urllib.request.OpenerDirector
class urllib.request.BaseHandler
class urllib.request.HTTPDefaultErrorHandler
class urllib.request.HTTPRedirectHandler
class urllib.request.HTTPCookieProcessor(cookiejar=None)
class urllib.request.ProxyHandler(proxies=None)
class urllib.request.HTTPPasswordMgr
还有很多,不一一列出了。。。
1.2 Request对象
下面的方法是Request提供的公共接口,所以它们可以被子类重写。同时,也提供了一些客户端可以查阅解析的请求的公共属性。
Request.full_url Request.type Request.host Request.origin_req_host #不包含端口号
Request.selector Request.data Request.unverifiable Request.method
Request.get_method() Request.add_header(key, val) Request.add_unredirected_header(key, header) Request.has_header(header) Request.remove_header(header)
Request.get_full_url() Request.set_proxy(host, type) Request.get_header(header_name, default=None) Request.header_items()
1.3 OpenerDirector Objects
有以下方法:
OpenerDirector.add_handler(handler)
OpenerDirector.open(url, data=None[, timeout])
OpenerDirector.error(proto, *args)
1.4 BaseHandler Objects
1.5 HTTPRedirectHandler Objects
1.6 HTTPCookieProcessor Objects
它只有一个属性:HTTPCookieProcessor.cookiejar ,所有的cookies都保存在http.cookiejar.CookeiJar中。
1.x 还有太多类,需要用时直接查看官方文档吧。。
EXamples
打开url读取数据:
>>> import urllib.request

>>> with urllib.request.urlopen('http://www.python.org/') as f:

...     print(f.read(300))

...

b'<!DOCTYPE html PUBLIC "-//W3C//DTD XHTML 1.0 Transitional//EN"

"http://www.w3.org/TR/xhtml1/DTD/xhtml1-transitional.dtd">\n\n\n<html

xmlns="http://www.w3.org/1999/xhtml" xml:lang="en" lang="en">\n\n<head>\n

<meta http-equiv="content-type" content="text/html; charset=utf-8" />\n

<title>Python Programming '
注意:urlopen返回一个bytes object(字节对象)。
>>> with urllib.request.urlopen('http://www.python.org/') as f:

...     print(f.read(100).decode('utf-8'))

...

<!DOCTYPE html PUBLIC "-//W3C//DTD XHTML 1.0 Transitional//EN"

"http://www.w3.org/TR/xhtml1/DTD/xhtm
向CGI的stdin发送数据流:
>>> import urllib.request

>>> req = urllib.request.Request(url='https://localhost/cgi-bin/test.cgi',

...                       data=b'This data is passed to stdin of the CGI')

>>> with urllib.request.urlopen(req) as f:

...     print(f.read().decode('utf-8'))

...

Got Data: "This data is passed to stdin of the CGI"
CGI的另一端通过stdin接收数据:
#!/usr/bin/env python

import sys

data = sys.stdin.read()

print('Content-type: text/plain\n\nGot Data: "%s"' % data)
Use of Basic HTTP Authentication:
import urllib.request

# Create an OpenerDirector with support for Basic HTTP Authentication...

auth_handler = urllib.request.HTTPBasicAuthHandler()

auth_handler.add_password(realm='PDQ Application',

                          uri='https://mahler:8092/site-updates.py',

                          user='klem',

                          passwd='kadidd!ehopper')

opener = urllib.request.build_opener(auth_handler)

# ...and install it globally so it can be used with urlopen.

urllib.request.install_opener(opener)

urllib.request.urlopen('http://www.example.com/login.html')
添加HTTP头部:
import urllib.request

req = urllib.request.Request('http://www.example.com/')

req.add_header('Referer', 'http://www.python.org/')

# Customize the default User-Agent header value:

req.add_header('User-Agent', 'urllib-example/0.1 (Contact: . . .)')

r = urllib.request.urlopen(req)
OpenerDirector automatically adds a User-Agent header to every Request. To change this:
import urllib.request

opener = urllib.request.build_opener()

opener.addheaders = [('User-agent', 'Mozilla/5.0')]

opener.open('http://www.example.com/')
Also, remember that a few standard headers (Content-Length, Content-Type and Host) are added when the Request is passed to urlopen() (or OpenerDirector.open()).
GET:
>>> import urllib.request

>>> import urllib.parse

>>> params = urllib.parse.urlencode({'spam': 1, 'eggs': 2, 'bacon': 0})

>>> url = "http://www.musi-cal.com/cgi-bin/query?%s" % params

>>> with urllib.request.urlopen(url) as f:

...     print(f.read().decode('utf-8'))
POST:
>>> import urllib.request

>>> import urllib.parse

>>> data = urllib.parse.urlencode({'spam': 1, 'eggs': 2, 'bacon': 0})

>>> data = data.encode('ascii')

>>> with urllib.request.urlopen("http://requestb.in/xrbl82xr", data) as f:

...     print(f.read().decode('utf-8'))
The following example uses an explicitly specified HTTP proxy, overriding environment settings:
>>> import urllib.request

>>> proxies = {'http': 'http://proxy.example.com:8080/'}

>>> opener = urllib.request.FancyURLopener(proxies)

>>> with opener.open("http://www.python.org") as f:

...     f.read().decode('utf-8'
The following example uses no proxies at all, overriding environment settings:
>>> import urllib.request

>>> opener = urllib.request.FancyURLopener({})

>>> with opener.open("http://www.python.org/") as f:

...     f.read().decode('utf-8')
《The Python Standard Library》——http模块阅读笔记1的更多相关文章
- Python Standard Library
Python Standard Library "We'd like to pretend that 'Fredrik' is a role, but even hundreds of vo ...
- Python 日期时间处理模块学习笔记
来自:标点符的<Python 日期时间处理模块学习笔记> Python的时间处理模块在日常的使用中用的不是非常的多,但是使用的时候基本上都是要查资料,还是有些麻烦的,梳理下,便于以后方便的 ...
- Python语言中对于json数据的编解码——Usage of json a Python standard library
一.概述 1.1 关于JSON数据格式 JSON (JavaScript Object Notation), specified by RFC 7159 (which obsoletes RFC 46 ...
- The Python Standard Library
The Python Standard Library¶ While The Python Language Reference describes the exact syntax and sema ...
- 《The Python Standard Library》——http模块阅读笔记2
http.server是用来构建HTTP服务器(web服务器)的模块,定义了许多相关的类. 创建及运行服务器的代码一般为: def run(server_class=HTTPServer, handl ...
- 《The Python Standard Library》——http模块阅读笔记3
http.cookies — HTTP state management http.cookies模块定义了一系列类来抽象cookies这个概念,一个HTTP状态管理机制.该模块支持string-on ...
- python os os.path模块学习笔记
#!/usr/bin/env python #coding=utf-8 import os #创建目录 os.mkdir(r'C:\Users\Silence\Desktop\python') #删除 ...
- Python Standard Library 学习(一) -- Built-in Functions 内建函数
内建函数列表 Built-in Functions abs() divmod() input() open() staticmethod() all() enumerate() int() ord() ...
- Python内置模块和第三方模块
1.Python内置模块和第三方模块 内置模块: Python中,安装好了Python后,本身就带有的库,就叫做Python的内置的库. 内置模块,也被称为Python的标准库. Python 2.x ...
随机推荐
- Requests接口测试(一)
接口测试概念 接口测试是测试系统组件间接口的一种测试.接口测试主要用于检测外部系统与系统之间以及内部各个子系统之间的交互点.测试的重点是要检查数据的交换,传递和控制管理过程,以及系统间的相互逻辑依赖关 ...
- oracle数据库之分组查询
本章内容和大家分享的是数据当中的分组查询.分组查询复杂一点的是建立在多张表的查询的基础之上,(我们在上一节课的学习中已经给大家分享了多表查询的使用技巧,大家可以自行访问:多表查询1 多表查询2)而在 ...
- Razor内幕之解析
ASPX语法比较简单,所以ASPX解析器几乎完全是通过正则表达式来实现的.Razor解析器与ASPX解析器之间有很大不同,它实际上分为三个独立的组件: 1)理解基础HTML语法的标记解析器: 2)理解 ...
- LightOJ 1038 Race to 1 Again (概率DP,记忆化搜索)
题意:给定一个数 n,然后每次除以他的一个因数,如果除到1则结束,问期望是多少. 析:概率DP,可以用记忆公搜索来做,dp[i] = 1/m*sum(dp[j] + 1) + 1/m * (dp[i] ...
- Firefox浏览器控件安装方法
说明:只需要安装up6.exe即可,up6.exe为插件集成安装包. 1.以管理员身份运行up6.exe.up6.exe中已经集成Chrome插件.
- (转)常见存储过程分页PK赛——简单测试分析常见存储过程分页速度
原文地址:http://www.cnblogs.com/yangyy753/archive/2013/01/23/2872753.html 数据的分页是我们再熟悉不过的功能了,各种各样的分页方式层出不 ...
- xubuntu14.04LTS安装steam后运行的错误解决办法
我在ubuntu14.10中没碰到过这个问题,但在xubuntu14.04LTS中碰到 Steam needs to install these additional packages: libgl1 ...
- GitHub小技巧-定义项目语言
GitHub是根据项目里文件数目最多的文件类型,识别项目类型.后端项目难免会包含前端的资源,有时候就会被标记成前端语言,因为项目里 css 等文件比较多, 被误识别成css项目. GitHub不提供指 ...
- vba实现excel多表合并
Excel多表合并之vba实现 需求 保留列名,复制每一个excel里的数据,合并到一个excel 操作步骤 将要合并的文件放在同一文件夹下,复制过来就好(ps:最好不要直接操作原数据文件,避免操作失 ...
- window phone 8资源管理器打开文件
一.打开安装包里面文件: StorageFolder sf = Package.Current.InstalledLocation;//ApplicationData.Current.LocalFol ...