
【CV】CVPR2015_A Discriminative CNN Video Representation for Event Detection
A Discriminative CNN Video Representation for Event Detection
Note here: it's a learning note on the topic of video representation, based on the paper below.
Link: http://arxiv.org/pdf/1411.4006v1.pdf
Motivation:
The use of improved Dense Trajectories (IDT) has led good performance on the task of event detection, while the performance of CNN based video representation is worse than that. The author argues the following three main reasons:
- Lack of labeled video data to train good models.
- Video level event labels are too coarse to finetune a pre-trained model for adapting the event detection task.
- The use of average pooling to generate a discriminative video level representation from CNN frame level descriptors works worse than hand-crafted features like IDT.
Proposed Model:
This paper proposes a model mainly targetting at the third problem, namely how to build a cost-efficient and discrimintive video representation based on CNN.
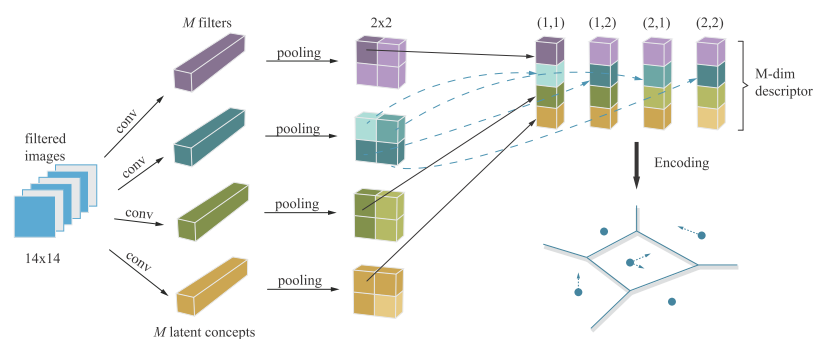
1) Firstly, we should extract frame-level descriptor:
We adopt M filters in the last convolutional layers as M latent concept classifiers. Each convolutional filter is corresponding to one latent concept, and each of it will apply on different location of the frame. So we’ll get responses of discrimintive latent concepts on different locations of the frame.
After that, we apply max-pooling operation on all concepts descriptors and concatenate different responses at the same location to form vectors each of which containing various concepts descriptions at this location.
By now, we’ve extract frame-level features.
(Actually, they didn’t do anything special at this step, they just give a new illustration of responses in CNN and rearrange those responses for further process.)
2) Secondly, we need to encode a discrimintive video-level descriptor from all these frame-level descriptors:
They introduce and compare three different encoding methods in the paper.
However, as I’m not proficient in the mathematical meanings of them, I can just give a briefly look at them instead of going further.
- Fisher Vector Encoding (refer to: http://blog.csdn.net/breeze5428/article/details/32706507 & http://www.cnblogs.com/CBDoctor/archive/2011/11/06/2236286.html)
- VLAD Encoding (simplified version of Fisher Vector Encoding)
- Average Pooling
Through experiment, they find out VLAD is better than other encoding methods. (You can refer to the paper for details about that experiment.)
"This is the first work on the video pooling of CNN descriptors and we broaden the encoding methods from local descriptors to CNN descriptors in video analysis."
(That's the takeaway in their work. They're the first to apply these encoding methods on the CNN descriptors. Previously, most of the works utilize Fisher Vector Encoding to encode a general feature of an image from local descriptors like HOG, SIFT, HOF and so on.)
3) Lastly, we get a video-level descriptor and feed it into a SVM to do detection task.
Two Tricks:
1) Spatial Pyramid Pooling: they apply four different CNN max-pooling operations to give more spatial locations for a single frame, which makes the descriptor more discrimintive. And that’s also more cost-friendly than applying spatial pyramid on raw frame.
2) Representation Compression: they do Product Quntization to compress the final representation while still maintain or even slightly improve the original performance.
【CV】CVPR2015_A Discriminative CNN Video Representation for Event Detection的更多相关文章
- 论文阅读(Weilin Huang——【TIP2016】Text-Attentional Convolutional Neural Network for Scene Text Detection)
Weilin Huang--[TIP2015]Text-Attentional Convolutional Neural Network for Scene Text Detection) 目录 作者 ...
- 【CV】ICCV2015_Unsupervised Learning of Visual Representations using Videos
Unsupervised Learning of Visual Representations using Videos Note here: it's a learning note on Prof ...
- 【PSMA】Progressive Sample Mining and Representation Learning for One-Shot Re-ID
目录 主要挑战 主要的贡献和创新点 提出的方法 总体框架与算法 Vanilla pseudo label sampling (PLS) PLS with adversarial learning Tr ...
- 【CV】ICCV2015_Learning Temporal Embeddings for Complex Video Analysis
Learning Temporal Embeddings for Complex Video Analysis Note here: it's a review note on novel work ...
- 【CV】ICCV2015_Unsupervised Visual Representation Learning by Context Prediction
Unsupervised Visual Representation Learning by Context Prediction Note here: it's a learning note on ...
- 【CV】ICCV2015_Unsupervised Learning of Spatiotemporally Coherent Metrics
Unsupervised Learning of Spatiotemporally Coherent Metrics Note here: it's a learning note on the to ...
- 【CV】ICCV2015_Describing Videos by Exploiting Temporal Structure
Describing Videos by Exploiting Temporal Structure Note here: it's a learning note on the topic of v ...
- 【ML】ICML2015_Unsupervised Learning of Video Representations using LSTMs
Unsupervised Learning of Video Representations using LSTMs Note here: it's a learning notes on new L ...
- 【实战问题】【3】iPhone无法播放video标签中的视频
问题:视频都是MP4格式,视频可以在手机上正常播放.video标签中的视频在安卓点击可以播放,但在iPhone无法播放 解决方案: 1,视频编码格式问题,具体iPhone手机支持的是哪些格式可见官方的 ...
随机推荐
- Linux驱动的两种载入方式过程分析
一.概念简述 在Linux下能够通过两种方式载入驱动程序:静态载入和动态载入. 静态载入就是把驱动程序直接编译进内核.系统启动后能够直接调用.静态载入的缺点是调试起来比較麻烦,每次改动一个地方都要又一 ...
- Eclipse字体最好
改变字体 windows->Preferences->General->Appearance->Colors and Fonts 右边选择Java ->Java Edit ...
- MongoDB逻辑操作符$or, $and,$not,$nor
$or是一个逻辑or操作符操作在一个数据或者多个表达式并且需要选择至少一个满足条件的表达式,$or有至少以下表达式: { $or: [ { <expression1> }, { <e ...
- Blinker 后台数据分析
如何解析出后台服务器认证信息,供自己的设备连接. 测试程序 天气 增加了 Debug输出信息功能 1手机APP添加控件信息 2硬件烧录程序 #define BLINKER_PRINT Serial ...
- WIN10 + VS 2013 配置Opencv2.4.1.3 32位
VS2013 配置Opencv2.4.1.3 32位 系统变量 Path: F:\2biancheng_tool\Opencv2413\opencv\build\x86\vc12\bin 用户变 ...
- Drool实战系列(一)之入门程序
Drools官网地址为:https://www.drools.org/ maven环境 入门程序例子如下: 项目结构截图: 一.导入pom文件 <project xmlns="http ...
- ros新建的包找不到
cannot find the package 这个问题的解决办法一:每次打开命令窗都使用一次 source ~/ros_ws/devel/setup.bash 解决方法二:在住文件夹的图形界面使用快 ...
- 新的WireGuard快照发布
导读 WireGuard首席开发人员Jason Donenfeld宣布发布WireGuard 0.0.20190123,作为Linux系统和其他平台的安全VPN隧道实施的最新快照. WireGuard ...
- VUE2 第五天学习--过渡效果
阅读目录 1.理解VUE---过渡效果 回到顶部 1.理解VUE---过渡效果 1. 过渡的-css-类名会有4个(css) 类名在 enter/leave 在过渡中切换.1. v-enter: 进入 ...
- Linux kernel Programming - Allocating Memory
kmalloc #include <linux/slab.h> void *kmalloc(size_t size,int flags); void kfree(void *addr); ...