
ELK学习总结(4-2)关于导入数据
用REST API的_bulk来批量插入,可以达到5到10w条每秒
把数据写进json文件,然后再通过批处理,执行文件插入数据:
1、先定义一定格式的json文件,文件不能过大,过大会报错
2、后用curl命令去执行Elasticsearch的_bulk来批量插入
建议生成10M一个文件,然后分别去执行这些小文件就可以了!
json数据文件内容的定义
{"index":{"_index":"meterdata","_type":"autoData"}}{"Mfid ":1,"TData":172170,"TMoney":209,"HTime":"2016-05-17T08:03:00"}{"index":{"_index":"meterdata","_type":"autoData"}}{"Mfid ":1,"TData":172170,"TMoney":209,"HTime":"2016-05-17T08:04:00"}{"index":{"_index":"meterdata","_type":"autoData"}}{"Mfid ":1,"TData":172170,"TMoney":209,"HTime":"2016-05-17T08:05:00"}{"index":{"_index":"meterdata","_type":"autoData"}}{"Mfid ":1,"TData":172170,"TMoney":209,"HTime":"2016-05-17T08:06:00"}{"index":{"_index":"meterdata","_type":"autoData"}}{"Mfid ":1,"TData":172170,"TMoney":209,"HTime":"2016-05-17T08:07:00"}cd E:\curl-7.50.3-win64-mingw\bincurl 172.17.1.15:9200/_bulk?pretty --data-binary @E:\Bin\Debug\testdata\437714060.jsoncurl 172.17.1.15:9200/_bulk?pretty --data-binary @E:\Bin\Debug\testdata\743719428.jsoncurl 172.17.1.15:9200/_bulk?pretty --data-binary @E:\Bin\Debug\testdata\281679894.jsoncurl 172.17.1.15:9200/_bulk?pretty --data-binary @E:\Bin\Debug\testdata\146257480.jsoncurl 172.17.1.15:9200/_bulk?pretty --data-binary @E:\Bin\Debug\testdata\892018760.jsonpause工具代码
private void button1_Click(object sender, EventArgs e)
{
//Application.StartupPath + "\\" + NextFile.Name
Task.Run(() => { CreateDataToFile(); });
}
public void CreateDataToFile()
{
StringBuilder sb = new StringBuilder();
StringBuilder sborder = new StringBuilder();
int flag = 1;
sborder.Append(@"cd E:\curl-7.50.3-win64-mingw\bin" + Environment.NewLine);
DateTime endDate = DateTime.Parse("2016-10-22");
for (int i = 1; i <= 10000; i++)//1w个点
{
DateTime startDate = DateTime.Parse("2016-10-22").AddYears(-1);
this.Invoke(new Action(() => { label1.Text = "生成第" + i + "个"; }));
while (startDate <= endDate)//每个点生成一年数据,每分钟一条
{
if (flag > 100000)//大于10w分割一个文件
{
string filename = new Random(GetRandomSeed()).Next(900000000) + ".json";
FileStream fs3 = new FileStream(Application.StartupPath + "\\testdata\\" + filename, FileMode.OpenOrCreate);
StreamWriter sw = new StreamWriter(fs3, Encoding.GetEncoding("GBK"));
sw.WriteLine(sb.ToString());
sw.Close();
fs3.Close();
sb.Clear();
flag = 1;
sborder.Append(@"curl 172.17.1.15:9200/_bulk?pretty --data-binary @E:\Bin\Debug\testdata\" + filename + Environment.NewLine);
}
else
{
sb.Append("{\"index\":{\"_index\":\"meterdata\",\"_type\":\"autoData\"}}" + Environment.NewLine);
sb.Append("{\"Mfid \":" + i + ",\"TData\":" + new Random().Next(1067500) + ",\"TMoney\":" + new Random().Next(1300) + ",\"HTime\":\"" + startDate.ToString("yyyy-MM-ddTHH:mm:ss") + "\"}" + Environment.NewLine);
flag++;
}
startDate = startDate.AddMinutes(1);//
}
}
sborder.Append("pause");
FileStream fs1 = new FileStream(Application.StartupPath + "\\testdata\\order.bat", FileMode.OpenOrCreate);
StreamWriter sw1 = new StreamWriter(fs1, Encoding.GetEncoding("GBK"));
sw1.WriteLine(sborder.ToString());
sw1.Close();
fs1.Close();
MessageBox.Show("生成完毕");
}
static int GetRandomSeed()
{//随机生成不重复的编号
byte[] bytes = new byte[4];
System.Security.Cryptography.RNGCryptoServiceProvider rng = new System.Security.Cryptography.RNGCryptoServiceProvider();
rng.GetBytes(bytes);
return BitConverter.ToInt32(bytes, 0);
}
总结
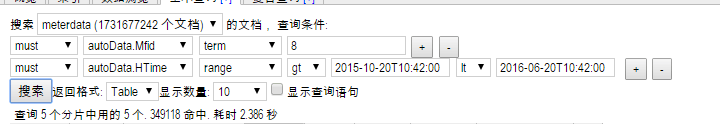
测试结果,发现Elasticsearch的搜索速度是挺快的,生成过程中,在17亿数据时查了一下,根据Mid和时间在几个月范围的数据,查十条数据两秒多完成查询,
而且同一查询条件查询越多,查询就越快,应该是Elasticsearch缓存了,
52亿条数据,大概占用500G空间左右,还是挺大的,
相比Protocol Buffers存储的数据,要大三倍左右,但搜索速度还是比较满意的。
ELK学习总结(4-2)关于导入数据的更多相关文章
- 吴裕雄--天生自然python学习笔记:pandas模块导入数据
有时候,手工生成 Pandas 的 DataFrame 数据是件非常麻烦的事情,所以我们通 常会先把数据保存在 Excel 或数据库中,然后再把数据导入 Pandas . 另 一种情况是抓 取网页中成 ...
- 大数据学习笔记——HBase使用bulkload导入数据
HBase使用bulkload批量导入数据 HBase可使用put命令向一张已经建好了的表中插入数据,然而,当遇到数据量非常大的情况,一条一条的进行插入效率将会大大降低,因此本篇博客将会整理提高批量导 ...
- ELK学习笔记之Elasticsearch和Kibana数据导出实战
0x00 问题引出 以下两个导出问题来自Elastic中文社区. 问题1.kibana怎么导出查询数据?问题2:elasticsearch数据导出就像数据库数据导出一样,elasticsearch可以 ...
- SPSS学习系列之SPSS Statistics导入读取数据(多种格式)(图文详解)
不多说,直接上干货! SPSS Statistics导入读取数据的步骤: 文件 -> 导入数据 成功! 欢迎大家,加入我的微信公众号:大数据躺过的坑 免费给分享 同时,大 ...
- 吴裕雄--天生自然 R语言开发学习:导入数据
2.3.6 导入 SPSS 数据 IBM SPSS数据集可以通过foreign包中的函数read.spss()导入到R中,也可以使用Hmisc 包中的spss.get()函数.函数spss.get() ...
- Solr学习笔记2(V7.2)---导入自己的数据
学而不思则罔,思而不学则殆,总是看文档不动手效果是不好的.没有实地的从自己的数据库获取数据测试一下始终是空,总结一下自己的操作步骤吧. 第一步准备配置文件 E:\Solr\server\solr\co ...
- Hbase 学习(十一)使用hive往hbase当中导入数据
我们可以有很多方式可以把数据导入到hbase当中,比如说用map-reduce,使用TableOutputFormat这个类,但是这种方式不是最优的方式. Bulk的方式直接生成HFiles,写入到文 ...
- Solr7.x学习(4)-导入数据
导入配置可参考官网:http://lucene.apache.org/solr/guide,http://lucene.apache.org/solr/guide/7_7/ 1.数据准备(MySQL8 ...
- 吴裕雄--天生自然MySQL学习笔记:MySQL 导入数据
1.mysql 命令导入 使用 mysql 命令导入语法格式为: mysql -u用户名 -p密码 < 要导入的数据库数据(runoob.sql) 实例: # mysql -uroot -p12 ...
- ELK学习笔记之CentOS 7下ELK(6.2.4)++LogStash+Filebeat+Log4j日志集成环境搭建
0x00 简介 现在的公司由于绝大部分项目都采用分布式架构,很早就采用ELK了,只不过最近因为额外的工作需要,仔细的研究了分布式系统中,怎么样的日志规范和架构才是合理和能够有效提高问题排查效率的. 经 ...
随机推荐
- [转]SVN使用log,list,cat,diff查看所有及特定文件版本信息
[转]SVN使用log,list,cat,diff查看所有及特定文件版本信息 http://onefishum.blog.163.com/blog/static/5184730520113153402 ...
- eclipse的注释
版权声明:本文为博主原创文章,转载请注明出处. 如果能帮助你,那我的目的就达到了 Window --> Java --> Code Style --> Code Templates ...
- 前端div层级控制
z-index:20000;使用此属性可以控制div的层级即哪个在上哪个在下
- selenium webdriver 的环境搭建时注意事项
selenium webdriver 在 eclipse中的配置,网络上应该很方便搜索到,这里只记搭建过程中容易出现的一些问题 1. selenium-java与selenium-sever-sta ...
- Linux压缩命令总结
2018-02-28 10:43:18 linux压缩和解压缩命令大全 tar命令:tar本身仅是一个打包的命令,不具有压缩的功能.打包后源文件仍然存在,具有将多个文件归档成一个文件的功能[root ...
- Android库项目中的资源ID冲突
1.前言 Android Studio对模块化开发提供的一个很有用的功能就是可以在主项目下新建库项目(Module),但是在使用库项目时却有一个问题就是资源ID冲突,因为编译时SDK会自动帮我们处理这 ...
- equals和hashCode详解
equals和hashCode详解 http://www.cnblogs.com/Qian123/p/5703507.html
- HTTP 0.9 HTTP 1.0 HTTP 1.1 HTTP 2.0区别
HTTP协议 :Hyper Text Transfer Protocol(超文本传输协议),是用于从万维网(WWW:World Wide Web)服务器传输超文本到本地浏览器的传送协议.是互联网上应用 ...
- mongodb的安装和配置
1.下载安装 wget https://fastdl.mongodb.org/linux/mongodb-linux-x86_64-3.0.6.tgz tar zxf mongodb-linux-x8 ...
- Linux下的指令:find,which
1. 在Linux系统下,使用find来查找文件: find [path] [condition] [operation] path指定了在哪个目录查找,condition限定了查找条件,operat ...