
074 hbase与mapreduce集成
一:运行给定的案例
1.获取jar包里的方法

2.运行hbase自带的mapreduce程序
lib/hbase-server-0.98.6-hadoop2.jar
3.具体运行
注意命令:mapredcp。
HADOOP_CLASSPATH是当前运行时需要的环境。

4.运行一个小方法
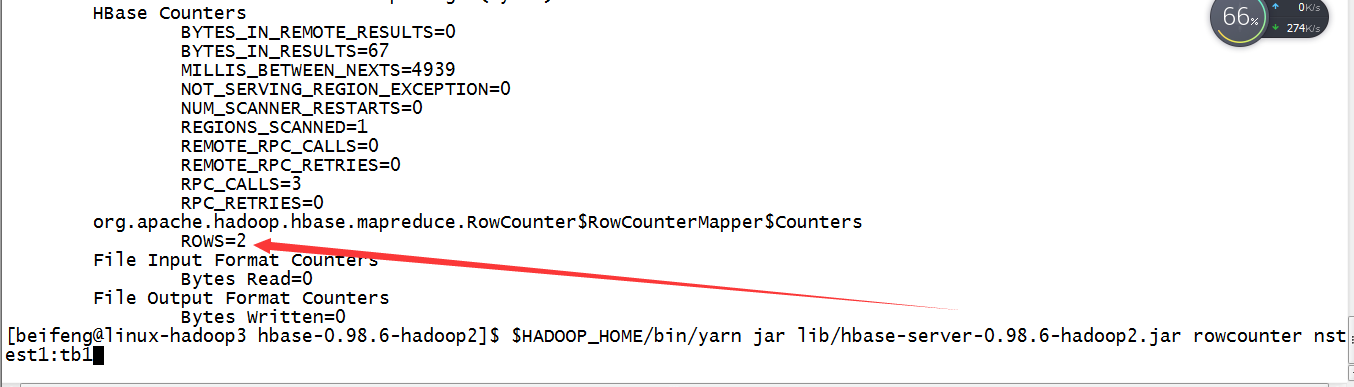
$HADOOP_HOME/bin/yarn jar lib/hbase-server-0.98.6-hadoop2.jar rowcounter nstest1:tb1
二:自定义hbase的数据拷贝
1.需求
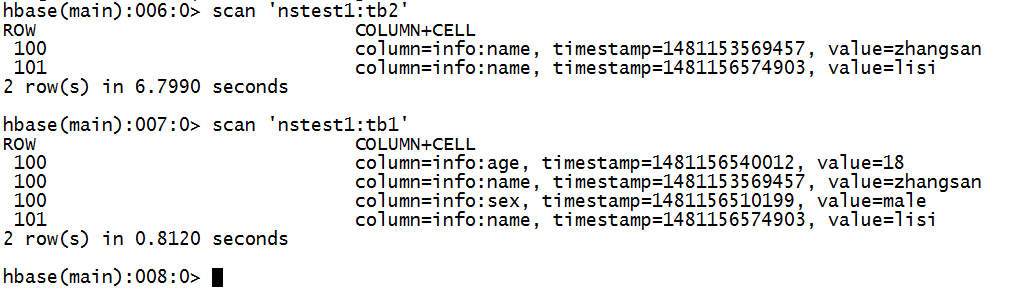
将nstest1:tb1的数据info:name列拷贝到nstest1:tb2
2.新建tb2表

3.书写mapreduce程序
输入:rowkey,result。
 package com.beifeng.bigdat;

 import java.io.IOException;

 import org.apache.hadoop.conf.Configuration;

 import org.apache.hadoop.conf.Configured;

 import org.apache.hadoop.hbase.Cell;

 import org.apache.hadoop.hbase.CellUtil;

 import org.apache.hadoop.hbase.HBaseConfiguration;

 import org.apache.hadoop.hbase.client.Put;

 import org.apache.hadoop.hbase.client.Result;

 import org.apache.hadoop.hbase.client.Scan;

 import org.apache.hadoop.hbase.io.ImmutableBytesWritable;

 import org.apache.hadoop.hbase.mapreduce.TableMapReduceUtil;

 import org.apache.hadoop.hbase.mapreduce.TableMapper;

 import org.apache.hadoop.hbase.mapreduce.TableReducer;

 import org.apache.hadoop.hbase.util.Bytes;

 import org.apache.hadoop.mapreduce.Job;

 import org.apache.hadoop.mapreduce.Mapper.Context;

 import org.apache.hadoop.util.Tool;

 import org.apache.hadoop.util.ToolRunner;

 public class HBaseMRTest extends Configured implements Tool{

     /**

      * map

      * @author      *

      */

     public static class tbMap extends TableMapper<ImmutableBytesWritable, Put>{

         @Override

         protected void map(ImmutableBytesWritable key, Result value,Context context) throws IOException, InterruptedException {

             Put put=new Put(key.get());

             for(Cell cell:value.rawCells()){

                 if("info".equals(Bytes.toString(CellUtil.cloneFamily(cell)))){

                     if("name".equals(Bytes.toString(CellUtil.cloneQualifier(cell)))){

                         put.add(cell);

                         context.write(key, put);

                     }

                 }

             }

         }

     }

     /**

      * reduce

      * @author      *

      */

     public static class tbReduce extends TableReducer<ImmutableBytesWritable, Put, ImmutableBytesWritable>{

         @Override

         protected void reduce(ImmutableBytesWritable key, Iterable<Put> values,Context context)throws IOException, InterruptedException {

             for(Put put:values){

                 context.write(key, put);

             }

         }

     }

     public int run(String[] args) throws Exception {

         Configuration conf=super.getConf();

         Job job =Job.getInstance(conf, "hbasemr");

         job.setJarByClass(HBaseMRTest.class);

         Scan scan=new Scan();

         TableMapReduceUtil.initTableMapperJob(

                 "nstest1:tb1",

                 scan,

                 tbMap.class,

                 ImmutableBytesWritable.class,

                 Put.class,

                 job);

         TableMapReduceUtil.initTableReducerJob(

                 "nstest1:tb2",

                 tbReduce.class,

                 job);

         boolean issucess=job.waitForCompletion(true);

         return issucess?0:1;

     }

     public static void main(String[] args) throws Exception{

         Configuration conf=HBaseConfiguration.create();

         int status=ToolRunner.run(conf, new HBaseMRTest(), args);

         System.exit(status);

     }

 }
4.打成jar包
5.运行语句
加上需要的export前提。
$HADOOP_HOME/bin/yarn jar /etc/opt/datas/HBaseMR.jar com.beifeng.bigdat.HBaseMRTest
6.效果
074 hbase与mapreduce集成的更多相关文章
- HBase概念学习(七)HBase与Mapreduce集成
这篇文章是看了HBase权威指南之后,依据上面的解说搬下来的样例,可是略微有些不一样. HBase与mapreduce的集成无非就是mapreduce作业以HBase表作为输入,或者作为输出,也或者作 ...
- HBase 与 MapReduce 集成
6. HBase 与 MapReduce 集成 6.1 官方 HBase 与 MapReduce 集成 查看 HBase 的 MapReduce 任务的执行:bin/hbase mapredcp; 环 ...
- hbase与mapreduce集成
一:运行给定的案例 1.获取jar包里的方法 2.运行hbase自带的mapreduce程序 lib/hbase-server-0.98.6-hadoop2.jar 3.具体运行 4.运行一个小方法 ...
- 【HBase】HBase与MapReduce集成——从HDFS的文件读取数据到HBase
目录 需求 步骤 一.创建maven工程,导入jar包 二.开发MapReduce程序 三.结果 需求 将HDFS路径 /hbase/input/user.txt 文件的内容读取并写入到HBase 表 ...
- hbase运行mapreduce设置及基本数据加载方法
hbase与mapreduce集成后,运行mapreduce程序,同时需要mapreduce jar和hbase jar文件的支持,这时我们需要通过特殊设置使任务可以同时读取到hadoop jar和h ...
- 【HBase】HBase与MapReduce的集成案例
目录 需求 步骤 一.创建maven工程,导入jar包 二.开发MapReduce程序 三.运行结果 HBase与MapReducer集成官方帮助文档:http://archive.cloudera. ...
- 大数据技术之_11_HBase学习_02_HBase API 操作 + HBase 与 Hive 集成 + HBase 优化
第6章 HBase API 操作6.1 环境准备6.2 HBase API6.2.1 判断表是否存在6.2.2 抽取获取 Configuration.Connection.Admin 对象的方法以及关 ...
- Hbase与hive集成与对比
HBase与Hive的对比 1.Hive (1) 数据仓库 Hive的本质其实就相当于将HDFS中已经存储的文件在Mysql中做了一个双射关系,以方便使用HQL去管理查询. (2) 用于数据分析.清洗 ...
- 《OD大数据实战》HBase整合MapReduce和Hive
一.HBase整合MapReduce环境搭建 1. 搭建步骤1)在etc/hadoop目录中创建hbase-site.xml的软连接.在真正的集群环境中的时候,hadoop运行mapreduce会通过 ...
随机推荐
- Ansi与Unicode编码
视频教程:Ansi与Unicode编码 大家在编程时经常遇到的数据类型: ● Ansi: char 代表一个字符 (CHAR) char * 代表一个字符串指针 (PCHAR PST ...
- luogu P2508 [HAOI2008]圆上的整点
传送门 推荐去bzoj看个视频了解一下 不要妄想视频直接告诉你题解 但是视频告诉了你后面要用的东西 首先我们要求的是\(x^2+y^2=n^2(x,y\in Z)\)的\((x,y)\)对数,可以转化 ...
- shiro与Web项目整合-Spring+SpringMVC+Mybatis+Shiro(八)
Jar包
- Java探针-Java Agent技术-阿里面试题
Java探针参考:Java探针技术在应用安全领域的新突破 最近面试阿里,面试官先是问我类加载的流程,然后问了个问题,能否在加载类的时候,对字节码进行修改 我懵逼了,答曰不知道,面试官说可以的,使用Ja ...
- /etc/my.cnf
[client] default-character-set=utf8 [mysqld] tmp_table_size = 2048M max_heap_table_size = 2048M max_ ...
- [转]HEX文件格式解析
1.前言 本文主要讲述keil MDK 下STM32编译生成的的HEX镜像文件格式.并说明镜像load地址是如何添加进HEX文件的. 2.keil MDK如何在HEX文件中添加load addr 通过 ...
- OpenWrt启动过程分析+添加自启动脚本【转】
一.OpenWrt启动过程分析 转自: http://www.eehello.com/?post=107 总结一下OpenWrt的启动流程:1.CFE->2.linux->3./etc/p ...
- 用nodejs搭建BS环境
var http = require('http'); http.createServer(function (req, res) {res.writeHead(200, {'Content-Type ...
- zabbix3.0.4报错Get value from agent failed: cannot connect to [[1.1.1.1]:10050]: [4] Interrupted syste
一.问题描述 部署完Zabbix agent之后,Server无法获取到数据.报错.报错信息如下: Get value from agent failed: cannot connect to [[1 ...
- centos6.7环境之kvm虚拟化quem工具配置及使用详解
环境准备 需要勾选CPU的虚拟化支持,支持cpu虚拟化的CPU列表: intel支持虚拟化技术CPU列表: Intel 6 Cores / 12 Threads CPU Number: Code Na ...