
Hadoop Compatibility in Flink
18 Nov 2014 by Fabian Hüske (@fhueske)
Apache Hadoop is an industry standard for scalable analytical data processing. Many data analysis applications have been implemented as Hadoop MapReduce jobs and run in clusters around the world. Apache Flink can be an alternative to MapReduce and improves it in many dimensions. Among other features, Flink provides much better performance and offers APIs in Java and Scala, which are very easy to use. Similar to Hadoop, Flink’s APIs provide interfaces for Mapper and Reducer functions, as well as Input- and OutputFormats along with many more operators. While being conceptually equivalent, Hadoop’s MapReduce and Flink’s interfaces for these functions are unfortunately not source compatible.
Flink’s Hadoop Compatibility Package
To close this gap, Flink provides a Hadoop Compatibility package to wrap functions implemented against Hadoop’s MapReduce interfaces and embed them in Flink programs. This package was developed as part of a Google Summer of Code 2014 project.
With the Hadoop Compatibility package, you can reuse all your Hadoop
InputFormats(mapred and mapreduce APIs)OutputFormats(mapred and mapreduce APIs)Mappers(mapred API)Reducers(mapred API)
in Flink programs without changing a line of code. Moreover, Flink also natively supports all Hadoop data types (Writables and WritableComparable).
The following code snippet shows a simple Flink WordCount program that solely uses Hadoop data types, InputFormat, OutputFormat, Mapper, and Reducer functions.
// Definition of Hadoop Mapper function

public class Tokenizer implements Mapper<LongWritable, Text, Text, LongWritable> { ... }

// Definition of Hadoop Reducer function

public class Counter implements Reducer<Text, LongWritable, Text, LongWritable> { ... }

public static void main(String[] args) {

  final String inputPath = args[0];

  final String outputPath = args[1];

  final ExecutionEnvironment env = ExecutionEnvironment.getExecutionEnvironment();

  // Setup Hadoop’s TextInputFormat

  HadoopInputFormat<LongWritable, Text> hadoopInputFormat =

      new HadoopInputFormat<LongWritable, Text>(

        new TextInputFormat(), LongWritable.class, Text.class, new JobConf());

  TextInputFormat.addInputPath(hadoopInputFormat.getJobConf(), new Path(inputPath));

  // Read a DataSet with the Hadoop InputFormat

  DataSet<Tuple2<LongWritable, Text>> text = env.createInput(hadoopInputFormat);

  DataSet<Tuple2<Text, LongWritable>> words = text

    // Wrap Tokenizer Mapper function

    .flatMap(new HadoopMapFunction<LongWritable, Text, Text, LongWritable>(new Tokenizer()))

    .groupBy(0)

    // Wrap Counter Reducer function (used as Reducer and Combiner)

    .reduceGroup(new HadoopReduceCombineFunction<Text, LongWritable, Text, LongWritable>(

      new Counter(), new Counter()));

  // Setup Hadoop’s TextOutputFormat

  HadoopOutputFormat<Text, LongWritable> hadoopOutputFormat =

    new HadoopOutputFormat<Text, LongWritable>(

      new TextOutputFormat<Text, LongWritable>(), new JobConf());

  hadoopOutputFormat.getJobConf().set("mapred.textoutputformat.separator", " ");

  TextOutputFormat.setOutputPath(hadoopOutputFormat.getJobConf(), new Path(outputPath));

  // Output & Execute

  words.output(hadoopOutputFormat);

  env.execute("Hadoop Compat WordCount");

}
As you can see, Flink represents Hadoop key-value pairs as Tuple2<key, value> tuples. Note, that the program uses Flink’s groupBy() transformation to group data on the key field (field 0 of the Tuple2<key, value>) before it is given to the Reducer function. At the moment, the compatibility package does not evaluate custom Hadoop partitioners, sorting comparators, or grouping comparators.
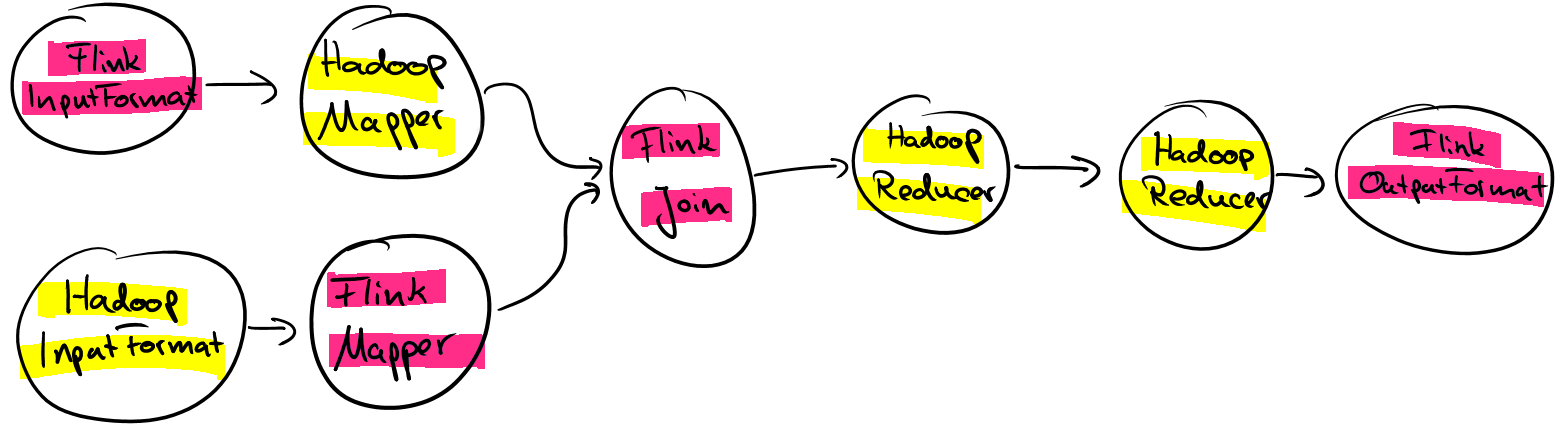
Hadoop functions can be used at any position within a Flink program and of course also be mixed with native Flink functions. This means that instead of assembling a workflow of Hadoop jobs in an external driver method or using a workflow scheduler such as Apache Oozie, you can implement an arbitrary complex Flink program consisting of multiple Hadoop Input- and OutputFormats, Mapper and Reducer functions. When executing such a Flink program, data will be pipelined between your Hadoop functions and will not be written to HDFS just for the purpose of data exchange.
What comes next?
While the Hadoop compatibility package is already very useful, we are currently working on a dedicated Hadoop Job operation to embed and execute Hadoop jobs as a whole in Flink programs, including their custom partitioning, sorting, and grouping code. With this feature, you will be able to chain multiple Hadoop jobs, mix them with Flink functions, and other operations such as Spargel operations (Pregel/Giraph-style jobs).
Summary
Flink lets you reuse a lot of the code you wrote for Hadoop MapReduce, including all data types, all Input- and OutputFormats, and Mapper and Reducers of the mapred-API. Hadoop functions can be used within Flink programs and mixed with all other Flink functions. Due to Flink’s pipelined execution, Hadoop functions can arbitrarily be assembled without data exchange via HDFS. Moreover, the Flink community is currently working on a dedicated Hadoop Job operation to supporting the execution of Hadoop jobs as a whole.
If you want to use Flink’s Hadoop compatibility package checkout our documentation.
Hadoop Compatibility in Flink的更多相关文章
- Hadoop,Spark,Flink 相关KB
Hive: https://stackoverflow.com/questions/17038414/difference-between-hive-internal-tables-and-exter ...
- flink hadoop yarn
新一代大数据处理引擎 Apache Flink https://www.ibm.com/developerworks/cn/opensource/os-cn-apache-flink/ 新一代大数据处 ...
- Flink学习笔记:Flink开发环境搭建
本文为<Flink大数据项目实战>学习笔记,想通过视频系统学习Flink这个最火爆的大数据计算框架的同学,推荐学习课程: Flink大数据项目实战:http://t.cn/EJtKhaz ...
- flink学习笔记-各种Time
说明:本文为<Flink大数据项目实战>学习笔记,想通过视频系统学习Flink这个最火爆的大数据计算框架的同学,推荐学习课程: Flink大数据项目实战:http://t.cn/EJtKh ...
- Flink Program Guide (1) -- 基本API概念(Basic API Concepts -- For Java)
false false false false EN-US ZH-CN X-NONE /* Style Definitions */ table.MsoNormalTable {mso-style-n ...
- 新一代大数据处理引擎 Apache Flink
https://www.ibm.com/developerworks/cn/opensource/os-cn-apache-flink/index.html 大数据计算引擎的发展 这几年大数据的飞速发 ...
- Flink知识点
1. Flink.Storm.Sparkstreaming对比 Storm只支持流处理任务,数据是一条一条的源源不断地处理,而MapReduce.spark只支持批处理任务,spark-streami ...
- 什么是Apache Flink
大数据计算引擎的发展 这几年大数据的飞速发展,出现了很多热门的开源社区,其中著名的有 Hadoop.Storm,以及后来的 Spark,他们都有着各自专注的应用场景.Spark 掀开了内存计算的先河, ...
- Flink 部署文档
Flink 部署文档 1 先决条件 2 下载 Flink 二进制文件 3 配置 Flink 3.1 flink-conf.yaml 3.2 slaves 4 将配置好的 Flink 分发到其他节点 5 ...
随机推荐
- 排查线上问题常用的几个Linux命令
top 相当于Windows任务管理器 可以看到,输出结果分两部分,前5行是总览,下面是具体的进程资源占用情况.下面逐行看一下 第1行 top - 18:14:58 up 112 days, 1:3 ...
- Markdown 文档生成工具
之前用了很多Markdown 文档生成工具,发现有几个挺好用的,现在整理出来,方便大家快速学习. loppo: 非常简单的静态站点生成器 idoc:简单的文档生成工具 gitbook:大名鼎鼎的文档协 ...
- C#2.0 迭代器
迭代器 迭代器模式是和为模式的一种范例,我们访问数据序列中所有的元素,不用关心序列是什么类型.从数据管道中数据经过一系列不同的转换或过滤后从管道的另一端出来. 像数组.集合等已经内置了迭代器,我们可以 ...
- C语言数组操作和指针操作谁更高效
在上一篇博文 代码优化小技巧(持续更新......) 第三条关于数组和指针谁更高效, 意犹未尽, 决定单独拉出一篇来讲 1. 数组和指针操作对比 #include <stdio.h> i ...
- 理解Python闭包概念
闭包并不只是一个python中的概念,在函数式编程语言中应用较为广泛.理解python中的闭包一方面是能够正确的使用闭包,另一方面可以好好体会和思考闭包的设计思想. 1.概念介绍 首先看一下维基上对闭 ...
- SpringMVC中@Controller和@RequestMapping用法和其他常用注解
一.简介 在SpringMVC 中,控制器Controller 负责处理由DispatcherServlet 分发的请求,它把用户请求的数据经过业务处理层处理之后封装成一个Model ,然后再把该Mo ...
- Perl List::Util模块用法详解
本文介绍Perl标准库List::Utils中的列表工具,有时候它们非常好用.比如Perl中测试列表中是否包含某个元素(某个元素是否存在于列表中)没有比较直接比较方便的功能,但使用List::Util ...
- Oracle闪回表
Oracle闪回技术 场景:测试环境数据库的表数据被误删除. 解决思路:使用闪回表技术 原理 闪回技术是Oracle强大数据库备份恢复机制的一部分,在数据库发生逻辑错误的时候,闪回技术能提供快速且最小 ...
- Springboot 系列(三)Spring Boot 自动配置原理
注意:本 Spring Boot 系列文章基于 Spring Boot 版本 v2.1.1.RELEASE 进行学习分析,版本不同可能会有细微差别. 前言 关于配置文件可以配置的内容,在 Spring ...
- DSAPI HTTP监听服务端与客户端
本文中,演示了使用DSAPI.网络相关.HTTP监听,快速建立服务端和客户端. HTTP监听服务端的作用,是监听指定计算机端口,以实现与IIS相同的解析服务,提供客户端的网页请求,当然,这不仅仅是应用 ...