
HADOOP/HDFS Essay
HDFS架构
the core of HADOOP/distributed systems is storeage(HDFS) and resource manager(YARN) for computing engines built on it.
Master/Slave: The character of distribution system follows M/S pattern.
Name Node
NN is the master and single active node. it contains / manges the namespace of files/dirs so called metadata , keeps block location andallocate data nodes.
Metadata is just like the one in linux file system including file name,size,owner/user,group,permission(umask) and HDFS specified elements like block ids , replication factor and block size and so on. Meta is in both memory and disk for fast access and restore respectively. NN also contains block location but it does not save it which is actually from DN. When a client access HDFS, it talks to NN first , NN checks the the permission, file existing just like the normal operation in a non-distributed linux system.
Data Node
The one actually stores files in form of blocks.
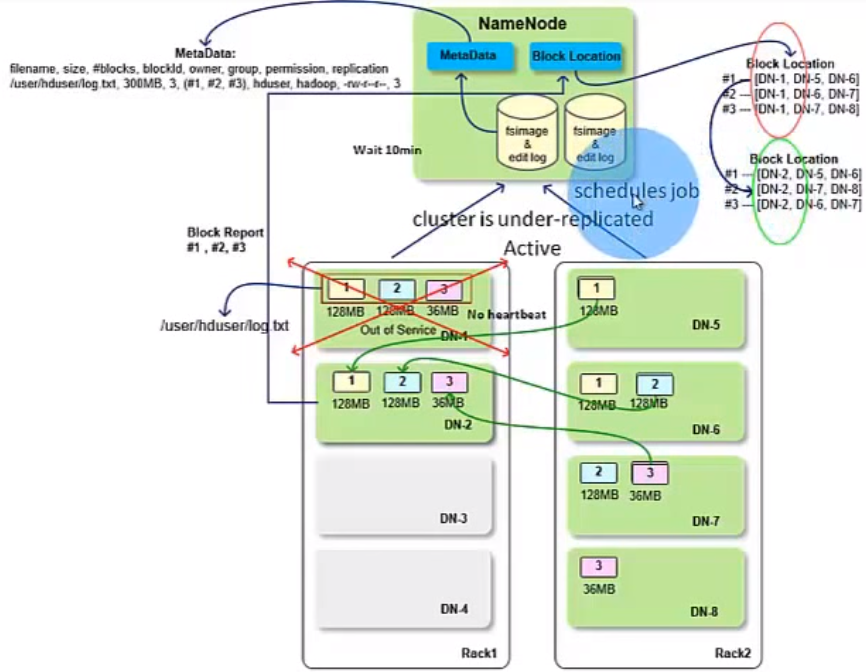
once a NN starts up, it sends its block report to NN like 'I(NN-1) has blocks #1,#2....' and it sends it periodically. So,NN can build a mapping of which bock in which DNs to serve file access request. DN also sends heartbeat information every 3 seconds to report its status along with actual data storage(total, free, used space and data transfer current in progress....) which is used for block allocating and and load banlancing by NN. a DN is considered dead if NN does not receive the HB within 10 mins. What is about the replication? It is for fault tolerance. If a block lost or a DN goes down, there is other nodes containing the same blocks. Also, based on the replciation, the system will also automatically replica the blocks if the number of copies does not meet the level.

Rack is nothing but a box with machines. dedicated power suply and network switch.
HDFS写
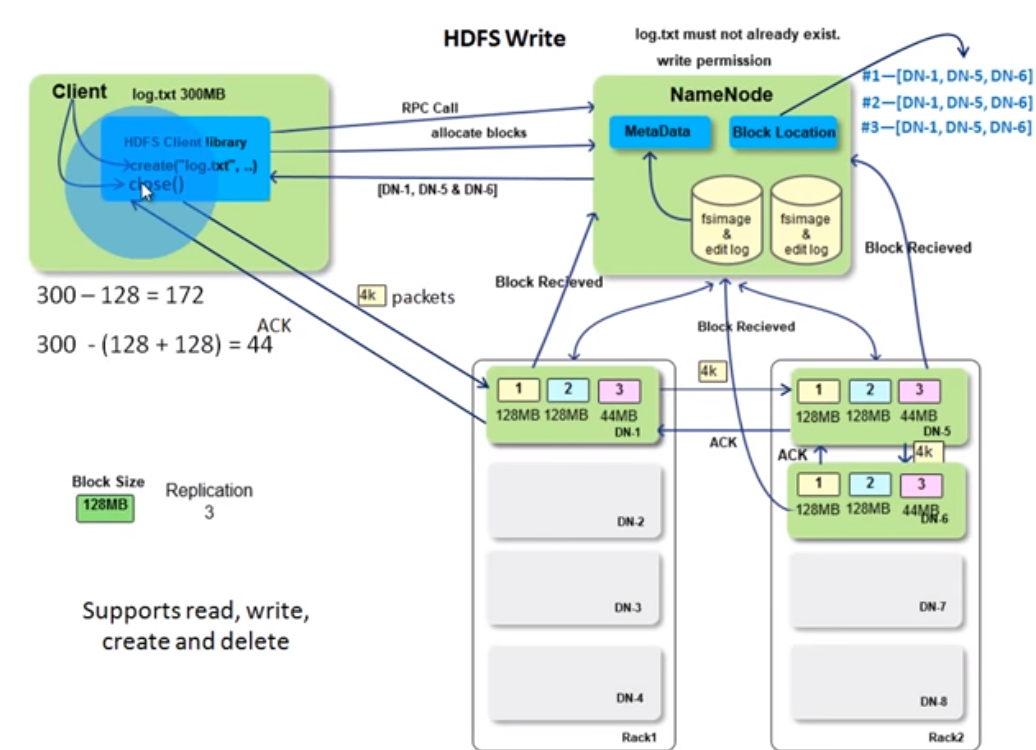
It should be easy to understand if you know the hdfs arch. client uses the hdfs client lib to manuplicate files. The communication is done thru RPC call. As mentioned before, NN will check metadata to see if client is qualified to write files. Then clients request NN to allocates blocks and NN returns the DN list(NN knows the status for each DN). for client to write the first 128MB block which is accumulated in the client library's managed space. This is the leader-folower pattern.The write to DNs is a pipleline so it is synchronized writing? client/leader writes data in a 4k packets and followers sends ACK so i guess it is synchronized writing. DNs also send the information to NN once it recieved the blocks. So, NN can build the block location in the write process as well. Then it contines to write the next 128 MB blocks. It loops till reach the EOF of the file. finally the client close() and indicates the operation is completed.
HDFS读
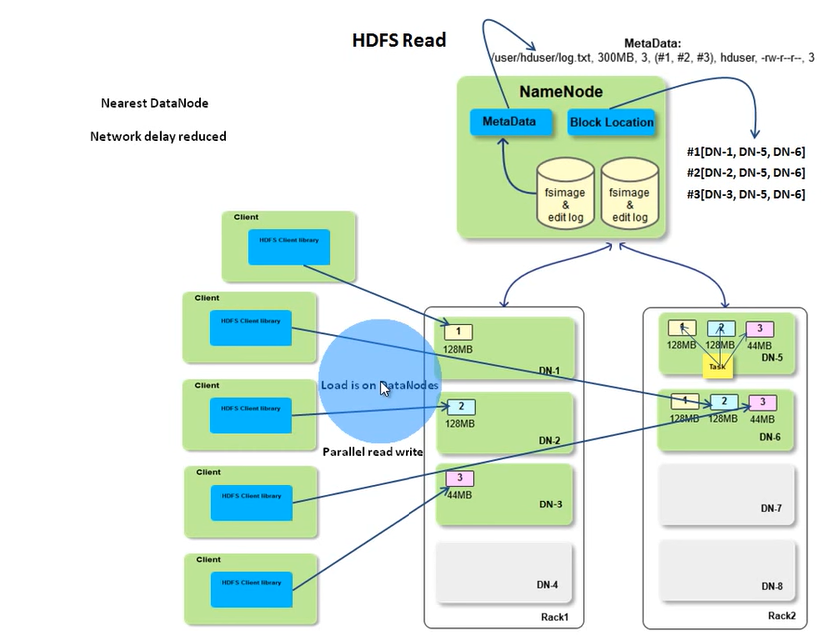
As mentioned before, you need HDFS java client library to perform the read operation like open the file, read the stream. client will call NN thru RPC to get the block id and block location. NN metadata has the block IDs for a file and the block location holds the mapping. Both of them are in memory and it should be fast. The actually read is between client and the DN. If the client is in a DN like a map task, the NN will return the block location with a list of network distance sort so the network delay will be reduced between racks. If the DN the map task is running on contains the blocks it needs, it will read directly locally. If the reading fails, client will switch to another node to read in the location list. Because of the data transfermation is between clients(you may have many current reads) and data nodes and name node only provides the block location, so, the load is distributed across the cluster. That's why HDFS is scalable. It may be not good to store vary large number of small files as name node may response poorly due to managing too much metadata.
When a DN is down
As we know, HDFS is reliable. If a data node goes down(NN does not receive its heart beat within 10 mins), there must be other data nodes storing the copies of the blocks in the failed data node depending on the replication level. So, the system is still available. But in this situation, the cluster is unser-replicated, and NN will schedule MR jobs to write the blocks to available data nodes to meet the replication level. When the data node(s) will send block report to NN , the block location will be updated accordingly.
Trade off among reliability, performance/network bandwidth
If you want to gain more reliability, for example, make the replication level to a big value (5?), the write operation will be very expensive(it not only involes writing data to disk of multiple data nodes but also count in tranferring data across data nodes so the performance is low) and vice versa.
HADOOP/HDFS Essay的更多相关文章
- Hadoop HDFS 用户指南
This document is a starting point for users working with Hadoop Distributed File System (HDFS) eithe ...
- Hadoop HDFS负载均衡
Hadoop HDFS负载均衡 转载请注明出处:http://www.cnblogs.com/BYRans/ Hadoop HDFS Hadoop 分布式文件系统(Hadoop Distributed ...
- Hive:org.apache.hadoop.hdfs.protocol.NSQuotaExceededException: The NameSpace quota (directories and files) of directory /mydir is exceeded: quota=100000 file count=100001
集群中遇到了文件个数超出限制的错误: 0)昨天晚上spark 任务突然抛出了异常:org.apache.hadoop.hdfs.protocol.NSQuotaExceededException: T ...
- Hadoop程序运行中的Error(1)-Error: org.apache.hadoop.hdfs.BlockMissingException
15/03/18 09:59:21 INFO mapreduce.Job: Task Id : attempt_1426641074924_0002_m_000000_2, Status : FAIL ...
- Hadoop HDFS编程 API入门系列之HDFS_HA(五)
不多说,直接上代码. 代码 package zhouls.bigdata.myWholeHadoop.HDFS.hdfs3; import java.io.FileInputStream;import ...
- Hadoop HDFS编程 API入门系列之简单综合版本1(四)
不多说,直接上代码. 代码 package zhouls.bigdata.myWholeHadoop.HDFS.hdfs4; import java.io.IOException; import ja ...
- [转]hadoop hdfs常用命令
FROM : http://www.2cto.com/database/201303/198460.html hadoop hdfs常用命令 hadoop常用命令: hadoop fs 查看H ...
- org.apache.hadoop.hdfs.server.namenode.SafeModeException: Cannot create directory /user/hive/warehouse/page_view. Name node is in safe mode
FAILED: Error in metadata: MetaException(message:Got exception: org.apache.hadoop.ipc.RemoteExceptio ...
- Hadoop HDFS文件常用操作及注意事项
Hadoop HDFS文件常用操作及注意事项 1.Copy a file from the local file system to HDFS The srcFile variable needs t ...
随机推荐
- oracle使用DBMS_RANDOM包生成随机数据
(一)DBMS_RANDOM包信息 DBMS_RANDOM包包含3个存储过程,4个函数,1个类型,一共8个模块,如下. SQL> desc dbms_random Element Type -- ...
- GPUImage源码解读之GPUImageContext
GPUImageContext类,提供OpenGL ES基本上下文,GPUImage相关处理线程,GLProgram缓存.帧缓存.由于是上下文对象,因此该模块提供的更多是存取.设置相关的方法. 属性列 ...
- 一站式学习Redis 从入门到高可用分布式实践
1:redis 是用c语言来实现的,速度快 持久化 单线程 复杂的数据类型有bitmap和hyperloglog和geo地理信息2:高可用.分布式 v2.8开始支持Redis-Sentinel(哨兵) ...
- js中回调函数写法
第一种方式 function studyEnglish(who){ document.write(who+"学习英语</br>"); } function study( ...
- Eclipse易卡死
在用eclipse编辑项目的时候,经常卡死,经过查询知道原来是我的JDK和eclipse版本对应的不好,我们都知道,eclipse的环境需要配置. 当时情况是这样的 2.容易出现卡死或者如图所示的情况 ...
- Redis(三):Redis数据类型
Redis数据类型目录导航: Redis五大数据类型 哪里去获取Redis常见数据类型操作命令 Redis键(Key) Redis字符串(String) Redis列表(List) Redis集合(S ...
- visual studio进程或线程自上一个步骤以来已更改
1.自己的解决方案:visual studio在多进程执行,在配置页面(webconfig)里把UseCounterThread参数设置为0 2.公司其他人解决方案,自己试了,多进程执行的时候没起作用 ...
- python3网络爬虫系统学习:第二讲 基本库requests(一)
之前,我们学习了基本库urllib的相关用法,但是在网页验证.Cookies处理等方面是比较繁琐的,需要用到Handler并且还需自己构建Opener.requests库的出现很好的解决了这个问题,下 ...
- Python学习笔记七:文件操作
文件操作 对照一个word文件的操作方式,来体会文件操作的内容 打开文件:f=open(“file”),提示编码错误,windows默认是GBK f=open(“file”,encoding=”utf ...
- c语言实现通讯录管理系统(c课程设计)
工具:Visual C++6.0 说明: 本系统基于C语言实现班级通讯录管理系统,为大一时学习C语言刚入门所做的课程设计.功能包括增.删.查.改等,非常适合初学者练手.通讯录包括的个人信息有姓名.学号 ...