
R语言作为BI中ETL的工具
R语言作为BI中ETL的工具,增删改
R语言提供了强大的R_package与各种数据库进行数据交互。
外加其强大数据变换清洗函数,为ETL提供一条方便快捷的道路。
RODBC
ROracal
RMysql
Rmongodb http://mirrors.ustc.edu.cn/CRAN/web/packages/rmongodb/vignettes/rmongodb_cheat_sheet.pdf
- step1 新建连接con,并查看其信息
library(RODBC)

con<-odbcConnect("LI")

con
RODBC Connection 1

Details:

  case=nochange

  DSN=LI

  UID=

  Trusted_Connection=Yes

  APP=RStudio

  WSID=LIYI-PC
- step2 引入数据集USArrests
data(USArrests)

head(USArrests)

           Murder Assault UrbanPop Rape

Alabama      13.2     236       58 21.2

Alaska       10.0     263       48 44.5

Arizona       8.1     294       80 31.0

Arkansas      8.8     190       50 19.5

California    9.0     276       91 40.6

Colorado      7.9     204       78 38.7
- step3 将USArrests保存到sqlserver
sqlSave(con, USArrests)
sqlSave(channel, dat, tablename = NULL, append = FALSE,

        rownames = TRUE, colnames = FALSE, verbose = FALSE,

        safer = TRUE, addPK = FALSE, typeInfo, varTypes,

        fast = TRUE, test = FALSE, nastring = NULL)

channel      数据库连接通道

dat              data frame.要存入的数据集

tablename  character 数据库中表名

index          character 索引列的名字

append       logical逻辑变量 ,是否数据集添加/写入已存在的表

rownames  logical 逻辑变量 or character字符串,如果是logical,表示是否把rowname这个字符串作为数据库表首列列名,如果是字符串,则将新字符串作为表首列列名

colnames  logical 逻辑变量 是否将数据集的列名保留作为表的首行 (谨慎更改,可能导致,列名变成数据第一行,各列的数据类型全部变为varchar(255)

verbose	  display statements as they are sent to the server?

safer     logical逻辑变量.如果真,生成一个新表,不在已存在的表后添加。如果假,强制删除已存在的同名表并新建,或者删除表中已存在的数据,覆盖写入

addPK     logical逻辑变量,是否将首列作为主键

typeInfo  list 数据框中数据类型。包括character ,double ,integer

varTypes  an optional named character vector giving the DBMSs datatypes to be used for some (or all) of the columns if a table is to be created.可选项涉及各列数据类型转换,因为数据库中的数据类型比R语言中的要多很多。

fast	  logical. If false, write data a row at a time. If true, use a parametrized INSERT INTO or UPDATE query to write all the data in one operation. 逻辑变量,如果F,数据将一次一行地写入,如果为Ture,将用到变量插入INSERT INTO,或者UPDATE 将数据一次性写入

nastring	 optional character string to be used for writing NAs to the database. 选择哪种字符串,将缺失项在数据库中填充
getSqlTypeInfo("Microsoft SQL Server")

$double

[1] "float"

$integer

[1] "int"

$character

[1] "varchar(255)"

$logical

[1] "varchar(5)"
sqlSave(con, USArrests,rownames = "city", addPK = T) # 原没有列名的rownames改名为city,并设置首列为主键key
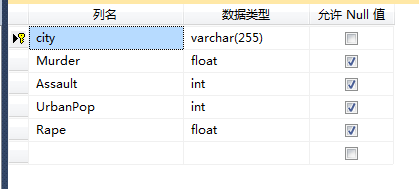
sqlSave(con, USArrests,'USA2',rownames = "city", addPK = T,fast=T,test=T) #注意此操作可能在数据库中create名为USA2的空表
Binding: 'city' DataType 12, ColSize 255

Binding: 'Murder' DataType 6, ColSize 53

Binding: 'Assault' DataType 4, ColSize 10

Binding: 'UrbanPop' DataType 4, ColSize 10

Binding: 'Rape' DataType 6, ColSize 53

Parameters:

no: 1: city Alabama/***/no: 2: Murder 13.2/***/no: 3: Assault 236/***/no: 4: UrbanPop 58/***/no: 5: Rape 21.2/***/

no: 1: city Alaska/***/no: 2: Murder 10/***/no: 3: Assault 263/***/no: 4: UrbanPop 48/***/no: 5: Rape 44.5/***/

no: 1: city Arizona/***/no: 2: Murder 8.1/***/no: 3: Assault 294/***/no: 4: UrbanPop 80/***/no: 5: Rape 31/***/

no: 1: city Arkansas/***/no: 2: Murder 8.8/***/no: 3: Assault 190/***/no: 4: UrbanPop 50/***/no: 5: Rape 19.5/***/

no: 1: city California/***/no: 2: Murder 9/***/no: 3: Assault 276/***/no: 4: UrbanPop 91/***/no: 5: Rape 40.6/***/

no: 1: city Colorado/***/no: 2: Murder 7.9/***/no: 3: Assault 204/***/no: 4: UrbanPop 78/***/no: 5: Rape 38.7/***/

no: 1: city Connecticut/***/no: 2: Murder 3.3/***/no: 3: Assault 110/***/no: 4: UrbanPop 77/***/no: 5: Rape 11.1/***/

no: 1: city Delaware/***/no: 2: Murder 5.9/***/no: 3: Assault 238/***/no: 4: UrbanPop 72/***/no: 5: Rape 15.8/***/

no: 1: city Florida/***/no: 2: Murder 15.4/***/no: 3: Assault 335/***/no: 4: UrbanPop 80/***/no: 5: Rape 31.9/***/

no: 1: city Georgia/***/no: 2: Murder 17.4/***/no: 3: Assault 211/***/no: 4: UrbanPop 60/***/no: 5: Rape 25.8/***/

no: 1: city Hawaii/***/no: 2: Murder 5.3/***/no: 3: Assault 46/***/no: 4: UrbanPop 83/***/no: 5: Rape 20.2/***/

no: 1: city Idaho/***/no: 2: Murder 2.6/***/no: 3: Assault 120/***/no: 4: UrbanPop 54/***/no: 5: Rape 14.2/***/

no: 1: city Illinois/***/no: 2: Murder 10.4/***/no: 3: Assault 249/***/no: 4: UrbanPop 83/***/no: 5: Rape 24/***/

no: 1: city Indiana/***/no: 2: Murder 7.2/***/no: 3: Assault 113/***/no: 4: UrbanPop 65/***/no: 5: Rape 21/***/

no: 1: city Iowa/***/no: 2: Murder 2.2/***/no: 3: Assault 56/***/no: 4: UrbanPop 57/***/no: 5: Rape 11.3/***/

no: 1: city Kansas/***/no: 2: Murder 6/***/no: 3: Assault 115/***/no: 4: UrbanPop 66/***/no: 5: Rape 18/***/

# 此处省略10000字
sqlColumns Enquire about the column structure of tables on an ODBC database connection. 访问数据库表的结构
columnsenquire<-sqlColumns(con,'USA2')

str(columnsenquire)
str(columnsenquire)

'data.frame':	5 obs. of  29 variables:

 $ TABLE_CAT                           : chr  "master" "master" "master" "master" ...

 $ TABLE_SCHEM                         : chr  "dbo" "dbo" "dbo" "dbo" ...

 $ TABLE_NAME                          : chr  "USA2" "USA2" "USA2" "USA2" ...

 $ COLUMN_NAME                         : chr  "city" "Murder" "Assault" "UrbanPop" ...

 $ DATA_TYPE                           : int  12 6 4 4 6

 $ TYPE_NAME                           : chr  "varchar" "float" "int" "int" ...

 $ COLUMN_SIZE                         : int  255 53 10 10 53

 $ BUFFER_LENGTH                       : int  255 8 4 4 8

 $ DECIMAL_DIGITS                      : int  NA NA 0 0 NA

 $ NUM_PREC_RADIX                      : int  NA 2 10 10 2

 $ NULLABLE                            : int  0 1 1 1 1

 $ REMARKS                             : chr  NA NA NA NA ...

 $ COLUMN_DEF                          : chr  NA NA NA NA ...

 $ SQL_DATA_TYPE                       : int  12 6 4 4 6

 $ SQL_DATETIME_SUB                    : int  NA NA NA NA NA

 $ CHAR_OCTET_LENGTH                   : int  255 NA NA NA NA

 $ ORDINAL_POSITION                    : int  1 2 3 4 5

 $ IS_NULLABLE                         : chr  "NO" "YES" "YES" "YES" ...

 $ SS_IS_SPARSE                        : int  0 0 0 0 0

 $ SS_IS_COLUMN_SET                    : int  0 0 0 0 0

 $ SS_IS_COMPUTED                      : int  0 0 0 0 0

 $ SS_IS_IDENTITY                      : int  0 0 0 0 0

 $ SS_UDT_CATALOG_NAME                 : chr  NA NA NA NA ...

 $ SS_UDT_SCHEMA_NAME                  : chr  NA NA NA NA ...

 $ SS_UDT_ASSEMBLY_TYPE_NAME           : chr  NA NA NA NA ...

 $ SS_XML_SCHEMACOLLECTION_CATALOG_NAME: chr  NA NA NA NA ...

 $ SS_XML_SCHEMACOLLECTION_SCHEMA_NAME : chr  NA NA NA NA ...

 $ SS_XML_SCHEMACOLLECTION_NAME        : chr  NA NA NA NA ...

 $ SS_DATA_TYPE                        : chr  "39" "109" "38" "38" ...
- step4 查询数据
sqlQuery(con,'select * from USArrests')
# 注意此时第一列的名字已经为city了

             city Murder Assault UrbanPop Rape

1         Alabama   13.2     236       58 21.2

2          Alaska   10.0     263       48 44.5

3         Arizona    8.1     294       80 31.0

4        Arkansas    8.8     190       50 19.5

5      California    9.0     276       91 40.6

6        Colorado    7.9     204       78 38.7

7     Connecticut    3.3     110       77 11.1

8        Delaware    5.9     238       72 15.8

9         Florida   15.4     335       80 31.9

10        Georgia   17.4     211       60 25.8

11         Hawaii    5.3      46       83 20.2

12          Idaho    2.6     120       54 14.2

13       Illinois   10.4     249       83 24.0

14        Indiana    7.2     113       65 21.0

...
对于sql语句可能是以‘XX’ 结尾则需要用如下形式来进行查询
sqlQuery(con,paste('select * from USArrests',

         "where city = 'Alabama'"))
 city Murder Assault UrbanPop Rape

1 Alabama   13.2     236       58 21.2
但是对于Update,以下却是失效的
a<-paste("update [master].[dbo].[USArrests]",

         "set Murder =13.2","where city ='Alabama'")

sqlQuery(con,a)   # 失效

sqlUpdate(con,a)  # 失效
sqlUpdate()  sqlUpdate(channel, dat, tablename = NULL, index = NULL,

          verbose = FALSE, test = FALSE, nastring = NULL,

          fast = TRUE)

不能进行脚本语句直接更新,但是可以进行如下操作

foo <- cbind(city=row.names(USArrests), USArrests)[1:3, c(1,3)]

 foo

           city Assault

Alabama Alabama     236

Alaska   Alaska     263

Arizona Arizona     294

 foo[1,2] <- 200

foo

           city Assault

Alabama Alabama     200

Alaska   Alaska     263

Arizona Arizona     294

流程是先选定要更新的行列,将值更新,然后再将值update入库
实例如下
temp<-sqlQuery(con,paste('select * from USArrests',

"where city = 'Alabama'"))

temp

     city Murder Assault UrbanPop Rape

1 Alabama   13.2     300       58 21.2

  str(temp)

'data.frame':	1 obs. of  5 variables:

 $ city    : Factor w/ 1 level "Alabama": 1

 $ Murder  : num 13.2

 $ Assault : num 300

 $ UrbanPop: int 58

 $ Rape    : num 21.2

  temp[1,]

[1] 300

  temp[1,3]<-200

  sqlUpdate(con, temp, "USArrests")

  sqlQuery(con,paste('select * from USArrests',

"where city = 'Alabama'"))

     city Murder Assault UrbanPop Rape

1 Alabama   13.2     200       58 21.2
sqlFetch(con, "USArrests", rownames = "city", max = 20,rows_at_time = 10)
实践后发现,单单对于简单的ETL,sqlQuery,sqlUpdate是足够了,
写一些for循环+list.files/liset.dir+reshape/ddplyr/tidyr(进行数据筛选,清洗,变换),
对于脚本是否执行的问题,可以写日志文件,对ETL过程进行检测。
step5 构建日志文件
- 监督机制,对于每次要写入/更新的数据进行count(originaldata),保存数据,然后与每次执行写入/变更的行数Rows进行比对,比对结果result为逻辑变量。将三者连同 执行时间,写成一个数据框,并在数据中新建对应的日志表,对执行结果进行监督。(对于追踪Rows没有找到很好的解决方法,send a letter ...)
- 暴力美学,对于sqlSave / sqlQuery 的执行结果进行追踪,成功为“1”,失败则"ON Errors"
step6 快速操作数据库
sqlClear deletes all the rows of the table sqtable. #清楚表中数据

sqlDrop removes the table sqtable (if permitted). #删除表

sqlClear(channel, sqtable, errors = TRUE)

sqlDrop(channel, sqtable, errors = TRUE)
R语言作为BI中ETL的工具的更多相关文章
- 概率图模型 基于R语言 这本书中的第一个R语言程序
概率图模型 基于R语言 这本书中的第一个R语言程序 prior <- c(working =0.99,broken =0.01) likelihood <- rbind(working = ...
- No.2 R语言在生物信息中的应用—模式匹配
目的: 1. 计算自定义模序在所有蛋白质的匹配位点和次数 2. 输出超过阈值的蛋白质序列到Hit_sequences.fasta 3. Hit_sequences.fasta中序列用小写字母,匹配用大 ...
- 微软的R语言发行版本MRO及开发工具RTVS
(此文章同时发表在本人微信公众号"dotNET每日精华文章",欢迎右边二维码来关注.) 题记:微软在收购R语言的开发商后,也独立发行或在自己的产品中集成了R语言,这里就介绍下它们包 ...
- [R语言]forecast.Arima中使用xreg报错
问题: 使用forecast.Arima对带xreg的arima模型进行预测,报xreg Error pre.m4x <- forecast.Arima(m4x, h = 20, xreg = ...
- No.1 R语言在生物信息中的应用——序列读取及格式化输出
目的:读入序列文件(fasta格式),返回一个数据框,内容包括--存储ID.注释行(anno).长度(len).序列内容(content) 一.问题思考: 1. 如何识别注释行和序列内容行 2. 如何 ...
- R语言读取matlab中数据
1. 在matlab中将数据保存到*.mat 文件夹 save("data.mat","data","label")#将data和label ...
- R语言使用过程中出现的问题--读取EXCEL文件
方法一: 按照R导论中的方法,使用RODBC包, library(RODBC) channel<-odbcConnectExcel("file.xlsx") da2<- ...
- R语言数据框中,用0替代NA缺失值
1.用0替代数据框中的缺失值NA 生成数据框: > m <- matrix(sample(c(NA, :), , replace = TRUE), ) > d <- as.da ...
- R语言判断向量中是否存在一个元素
判断ori_data[,1]中是否存在元素a: a %in% ori_data[,1] 如果存在返回 true,否则返回 false
随机推荐
- 多线程IP获取工具(C#)
以前帮一个朋友写的“IP采集工具”! Control.CheckForIllegalCrossThreadCalls = false; 多线程,测试后还比较稳定. 500线程时候,CPU5%左右,内存 ...
- [AR]高通Vuforia Getting Started
Vuforia Getting Started 简介 Vuforia创建增强现实应用程序是一个软件平台.开发人员可以轻松地将先进的计算机视觉功能添加到任何应用程序中,允许它识别图像和对象,或在现实 ...
- 去除inline-block元素间间距
根本原因:inline-block元素之间之所以有空白间距是因为空格有字体大小原因. 第一种: 把代码之间的换行空白都去掉. 例如: <div>第一个inline-block元素</ ...
- python-进程&线程
进程(process):相当于一个程序要运行时所需的所有资源的集合,相当于一个车间,不工作 两个进程之间的数据不共享,完全不独立,互相不能访问. 线程(thread):一道单一指令的控制流,寄生在进程 ...
- pcl曲面重建模块-poisson重建算法示例
poisson曲面重建算法 pcl-1.8测试通过 #include <iostream> #include <pcl/common/common.h> #include &l ...
- [LeetCode] Rotate Function 旋转函数
Given an array of integers A and let n to be its length. Assume Bk to be an array obtained by rotati ...
- [LeetCode] Transpose File 转置文件
Given a text file file.txt, transpose its content. You may assume that each row has the same number ...
- [LeetCode] Median of Two Sorted Arrays 两个有序数组的中位数
There are two sorted arrays nums1 and nums2 of size m and n respectively. Find the median of the two ...
- C#代码中实现两个表(DataTable)的关联查询(JOIN)
之前通常都是使用SQL直接从数据库中取出表1和表2关联查询后的数据,只需要用一个JOIN就可以了,非常方便.近日遇到一种情况,两个表中的数据已经取到代码中,需要在代码中将这两个表关联起来,并得到它们横 ...
- 关于delphi7的四舍五入
round 函数是银行用的 采用了 四舍六入5留偶 网上找到了个实现方法 先乘1000,用Trunc取整,除10取余,余数再取整,如果大于5,进位,小于5不进位. 函数就好写了 现在只写一个保留两 ...