
#论文阅读# Universial language model fine-tuing for text classification

论文链接:https://aclweb.org/anthology/P18-1031
对文章内容的总结
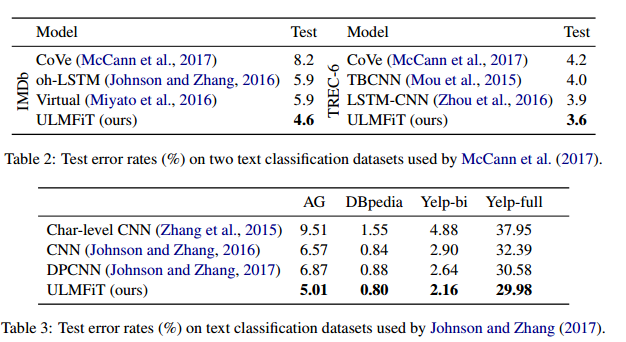
文章研究了一些在general corous上pretrain LM,然后把得到的model transfer到text classiffication上 整个过程的训练技巧。这些技巧的切入点是learning rate. 主要是三个:(1)discriminative fine-tuning (其中的discriminative 指 fine-tune each layer with different learning rate LR)(2)slanted triangular learning rate (在训练过程中先增加LR,增到预设的最大值后减小(减小速度<增加速度,所以LR随训练步数的曲线看起来是slanted triangle))(3)在训练text classiffication model时, perform gradual unfreezing. (即先锁住所有层的参数,训练过程中从最后一层开始,每训练一个epoch向前放开一层)
以下是ABSTACT和INTRODUCTION主要内容的翻译:

Contributions:
#论文阅读# Universial language model fine-tuing for text classification的更多相关文章
- 论文笔记 - Noisy Channel Language Model Prompting for Few-Shot Text Classification
Direct && Noise Channel 进一步把语言模型推理的模式分为了: 直推模式(Direct): 噪声通道模式(Noise channel). 直观来看: Direct ...
- 论文列表——text classification
https://blog.csdn.net/BitCs_zt/article/details/82938086 列出自己阅读的text classification论文的列表,以后有时间再整理相应的笔 ...
- 论文分享|《Universal Language Model Fine-tuning for Text Classificatio》
https://www.sohu.com/a/233269391_395209 本周我们要分享的论文是<Universal Language Model Fine-tuning for Text ...
- 【论文翻译】KLMo: Knowledge Graph Enhanced Pretrained Language Model with Fine-Grained Relationships
KLMo:建模细粒度关系的知识图增强预训练语言模型 (KLMo: Knowledge Graph Enhanced Pretrained Language Model with Fine-Graine ...
- 论文阅读笔记 Word Embeddings A Survey
论文阅读笔记 Word Embeddings A Survey 收获 Word Embedding 的定义 dense, distributed, fixed-length word vectors, ...
- 论文阅读笔记 Improved Word Representation Learning with Sememes
论文阅读笔记 Improved Word Representation Learning with Sememes 一句话概括本文工作 使用词汇资源--知网--来提升词嵌入的表征能力,并提出了三种基于 ...
- NLP问题特征表达基础 - 语言模型(Language Model)发展演化历程讨论
1. NLP问题简介 0x1:NLP问题都包括哪些内涵 人们对真实世界的感知被成为感知世界,而人们用语言表达出自己的感知视为文本数据.那么反过来,NLP,或者更精确地表达为文本挖掘,则是从文本数据出发 ...
- YOLO 论文阅读
YOLO(You Only Look Once)是一个流行的目标检测方法,和Faster RCNN等state of the art方法比起来,主打检测速度快.截止到目前为止(2017年2月初),YO ...
- BERT 论文阅读笔记
BERT 论文阅读 BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding 由 @快刀切草莓君 ...
随机推荐
- while 循环 continue break 用法例子
py2 temp = "理解" # utf- 8 #解码, 需要指定原来的是什么编码 temp_unicode = temp.decode("utf-8") # ...
- HDU 1074 Doing Homework ——(状态压缩DP)
考虑到n只有15,那么状压DP即可. 题目要求说输出字典序最小的答案的顺序,又考虑到题目给出的字符串本身字典序是递增的,那么枚举i的时候倒着来即可.因为在同样完成的情况下,后选字典序大的,小的字典序就 ...
- ICEM—三分之一风扇
原视频下载地址:https://yunpan.cn/cSwYBI6sb9vHS 访问密码 9059
- 【locust】使用locust + boomer实现对接口的压测
背景 很早之前,考虑单机执行能力,使用locust做过公司短信网关的压测工作,后来发现了一个golang版本的locust,性能是python版本的5到10倍以上,但是一直没有机会使用. 最近公司想做 ...
- windows工程总结
1.win32控制台console程序 运行在MS-DOS环境中的程序.控制台应用程序通常没有可视化的界面,只是通过字符串来显示或者监控程序.控制台程序常常被应用在测试.监控等用途,用户往往只关心数据 ...
- Oracle中shrink space命令
shrink_clause: http://docs.oracle.com/cd/B19306_01/server.102/b14200/statements_3001.htm#i2192484 ...
- 如何修改layer-layui中的confirm
需求: 改成 背景: 这个confirm是layui中的layer弹出框,要想修改这个弹出框的内容岂不是要去修改源码?当我在源码里扒拉半天梳理好了逻辑之后,突然意识到,其实我本可以不必这么麻烦的,直接 ...
- JAVA运维总结篇
写这篇文章主要目的是完成自己多年来运维JAVA应用的一个总结,相当于个人知识库,以后工作中遇到问题便于临时查阅并不断完善自己的知识体系. 上图,就知道Tomcat在JAVA容器界是多么重要. ...
- fastjson在将Map<Integer, String>转换成JSON字符串时,出现中文乱码问题
fastjson在将Map<Integer, String>转换成JSON字符串时,出现中文乱码问题. 先记下这个坑,改天在看看是怎么导致的,暂时通过避免使用Integer作为键(使用St ...
- JAVA 基础编程练习题27 【程序 27 求素数】
27 [程序 27 求素数] 题目:求 100 之内的素数 package cskaoyan; public class cskaoyan27 { @org.junit.Test public voi ...