
[转帖]怎样设计异步系统: Linux Native AIO vs io_uring
https://zhuanlan.zhihu.com/p/149836046
Linux native aio一方面有其实用价值, 基本满足了特别业务比如大型数据库系统对异步io的需求, 另一方面却被总是被诟病, 既不完美也不通用, 究其原因在于设计异步系统的理念.
AIO的需求
aio最核心的需求就是解偶submit和wait for completion, 简单地说就是在submit的时候不要阻塞, 这样用户在submit之后可以做其它事情或者继续submit新的io, 从而获得更高的cpu利用率和磁盘带宽. 早期aio的需求主要来源于数据库, 这对当时aio的设计起到了决定性的作用. 和大部分情况一样, 第一步先解决现有问题, 然后才去看能不能扩展到更通用的领域, 而实际情况往往是第一步就决定了后面不好扩展. 数据库比如innodb, page buffer由db自己管理, 基本不使用os提供的page cache, 只要实现异步的direct io就能满足db的需求.
AIO + DIO
因为主要目标是实现异步的direct io, 把io提交到device的request queue就可以, 后面的执行本来就是异步过程.
        do_syscall_64

        __x64_sys_io_submit

        io_submit_one

        __io_submit_one.constprop.0

        aio_write

        btrfs_file_write_iter

        generic_file_direct_write

        btrfs_direct_IO

        __blockdev_direct_IO

        do_blockdev_direct_IO

        btrfs_submit_direct

        btrfs_map_bio

        generic_make_request
大部分情况下submit direct io可以直接提交到request queue, 但是submit的路径上并不是完全没有阻塞点, 比如pin user page以及文件系统get_block, 或者超过了qdepth. 在某些编程模型下, 比如为了减少context switch的开销, 每个cpu只有一个thread, 当该thread sleep的时候, 就会直接影响到系统的吞吐. 但是db的编程模型并没有这种严格要求, 偶尔的阻塞并不一定能直接导致性能下降, 而且用户态也可以通过一些手段来降低submit阻塞的情况.
另外, 关于dio的语义也是比较模糊的, 引用 Clarifying Direct IO's Semantics 的一段话
The exact semantics of Direct I/O (O_DIRECT) are not well specified. It is not a part of POSIX, or SUS, or any other formal standards specification. The exact meaning of O_DIRECT has historically been negotiated in non-public discussions between powerful enterprise database companies and proprietary Unix systems, and its behaviour has generally been passed down as oral lore rather than as a formal set of requirements and specifications.
AIO + Buffer IO
难点
异步buffer io比dio复杂很多, dio本质上使用了device的request queue来处理磁盘io的阻塞, 而buffer io因为增加了一层page cache, 多出了很多阻塞点.
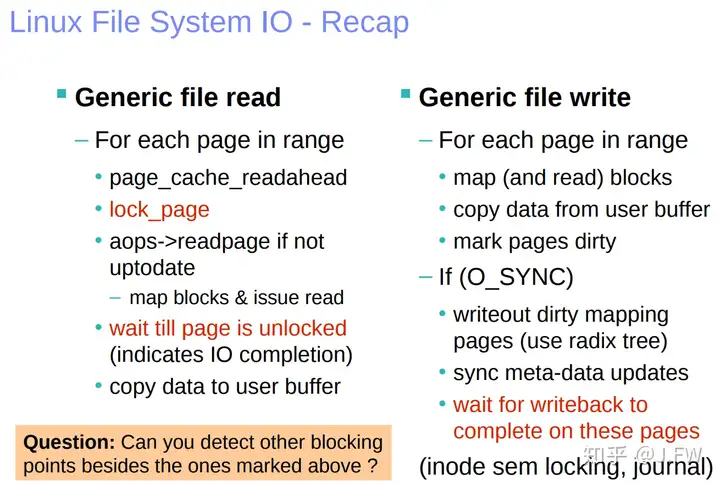
以read为例, 这里的异步并不要求page cache到user buffer的copy是异步的, 毕竟这并没有阻塞, 这里关注lock_page等导致的阻塞. 比如要读2个page, 第一个在page cache中并且uptodate, 而第二个不在page cache中, 同步的read会因为第2个page没有ready从而阻塞.
Retry-Based
为了做到异步化, 内核实现了retry-based的机制:
In a retry-based model, an operation executes by running through a series of iterations. Each iteration makes as much progress as possible in a non-blocking manner and returns. The model assumes that a restart of the operation from where it left off will occur at the next opportunity. To ensure that another opportunity indeed arises, each iteration initiates steps towards progress without waiting. The iteration then sets up to be notified when enough progress has been made and it is worth trying the next iteration. This cycle is repeated until the entire operation is finished.
以内核2.6.12为例, 支持aio的文件系统实现aio_read, 如果没有读完, 需要通知后面进行retry:
aio_pread

  ret = file->f_op->aio_read(iocb, iocb->ki_buf, iocb->ki_left, iocb->ki_pos);

  return -EIOCBRETRY if (ret > 0);  // 如果没有读完
而retry的函数正是aio_pread:
io_submit_one

  init_waitqueue_func_entry(&req->ki_wait, aio_wake_function);

  aio_setup_iocb(req);

    kiocb->ki_retry = aio_pread;

  aio_run_iocb(req);

    current->io_wait = &iocb->ki_wait;

    ret = retry(iocb);

    current->io_wait = NULL;

    __queue_kicked_iocb(iocb) if (-EIOCBRETRY == ret);
当read的数据ready时, 会retry之前未完成的部分:
aio_wake_function

  kick_iocb(iocb);

    queue_kicked_iocb

      run = __queue_kicked_iocb(iocb);

      aio_queue_work(ctx) if (run);

        queue_delayed_work(aio_wq, &ctx->wq, timeout);

INIT_WORK(&ctx->wq, aio_kick_handler, ctx);

aio_kick_handler

  requeue =__aio_run_iocbs(ctx);

  queue_work(aio_wq, &ctx->wq) if (requeue);
retry机制依赖一个前提, 每一次调用ki_retry()的时候不能block, 否则就没有retry一说, 所以需要将之前的阻塞点比如lock_page改造成非阻塞点, 在资源不ready的情况返回EIOCBRETRY, 而不是同步等待资源ready. 具体可以参考Filesystem AIO rdwr - aio read
-void __lock_page(struct page *page)

+int __lock_page_wq(struct page *page, wait_queue_t *wait)

 {

    wait_queue_head_t *wqh = page_waitqueue(page);

-   DEFINE_WAIT(wait);

+   DEFINE_WAIT(local_wait);

+   if (!wait)

+       wait = &local_wait;

+

    while (TestSetPageLocked(page)) {

-       prepare_to_wait(wqh, &wait, TASK_UNINTERRUPTIBLE);

+       prepare_to_wait(wqh, wait, TASK_UNINTERRUPTIBLE);

        if (PageLocked(page)) {

            sync_page(page);

+           if (!is_sync_wait(wait))

+               return -EIOCBRETRY;

            io_schedule();

        }

    }

-   finish_wait(wqh, &wait);

+   finish_wait(wqh, wait);

+   return 0;

+}

+EXPORT_SYMBOL(__lock_page_wq);

+

+void __lock_page(struct page *page)

+{

+   __lock_page_wq(page, NULL);

 }

 EXPORT_SYMBOL(__lock_page);

@@ -621,7 +655,13 @@

            goto page_ok;

        /* Get exclusive access to the page ... */

-       lock_page(page);

+

+       if (lock_page_wq(page, current->io_wait)) {

+           pr_debug("queued lock page \n");

+           error = -EIOCBRETRY;

+           /* TBD: should we hold on to the cached page ? */

+           goto sync_error;

+       }
Status
以2.6.12为例, 只有在aio_pread/aio_pwrite两个函数中返回了EIOCBRETRY, 而上面提到的lock_page等改造并没有进入内核, 所以buffer io的异步支持没有完成, 只是先加了用于支持retry的框架. 最终在这个commit中全部删掉了, btw, 下面说的kernel thread需要使用submit task的mm, 因为里面会涉及user/kernel间的内存拷贝.
commit 41003a7bcfed1255032e1e7c7b487e505b22e298

Author: Zach Brown <zab@redhat.com>

Date:   Tue May 7 16:18:25 2013 -0700

    aio: remove retry-based AIO

    This removes the retry-based AIO infrastructure now that nothing in tree

    is using it.

    We want to remove retry-based AIO because it is fundemantally unsafe.

    It retries IO submission from a kernel thread that has only assumed the

    mm of the submitting task.  All other task_struct references in the IO

    submission path will see the kernel thread, not the submitting task.

    This design flaw means that nothing of any meaningful complexity can use

    retry-based AIO.

    This removes all the code and data associated with the retry machinery.

    The most significant benefit of this is the removal of the locking

    around the unused run list in the submission path.
小结
retry based实现的aio + buffer io使用的设计模式是:
AIO = Sync IO - wait + retry这种模式注定了改造起来非常复杂, 首先要找到所有的同步点, 再一个一个改造成异步点, 这种try-and-fix的方法很难提供一个清晰的演进路径, 而aio + buffer io的user case不足以驱动全面改造, 最终native aio并没有真的提供buffer io的异步化. 最后我们引用 Asynchronous I/O Support in Linux 2.5 的一段话来看当时的设计目标:
Ideally, an AIO operation is completely non-blocking. If too few resources exist for an AIO operation to be completely non-blocking, the operation is expected to return -EAGAIN to the application rather than cause the process to sleep while waiting for resources to become available.
However, converting all potential blocking points that could be encountered in existing file I/O paths to an asynchronous form involves trade-offs in terms of complexity and/or invasiveness. In some cases, this tradeoff produces only marginal gains in the degree of asynchrony.
This issue motivated a focus on first identifying and tackling the major blocking points and less deeply nested cases to achieve maximum asynchrony benefits with reasonably limited changes. The solution can then be incrementally improved to attain greater asynchrony.
io_uring
小测试
我们使用fio来做个简单的测试, 看看io_uring大致的工作流程.
- 清空page cache, 后面的read需要从磁盘load数据
# echo 3 > /proc/sys/vm/drop_caches- 监控io_read / page_cache_sync_readahead / page_cache_async_readahead等函数
$ sudo trace-bpfcc -K 'r::io_read (retval) "r=%x", retval' \

        'r::page_cache_sync_readahead' \

'r::page_cache_async_readahead'- 使用io_uring引擎执行fio
$ ./fio --name=aaa --filename=aaa --ioengine=io_uring --rw=read --size=16k --bs=8k根据如下收集的结果, 我们可以大致看出io_uring异步读数据流程:
- fio通过io_uring_enter发送异步读请求. 因为page cache中没有该数据, 肯定需要磁盘io. 但是在该submit路径上, 并未下发io请求, 而是返回了EAGAIN (fffffff5)
- 随后在kworker中, 真正下发io请求
- 第3个栈是因为我们需要读入连续的(顺序读)两个block(16k/8k), 第2个io在前一个io的readahead window
17547   17547   fio             io_read          r=fffffff5

        kretprobe_trampoline+0x0 [kernel]

        io_queue_sqe+0xd3 [kernel]

        io_submit_sqe+0x2ea [kernel]

        io_ring_submit+0xbf [kernel]

        __x64_sys_io_uring_enter+0x1aa [kernel]

        do_syscall_64+0x5a [kernel]

        entry_SYSCALL_64_after_hwframe+0x44 [kernel]

15931   15931   kworker/u64:10  page_cache_sync_readahead

        kretprobe_trampoline+0x0 [kernel]

        generic_file_read_iter+0xdc [kernel]

        io_read+0xeb [kernel]

        kretprobe_trampoline+0x0 [kernel]

        io_sq_wq_submit_work+0x15f [kernel]

        process_one_work+0x1db [kernel]

        worker_thread+0x4d [kernel]

        kthread+0x104 [kernel]

        ret_from_fork+0x22 [kernel]

17547   17547   fio             page_cache_async_readahead

        kretprobe_trampoline+0x0 [kernel]

        generic_file_read_iter+0xdc [kernel]

        io_read+0xeb [kernel]

        kretprobe_trampoline+0x0 [kernel]

        io_queue_sqe+0xd3 [kernel]

        io_submit_sqe+0x2ea [kernel]

        io_ring_submit+0xbf [kernel]

        __x64_sys_io_uring_enter+0x1aa [kernel]

        do_syscall_64+0x5a [kernel]

        entry_SYSCALL_64_after_hwframe+0x44 [kernel]
实现
具体的实现这里不一一展开, 主要看一下user space和kernel space交互的几个ring buffer. 图片来源: https://mattermost.com/blog/iouring-and-go/
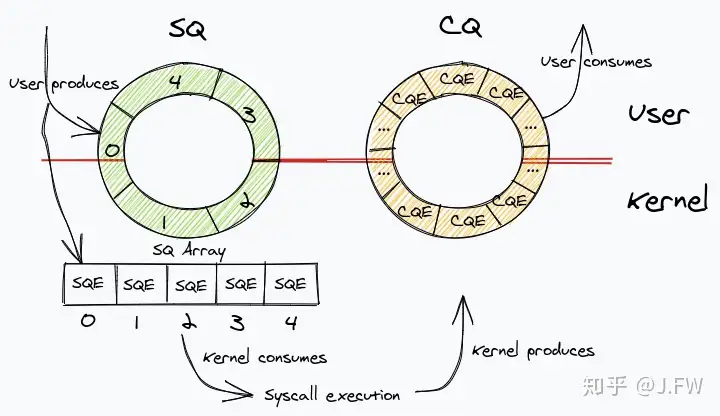
通过SQ, 把submit path的逻辑和kernel的其他模块解耦, 确保submit path上不会阻塞. 如上面的测试, 在io_uring_enter的时候不会去调用可能会导致阻塞的page_cache_sync_readahead, 而是使用workqueue的方式后台执行, 当然worker线程是可能也是可以被阻塞的. 另外SQ的可用长度在userspace是可见的, 所以也不会因为等待SQ entry而阻塞.
总结
最简单高效的异步系统是生产者将任务投递到一条队列上, 消费者处理队列上的任务. 如果在任务到达队列之前生产者就已经阻塞, 那么就不能达到异步的目的, 所以这条队列需要尽可能靠近生产者, 而不是靠近消费者. 这样的投递系统不只简单高效, 并且十分通用, 可以适用绝大部分任务, 所以io_uring不只在传统的块设备上发挥重要作用, 已经广泛应用到各种场合.
参考资料
[转帖]怎样设计异步系统: Linux Native AIO vs io_uring的更多相关文章
- Linux Native Aio 异步AIO的研究
Linux Native Aio 异步AIO的研究 http://rango.swoole.com/archives/282 首先声明一下epoll+nonblock从宏观角度可以叫做全异步,但从微观 ...
- 浅析Linux Native AIO的实现
前段时间在自研的基于iSCSI的SAN 上跑mysql,CPU的iowait很大,后面改用Native AIO,有了非常大的改观.这里简单总结一下Native AIO的实现.对于以IO为最大瓶颈的数据 ...
- 嵌入式系统Linux内核开发工程师必须掌握的三十道题(转)
嵌入式系统Linux内核开发工程师必须掌握的三十道题 如果你能正确回答以下问题并理解相关知识点原理,那么你就可以算得上是基本合格的Linux内核开发工程师,试试看! 1) Linux中主要有哪几种内核 ...
- 架构设计:系统存储(28)——分布式文件系统Ceph(挂载)
(接上文<架构设计:系统存储(27)--分布式文件系统Ceph(安装)>) 3. 连接到Ceph系统 3-1. 连接客户端 完毕Ceph文件系统的创建过程后.就能够让客户端连接过去. Ce ...
- Java生鲜电商平台-电商促销业务分析设计与系统架构
Java生鲜电商平台-电商促销业务分析设计与系统架构 说明:Java开源生鲜电商平台-电商促销业务分析设计与系统架构,列举的是常见的促销场景与源代码下载 左侧为享受促销的资格,常见为这三种: 首单 大 ...
- 10、ERP设计之系统基础管理(BS)- 平台化设计
ShareERP 2013-09-03 ERP业务平台化是每个软件提供商必须要进行的趋势,传统定制化路线已死,不能走定制化的老路了.以往最大问的题是不能累积和沉淀技术及提升项目业务管理能力,其次是管理 ...
- 架构设计:系统存储(24)——数据一致性与Paxos算法(中)
(接上文<架构设计:系统存储(23)--数据一致性与Paxos算法(上)>) 2-1-1. Prapare准备阶段 首先须要介绍几个在Acceptor角色上须要被持久化保存的数据属性: P ...
- 架构设计:系统间通信(20)——MQ:消息协议(下)
(接上文<架构设计:系统间通信(19)--MQ:消息协议(上)>) 上篇文章中我们重点讨论了"协议"的重要性.并为各位读者介绍了Stomp协议和XMPP协议. 这两种协 ...
- ERP设计之系统基础管理(BS)-日志模块设计(转载)
原文地址:8.ERP设计之系统基础管理(BS)-日志模块设计作者:ShareERP 日志模块基本要素包括: 用户会话.登录.注销.模块加载/卸载.数据操作(增/删/改/审/弃/关等等).数据恢复.日志 ...
- 架构设计:系统间通信(34)——被神化的ESB(上)
1.概述 从本篇文章开始,我们将花一到两篇的篇幅介绍ESB(企业服务总线)技术的基本概念,为读者们理清多个和ESB技术有关名词.我们还将在其中为读者阐述什么情况下应该使用ESB技术.接下来,为了加深读 ...
随机推荐
- 第六部分_Shell脚本流程控制语句
流程控制语句 关键词:选择(人生漫漫长路,我该何去何从) 1. 基本语法结构 ㈠ if结构 箴言1:只要正确,就要一直向前冲️ F:表示false,为假 T:表示true,为真 if [ condit ...
- 高性能网络设计秘笈:深入剖析Linux网络IO与epoll
本文分享自华为云社区<高性能网络设计秘笈:深入剖析Linux网络IO与epoll>,作者: Lion Long . 一.epoll简介 epoll是Linux内核中一种可扩展的IO事件处理 ...
- 再获殊荣!华为云GaussDB喜提“科技进步一等奖”
摘要:近日,中国电子学会科学技术奖励大会颁发了2021-2022年度中国电子学会科学技术奖获奖项目,华为云主导的"GaussDB智能云原生分布式数据库"项目荣获"科技进步 ...
- 教你如何优雅的改写“if-else”
摘要:这些场景,你是怎么写的代码? if-else,这是个再正常不过的coding习惯,当我们代码量小的时候用来做条件判断是再简单不过的了.但对于优秀程序员来说,这却不是好代码. 不信你往下看- 1. ...
- Apache HBase MTTR 优化实践:减少恢复时长
摘要:HBase是Hadoop Database的简称,是建立在Hadoop文件系统之上的分布式面向列的数据库,它具有高可靠.高性能.面向列和可伸缩的特性,提供快速随机访问海量数据能力. 本文分享自华 ...
- AI贺新年,开发者的虎年这样过才有意思
摘要:祝所有的开发者们新春快乐,万事如意迎新年,如虎添翼旺全年! 普通人拜年,发一个祝福微信.程序员拜年,运行一串代码,制作独一无二的拜年短视频. 普通人送祝福,新年快乐.程序员送祝福,信手捏来一首拜 ...
- xcode打包导出ipa
xcode打包导出ipa 众所周知,在开发苹果应用时需要使用签名(证书)才能进行打包安装苹果IPA,作为刚接触ios开发的同学,只是学习ios app开发内测,并没有上架appstore需求,对于苹果 ...
- 智能电视APP鲜时光,如何应用AB测试打造极致的用户观看体验?
更多技术交流.求职机会,欢迎关注字节跳动数据平台微信公众号,回复[1]进入官方交流群 数字技术的发展让智能电视普及率大幅提升,2023年智能电视的市场渗透率已超90%,与智能电视相匹配的各类应用 ...
- Intellij 查找排除JAR包的依赖关系(Maven Helper)
Intellij 查找排除JAR包的依赖关系(Maven Helper) 安装插件 Windows 类似
- 用户 IP,里面藏了多少秘密?
大家都知道,要邮寄一封信给正确的收件人,需要提供准确而精细的地址,这个地址需要从国家和城市精确到邮政编码,街道和门牌号码.只有这样,邮局的工作人员才能知道将信送到那里. Internet 上也是如此, ...