
Hadoop 上Hive 的操作
数据dept表的准备:
--创建dept表

CREATE TABLE dept(

  deptno int,

  dname string,

  loc string)

ROW FORMAT DELIMITED FIELDS TERMINATED BY ','  STORED AS textfile;
数据文件准备:
vi detp.txt

10,ACCOUNTING,NEW YORK

20,RESEARCH,DALLAS

30,SALES,CHICAGO

40,OPERATIONS,BOSTON
数据表emp准备:
CREATE TABLE emp(

  empno int,

  ename string,

  job string,

  mgr int,

  hiredate string,

  sal int,

  comm int,

  deptno int)

ROW FORMAT DELIMITED FIELDS TERMINATED BY ',' STORED AS textfile;
表emp数据准备:
vi emp.txt

7369,SMITH,CLERK,7902,1980-12-17,800,null,20

7499,ALLEN,SALESMAN,7698,1981-02-20,1600,300,30

7521,WARD,SALESMAN,7698,1981-02-22,1250,500,30

7566,JONES,MANAGER,7839,1981-04-02,2975,null,20

7654,MARTIN,SALESMAN,7698,1981-09-28,1250,1400,30

7698,BLAKE,MANAGER,7839,1981-05-01,2850,null,30

7782,CLARK,MANAGER,7839,1981-06-09,2450,null,10

7788,SCOTT,ANALYST,7566,1987-04-19,3000,null,20

7839,KING,PRESIDENT,null,1981-11-17,5000,null,10

7844,TURNER,SALESMAN,7698,1981-09-08,1500,0,30

7876,ADAMS,CLERK,7788,1987-05-23,1100,null,20

7900,JAMES,CLERK,7698,1981-12-03,950,null,30

7902,FORD,ANALYST,7566,1981-12-02,3000,null,20

7934,MILLER,CLERK,7782,1982-01-23,1300,null,10
把数据文件装到表里
load data local inpath '/home/hadoop/tmp/dept.txt' overwrite into table dept;

load data local inpath '/home/hadoop/tmp/emp.txt' overwrite into table emp;
查询语句
select d.dname,d.loc,e.empno,e.ename,e.hiredate from dept d join emp e on e.deptno = d.deptno ;

  * 可以看到走的是map reduce 程序
二、Hive分区
hive分区的目的
* hive为了避免全表扫描,从而引进分区技术来将数据进行划分。减少不必要数据的扫描,从而提高效率。
hive分区和mysql分区的区别
* mysql分区字段用的是表内字段;而hive分区字段采用表外字段。
hive的分区技术
* hive的分区字段是一个伪字段,但是可以用来进行操作。
* 分区字段不进行区分大小写
* 分区可以是表分区或者分区的分区,可以有多个分区
hive分区根据
* 看业务,只要是某个标识能把数据区分开来。比如:年、月、日、地域、性别等
分区关键字
* partitioned by(字段)
分区本质
* 在表的目录或者是分区的目录下在创建目录,分区的目录名为指定字段=值
创建分区表:
create table if not exists u1( id int, name string, age int ) partitioned by(dt string) row format delimited fields terminated by ' '
stored as textfile;
数据准备:
[hadoop@master tmp]$ more u1.txt

1 xm1 16

2 xm2 18

3 xm3 22
加载数据:
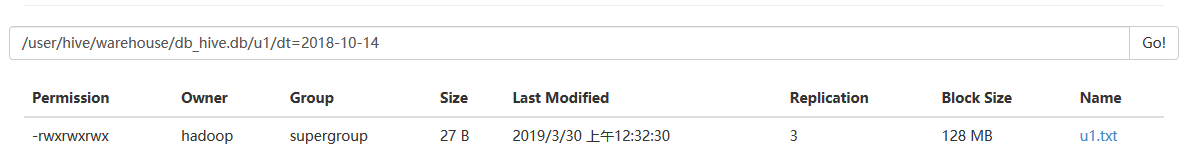
load data local inpath '/home/hadoop/tmp/u1.txt' into table u1 partition(dt="2018-10-14");
查询:
hive> select * from u1;

OK

1       xm1     16      2018-10-14

2       xm2     18      2018-10-14

3       xm3     22      2018-10-14

Time taken: 5.919 seconds, Fetched: 3 row(s)
查询分区:
hive> select * from u1 where dt='2018-10-15';

OK

1       xm1     16      2018-10-15

2       xm2     18      2018-10-15

3       xm3     22      2018-10-15

Time taken: 0.413 seconds, Fetched: 3 row(s)
Hive的二级分区
创建表u2
create table if not exists u2(id int,name string,age int)

partitioned by(month int,day int) row format delimited fields terminated by ' ' stored as textfile;
导入数据:
load data local inpath '/home/hadoop/tmp/u2.txt' into table u2 partition(month=9,day=14);
数据查询:
hive> select * from u2;

OK

1       xm1     16      9       14

2       xm2     18      9       14

Time taken: 0.303 seconds, Fetched: 2 row(s)
分区修改:
查看分区:
hive>  show partitions u1;
OK
dt=2018-10-14
dt=2018-10-15
增加分区:
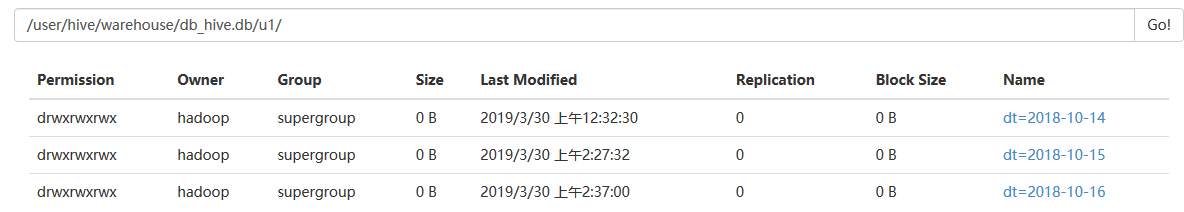
 > alter table u1 add partition(dt="2018-10-16");

  OK
查看新增加的分区:
hive>  show partitions u1;

OK

dt=2018-10-14

dt=2018-10-15

dt=2018-10-16

Time taken: 0.171 seconds, Fetched: 3 row(s)
删除分区:
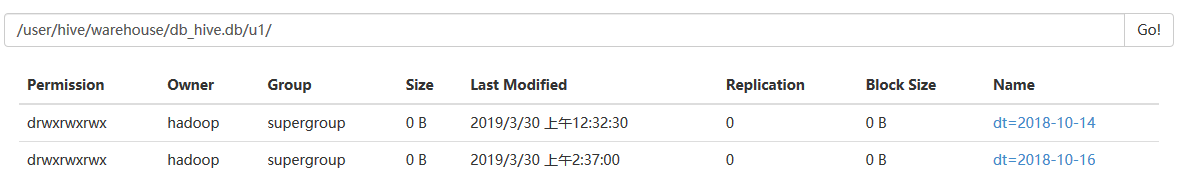
hive> alter table u1 drop partition(dt="2018-10-15");

Dropped the partition dt=2018-10-15

OK

Time taken: 0.576 seconds

hive>  select * from u1 ;

OK

1       xm1     16      2018-10-14

2       xm2     18      2018-10-14

3       xm3     22      2018-10-14

Time taken: 0.321 seconds, Fetched: 3 row(s)
三、hive动态分区
hive配置文件hive-site.xml 文件里有配置参数:
hive.exec.dynamic.partition=true; 是否允许动态分区
hive.exec.dynamic.partition.mode=strict/nostrict; 动态区模式为严格模式
strict: 严格模式,最少需要一个静态分区列(需指定固定值)
nostrict:非严格模式,允许所有的分区字段都为动态。
hive.exec.max.dynamic.partitions=1000; 允许最大的动态分区
hive.exec.max.dynamic.partitions.pernode=100; 单个节点允许最大分区
创建动态分区表
动态分区表的创建语句与静态分区表相同,不同之处在与导入数据,静态分区表可以从本地文件导入,但是动态分区表需要使用from…insert into语句导入。
create table if not exists u3(id int,name string,age int) partitioned by(month int,day int)
row format delimited fields terminated by ' ' stored as textfile;
导入数据,将u2表中的数据加载到u3中:
from u2

insert into table u3 partition(month,day)

select id,name,age,month,day;
FAILED: SemanticException [Error 10096]: Dynamic partition strict mode requires at least one static partition column. To turn this off set hive.exec.dynamic.partition.mode=nonstrict
解决方法:
要动态插入分区必需设置hive.exec.dynamic.partition.mode=nonstrict
hive> set hive.exec.dynamic.partition.mode;
hive.exec.dynamic.partition.mode=strict
hive> set hive.exec.dynamic.partition.mode=nonstrict;
然后再次插入就可以了
查询:
hive> select * from u3;

OK

1       xm1     16      9       14

2       xm2     18      9       14

Time taken: 0.451 seconds, Fetched: 2 row(s)
hive分桶
分桶目的作用
* 更加细致地划分数据;对数据进行抽样查询,较为高效;可以使查询效率提高
* 记住,分桶比分区,更高的查询效率。
分桶原理关键字
* 分桶字段是表内字段,默认是对分桶的字段进行hash值,然后再模于总的桶数,得到的值则是分区桶数。每个桶中都有数据,但每个桶中的数据条数不一定相等。
bucket
clustered by(id) into 4 buckets
分桶的本质
* 在表目录或者分区目录中创建文件。
分桶案例
* 分四个桶
create table if not exists u4(id int, name string, age int) partitioned by(month int,day int)

clustered by(id) into 4 buckets row format delimited fields terminated by ' ' stored as textfile;
对分桶的数据不能使用load的方式加载数据,使用load方式加载不会报错,但是没有分桶的效果。
为分桶表添加数据,需要设置set hive.enforce.bucketing=true;
首先将数据添加到u2表中
 xm1

 xm2

 xm3

 xh4

 xh5

 xh6

 xh7

 xh8

 xh9
load data local inpath '/home/hadoop/tmp/u2.txt' into table u2 partition(month=9,day=14);
加载到桶表中:
from u2 insert into table u4 partition(month=,day=) select id,name,age where month = and day = ;
-- ::, Stage- map = %,  reduce = %

-- ::, Stage- map = %,  reduce = %, Cumulative CPU 0.85 sec

-- ::, Stage- map = %,  reduce = %, Cumulative CPU 1.95 sec

-- ::, Stage- map = %,  reduce = %, Cumulative CPU 3.21 sec

-- ::, Stage- map = %,  reduce = %, Cumulative CPU 4.35 sec

-- ::, Stage- map = %,  reduce = %, Cumulative CPU 5.35 sec

MapReduce Total cumulative CPU time:  seconds  msec

Ended Job = job_1554061731326_0001

Loading data to table db_hive.u4 partition (month=, day=)

MapReduce Jobs Launched:

Stage-Stage-: Map:   Reduce:    Cumulative CPU: 5.35 sec   HDFS Read:  HDFS Write:  SUCCESS

Total MapReduce CPU Time Spent:  seconds  msec
加载日志可以看到有:Map: 1 Reduce: 4
对分桶进行查询:tablesample(bucket x out of y on id)
* x:表示从哪个桶开始查询
* y:表示桶的总数,一般为桶的总数的倍数或者因子。
* x不能大于y。
hive> select * from u4;

OK

       xh8

       xh4

       xh9

       xh5

       xm1

       xh6

       xm2

       xh7

       xm3

Time taken: 0.148 seconds, Fetched:  row(s)
    > select * from u4 tablesample(bucket  out of  on id);

OK

       xh8

       xh4

Time taken: 0.149 seconds, Fetched:  row(s)

hive> select * from u4 tablesample(bucket  out of  on id);

OK

       xh9

       xh5

       xm1

Time taken: 0.069 seconds, Fetched:  row(s)

hive> select * from u4 tablesample(bucket  out of  on id);

OK

       xh8

       xh4

       xh6

       xm2

Time taken: 0.089 seconds, Fetched:  row(s)

hive> select * from u4 tablesample(bucket  out of  on id) where age > ;

OK

       xh8

Time taken: 0.075 seconds, Fetched:  row(s)
随机查询:
select * from u4 order by rand() limit 3;
OK
1 xm1 16 9 14
3 xm3 22 9 14
6 xh6 23 9 14
Time taken: 20.724 seconds, Fetched: 3 row(s) --走map reduce任务
    > select * from u4 tablesample( rows);

OK

       xh8

       xh4

       xh9

Time taken: 0.073 seconds, Fetched:  row(s)
hive> select * from u4 tablesample( percent);

OK

       xh8

       xh4

       xh9

Time taken: 0.058 seconds, Fetched:  row(s)
    > select * from u4 tablesample(3G);

OK

       xh8

       xh4

       xh9

       xh5

       xm1

       xh6

       xm2

       xh7

       xm3

Time taken: 0.069 seconds, Fetched:  row(s)
hive> select * from u4 tablesample(3K);

OK

       xh8

       xh4

       xh9

       xh5

       xm1

       xh6

       xm2

       xh7

       xm3

Time taken: 0.058 seconds, Fetched:  row(s)
* 分区与分桶的对比
* 分区使用表外的字段,分桶使用表内字段
* 分区可以使用load加载数据,而分桶就必须要使用insert into方式加载数据
* 分区常用;分桶少用
hive数据导入
* load从本地加载
* load从hdfs中加载
* insert into方式加载
* location指定
* like指定,克隆
* ctas语句指定(create table as)
* 手动将数据copy到表目录
hive数据导出
* insert into方式导出
* insert overwrite local directory:导出到本地某个目录
* insert overwrite directory:导出到hdfs某个目录
导出到文件
hive -S -e “use gp1801;select * from u2” > /home/out/02/result
Hadoop 上Hive 的操作的更多相关文章
- hadoop上hive的安装
1.前言 说明:安装hive前提是要先安装hadoop集群,并且hive只需要再hadoop的namenode节点集群里安装即可(需要再所有namenode上安装),可以不在datanode节点的机器 ...
- Hadoop上 Hive 操作
数据dept表的准备: --创建dept表 CREATE TABLE dept( deptno int, dname string, loc string) ROW FORMAT DELIMITED ...
- hadoop之hive高级操作
在输出结果较多,需要输出到文件中时,可以在hive CLI之外执行hive -e "sql" > output.txt操作 但当SQL语句太长或太多时,这种方式不是很方便,可 ...
- hadoop集群配置和在windows系统上运用java操作hdfs
安装 配置 概念 hadoop常用shell命令 使用java操作hadoop 本文介绍hadoop集群配置和在windows系统上运用java操作hdfs 安装 http://mirror.bit. ...
- 初识Hadoop、Hive
2016.10.13 20:28 很久没有写随笔了,自打小宝出生后就没有写过新的文章.数次来到博客园,想开始新的学习历程,总是被各种琐事中断.一方面确实是最近的项目工作比较忙,各个集群频繁地上线加多版 ...
- Hadoop之Hive篇
想了解Hadoop整体结构及各框架角色建议飞入这篇文章,写的很好:http://www.open-open.com/lib/view/open1385685943484.html .以下文章是本人参考 ...
- 大数据技术生态圈形象比喻(Hadoop、Hive、Spark 关系)
[摘要] 知乎上一篇很不错的科普文章,介绍大数据技术生态圈(Hadoop.Hive.Spark )的关系. 链接地址:https://www.zhihu.com/question/27974418 [ ...
- hadoop记录-hive常见设置
分区表 set hive.exec.dynamic.partition=true; set hive.exec.dynamic.partition.mode=nonstrict;create tabl ...
- HIVE简单操作
1.hive命令登录HIVE数据库后,执行show databases;命令可以看到hive数据库中有一个默认的default数据库. [root@hadoop hive]# hive Logging ...
随机推荐
- HAproxy负载均衡-ACL篇
ACL定制法则: 开放策略:拒绝所有,只开放已知 拒绝策略:允许所有,只拒绝某些 事实上实现安全策略,无非也就是以上两种方法 redirect 参考:http://cbonte.github.io/h ...
- jsp细节------<base>
1:jsp一般都有这个<base href="<%=basePath%>">,它的作用一般用不到,但在使用java框架用注解时会用. 如下代码(xxx.js ...
- Linux系统管理_主题02 :管好文件(1)_2.1 切换、创建和删除目录_cd_mkdir_rmdir
用法:cd [目录路径] 变换工作目录至制定目录路径,若[目录路径]参数省略则变换至使用者的 家目录, 其中[目录路径]可为绝对路径或相对路径 另外 "~" 在 Bash 中表示当 ...
- Linux下高cpu解决方案(转载)
Linux下高cpu解决方案(转载 1.用top命令查看哪个进程占用CPU高gateway网关进程14094占用CPU高达891%,这个数值是进程内各个线程占用CPU的累加值. PID USER ...
- 《精通并发与Netty》学习笔记(05 - Google Protobuf与Netty的结合)
protobuf是由Google开发的一套对数据结构进行序列化的方法,可用做通信协议,数据存储格式,等等.其特点是不限语言.不限平台.扩展性强 Netty也提供了对Protobuf的天然支持,我们今天 ...
- CRLF注入漏洞
CRLF是“回车+换行”(\r\n,%0d%0a)的简称. HTTP协议中,HTTP Header之间以一个CRLF分隔,Header与Body以两个CRLF分隔.URL重定向通常通过响应头中的Loc ...
- prometheus 监控 zookeeper
1.zookeeper的规则 [root@do1cloud01 prometheus]# cat zookeeper.yml rules: - pattern: "org.apache.Zo ...
- English 邮件
1.email http://www2.elc.polyu.edu.hk/cill/eiw/e-mail.htm
- Linux文件权限基础知识
一.文件权限概述 Linux中每个文件或目录都有一组一组9个基础权限位,每三位字符被分为一组,他们分别是属主权限位(占三个字符).用户组权限位(占三个字符).其他用户权限位(占三个字符).比如rwxr ...
- ssm框架的小总结
一.mybatis框架 mybatis框架主要就是完成持久层的实现,简化了持久层的开发, 1.首先是配置文件的编写,我们这里就命名为mybatis-config.xml,先配置文件头,然后加载连接数据 ...