
UVa 1592 Database(巧用map)
Peter studies the theory of relational databases. Table in the relational database consists of values that are arranged in rows and columns.
There are different normal forms that database may adhere to. Normal forms are designed to minimize the redundancy of data in the database. For example, a database table for a library might have a row for each book and columns for book name, book author, and author's email.
If the same author wrote several books, then this representation is clearly redundant. To formally define this kind of redundancy Peter has introduced his own normal form. A table is in Peter's Normal Form (PNF) if and only if there is no pair of rows and a pair of columns such that the values in the corresponding columns are the same for both rows.
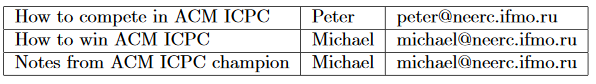
The above table is clearly not in PNF, since values for 2rd and 3rd columns repeat in 2nd and 3rd rows. However, if we introduce unique author identifier and split this table into two tables -- one containing book name and author id, and the other containing book id, author name, and author email, then both resulting tables will be in PNF.
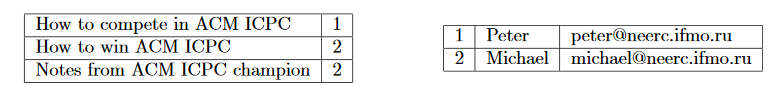
Given a table your task is to figure out whether it is in PNF or not.
Input
Input contains several datasets. The first line of each dataset contains two integer numbers n and m ( 1≤n≤10000, 1≤m≤10), the number of rows and columns in the table. The following n lines contain table rows. Each row has m column values separated by commas. Column values consist of ASCII characters from space (ASCII code 32) to tilde (ASCII code 126) with the exception of comma (ASCII code 44). Values are not empty and have no leading and trailing spaces. Each row has at most 80 characters (including separating commas).
Output
For each dataset, if the table is in PNF write to the output file a single word `` YES" (without quotes). If the table is not in PNF, then write three lines. On the first line write a single word `` NO" (without quotes). On the second line write two integer row numbers r1 and r2 ( 1≤r1,r2≤n, r1≠r2), on the third line write two integer column numbers c1 and c2 ( 1≤c1, c2≤m, c1≠c2), so that values in columns c1 and c2 are the same in rows r1 and r2.
Sample Input
3 3
How to compete in ACM ICPC,Peter,peter@neerc.ifmo.ru
How to win ACM ICPC,Michael,michael@neerc.ifmo.ru
Notes from ACM ICPC champion,Michael,michael@neerc.ifmo.ru
2 3
1,Peter,peter@neerc.ifmo.ru
2,Michael,michael@neerc.ifmo.ru
Sample Output
NO
2 3
2 3
YES
题意
给一个数据库,查找是否存在一组(r1行,c1列)=(r2行,c1列) && (r1行,c2列)=(r2行,c2列),即:不同的二行,对应二列字符串相同
题解
这里先用map<string,int>把字符串映射成一个值方便后面查找是否相同(如果找字符串,不断比较,TLE预定)
然后可以map<pair<int,int>,int>把r1行的两个点的值映射成r1,这样再往下循环的时候,如果r2的两个点的值在map里出现过,就OK了(用O(n)避免暴力循环O(n^2))
代码
 #include<bits/stdc++.h>

 using namespace std;

 int Map[][];

 int main()

 {

     int n,m;

     while(cin>>n>>m)

     {

         getchar();

         map<string,int> ma;

         int cnt=;

         for(int i=;i<=n;i++)

         {

             string s,ss;

             getline(cin,ss);

             int k=,Len=ss.size();

             for(int j=;j<=Len;j++)

             {

                 if(j==Len||ss[j]==',')

                 {

                     if(ma[s]==)

                         ma[s]=cnt++;

                     Map[i][k++]=ma[s];

                     s.clear();

                 }

                 else

                     s+=ss[j];

             }

         }

         int F=;

         for(int j=;j<=m;j++)//c1

         {

             for(int jj=j+;jj<=m;jj++)//c2

             {

                 map<pair<int,int>,int> Ma;//把r1的两个点映射成r1

                 for(int i=;i<=n;i++)//r2

                 {

                     if(Ma[make_pair(Map[i][j],Map[i][jj])]==)//r1

                         Ma[make_pair(Map[i][j],Map[i][jj])]=i;

                     else

                     {

                         F=;

                         printf("NO\n%d %d\n%d %d\n",Ma[make_pair(Map[i][j],Map[i][jj])],i,j,jj);

                         break;

                     }

                 }

                 if(F)break;

             }

             if(F)break;

         }

         if(F==)

             cout<<"YES"<<endl;

     }

     return ;

 }
UVa 1592 Database(巧用map)的更多相关文章
- UVA - 1592 Database 枚举+map
思路 直接枚举两列,然后枚举每一行用map依次记录每对字符串出现的是否出现过(字符串最好先处理成数字,这样会更快),如果出现就是"NO",否则就是"YES". ...
- UVa 1592 Database (map)
题意:给出n行m列的数据库(数据范围: n 1~10000, m 1~10), 问你能不能找出两行r1, r2,使得这两行中的c1, c2列是一样的, 即(r1,c1)==(r2,c1) && ...
- UVA 1592 DataBase
思路: 知识补充: ①make_pair和pair: /*pair是将2个数据组合成一个数据,当需要这样的需求时就可以使用pair,如stl中的map就是将key和value放在一起来保存.另一个应用 ...
- UVa - 1592 Database(STL,优化)
给一个n行m列的数据库表格,问有没有两个行 r1,r2 和 c1,c2,满足(r1,r2)的元素=(c1,c2)的元素. n≤10000,m≤10. 直接枚举4个肯定会T的.可以只枚举c1 c2,然后 ...
- uva 1592 Database (STL)
题意: 给出n行m列共n*m个字符串,问有没有在不同行r1,r2,有不同列c1,c2相同.即(r1,c1) = (r2,c1);(r1,c2) = (r2,c2); 如 2 3 123,456,789 ...
- 巧用map解决nginx的Location里if失效问题
需求: Nginx根据参数来输出不同的header 我们想用Nginx来判断一些通用的参数, 根据参数情况在输出中不同的header, 或者cookie, 那么根据正常思路, 有如下配置: locat ...
- Database UVA - 1592
对于每组数据,首先通过一个map将每个字符串由一个数字代替,相同的字符串由相同数字代替,不同的字符串由不同数字代替.那么题目就变为了询问是否存在行r1,r2以及列c1,c2使得str[r1][c1]= ...
- 【例题5-9 UVA - 1592】Database
[链接] 我是链接,点我呀:) [题意] 在这里输入题意 [题解] 枚举不同的列是哪两个列,然后枚举行. 把那一行的这两列的字符接在一起,然后用map判重. 为了防止逐个比较字符. 可以一开始先把字符 ...
- UVa 1592 数据库(c++pair)
Input Input contains several datasets. The first line of each dataset contains two integer numbersn ...
随机推荐
- word2vec剖析,资料整理备存
声明:word2vec剖析,资料整理备存,以下资料均为转载,膜拜大神,仅作学术交流之用. word2vec是google最新发布的深度学习工具,它利用神经网络将单词映射到低维连续实数空间,又称为单词嵌 ...
- AWS CLI以及AWS S3 SYNC命令行使用
1.到AWS的IAM创建用户,并且获取到访问密钥 ID 和私有访问密钥.下载密钥并保存. 2.到http://docs.amazonaws.cn/cli/latest/userguide/instal ...
- JDK1.5多线程提高
1.名词: 1.任务的执行与任务的提交解耦 2.任务的执行策略-可中断,取消 2.线程封闭机制: 针对单线程池而言,提高任务执行的速度,但是无需锁定 3.饥饿死锁: 任务长期得不到执行,其实就是形成闭 ...
- Hadoop使用场景
Hadoop使用场景: 大数据量存储:分布式存储 日志处理: Hadoop擅长这个 海量计算: 并行计算 ETL:数据抽取到oracle.mysql.DB2.mongdb及主流数据库 使用HBase做 ...
- case功能菜单选项
脚本aim; 实现如下功能菜单并实现相应的功能;同在之前公司的一个游戏控制脚本; 1),显示当前时间; 2),显示cpu负载 3),显示剩余内存 0),退出脚本 如图菜单界面
- 解决maven工程 子工程中的一些配置读取进来的问题
方案:在父工程中手动配置一些节点 <build> <!-- 插件 --> <plugins> <plugin> <groupId>org.a ...
- maven下载与配置
转自:https://www.cnblogs.com/jdys/p/3770534.html 1.访问官网:从maven官网下载maven http://maven.apache.org/downlo ...
- 未能同步 iPhone XXX,因为这台电脑不再被授权使用在此iPhone上购买的项目。
打包生成的ipa文件,安装到手机上,p12和ppf证书都正确,手机的udid也正确.用itunes安装到手机报错. 未能同步 iPhone XXX,因为这台电脑不再被授权使用在此iPhone上购买的项 ...
- WebService 服务端客户端 实例 HTTPRIO (一) SOAP WSDL
Delphi中WebService包含的组件解释(有7个) (1) THTTPRIO-------:使用Http消息来调用远程使用SOAP的接口对象 (2) THTTPReqResp- ...
- Spring mvc 返回json包含双引号问题 解决
解决方式1: @RequestMapping(value="/shopsList.json", produces = "text/html;charset=UTF-8&q ...