
.Net HttpWebRequest 爬虫核心爬取
1 爬虫,爬虫攻防
2 下载html
3 xpath解析html,获取数据和深度抓取(和正则匹配)
4 多线程抓取
熟悉http协议
提供两个方法Post和Get
public static string HttpGet(string url, Encoding encoding = null,  Dictionary<string,string> headDic=null)

        {

            string html = string.Empty;

            try

            {

                HttpWebRequest request = HttpWebRequest.Create(url) as HttpWebRequest;//模拟请求

                request.Timeout =  * ;

                request.UserAgent = "Mozilla/5.0 (Windows NT 10.0; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.106 Safari/537.36";

                request.ContentType = "text/html; charset=utf-8";

                if (headDic != null)

                {

                    foreach (var item in headDic)

                    {

                        request.Headers.Add(item.Key, item.Value);

                    }

                }

                if(encoding==null)

                    encoding = Encoding.UTF8; // 如果是乱码就改成 utf-8 / GB2312

                else

                    encoding=Encoding.GetEncoding("GB2312");

                using (HttpWebResponse response = request.GetResponse() as HttpWebResponse)

                {

                    if (response.StatusCode != HttpStatusCode.OK)

                    {

                        log.Warn(string.Format("抓取{0}地址返回失败,response.StatusCode为{1}", url, response.StatusCode));

                    }

                    else

                    {

                        try

                        {

                            StreamReader sr = new StreamReader(response.GetResponseStream(), encoding);

                            html = sr.ReadToEnd();//读取数据

                            sr.Close();

                        }

                        catch (Exception ex)

                        {

                            log.Error(string.Format("DownloadHtml抓取{0}保存失败", url), ex);

                            html = null;

                        }

                    }

                }

            }

            catch (WebException ex)

            {

                if (ex.Message.Equals("远程服务器返回错误: (306)。"))

                {

                    log.Error("远程服务器返回错误: (306)。", ex);

                    return null;

                }

            }

            catch (Exception ex)

            {

                log.Error(string.Format("DownloadHtml抓取{0}出现异常", url), ex);

                html = null;

            }

            return html;

        }
        /// <summary>

        /// Post 调用借口

        /// </summary>

        /// <param name="url">接口地址</param>

        /// <param name="value">接口参数</param>

        /// <returns></returns>

        public static string HttpPost(string url, string value)

        {

            string param = value;

            Stream stream = null;

            byte[] postData = Encoding.UTF8.GetBytes(param);

            try

            {

                HttpWebRequest myRequest = (HttpWebRequest)WebRequest.Create(url);

                myRequest.Method = "POST";

                myRequest.ContentType = "application/x-www-form-urlencoded";

                myRequest.ContentLength = postData.Length;

                stream = myRequest.GetRequestStream();

                stream.Write(postData, , postData.Length);

                HttpWebResponse myResponse = (HttpWebResponse)myRequest.GetResponse();

                if (myResponse.StatusCode == HttpStatusCode.OK)

                {

                    StreamReader sr = new StreamReader(myResponse.GetResponseStream(), Encoding.UTF8);

                    string rs = sr.ReadToEnd().Trim();

                    sr.Close();

                    return rs;

                }

                else

                {

                    return "失败:Status:" + myResponse.StatusCode.ToString();

                }

            }

            catch (Exception ex)

            {

                return "失败:ex:" + ex.ToString();

            }

            finally

            {

                if (stream != null)

                {

                    stream.Close();

                    stream.Dispose();

                }

            }

        }
下载Html
StreamWriter sw = new StreamWriter("路径.txt", true, Encoding.GetEncoding("utf-8"));

sw.Write("爬取的html字符串");

sw.Close();
xpath
http://www.cnblogs.com/zhaozhan/archive/2009/09/09/1563617.html
http://www.cnblogs.com/zhaozhan/archive/2009/09/09/1563679.html
http://www.cnblogs.com/zhaozhan/archive/2009/09/10/1563703.html
正则匹配
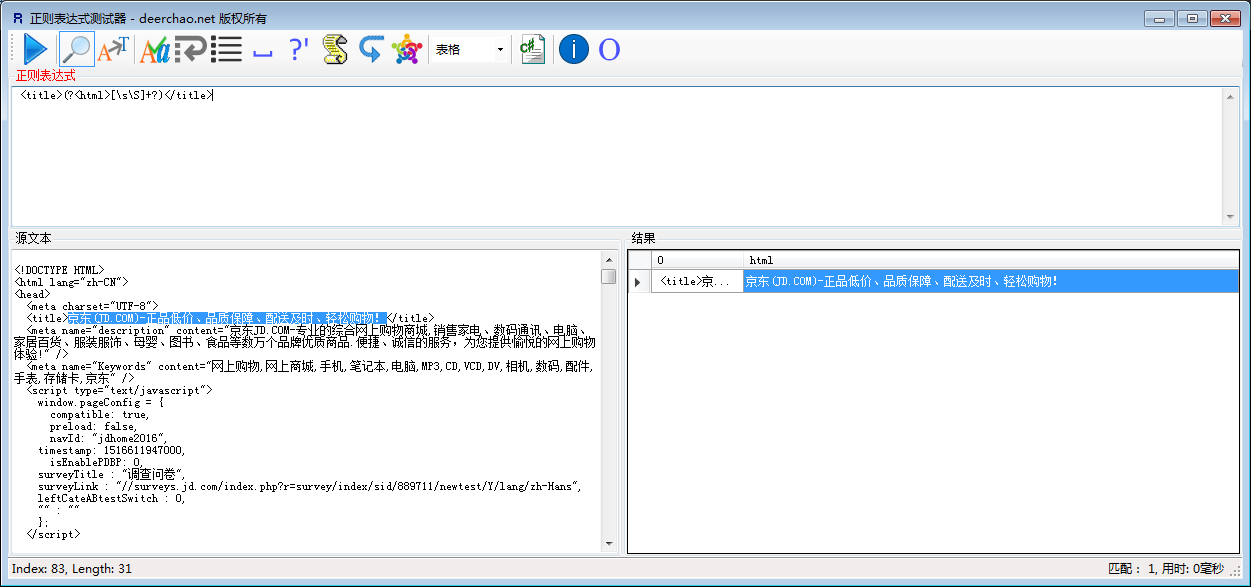
目前使用起来最好用的正则
<title>(?<html>[\s\S]+?)</title> 意思是匹配 <title> *********</title>标签里面的任意字符串
Regex reTitle = new Regex(@"<title>(?<html>[\s\S]+?)</title>"/>");

string title = reTitle.Match(html).Groups["html"].Value;
多个选择
Regex rgInfo = new Regex(@"<td align=""left"">(?<company>[^<>]+)</td><td align=""center"">(?<id>[\dA-Z]+)</td><td align=""center"">(?<cat>[^<>]+)</td><td align=""center"">(?<grade>[A-Z]+)</td><td align=""center"">(?<date>[^\s&]*)");
MatchCollection mchInfos = rgInfo.Matches(strHtml);
foreach (Match m in mchInfos)
{
string strCompany = m.Groups["company"].Value;
string strId = m.Groups["id"].Value;
string strCat = m.Groups["cat"].Value.Replace(" ", "");
string grade = m.Groups["grade"].Value;
string date = m.Groups["date"].Value;
}
多线程
List<Task> taskList = new List<Task>();

TaskFactory taskFactory = new TaskFactory();

for(int i=;i<;i++)

{

   taskList.Add(taskFactory.StartNew(Crawler));//将一个执行Crawler方法的线程放到集合里面,创建并启动 任务

   if (taskList.Count > ) //线程池启动15个线程

   {

        taskList = taskList.Where(t => !t.IsCompleted && !t.IsCanceled && !t.IsFaulted).ToList();

        Task.WaitAny(taskList.ToArray());//有线程执行完毕

    }

}

Task.WaitAll(taskList.ToArray());//100个线程全部执行完成

Console.WriteLine("抓取全部完成 - -", DateTime.Now);
该文档只是自己记录,纯属记事本
.Net HttpWebRequest 爬虫核心爬取的更多相关文章
- 使用htmlparse爬虫技术爬取电影网页的全部下载链接
昨天,我们利用webcollector爬虫技术爬取了网易云音乐17万多首歌曲,而且还包括付费的在内,如果时间允许的话,可以获取更多的音乐下来,当然,也有小伙伴留言说这样会降低国人的知识产权保护意识,诚 ...
- [Python爬虫] Selenium爬取新浪微博客户端用户信息、热点话题及评论 (上)
转载自:http://blog.csdn.net/eastmount/article/details/51231852 一. 文章介绍 源码下载地址:http://download.csdn.net/ ...
- scrapy进阶(CrawlSpider爬虫__爬取整站小说)
# -*- coding: utf-8 -*- import scrapy,re from scrapy.linkextractors import LinkExtractor from scrapy ...
- 使用htmlparser爬虫技术爬取电影网页的全部下载链接
昨天,我们利用webcollector爬虫技术爬取了网易云音乐17万多首歌曲,而且还包括付费的在内,如果时间允许的话,可以获取更多的音乐下来,当然,也有小伙伴留言说这样会降低国人的知识产权保护意识,诚 ...
- scrapy-redis实现爬虫分布式爬取分析与实现
本文链接:http://blog.csdn.net/u012150179/article/details/38091411 一 scrapy-redis实现分布式爬取分析 所谓的scrapy-redi ...
- 网络爬虫之定向爬虫:爬取当当网2015年图书销售排行榜信息(Crawler)
做了个爬虫,爬取当当网--2015年图书销售排行榜 TOP500 爬取的基本思想是:通过浏览网页,列出你所想要获取的信息,然后通过浏览网页的源码和检查(这里用的是chrome)来获相关信息的节点,最后 ...
- python 爬虫之爬取大街网(思路)
由于需要,本人需要对大街网招聘信息进行分析,故写了个爬虫进行爬取.这里我将记录一下,本人爬取大街网的思路. 附:爬取得数据仅供自己分析所用,并未用作其它用途. 附:本篇适合有一定 爬虫基础 crawl ...
- Python爬虫之爬取慕课网课程评分
BS是什么? BeautifulSoup是一个基于标签的文本解析工具.可以根据标签提取想要的内容,很适合处理html和xml这类语言文本.如果你希望了解更多关于BS的介绍和用法,请看Beautiful ...
- python爬虫项目-爬取雪球网金融数据(关注、持续更新)
(一)python金融数据爬虫项目 爬取目标:雪球网(起始url:https://xueqiu.com/hq#exchange=CN&firstName=1&secondName=1_ ...
随机推荐
- mysql系列之8.mysql高可用 (mha4mysql)
环境: 三台机器 主服务器: 192.168.1.130 主备机器: 192.168.1.131 监控机器: 192.168.1.132 130和131, 是mysql双主架构 1.在三台机器上安装m ...
- Hadoop实战-Flume之Source multiplexing(十五)
a1.sources = r1 a1.sinks = k1 k2 a1.channels = c1 c2 # Describe/configure the source a1.sources.r1.t ...
- 去ioe
http://baike.baidu.com/link?url=ntILcQyM_S7rpsbUrVu7vLEKHXNfSlJyWdWQnUo9LYO7JfoOpDEvbKldXobL0_nUEkXn ...
- html乱码怎问题
大家会不会常常遇到中文乱码的情况?html中文乱码问题该怎么调? <标签名 lang=lang> - 指定语言种类 lang 属性能够指定标签范围内的元素的语言种类. 英语lang=&qu ...
- mysql中Incorrect string value乱码问题解决方案
mysql中Incorrect string value乱码问题解决方案 你是否遇到过类似以下错误? java.sql.SQLException: Incorrect string value: ...
- ios点击链接直接跳转到 App Store 指定应用下载页面
//跳转到应用页面 NSString *str = [NSString stringWithFormat:@"http://itunes.apple.com/us/app/id%d&quo ...
- Automator 实例:使用快捷键 实现 快速在当前路径 打开 iTerm
1. 在 finder -> 应用程序 或 通过 Spotlight 打开:Automator.app 2. 选择新建 “服务” 3. 设置服务,见下图,设置完成之后,command + s 保 ...
- YYYY-mm-dd HH:MM:SS 备忘录
d 月中的某一天.一位数的日期没有前导零. dd 月中的某一天.一位数的日期有一个前导零. ddd 周中某天的缩写名称,在 AbbreviatedDayNames 中定义. dddd 周中某天的完整名 ...
- codeforces 659D D. Bicycle Race(水题)
题目链接: D. Bicycle Race time limit per test 1 second memory limit per test 256 megabytes input standar ...
- Ubuntu 16.04上编译SkyEye的测试程序
一.首先确保Ubuntu系统上已经安装了Skyeye.skyeye-testsuite和arm-linux-gcc交叉编译工具链,如果没有安装请参考: 1.Skyeye的安装:http://www.c ...