
Python: Pandas的DataFrame如何按指定list排序
本文首发于微信公众号“Python数据之道”(ID:PyDataRoad)
前言
写这篇文章的起由是有一天微信上一位朋友问到一个问题,问题大体意思概述如下:
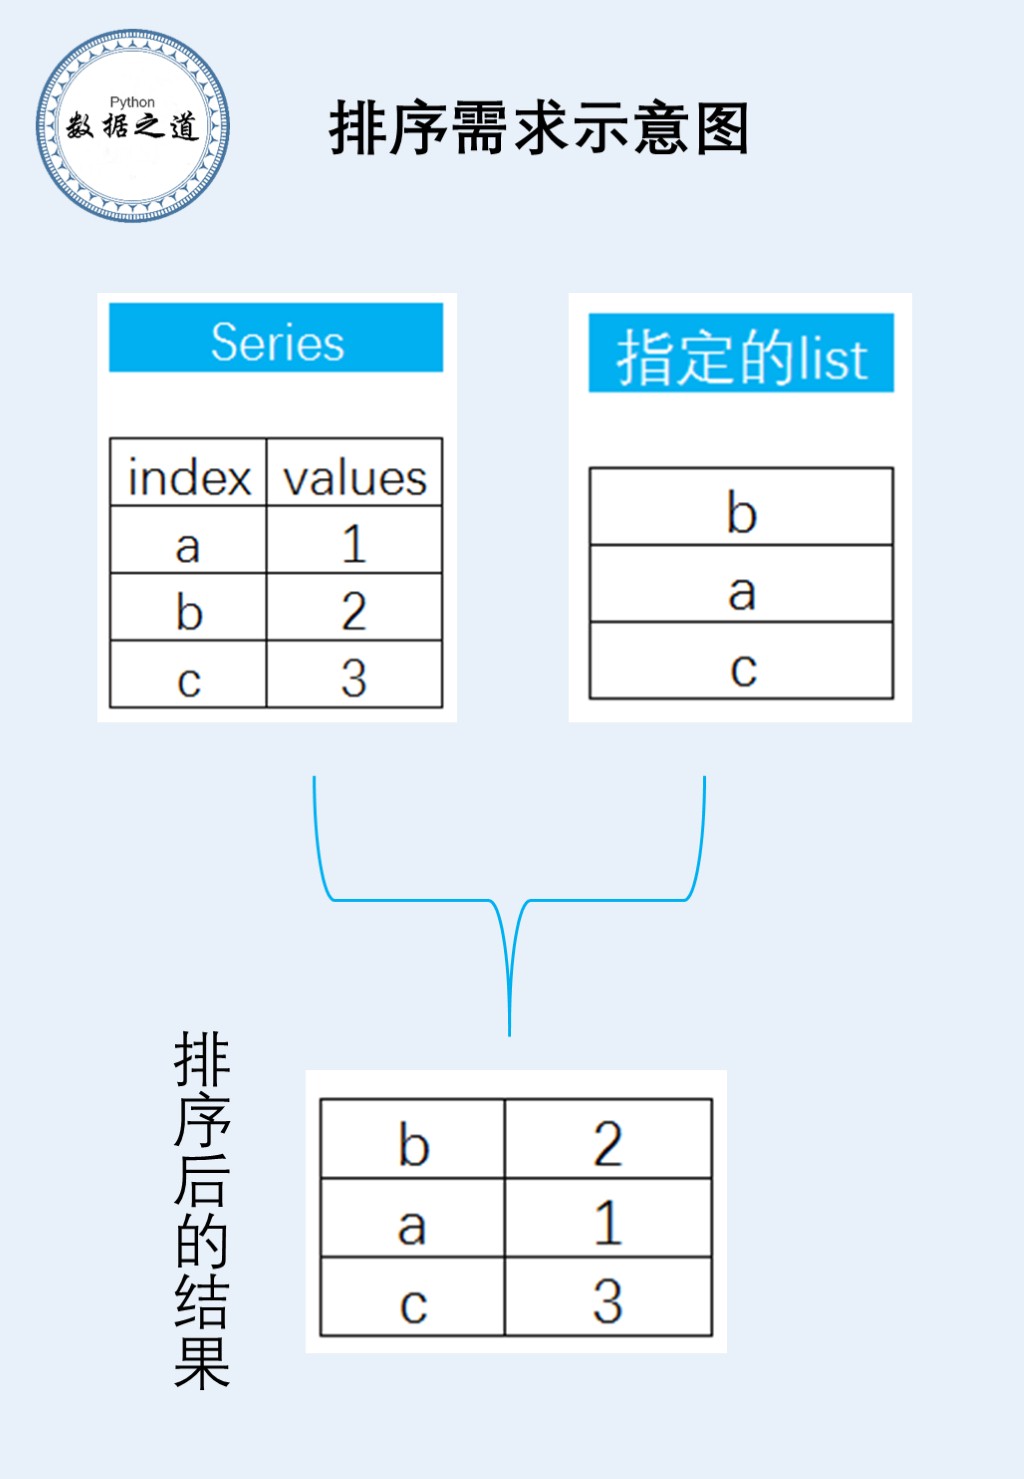
现在有一个pandas的Series和一个python的list,想让Series按指定的list进行排序,如何实现?
这个问题的需求用流程图描述如下:
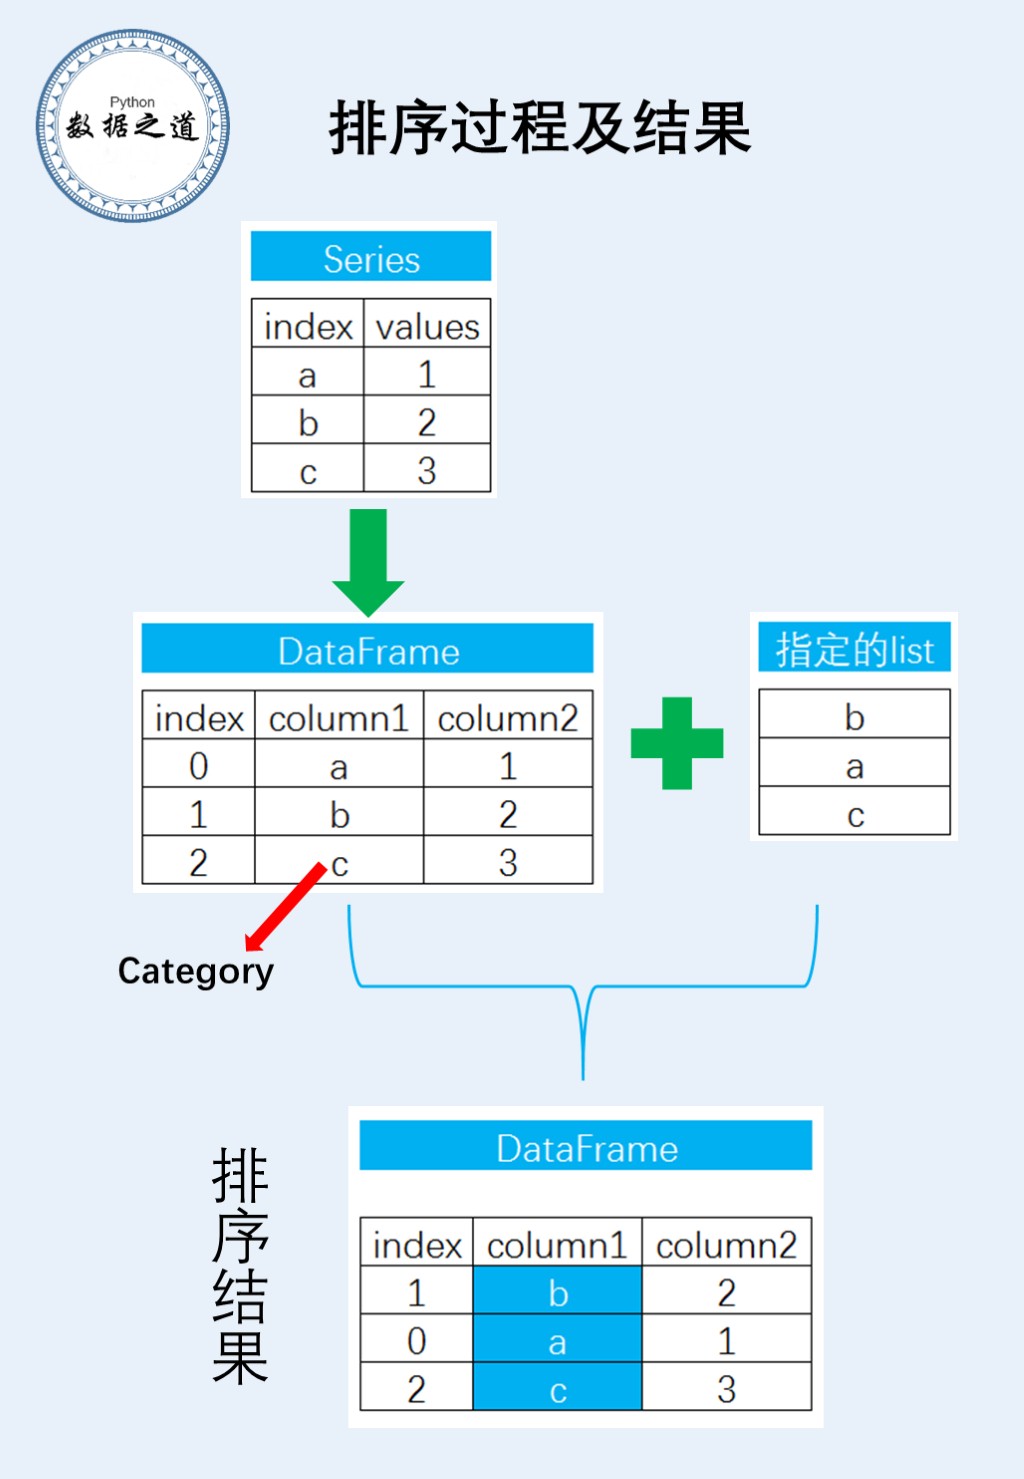
我思考了一下,这个问题解决的核心是引入pandas的数据类型“category”,从而进行排序。
在具体的分析过程中,先将pandas的Series转换成为DataFrame,然后设置数据类型,再进行排序。思路用流程图表示如下:
分析过程
- 引入pandas库
import pandas as pd
- 构造Series数据
s = pd.Series({'a':1,'b':2,'c':3})

s
a    1

b    2

c    3

dtype: int64
s.index
Index(['a', 'b', 'c'], dtype='object')
- 指定的list,后续按指定list的元素顺序进行排序
list_custom = ['b', 'a', 'c']

list_custom
['b', 'a', 'c']
- 将Series转换成DataFrame
df = pd.DataFrame(s)

df = df.reset_index()

df.columns = ['words', 'number']

df
| words | number | |
|---|---|---|
| 0 | a | 1 |
| 1 | b | 2 |
| 2 | c | 3 |
设置成“category”数据类型
# 设置成“category”数据类型

df['words'] = df['words'].astype('category')
# inplace = True,使 recorder_categories生效

df['words'].cat.reorder_categories(list_custom, inplace=True)

# inplace = True,使 df生效

df.sort_values('words', inplace=True)

df
| words | number | |
|---|---|---|
| 1 | b | 2 |
| 0 | a | 1 |
| 2 | c | 3 |
指定list元素多的情况:
若指定的list所包含元素比Dataframe中需要排序的列的元素多,怎么办?
- reorder_catgories()方法不能继续使用,因为该方法使用时要求新的categories和dataframe中的categories的元素个数和内容必须一致,只是顺序不同。
- 这种情况下,可以使用 set_categories()方法来实现。新的list可以比dataframe中元素多。
list_custom_new = ['d', 'c', 'b','a','e']

dict_new = {'e':1, 'b':2, 'c':3}

df_new = pd.DataFrame(list(dict_new.items()), columns=['words', 'value'])

print(list_custom_new)

df_new.sort_values('words', inplace=True)

df_new
['d', 'c', 'b', 'a', 'e']
| words | value | |
|---|---|---|
| 0 | b | 2 |
| 1 | c | 3 |
| 2 | e | 1 |
df_new['words'] = df_new['words'].astype('category')

# inplace = True,使 set_categories生效

df_new['words'].cat.set_categories(list_custom_new, inplace=True)

df_new.sort_values('words', ascending=True)
| words | value | |
|---|---|---|
| 1 | c | 3 |
| 0 | b | 2 |
| 2 | e | 1 |
指定list元素少的情况:
若指定的list所包含元素比Dataframe中需要排序的列的元素少,怎么办?
- 这种情况下,set_categories()方法还是可以使用的,只是没有的元素会以NaN表示
注意下面的list中没有元素“b”
list_custom_new = ['d', 'c','a','e']

dict_new = {'e':1, 'b':2, 'c':3}

df_new = pd.DataFrame(list(dict_new.items()), columns=['words', 'value'])

print(list_custom_new)

df_new.sort_values('words', inplace=True)

df_new
['d', 'c', 'a', 'e']
| words | value | |
|---|---|---|
| 0 | b | 2 |
| 1 | c | 3 |
| 2 | e | 1 |
df_new['words'] = df_new['words'].astype('category')

# inplace = True,使 set_categories生效

df_new['words'].cat.set_categories(list_custom_new, inplace=True)

df_new.sort_values('words', ascending=True)
| words | value | |
|---|---|---|
| 0 | NaN | 2 |
| 1 | c | 3 |
| 2 | e | 1 |
总结
根据指定的list所包含元素比Dataframe中需要排序的列的元素的多或少,可以分为三种情况:
- 相等的情况下,可以使用 reorder_categories和 set_categories方法;
- list的元素比较多的情况下, 可以使用set_categories方法;
- list的元素比较少的情况下, 也可以使用set_categories方法,但list中没有的元素会在DataFrame中以NaN表示。
源代码
需要的童鞋可在微信公众号“Python数据之道”(ID:PyDataRoad)后台回复关键字获取视频,关键字如下:
“2017-025”(不含引号)
Python: Pandas的DataFrame如何按指定list排序的更多相关文章
- python. pandas(series,dataframe,index) method test
python. pandas(series,dataframe,index,reindex,csv file read and write) method test import pandas as ...
- python pandas.Series&&DataFrame&& set_index&reset_index
参考CookBook :http://pandas.pydata.org/pandas-docs/stable/cookbook.html Pandas set_index&reset_ind ...
- python pandas ---Series,DataFrame 创建方法,操作运算操作(赋值,sort,get,del,pop,insert,+,-,*,/)
pandas 是基于 Numpy 构建的含有更高级数据结构和工具的数据分析包 pandas 也是围绕着 Series 和 DataFrame 两个核心数据结构展开的, 导入如下: from panda ...
- 吴裕雄--天生自然python学习笔记:pandas模块DataFrame 数据的修改及排序
import pandas as pd datas = [[65,92,78,83,70], [90,72,76,93,56], [81,85,91,89,77], [79,53,47,94,80]] ...
- python基础:如何使用python pandas将DataFrame转换为dict
之前在知乎上看到有网友提问,如何将DataFrame转换为dict,专门研究了一下,pandas在0.21.0版本中是提供了这个方法的.下面一起学习一下,通过调用help方法,该方法只需传入一个参数, ...
- python学习笔记—DataFrame和Series的排序
更多大数据分析.建模等内容请关注公众号<bigdatamodeling> ################################### 排序 ################## ...
- python 数据处理学习pandas之DataFrame
请原谅没有一次写完,本文是自己学习过程中的记录,完善pandas的学习知识,对于现有网上资料的缺少和利用python进行数据分析这本书部分知识的过时,只好以记录的形势来写这篇文章.最如果后续工作定下来 ...
- oracle数据据 Python+Pandas 获取Oracle数据库并加入DataFrame
import pandas as pd import sys import imp imp.reload(sys) from sqlalchemy import create_engine impor ...
- 【跟着stackoverflow学Pandas】 - Adding new column to existing DataFrame in Python pandas - Pandas 添加列
最近做一个系列博客,跟着stackoverflow学Pandas. 以 pandas作为关键词,在stackoverflow中进行搜索,随后安照 votes 数目进行排序: https://stack ...
随机推荐
- Atom手动安装插件和模块的解决方案
最近开始使用Atom编辑器写作.为了预览带LaTeX公式的markdown文档,尝试安装插件markdown-preview-plus,但是总是失败.经过仔细查看错误输出和网上相关问答,发现尽管报错为 ...
- NodeJS 事件循环
Node.js 是单进程单线程应用程序,但是通过事件和回调支持并发,所以性能非常高. Node.js 的每一个 API 都是异步的,并作为一个独立线程运行,使用异步函数调用,并处理并发. Node.j ...
- bzoj1898 [Zjoi2005]沼泽鳄鱼
Description 潘塔纳尔沼泽地号称世界上最大的一块湿地,它地位于巴西中部马托格罗索州的南部地区.每当雨季来临,这里碧波荡漾.生机盎然,引来不少游客.为了让游玩更有情趣,人们在池塘的中央建设了几 ...
- 为什么说B+-tree比B 树更适合实际应用中操作系统的文件索引和数据库索引?
B树: B+树 1) B+-tree的磁盘读写代价更低 B+-tree的内部结点并没有指向关键字具体信息的指针.因此其内部结点相对B 树更小.如果把所有同一内部结点的关键字存放在同一盘块中,那么盘块所 ...
- (转载)Linux查看文件编码格式及文件编码转换
Linux查看文件编码格式及文件编码转换 时间:2011-04-08作者:woyoo分类:linux评论:0 我友分享: 新浪微博 腾讯微博 搜狐微博 网易微博 开心网 QQ空间 msn 如果你需要在 ...
- lightoj1336数论基础
#include<iostream> #include<cstdio> #include<cmath> #define ll long long using nam ...
- ESXi5.0误删除虚拟机还有办法恢复吗?答案是可以!
[数据恢复故障描述]故障的虚拟化系统是 ESXi5.0,连接了多个LUN,其中一个1T的LUN上跑有7 台虚拟机,均为Windows Server 2003,管理员因为其它原因误删除了一台虚拟机,此台 ...
- 原创-angularjs2不同组件间的通信
AngualrJs2官方方法是以@Input,@Output来实现组件间的相互传值,而且组件之间必须父子关系,下面给大家提供一个简单的方法,实现组件间的传值,不仅仅是父子组件,跨模块的组件也可以实现传 ...
- selenium 远程服务设置
第一步:将浏览器的安装地址以及浏览器的驱动地址添加到系统变量path中.浏览器只需要添加此浏览器exe文件所在的目录就可以,驱动需要添加完整的地址包括驱动本身XXX.exe. 第二步:需要安装jdk环 ...
- linux -- 个人笔记
##转自别人的博客 一般直接用tar命令打包很简单,直接使用 tar -zcvf test.tar.gz test 即可. 在很多时候,我们要对某一个目录打包,而这个目录下有几十个子目录和子文件,我们 ...