
《Enhanced LSTM for Natural Language Inference》(自然语言推理)
解决的问题
自然语言推理,判断a是否可以推理出b。简单讲就是判断2个句子ab是否有相同的含义。
方法
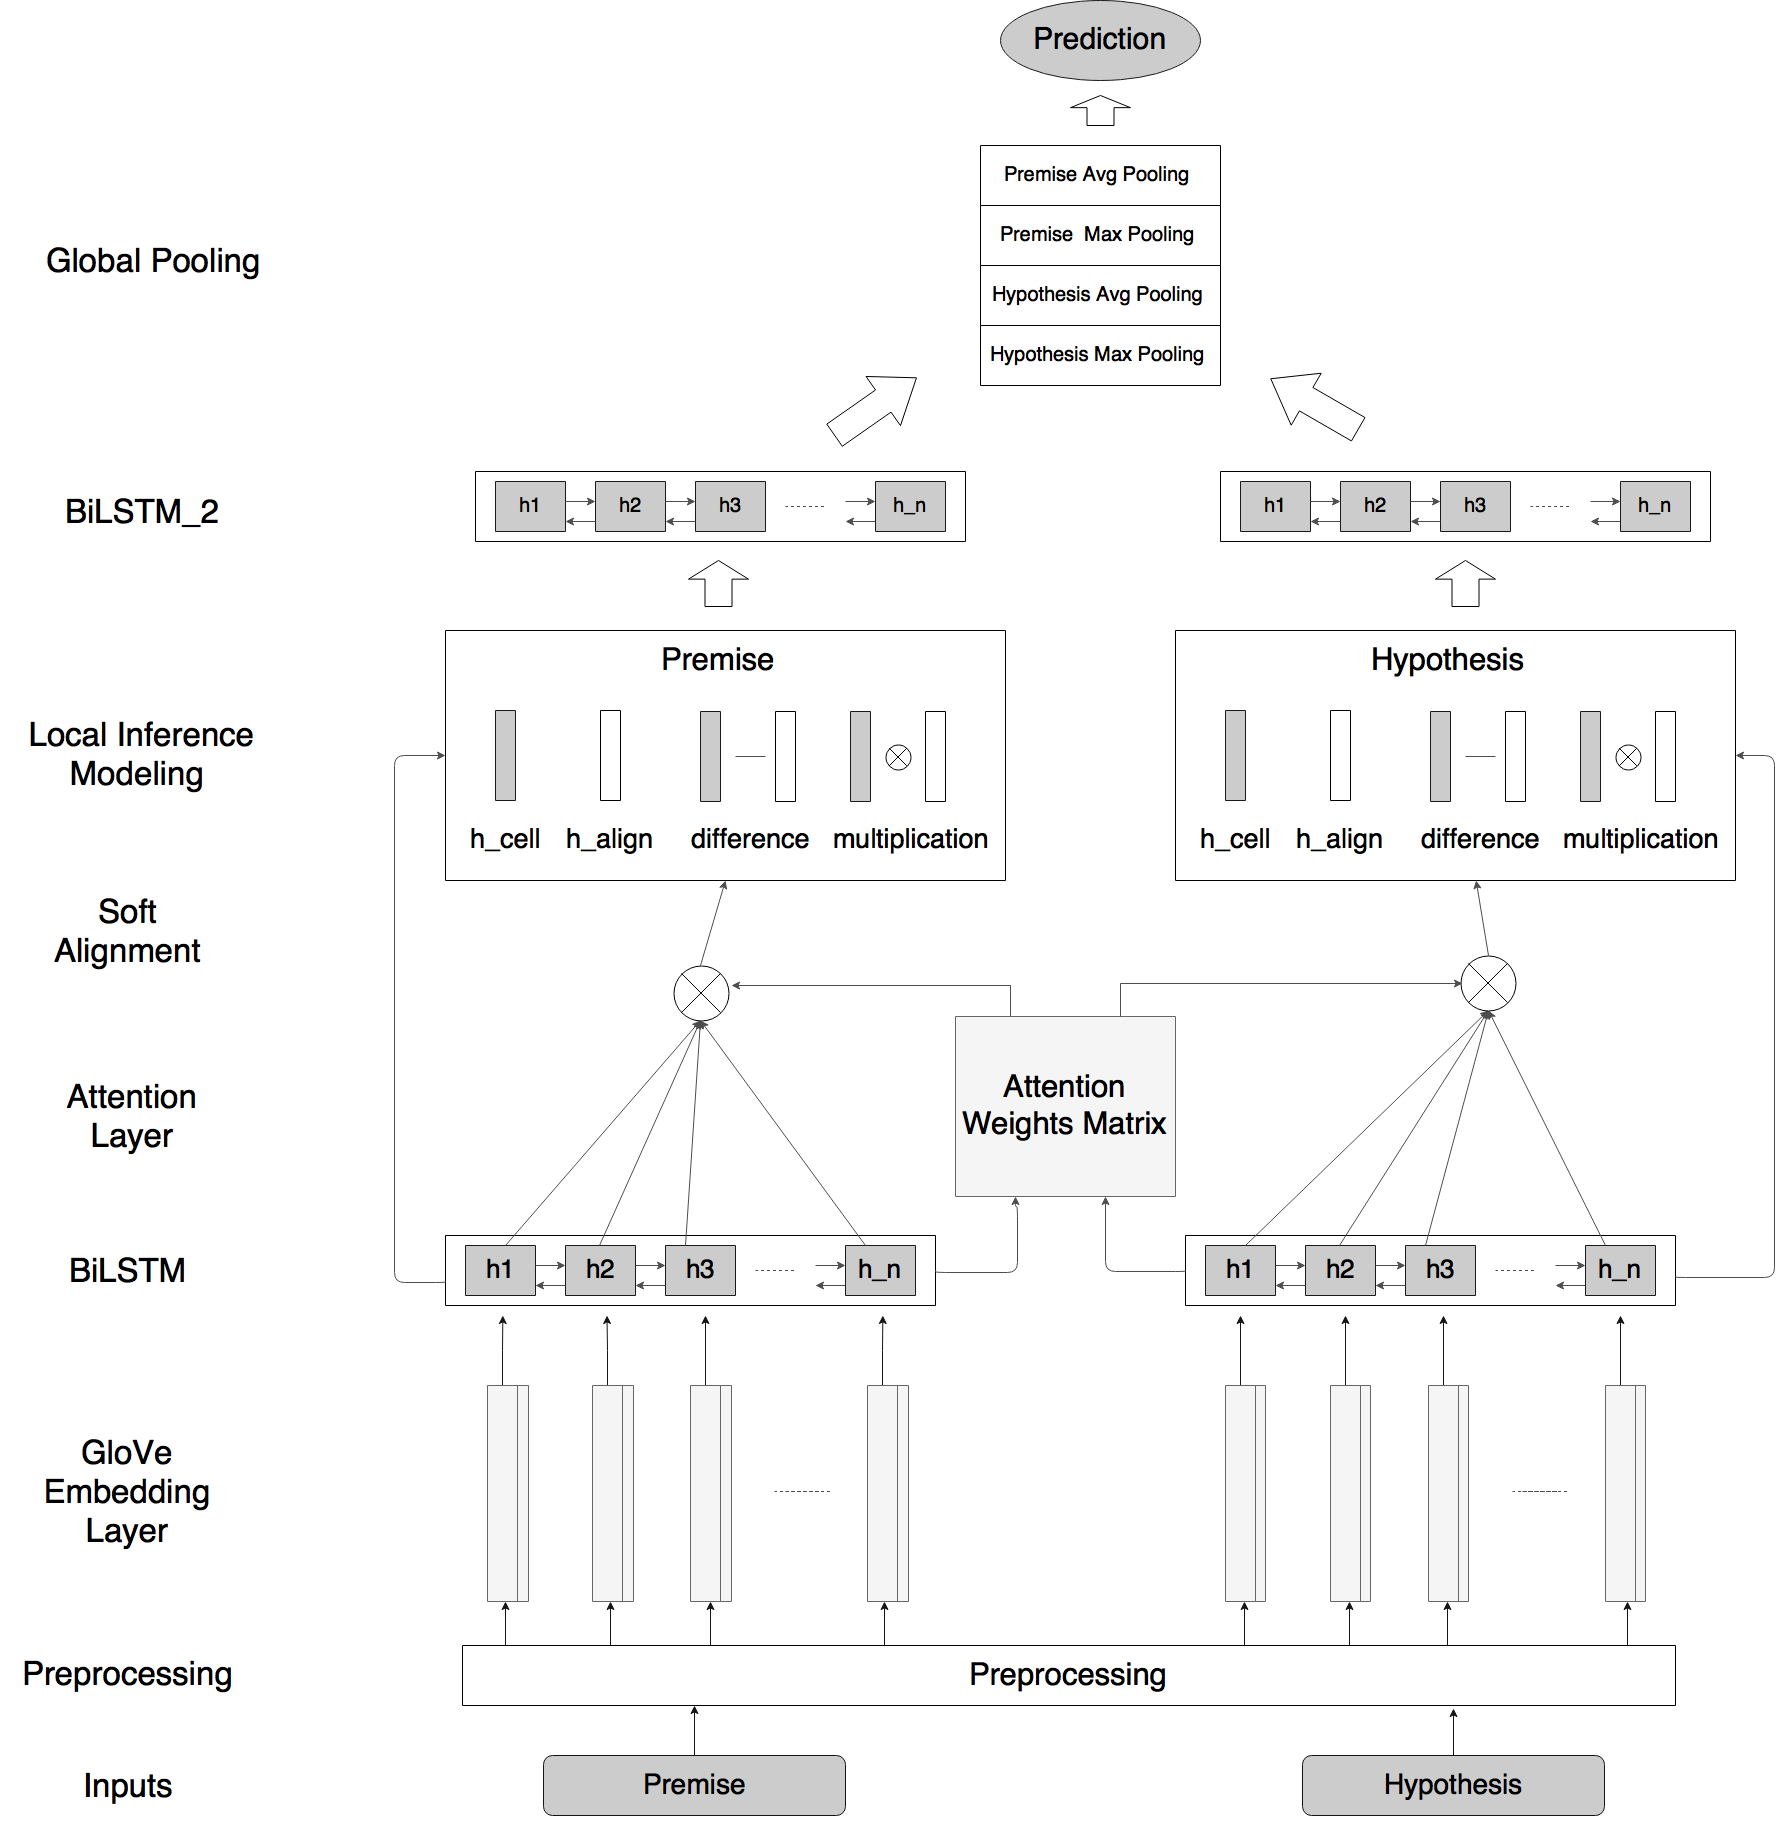
我们的自然语言推理网络由以下部分组成:输入编码(Input Encoding ),局部推理模型(Local Inference Modeling ),和推理合成(inference composition)。结构图如下所示:
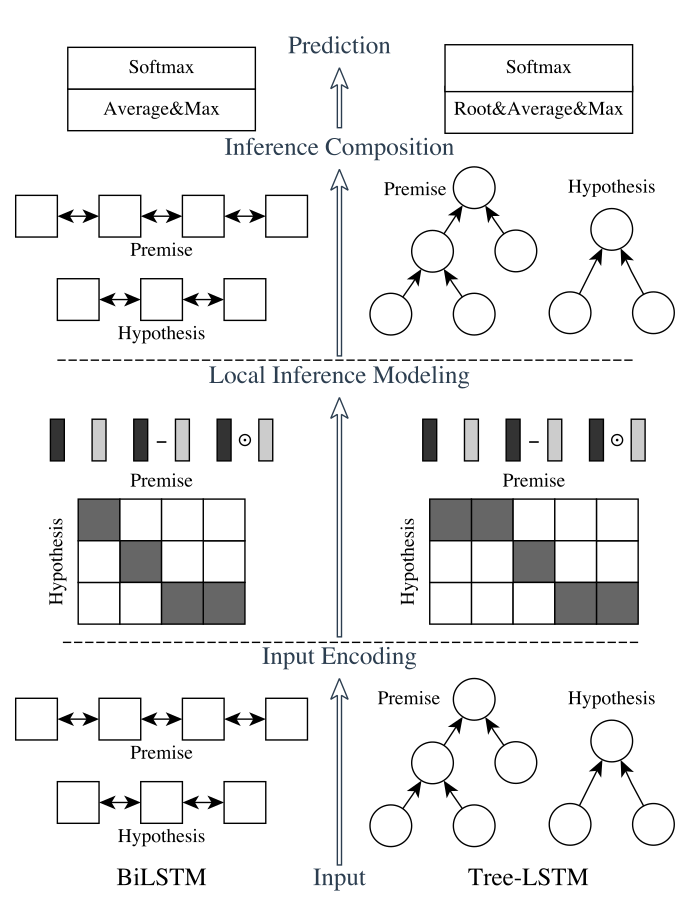
垂直来看,上图显示了系统的三个主要组成部分;水平来看,左边代表称为ESIM的序列NLI模型,右边代表包含了句法解析信息的树形LSTM网络。
输入编码
     # Based on arXiv:1609.06038

     q1 = Input(name='q1', shape=(maxlen,))

     q2 = Input(name='q2', shape=(maxlen,))

     # Embedding

     embedding = create_pretrained_embedding(

         pretrained_embedding, mask_zero=False)

     bn = BatchNormalization(axis=2)

     q1_embed = bn(embedding(q1))

     q2_embed = bn(embedding(q2))

     # Encode

     encode = Bidirectional(LSTM(lstm_dim, return_sequences=True))

     q1_encoded = encode(q1_embed)

     q2_encoded = encode(q2_embed)
有2种lstm:
A: sequential model 的做法
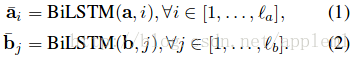
句子中的每个词都有了包含周围信息的 word representation
B: Tree-LSTM model的做法
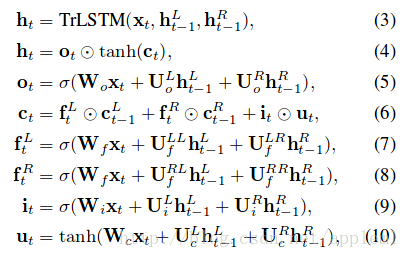
树中的每个节点(短语或字句)有了向量表示 htt
关于tree-LSTM 的介绍需要看文章:
[1] Improved semantic representations from tree-structured long short-term memory networks
[2] Natural Language inference by tree-based convolution and heuristic matching
[3] Long short-term memory over recursive structures
局部推理(Local Inference Modeling )
个人感觉就是一个attention的过程,取了个名字叫局部推理。
A: sequential model
 def soft_attention_alignment(input_1, input_2):

     "Align text representation with neural soft attention"

     attention = Dot(axes=-1)([input_1, input_2])

     #计算两个tensor中样本的张量乘积。例如,如果两个张量a和b的shape都为(batch_size, n),

     #则输出为形如(batch_size,1)的张量,结果张量每个batch的数据都是a[i,:]和b[i,:]的矩阵(向量)点积。

     w_att_1 = Lambda(lambda x: softmax(x, axis=1),

                      output_shape=unchanged_shape)(attention)

     w_att_2 = Permute((2, 1))(Lambda(lambda x: softmax(x, axis=2),

                                      output_shape=unchanged_shape)(attention))

     #Permute层将输入的维度按照给定模式进行重排,例如,当需要将RNN和CNN网络连接时,可能会用到该层。

     #dims:整数tuple,指定重排的模式,不包含样本数的维度。重拍模式的下标从1开始。

     #例如(2,1)代表将输入的第二个维度重拍到输出的第一个维度,而将输入的第一个维度重排到第二个维度

     in1_aligned = Dot(axes=1)([w_att_1, input_1])

     in2_aligned = Dot(axes=1)([w_att_2, input_2])

     return in1_aligned, in2_aligned
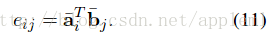
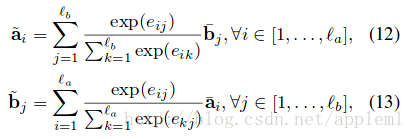
两句话相似或相反的对应
B: Tree-LSTM model
待续
推理合成(inference composition)
a是上层局部推理得到的。

ma 输入LSTM

对 lstm 每个time step 的结果进行pooling.

    # Compare

    q1_combined = Concatenate()(

        [q1_encoded, q2_aligned, submult(q1_encoded, q2_aligned)])

    q2_combined = Concatenate()(

        [q2_encoded, q1_aligned, submult(q2_encoded, q1_aligned)])

    compare_layers = [

        Dense(compare_dim, activation=activation),

        Dropout(compare_dropout),

        Dense(compare_dim, activation=activation),

        Dropout(compare_dropout),

    ]

    q1_compare = time_distributed(q1_combined, compare_layers)

    q2_compare = time_distributed(q2_combined, compare_layers)

    # Aggregate

    q1_rep = apply_multiple(q1_compare, [GlobalAvgPool1D(), GlobalMaxPool1D()])

    q2_rep = apply_multiple(q2_compare, [GlobalAvgPool1D(), GlobalMaxPool1D()])
《Enhanced LSTM for Natural Language Inference》(自然语言推理)的更多相关文章
- <A Decomposable Attention Model for Natural Language Inference>(自然语言推理)
http://www.xue63.com/toutiaojy/20180327G0DXP000.html 本文提出一种简单的自然语言推理任务下的神经网络结构,利用注意力机制(Attention Mec ...
- 论文阅读笔记: Natural Language Inference over Interaction Space
这篇文章提出了DIIN(DENSELY INTERACTIVE INFERENCE NETWORK)模型. 是解决NLI(NATURAL LANGUAGE INFERENCE)问题的很好的一种方法. ...
- <<Natural Language Inference over Interaction Space >> 句子匹配
模型结构 code :https://github.com/YichenGong/Densely-Interactive-Inference-Network 首先是模型图: Embedding Lay ...
- 第四篇:NLP(Natural Language Processing)自然语言处理
NLP自然语言处理: 百度AI的 NLP自然语言处理python语言--pythonSDK文档: https://ai.baidu.com/docs#/NLP-Python-SDK/top 第三方模块 ...
- 《Bilateral Multi-Perspective Matching for Natural Language Sentences》(句子匹配)
问题: Natural language sentence matching (NLSM),自然语言句子匹配,是指比较两个句子并判断句子间关系,是许多任务的一项基本技术.针对NLSM任务,目前有两种流 ...
- Bilateral Multi-Perspective Matching for Natural Language Sentences---读书笔记
自然语言句子的双向.多角度匹配,是来自IBM 2017 年的一篇文章.代码github地址:https://github.com/zhiguowang/BiMPM 摘要 这篇论文主要 ...
- 论文笔记:Tracking by Natural Language Specification
Tracking by Natural Language Specification 2018-04-27 15:16:13 Paper: http://openaccess.thecvf.com/ ...
- 【翻译】Knowledge-Aware Natural Language Understanding(摘要及目录)
翻译Pradeep Dasigi的一篇长文 Knowledge-Aware Natural Language Understanding 基于知识感知的自然语言理解 摘要 Natural Langua ...
- BiMPM:Bilateral Multi-Perspctive Matching for Natural Language Sentences
导言 本论文的工作主要是在 'matching-aggregation'的sentence matching的框架下,通过增加模型的特征(实现P与Q的双向匹配和多视角匹配),来增加NLSM(Natur ...
随机推荐
- IIS "rewrite.dll failed to load. The data is the error." 错误解决方法
在Windows 10 build 17133.73上部署一个较老版本的ASP.NET 2.0程序,访问时候出现: Service Unavailable HTTP Error 503. The se ...
- Egret动态设置按钮的图片
参考: 动态设置Button按钮的状态图片 按钮有3个状态,up down disabled.这里区别于source,source.down,source.disabled,而是每个状态单独一个ima ...
- Linux批量杀死进程
杀死进程在linux中使用kill命令了,我们可以下面来给各位介绍一篇关于Linux下批量杀死进程的例子,希望此例子可以对各位同学带来帮助的哦. 批量杀死包含关键字“php-fpm”的进程. kill ...
- Linux(CentOS)安装JDK(.tar.gz)并配置
本文思路转自http://blog.sina.com.cn/s/blog_81631744010137iy.html 点击(此处)折叠或打开 1.到 甲骨文(oracle)下载jdk不用多说 tar ...
- 【CF802C】Heidi and Library (hard) 费用流
[CF802C]Heidi and Library (hard) 题意:有n个人依次来借书,第i人来的时候要求书店里必须有种类为ai的书,种类为i的书要花费ci块钱购入.而书店的容量只有k,多余的书只 ...
- Windows Server 2008 R2之二从介质安装 AD DS
可以使用 Ntdsutil.exe 为在域中创建的其他域控制器创建安装介质.通过从介质安装,可以最大程度地减少网络上目录数据的复制.有利于在远程站点中更高效地安装其他域控制器. 实验环境: 在Wind ...
- K-means中的K值选择
关于如何选择Kmeans等聚类算法中的聚类中心个数,主要有以下方法(译自维基): 1. 最简单的方法:K≍sqrt(N/2) 2. 拐点法:把聚类结果的F-test值(类间Variance和全局Var ...
- mysql语句性能分析
1.开启慢查询 slow_query_log = 1 //开启 slow_query_log_file = mysql_slow_query.log //日志文件位置 long_query_time ...
- Pangolin中opengl的混合(gl_blend)
Blend 混合是将源色和目标色以某种方式混合生成特效的技术.混合常用来绘制透明或半透明的物体.在混合中起关键作用的α值实际上是将源色和目标色按给定比率进行混合,以达到不同程度的透明.α值为0则完全透 ...
- Shiro - 轻量级Java 安全框架
Apache Shiro 是一个强大易用的 Java 安全框架,提供了认证.授权.加密和会话管理等功能,对于任何一个应用程序,Shiro 都可以提供全面的安全管理服务. 并且相对于其他安全框架,Shi ...