
Spark 2.0
Apache Spark 2.0: Faster, Easier, and Smarter
http://blog.madhukaraphatak.com/categories/spark-two/
https://amplab.cs.berkeley.edu/technical-preview-of-apache-spark-2-0-easier-faster-and-smarter/
Dataset - New Abstraction of Spark
For long, RDD was the standard abstraction of Spark.
But from Spark 2.0, Dataset will become the new abstraction layer for spark. Though RDD API will be available, it will become low level API, used mostly for runtime and library development. All user land code will be written against the Dataset abstraction and it’s subset Dataframe API.
2.0中,最关键的是在RDD这个low level抽象层上,又加了一组DataSet的high level的抽象层,让用户可以跟方便的开发
From Definition, ” A Dataset is a strongly typed collection of domain-specific objects that can be transformed in parallel using functional or relational operations. Each dataset also has an untyped view called a DataFrame, which is a Dataset of Row. “
which sounds similar to RDD definition
” RDD represents an immutable,partitioned collection of elements that can be operated on in parallel “
Dataset is a superset of Dataframe API which is released in Spark 1.3.
Dataframe是一种特殊化的Dataset,Dataframe = Dataset[row]
SparkSession - New entry point of Spark
In earlier versions of spark, spark context was entry point for Spark. As RDD was main API, it was created and manipulated using context API’s. For every other API,we needed to use different contexts.For streaming, we needed StreamingContext, for SQL sqlContext and for hive HiveContext. But as DataSet and Dataframe API’s are becoming new standard API’s we need an entry point build for them. So in Spark 2.0, we have a new entry point for DataSet and Dataframe API’s called as Spark Session.
因为有了新的抽象层,所以需要加新的入口,SparkSession
就像RDD对应于SparkContext
更强大的SQL支持
On the SQL side, we have significantly expanded the SQL capabilities of Spark, with the introduction of a new ANSI SQL parser and support for subqueries.
Spark 2.0 can run all the 99 TPC-DS queries, which require many of the SQL:2003 features.
Tungsten 2.0
Spark 2.0 ships with the second generation Tungsten engine.
This engine builds upon ideas from modern compilers and MPP databases and applies them to data processing.
The main idea is to emit optimized bytecode at runtime that collapses the entire query into a single function, eliminating virtual function calls and leveraging CPU registers for intermediate data. We call this technique “whole-stage code generation.”
在内存管理和基于CPU的性能优化上,faster
Structured Streaming
Spark 2.0’s Structured Streaming APIs is a novel way to approach streaming.
It stems from the realization that the simplest way to compute answers on streams of data is to not having to reason about the fact that it is a stream.
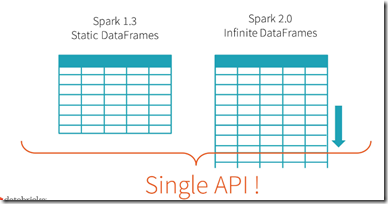
意思就是说,不要意识到流,流就是个无限的DataFrames
这个是典型的spark的思路,batch是一切的根本,和Flink截然相反
Spark 2.0的更多相关文章
- Spark 1.0.0 横空出世 Spark on Yarn 部署(Hadoop 2.4)
就在昨天,北京时间5月30日20点多.Spark 1.0.0最终公布了:Spark 1.0.0 released 依据官网描写叙述,Spark 1.0.0支持SQL编写:Spark SQL Progr ...
- APACHE SPARK 2.0 API IMPROVEMENTS: RDD, DATAFRAME, DATASET AND SQL
What’s New, What’s Changed and How to get Started. Are you ready for Apache Spark 2.0? If you are ju ...
- Apache Spark 3.0 将内置支持 GPU 调度
如今大数据和机器学习已经有了很大的结合,在机器学习里面,因为计算迭代的时间可能会很长,开发人员一般会选择使用 GPU.FPGA 或 TPU 来加速计算.在 Apache Hadoop 3.1 版本里面 ...
- spark 2.0.0集群安装与hive on spark配置
1. 环境准备: JDK1.8 hive 2.3.4 hadoop 2.7.3 hbase 1.3.3 scala 2.11.12 mysql5.7 2. 下载spark2.0.0 cd /home/ ...
- Spark 2.0 PCA主成份分析
PCA在Spark2.0中用法比较简单,只需要设置: .setInputCol(“features”)//保证输入是特征值向量 .setOutputCol(“pcaFeatures”)//输出 .se ...
- Apache Spark 2.0三种API的传说:RDD、DataFrame和Dataset
Apache Spark吸引广大社区开发者的一个重要原因是:Apache Spark提供极其简单.易用的APIs,支持跨多种语言(比如:Scala.Java.Python和R)来操作大数据. 本文主要 ...
- Spark 2.0 DataFrame map操作中Unable to find encoder for type stored in a Dataset.问题的分析与解决
转载:http://blog.csdn.net/sparkexpert/article/details/52871000 随着新版本的spark已经逐渐稳定,最近拟将原有框架升级到spark 2.0. ...
- Spark 2.0.0 SPARK-SQL returns NPE Error
com.esotericsoftware.kryo.KryoException: java.lang.NullPointerExceptionSerialization trace:underlyin ...
- Apache Spark 3.0 预览版正式发布,多项重大功能发布
2019年11月08日 数砖的 Xingbo Jiang 大佬给社区发了一封邮件,宣布 Apache Spark 3.0 预览版正式发布,这个版本主要是为了对即将发布的 Apache Spark 3. ...
随机推荐
- 面试整理之DOM事件阶段
因为快面试了,打开<JavaScript高级程序设计>,对DOM事件进行整理了下 本文主要解决的问题: 事件流 DOM事件流的三个阶段 先理解流的概念 在现今的JavaScript中随处可 ...
- WebService站点服务的地址
天气的地址 http://webservice.webxml.com.cn/WebServices/WeatherWS.asmx
- JVM的回收实现
通过一系列的称为"GC Roots"的对象作为起始点,从这些节点开始向下搜索,搜索所走过的路径称为引用链(Reference Chain),当一个对象到GC Roots没有任何引用 ...
- stack+DFS ZOJ 1004 Anagrams by Stack
题目传送门 /* stack 容器的应用: 要求字典序升序输出,所以先搜索入栈的 然后逐个判断是否满足答案,若不满足,回溯继续搜索,输出所有符合的结果 */ #include <cstdio&g ...
- cocosjs 触摸
/** * Created by sun on 15/11/24. */ var Piece = cc.Sprite.extend({ ctor:function (num) { this._supe ...
- 【wikioi】1116 四色问题
题目链接 算法:DFS 刚开始卡了一下,但后面想了想,于是 放上代码: #include <iostream> using namespace std; bool map[9][9]; i ...
- ASP.NET后台JS弹框使前台页面样式丢失 解决办法
Response.Write("<script>alert('您还没有上传相关图片!');</script>");是向前台输出js 应该用下面的方法 Cli ...
- NSThread
每个iOS应用程序都有个专门用来更新显示UI界面.处理用户的触摸事件的主线程,因此不能将其他太耗时的操作放在主线程中执行,不然会造成主线程堵塞(出现卡机现象),带来极坏的用户体验.一般的解决方案就是将 ...
- python 操作mysql
安装模块: #pip install .... MySQLdb(2.x) pymysql(3.x) import MySQLdb as sql con = sql.connect( host = &q ...
- hdu City Game
做这题之前建议做一下hdu1506题,两道题是极度相似的题,不同的是这个要处理的是m行,所以可以用一个dp[][]数组存储矩形的高度,之后就变成hdu1506了. 例如测试样例: 0 1 1 1 1 ...