
SpringBoot 2.0 整合sharding-jdbc中间件,实现数据分库分表
本文源码:GitHub·点这里 || GitEE·点这里
一、水平分割
1、水平分库
1)、概念:
以字段为依据,按照一定策略,将一个库中的数据拆分到多个库中。
2)、结果
每个库的结构都一样;数据都不一样;
所有库的并集是全量数据;
2、水平分表
1)、概念
以字段为依据,按照一定策略,将一个表中的数据拆分到多个表中。
2)、结果
每个表的结构都一样;数据都不一样;
所有表的并集是全量数据;
二、Shard-jdbc 中间件
1、架构图
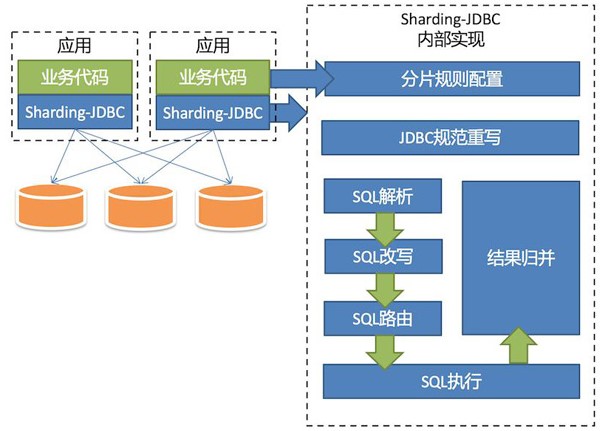
2、特点
1)、Sharding-JDBC直接封装JDBC API,旧代码迁移成本几乎为零。
2)、适用于任何基于Java的ORM框架,如Hibernate、Mybatis等 。
3)、可基于任何第三方的数据库连接池,如DBCP、C3P0、 BoneCP、Druid等。
4)、以jar包形式提供服务,无proxy代理层,无需额外部署,无其他依赖。
5)、分片策略灵活,可支持等号、between、in等多维度分片,也可支持多分片键。
6)、SQL解析功能完善,支持聚合、分组、排序、limit、or等查询。
三、项目演示
1、项目结构
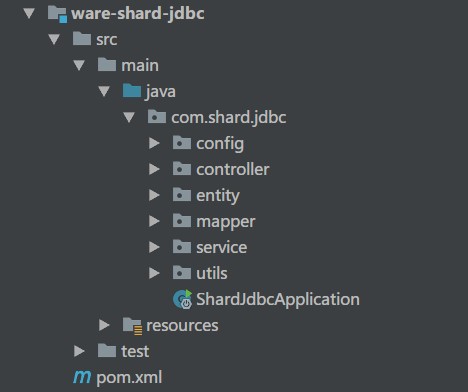
springboot     2.0 版本

druid          1.1.13 版本

sharding-jdbc  3.1 版本
2、数据库配置
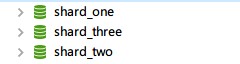
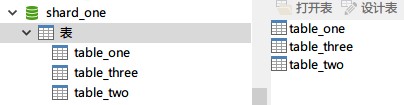
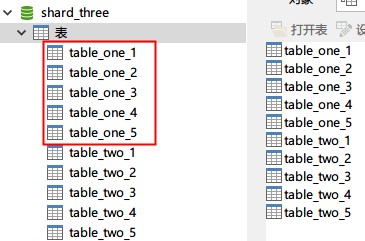
一台基础库映射(shard_one)

两台库做分库分表(shard_two,shard_three)。

表使用:table_one,table_two
3、核心代码块
- 数据源配置文件
spring:

  datasource:

    # 数据源:shard_one

    dataOne:

      type: com.alibaba.druid.pool.DruidDataSource

      druid:

        driverClassName: com.mysql.jdbc.Driver

        url: jdbc:mysql://localhost:3306/shard_one?useUnicode=true&characterEncoding=UTF8&zeroDateTimeBehavior=convertToNull&useSSL=false

        username: root

        password: 123

        initial-size: 10

        max-active: 100

        min-idle: 10

        max-wait: 60000

        pool-prepared-statements: true

        max-pool-prepared-statement-per-connection-size: 20

        time-between-eviction-runs-millis: 60000

        min-evictable-idle-time-millis: 300000

        max-evictable-idle-time-millis: 60000

        validation-query: SELECT 1 FROM DUAL

        # validation-query-timeout: 5000

        test-on-borrow: false

        test-on-return: false

        test-while-idle: true

        connectionProperties: druid.stat.mergeSql=true;druid.stat.slowSqlMillis=5000

    # 数据源:shard_two

    dataTwo:

      type: com.alibaba.druid.pool.DruidDataSource

      druid:

        driverClassName: com.mysql.jdbc.Driver

        url: jdbc:mysql://localhost:3306/shard_two?useUnicode=true&characterEncoding=UTF8&zeroDateTimeBehavior=convertToNull&useSSL=false

        username: root

        password: 123

        initial-size: 10

        max-active: 100

        min-idle: 10

        max-wait: 60000

        pool-prepared-statements: true

        max-pool-prepared-statement-per-connection-size: 20

        time-between-eviction-runs-millis: 60000

        min-evictable-idle-time-millis: 300000

        max-evictable-idle-time-millis: 60000

        validation-query: SELECT 1 FROM DUAL

        # validation-query-timeout: 5000

        test-on-borrow: false

        test-on-return: false

        test-while-idle: true

        connectionProperties: druid.stat.mergeSql=true;druid.stat.slowSqlMillis=5000

    # 数据源:shard_three

    dataThree:

      type: com.alibaba.druid.pool.DruidDataSource

      druid:

        driverClassName: com.mysql.jdbc.Driver

        url: jdbc:mysql://localhost:3306/shard_three?useUnicode=true&characterEncoding=UTF8&zeroDateTimeBehavior=convertToNull&useSSL=false

        username: root

        password: 123

        initial-size: 10

        max-active: 100

        min-idle: 10

        max-wait: 60000

        pool-prepared-statements: true

        max-pool-prepared-statement-per-connection-size: 20

        time-between-eviction-runs-millis: 60000

        min-evictable-idle-time-millis: 300000

        max-evictable-idle-time-millis: 60000

        validation-query: SELECT 1 FROM DUAL

        # validation-query-timeout: 5000

        test-on-borrow: false

        test-on-return: false

        test-while-idle: true

        connectionProperties: druid.stat.mergeSql=true;druid.stat.slowSqlMillis=5000
- 数据库分库策略
/**

 * 数据库映射计算

 */

public class DataSourceAlg implements PreciseShardingAlgorithm<String> {

    private static Logger LOG = LoggerFactory.getLogger(DataSourceAlg.class);

    @Override

    public String doSharding(Collection<String> names, PreciseShardingValue<String> value) {

        LOG.debug("分库算法参数 {},{}",names,value);

        int hash = HashUtil.rsHash(String.valueOf(value.getValue()));

        return "ds_" + ((hash % 2) + 2) ;

    }

}
- 数据表1分表策略
/**

 * 分表算法

 */

public class TableOneAlg implements PreciseShardingAlgorithm<String> {

    private static Logger LOG = LoggerFactory.getLogger(TableOneAlg.class);

    /**

     * 该表每个库分5张表

     */

    @Override

    public String doSharding(Collection<String> names, PreciseShardingValue<String> value) {

        LOG.debug("分表算法参数 {},{}",names,value);

        int hash = HashUtil.rsHash(String.valueOf(value.getValue()));

        return "table_one_" + (hash % 5+1);

    }

}
- 数据表2分表策略
/**

 * 分表算法

 */

public class TableTwoAlg implements PreciseShardingAlgorithm<String> {

    private static Logger LOG = LoggerFactory.getLogger(TableTwoAlg.class);

    /**

     * 该表每个库分5张表

     */

    @Override

    public String doSharding(Collection<String> names, PreciseShardingValue<String> value) {

        LOG.debug("分表算法参数 {},{}",names,value);

        int hash = HashUtil.rsHash(String.valueOf(value.getValue()));

        return "table_two_" + (hash % 5+1);

    }

}
- 数据源集成配置
/**

 * 数据库分库分表配置

 */

@Configuration

public class ShardJdbcConfig {

    // 省略了 druid 配置,源码中有

    /**

     * Shard-JDBC 分库配置

     */

    @Bean

    public DataSource dataSource (@Autowired DruidDataSource dataOneSource,

                                  @Autowired DruidDataSource dataTwoSource,

                                  @Autowired DruidDataSource dataThreeSource) throws Exception {

        ShardingRuleConfiguration shardJdbcConfig = new ShardingRuleConfiguration();

        shardJdbcConfig.getTableRuleConfigs().add(getTableRule01());

        shardJdbcConfig.getTableRuleConfigs().add(getTableRule02());

        shardJdbcConfig.setDefaultDataSourceName("ds_0");

        Map<String,DataSource> dataMap = new LinkedHashMap<>() ;

        dataMap.put("ds_0",dataOneSource) ;

        dataMap.put("ds_2",dataTwoSource) ;

        dataMap.put("ds_3",dataThreeSource) ;

        Properties prop = new Properties();

        return ShardingDataSourceFactory.createDataSource(dataMap, shardJdbcConfig, new HashMap<>(), prop);

    }

    /**

     * Shard-JDBC 分表配置

     */

    private static TableRuleConfiguration getTableRule01() {

        TableRuleConfiguration result = new TableRuleConfiguration();

        result.setLogicTable("table_one");

        result.setActualDataNodes("ds_${2..3}.table_one_${1..5}");

        result.setDatabaseShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new DataSourceAlg()));

        result.setTableShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new TableOneAlg()));

        return result;

    }

    private static TableRuleConfiguration getTableRule02() {

        TableRuleConfiguration result = new TableRuleConfiguration();

        result.setLogicTable("table_two");

        result.setActualDataNodes("ds_${2..3}.table_two_${1..5}");

        result.setDatabaseShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new DataSourceAlg()));

        result.setTableShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new TableTwoAlg()));

        return result;

    }

}
- 测试代码执行流程
@RestController

public class ShardController {

    @Resource

    private ShardService shardService ;

    /**

     * 1、建表流程

     */

    @RequestMapping("/createTable")

    public String createTable (){

        shardService.createTable();

        return "success" ;

    }

    /**

     * 2、生成表 table_one 数据

     */

    @RequestMapping("/insertOne")

    public String insertOne (){

        shardService.insertOne();

        return "SUCCESS" ;

    }

    /**

     * 3、生成表 table_two 数据

     */

    @RequestMapping("/insertTwo")

    public String insertTwo (){

        shardService.insertTwo();

        return "SUCCESS" ;

    }

    /**

     * 4、查询表 table_one 数据

     */

    @RequestMapping("/selectOneByPhone/{phone}")

    public TableOne selectOneByPhone (@PathVariable("phone") String phone){

        return shardService.selectOneByPhone(phone);

    }

    /**

     * 5、查询表 table_one 数据

     */

    @RequestMapping("/selectTwoByPhone/{phone}")

    public TableTwo selectTwoByPhone (@PathVariable("phone") String phone){

        return shardService.selectTwoByPhone(phone);

    }

}
四、项目源码
GitHub·地址

https://github.com/cicadasmile/middle-ware-parent

GitEE·地址

https://gitee.com/cicadasmile/middle-ware-parent
SpringBoot 2.0 整合sharding-jdbc中间件,实现数据分库分表的更多相关文章
- (二)基于shard-jdbc中间件,实现数据分库分表
基于shard-jdbc中间件,实现数据分库分表 Sharding-JDBC简介 Sharding配置示意图 1.水平分割 1.1 水平分库 1.2 水平分表 2.Shard-jdbc中间件 2.1 ...
- sharding demo 读写分离 U (分库分表 & 不分库只分表)
application-sharding.yml sharding: jdbc: datasource: names: ds0,ds1,dsx,dsy ds0: type: com.zaxxer.hi ...
- SpringBoot+MybatisPlus+Mysql+Sharding-JDBC分库分表实践
一.序言 在实际业务中,单表数据增长较快,很容易达到数据瓶颈,比如单表百万级别数据量.当数据量继续增长时,数据的查询性能即使有索引的帮助下也不尽如意,这时可以引入数据分库分表技术. 本文将基于Spri ...
- mysql大数据解决方案--分表分库(0)
引言 对于一个大型的互联网应用,海量数据的存储和访问成为了系统设计的瓶颈问题,对于系统的稳定性和扩展性造成了极大的问题.通过数据切分来提高网站性能,横向扩展数据层已经成为架构研发人员首选的方式. •水 ...
- Sharding JDBC整合SpringBoot 2.x 和 MyBatis Plus 进行分库分表
Sharding JDBC整合SpringBoot 2.x 和 MyBatis Plus 进行分库分表 交易所流水表的单表数据量已经过亿,选用Sharding-JDBC进行分库分表.MyBatis-P ...
- 【ShardingSphere技术专题】「ShardingJDBC」SpringBoot之整合ShardingJDBC实现分库分表(JavaConfig方式)
前提介绍 ShardingSphere介绍 ShardingSphere是一套开源的分布式数据库中间件解决方案组成的生态圈,它由Sharding-JDBC.Sharding-Proxy和Shardin ...
- Sharding-JDBC基本使用,整合Springboot实现分库分表,读写分离
结合上一篇docker部署的mysql主从, 本篇主要讲解SpringBoot项目结合Sharding-JDBC如何实现分库分表.读写分离. 一.Sharding-JDBC介绍 1.这里引用官网上的介 ...
- SpringBoot+Mybatis-Plus整合Sharding-JDBC5.1.1实现单库分表【全网最新】
一.前言 小编最近一直在研究关于分库分表的东西,前几天docker安装了mycat实现了分库分表,但是都在说mycat的bug很多.很多人还是倾向于shardingsphere,其实他是一个全家桶,有 ...
- 三、SpringBoot 整合mybatis 多数据源以及分库分表
前言 说实话,这章本来不打算讲的,因为配置多数据源的网上有很多类似的教程.但是最近因为项目要用到分库分表,所以让我研究一下看怎么实现.我想着上一篇博客讲了多环境的配置,不同的环境调用不同的数据库,那接 ...
随机推荐
- ElasticSearch(二)核心概念
elasticsearch核心概念 (1)Near Realtime(NRT):近实时,两个意思,从写入数据到数据可以被搜索到有一个小延迟(大概1秒):基于es执行搜索和分析可以达到秒级 (2)Clu ...
- Java单元测试(Junit+Mock+代码覆盖率)---------转
Java单元测试(Junit+Mock+代码覆盖率) 原文见此处 单元测试是编写测试代码,用来检测特定的.明确的.细颗粒的功能.单元测试并不一定保证程序功能是正确的,更不保证整体业务是准备的. 单元测 ...
- ubuntu 查看网卡 数据包处理 速度
ubuntu 查看网卡 数据包处理 速度 sar -l 1 10 首先要安装sar .使用 apt-get install atsar sar 命令中的 "-l"參数是 net-i ...
- 《打造Facebook》
王淮的<打造Facebook>一书不厚,花半天时间轻松读完.书中没有大段的说教,只有近乎流水的陈述.正如作者所说,打造Facebook这本书由巴克伯格来写再合适不过.可惜他至少在近几年内没 ...
- Vue数据双向绑定探究
前面的啰嗦话,写一点吧,或许就有点用呢 使用过vue的小伙伴都会感觉,哇,这个框架对开发者这么友好,简直都要笑出声了. 确实,使用过vue的框架做开发的人都会感觉到,以前写一大堆操作dom,bom的东 ...
- SPOJ1811 LCS SAM
后缀自动机简单题. 其主要思路是,先对第一个字符串建立后缀自动机,把第二个串放在上面匹配, 若当前状态s有字符x的转移,直接转移len=step+1. 若当前状态s没有向字符x的转移,退回pres检查 ...
- UVA12293 Box Game —— SG博弈
题目链接:https://vjudge.net/problem/UVA-12293 题意: 两人玩游戏,有两个盒子,开始时第一个盒子装了n个球, 第二个盒子装了一个球.每次操作都将刷量少的盒子的球倒掉 ...
- jinja 多值合并
示例 {% for node in groups["db"] %} {{ node | join("") }}:5672 {% if not loop.last ...
- 从ffmpeg filter里出来的数据直接送给avcodec_encode_audio2编码,写文件有错。
http://hi.baidu.com/mingyuejingque/item/78e71aff57ae9ec5a835a2e4 感谢mingyuejingque st = avformat_new_ ...
- 存储过程系列三:根据表别名方式distinct去重插入
1.根据表别名方式distinct去重插入 insert into GG_XKZ_YLQXSCXKESL_SCDZ ( bzj, xkzid, sqid, jtdz, szsf, ...