
Yandex Big Data Essentials Week1 Scaling Distributed File System
GFS Key Components
- components failures are a norm
- even space utilisation
- write-once-read-many
GFS and Hadoop Distributed File System
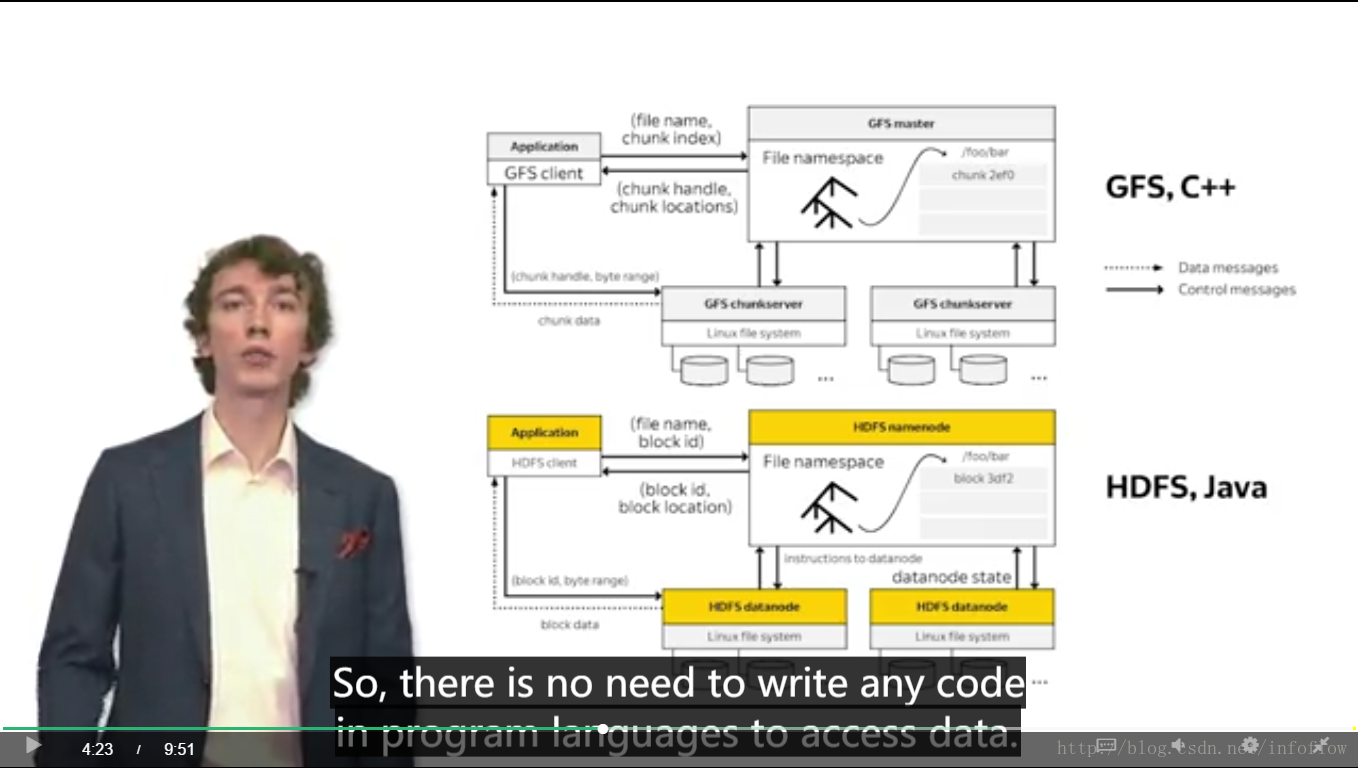
GFS主要分为:Application 、Master、ChannelServer
hdfs主要分为:Appllcation 、 NameNode 、DataNode三部分
how to read file from hdfs
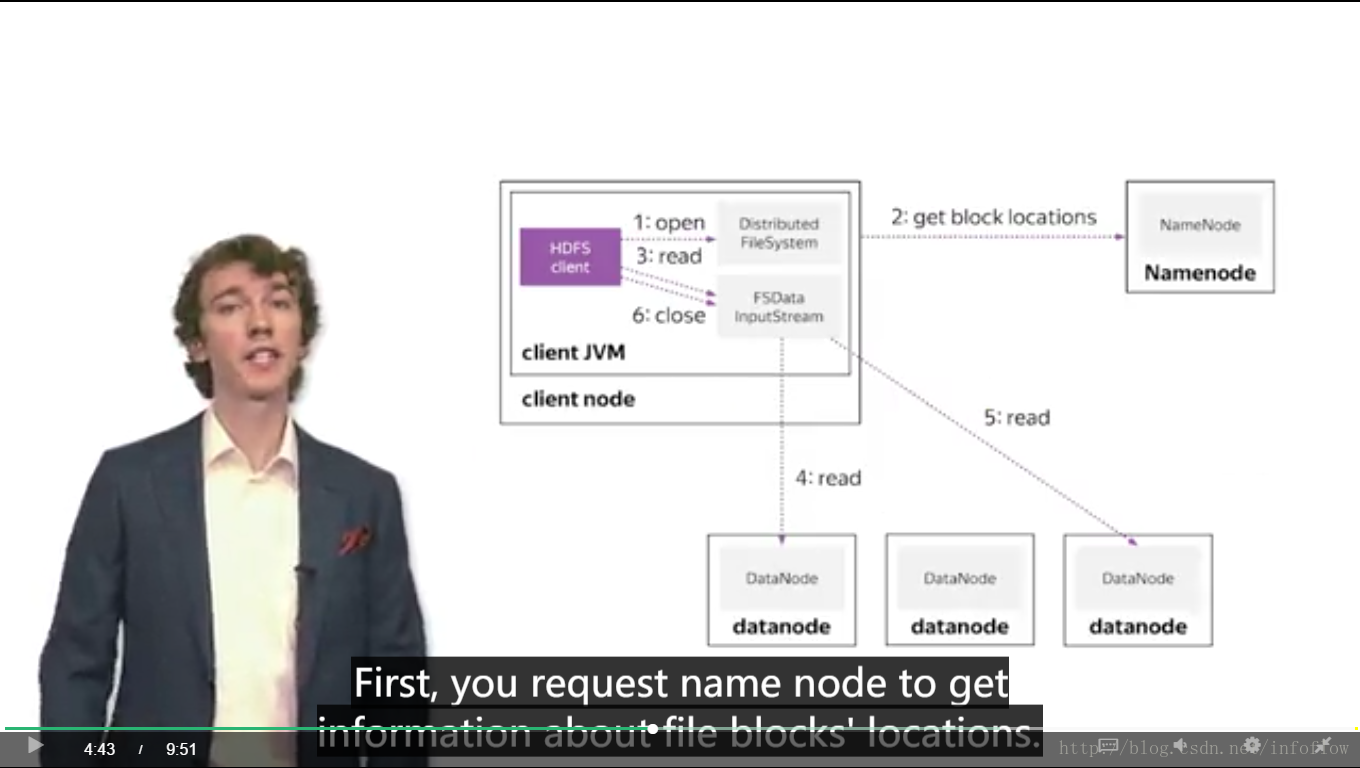
HDFS client 运行在client node 上的client jvm上。
读取文件的流程
- 打开分布式文件系统上的文件
- 从NameNode处取的文件块的位置
- HDFS client将块位置信息传给FSDataInputStream
- FSDataInputStream再从相应的DataNode里面读取其中一个块数据
- FSDataInputStream再从相应的DataNode里面读取另一个块数据
- 关闭FSDataInputStream
写入文件的流程

hdfs client 运行在client jvm上,client jvm运行在client jvm上。
写入文件的流程:
1. HDFS client 在Distributed FileSystem上创建文件
2. DistributedFileSystem 在NameNode上create一个文件
3. HDFS client 通过FSDataInputStream向datanode发送write packet
4. 至少三个datanode组成Pipeline of datanodes写入多个副本
5. datanode向FSDataInpuStream发送ack packet
6. 关闭
In DFS,you can “append” into file,but cannot “modify” a file in the middle. Why?
DFS的核心特性write once read many time 描述了一种数据存储策略。信息一旦写入就不能修改,因为修改操作需要对对底层的存储结构进行修改。如果需要修改分布式文件系统(例如hdfs)中的文件,可以写一份新的同样文件名的数据。旧的文件在hdfs在整理数据的时候会丢弃。
HDFS应用需要一个“一次写入多次读取”的文件访问模型。一个文件经过创建、写入和关闭之后就不需要改变。这一假设简化了数据一致性问题,并且使高吞吐量的数据访问成为可能。Map/Reduce应用或者网络爬虫应用都非常适合这个模型。目前还有计划在将来扩充这个模型,使之支持文件的附加写操作。
Yandex Big Data Essentials Week1 Scaling Distributed File System的更多相关文章
- Yandex Big Data Essentials Week1 Unix Command Line Interface File System exploration
File System Function In computing, a file system or filesystem is used to control how data is stored ...
- Yandex Big Data Essentials Week1 Unix Command Line Interface Processes managing
free displays the total amount of free and used memory free [options] top provides a dynamic real-ti ...
- Yandex Big Data Essentials Week1 Unix Command Line Interface File Content exploration
cat displays the contents of a file at the command line copies or apppend text file into a document ...
- HDFS分布式文件系统(The Hadoop Distributed File System)
The Hadoop Distributed File System (HDFS) is designed to store very large data sets reliably, and to ...
- HDFS(Hadoop Distributed File System )
HDFS(Hadoop Distributed File System ) HDFS(Hadoop Distributed File System )Hadoop分布式文件系统.是根据google发表 ...
- 5105 pa3 Distributed File System based on Quorum Protocol
1 Design document 1.1 System overview We implemented a distributed file system using a quorum based ...
- Ceph: A Scalable, High-Performance Distributed File System译文
原文地址:陈晓csdn博客 http://blog.csdn.net/juvxiao/article/details/39495037 论文概况 论文名称:Ceph: A Scalable, High ...
- Hadoop ->> HDFS(Hadoop Distributed File System)
HDFS全称是Hadoop Distributed File System.作为分布式文件系统,具有高容错性的特点.它放宽了POSIX对于操作系统接口的要求,可以直接以流(Stream)的形式访问文件 ...
- HDFS(Hadoop Distributed File System )hadoop分布式文件系统。
HDFS(Hadoop Distributed File System )hadoop分布式文件系统.HDFS有如下特点:保存多个副本,且提供容错机制,副本丢失或宕机自动恢复.默认存3份.运行在廉价的 ...
随机推荐
- C# 获取WebBrowser内容的高度
int webHeight =0; WebBrowser web =new WebBrowser(); web.Navigate("about:blank"); while (we ...
- es snapshot备份到hdfs及从hdfs恢复snapshot
snapshot可以将es整个集群,具体索引数据备份到磁盘,hdfs等.需要时,可以从磁盘,hdfs恢复数据到es. 具体参考: https://elasticsearch.cn/article/61 ...
- Java HashSet集合的子类LinkedHashSet集合
说明 HashSet保证元素的唯一性,可是元素存放进去是没有顺序的. 在HashSet下面有一个子类java.util.LinkedHashSet,它是 链表 + 哈希表(数组+链表 或者 数组+红黑 ...
- Unity_Dungeonize 随机生成迷宫
本文对随机生成迷宫的实现思路进行记录,其作用在于为游戏过程提供随机性以及节省开发周期,下面是Dungeonize的结构 随机迷宫的生成主要包括几个阶段 1.生成房间体结构,为墙体,自定义房间,自定义物 ...
- 基于Java+HttpClient+TestNG的接口自动化测试框架(四)-------参数存取处理
在真正开始接口测试之前,我们需要对参数的处理进行梳理.这里所说的“参数”,既包含之前在xml中的配置(我们称之为全局参数),也包含在每一条用例中书写的param.全局参数为固定不变的,而根据接口相应获 ...
- __init__.py在导包中起到的作用
说明:__init__.py这个文件本人使用频率不高 例子: __init__.py文件作用:初始化这个包 1.v1.py def vi(): return 'views' 2.views->_ ...
- python 进程事件
1.作用 通过信号量,控制全部进程进入阻塞状态,也可以通过控制信号量,解除全部进程的阻塞 注意:定义的事件对象,默认状态是阻塞 2.常用方法 """ 对象.set() 作 ...
- spring cloud 与 docker 读书笔记 1
Eureka Server 的高可用
- [mvc>actionResult] 封装一个操作方法的结果并用于代表该操作方法执行框架级操作
- Mixing .NET