
Paper Reading - CNN+CNN: Convolutional Decoders for Image Captioning
Link of the Paper: https://arxiv.org/abs/1805.09019
Innovations:
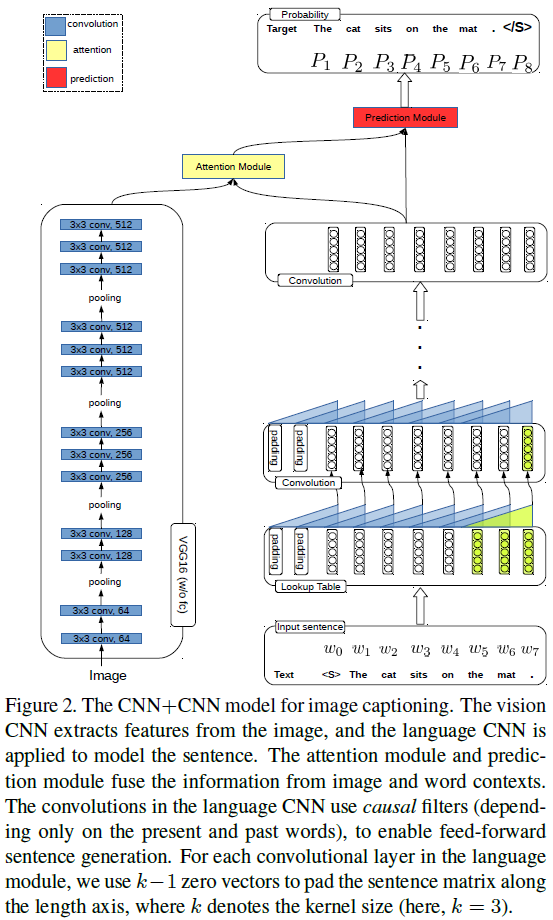
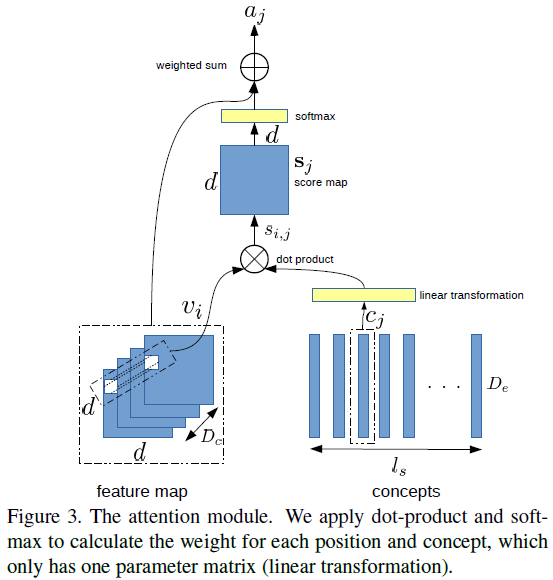
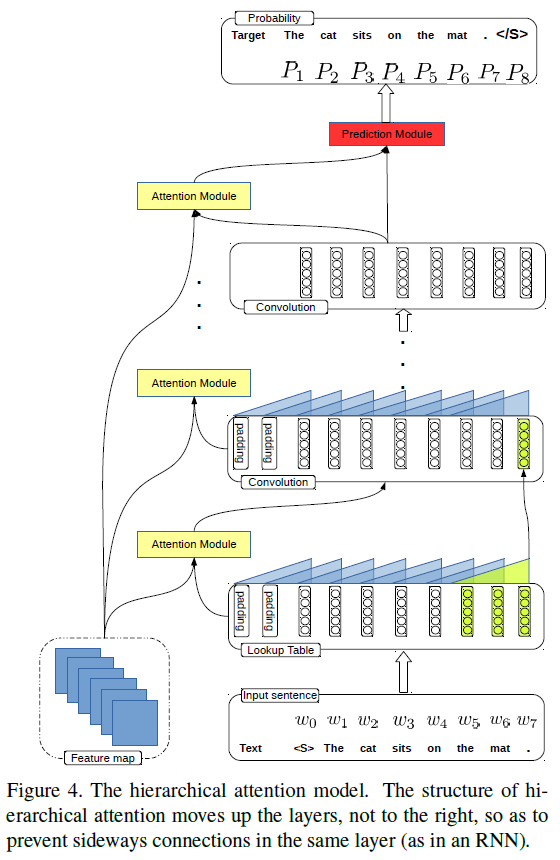
- The authors propose a CNN + CNN framework for image captioning. There are four modules in the framework: vision module ( VGG-16 ), which is adopted to "watch" images; language module, which is to model sentences; attention module, which connects the vision module with the language module; prediction module, which takes the visual features from the attention module and concepts from the language module as input and predicts the next word.
General Points:
- RNNs or LSTMs cannot be calculated in parallel and ignore the underlying hierarchical structure of a sentence.
- Directly feeding the output of the CNN into the RNN treats objects in an image the same and ignores the salient objects when generating one word.
- In both m-RNN and NIC, an image is represented by a single vector, which ignores different areas and objects in the image. A spatial attention mechanism is introduced into image captioning model in Show, attend and tell: Neural image caption generation with visual attention, which allows the model to pay attention to different areas at each time step.
Paper Reading - CNN+CNN: Convolutional Decoders for Image Captioning的更多相关文章
- Paper Reading - Long-term Recurrent Convolutional Networks for Visual Recognition and Description ( CVPR 2015 )
Link of the Paper: https://arxiv.org/abs/1411.4389 Main Points: A novel Recurrent Convolutional Arch ...
- 使用CNN(convolutional neural nets)关键的一点是检测到的面部教程(四):学习率,学习潜能,dropout
第七部分 让 学习率 和 学习潜能 随时间的变化 光训练就花了一个小时的时间.等结果并非一个令人心情愉快的事情.这一部分.我们将讨论将两个技巧结合让网络训练的更快! 直觉上的解决的方法是,開始训练时取 ...
- Paper Reading: Stereo DSO
开篇第一篇就写一个paper reading吧,用markdown+vim写东西切换中英文挺麻烦的,有些就偷懒都用英文写了. Stereo DSO: Large-Scale Direct Sparse ...
- SCA-CNN: Spatial and Channel-wise Attention in Convolutional Networks for Image Captioning
题目:SCA-CNN: Spatial and Channel-wise Attention in Convolutional Networks for Image Captioning 作者: Lo ...
- Paper Reading - Convolutional Image Captioning ( CVPR 2018 )
Link of the Paper: https://arxiv.org/abs/1711.09151 Motivation: LSTM units are complex and inherentl ...
- Deep Learning 学习随记(八)CNN(Convolutional neural network)理解
前面Andrew Ng的讲义基本看完了.Andrew讲的真是通俗易懂,只是不过瘾啊,讲的太少了.趁着看完那章convolution and pooling, 自己又去翻了翻CNN的相关东西. 当时看讲 ...
- Paper Reading - Convolutional Sequence to Sequence Learning ( CoRR 2017 ) ★
Link of the Paper: https://arxiv.org/abs/1705.03122 Motivation: Compared to recurrent layers, convol ...
- About CNN(convolutional neural network)
NO.1卷积神经网络基本概念 CNN是第一个被成功训练的多层深度神经网络结构,具有较强的容错.自学习及并行处理能力.最初是为识别二维图像而设计的多层感知器,局部连接和权值共享网络结构 类似于生物神经网 ...
- paper 158:CNN(卷积神经网络):Dropout Layer
Dropout作用 在hinton的论文Improving neural networks by preventing coadaptation提出的,主要作用就是为了防止模型过拟合.当模型参数较多, ...
随机推荐
- 课时53.video标签(掌握)
这节课来学习一下html5中新增的标签,我们先来看一下,html5中新增了哪些标签? 打开W3school的网页,点击参考手册中的HTML/HTML5标签,有一个按字母顺序排列的标签,但凡标签后面带有 ...
- IDEA(2018.3.2)
N757JE0KCT-eyJsaWNlbnNlSWQiOiJONzU3SkUwS0NUIiwibGljZW5zZWVOYW1lIjoid3UgYW5qdW4iLCJhc3NpZ25lZU5hbWUiO ...
- POJ 3528--Ultimate Weapon(三维凸包)
Ultimate Weapon Time Limit: 2000MS Memory Limit: 131072K Total Submissions: 2430 Accepted: 1173 ...
- php 当不确定用户输入的是浮点 还是整数 还是字符串时
$price = (floatval($price))?intval(floatval($price)*100)/100:0;
- idea 聚合项目里如果子项目引用不到父类的maven应用
idea 聚合项目里如果子项目引用不到父类的maven应用,可以点看子类pom.xml文件,然后右键---->maven----->Reimport即可 点击右边子项目的maven---& ...
- Python Homework 001
1 #!/usr/bin/env python 2 #-*- coding:utf-8 -*- 3 4 import getpass 5 name = "xilong" 6 pas ...
- CentOS6.5 虚拟机 磁盘扩容
1. 关闭虚拟机 2. 编辑虚拟机设置:增加硬盘的置备大小,或者添加新的硬盘 3. 启动虚拟机,查看可用磁盘大小 : # df -Th Filesystem Type Size Used Avail ...
- 关于js复制的那些事儿
window.clipboardData的作用是在页面上将需要的东西复制到剪贴板上,提供了对于预定义的剪贴板格式的访问,以便在编辑操作中使用. 三个方法 (1)clearData(sDataForma ...
- redis的docker化安装
只需要关注几点: 端口映射 配置文件映射 持久化映射 要做的就是拉取官方镜像并把关注的几个点处理一下就好了: docker pull redis docker run -d -p : -v /data ...
- PHP读取zip包
$filename = $this->upload->data('file_name'); //得到文件夹(此处是CI框架上传文件之后得到文件名称) $file_root = 'can ...