
A Statistical Model for Scientific Readability-paper
Authors:
Luo SiCarnegie Mellon University, Pittsburgh, PA
Jamie CallanCarnegie Mellon University, Pittsburgh, PA
Atlanta, Georgia, USA — October 05 - 10, 2001
ACM New York, NY, USA ©2001
数据不公开: educational Web pages ,A total of 91 Web pages。Pages were grouped into three readability levels: KindergartenGrade2, Grade3-Grade5, and Grade6-Grade8
monosyllable 单音节词
2. READABILITY METRICS
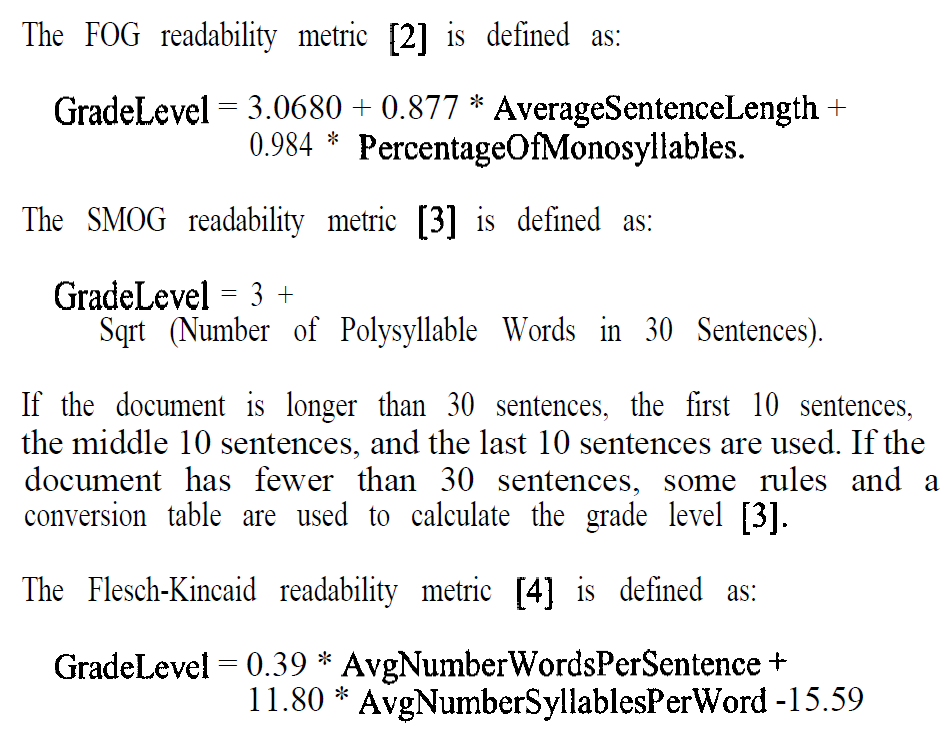
第一个是个初级中级学习者
第二个会比别的给的难度分更高
第三个用的更广
3. STATISTICAL LANGUAGE MODELS
线性模型广泛用于模型的组合,EM算法用来寻找最佳参数
线性插值公式来组合语言模型和句子长度模型:前者用ngram,后者考虑句长
1)unigram语言模型假设生成一个词的概率适合上下文无关的。虽然unigram模型在人类语言上效果不好,但是它们适合很多应用,有可以在小数据上训练的优点。
2)通过看某个特征的值是否和难度成正比或反比,来判断特征重要与否,最后得出句长特征很重要,公式法中单音节不适合该数据集;然后假设符合正态分布

4 实验
KF这种公式法只能得出最终属于哪个等级,但是我们的数据集并不含有这些等级。我们统计的方法可以给出概率这种soft metric。
-------------------------
N-Gram是基于一个假设:
第n个词出现与前n-1个词相关,而与其他任何词不相关。(这也是隐马尔可夫当中的假设。)整个句子出现的概率就等于各个词出现的概率乘积。各个词的概率可以通过语料中统计计算得到。假设句子T是有词序列w1,w2,w3...wn组成,用公式表示N-Gram语言模型如下:
P(T)=P(w1)*p(w2)*p(w3)...p(wn)=p(w1)*p(w2|w1)*p(w3|w1w2)...p(wn|w1w2w3...)
一般常用的N-Gram模型是Bi-Gram和Tri-Gram。分别用公式表示如下:
Bi-Gram:P(T)=p(w1|begin)*p(w2|w1)*p(w3|w2)...p(wn|wn-1)
Tri-Gram:P(T)=p(w1|begin1,begin2)*p(w2|w1,begin1)*p(w3|w2w1)...p(wn|wn-1,wn-2)
https://github.com/lijingpeng/kaggle/blob/master/competitions/Bag_of_Words/bags_of_words.ipynb 包含贝叶斯、回归分类
A Statistical Model for Scientific Readability-paper的更多相关文章
- machine learning model(algorithm model) .vs. statistical model
https://www.analyticsvidhya.com/blog/2015/07/difference-machine-learning-statistical-modeling/ http: ...
- Writing your first academic paper
Writing your first academic paper If you are working in academics (and you are if you are working wi ...
- The Model Complexity Myth
The Model Complexity Myth (or, Yes You Can Fit Models With More Parameters Than Data Points) An oft- ...
- A Statistical View of Deep Learning (II): Auto-encoders and Free Energy
A Statistical View of Deep Learning (II): Auto-encoders and Free Energy With the success of discrimi ...
- [转]NLP Tasks
Natural Language Processing Tasks and Selected References I've been working on several natural langu ...
- Targeted Learning R Packages for Causal Inference and Machine Learning(转)
Targeted learning methods build machine-learning-based estimators of parameters defined as features ...
- 【RNN】资源汇总
wesome Recurrent Neural Networks A curated list of resources dedicated to recurrent neural networks ...
- Lessons Learned from Developing a Data Product
Lessons Learned from Developing a Data Product For an assignment I was asked to develop a visual ‘da ...
- CVPR 2015 papers
CVPR2015 Papers震撼来袭! CVPR 2015的文章可以下载了,如果链接无法下载,可以在Google上通过搜索paper名字下载(友情提示:可以使用filetype:pdf命令). Go ...
随机推荐
- 网站基础html javascript jquery
第二章HTML HBuilder的使用 边改边看模式 chrome浏览器看. HTML的基本格式 超文本标记语言 HyperText Markup Language HyperText 超文本 Mar ...
- G711 G723 G729线路占多少带宽问题
G.711 G.711 也称为PCM(脉冲编码调制),是国际电信联盟订定出来的一套语音压缩标准,主要用于电话.它主要用脉冲编码调制对音频采样,采样率为8k每秒.它利用一个 64Kbps 未压缩 ...
- 如何设置openwrt在编译linux内核时不优化内核?
答:修改openwrwt源码目录下rule.mk文件中的HOST_CFLAGS即可 将HOST_CFLAGS:=-O2 $(HOST_CPPFLAGS)改成: HOST_CFLAGS:=-O1 $(H ...
- linux基础之find
linux上文件查找工具: locate, find locate: 依赖于事先构建的索引,索引的构建在系统较为空闲时自动进行(周期性任务),手动更新数据库(updatedb) 索引构建过程需要遍历整 ...
- jQuery学习笔记(一)
jQuery 事件 - ready() 方法 实例 在文档加载后激活函数(): $(document).ready(function(){ $(".btn1").click(fun ...
- Lintcode105 Copy List with Random Pointer solution 题解
[题目描述] A linked list is given such that each node contains an additional random pointer which could ...
- [Spring MVC] 表单提交日期转换问题,比如可能导致封装实体类时400错误
三种格式的InitBinder @InitBinder//https://stackoverflow.com/questions/20616319/the-request-sent-by-the-cl ...
- Probability和Likelihood的区别
Bayes for Beginners: Probability and Likelihood 好好看,非常有用. 以前死活都不理解Probability和Likelihood的区别,为什么这两个东西 ...
- C# 获取CPU序列号、网卡MAC地址、硬盘序列号封装类,用于软件绑定电脑
using System.Management; namespace GLaLa { /// <summary> /// hardware_mac 的摘要说明. /// </summ ...
- 7.9 GRASP原则九: 隔离变化
GRASP原则九: 隔离变化 Protected Variations 需求一定会变化的!如何做到以系统的局部变化为代价就可以应对这一点?4.1 GRASP rule9: Protected ...