
Apache Spark : Introduction
看了一点《数据算法:Hadoop/Spark大数据处理技巧》,觉得有必要了解一下 Spark 。
以上。
Spark was introduced by Apache Software Foundation for speeding up the Hadoop computational computing software process.
As against a common belief, Spark is not a modified version of Hadoop and is not, really, dependent on Hadoop because it has its own cluster management. Hadoop is just one of the ways to implement Spark.
Spark uses Hadoop in two ways – one is storage and second is processing. Since Spark has its own cluster management computation, it uses Hadoop for storage purpose only.
Hadoop 是对大数据集进行分布式计算的标准工具,允许使用相对便宜的商业硬件集群进行超级计算机级别的计算。不过,Hadoop 也存在很多已知限制。比如说 MapReduce 作业的 I/O 成本很高,导致交互分析和迭代算法(iterative algorithms)开销很大。但是事实上,几乎所有的最优化和机器学习都是迭代的。为了解决这些问题,Hadoop 一直在向一种更为通用的资源管理框架转变,即 YARN(Yet Another Resource Negotiator, 又一个资源协调者)。而 Spark 是第一个脱胎于该转变的快速、通用分布式计算范式,拥有自己的集群管理方式,并不是 Hadoop 的一个新版本。Hadoop 只是 Spark 实现方式的一种,而且只是用来存储数据。
Apache Spark
Apache Spark is a lightning-fast cluster computing technology, designed for fast computation. It is based on Hadoop MapReduce and it extends the MapReduce model to efficiently use it for more types of computations, which includes interactive queries and stream processing. The main feature of Spark is its in-memory cluster computing that increases the processing speed of an application.
Spark is designed to cover a wide range of workloads such as batch applications, iterative algorithms, interactive queries and streaming. Apart from supporting all these workload in a respective system, it reduces the management burden of maintaining separate tools.
Spark 是个轻量快速的集群计算技术,设计成能进行快速的计算。使用函数式编程范式扩展了 MapReduce 模型以支持更多计算类型,可以涵盖广泛的工作流,这些工作流之前被实现为 Hadoop 之上的特殊系统。Spark 使用内存缓存来提升性能,因此进行交互式分析也足够快速。缓存同时提升了迭代算法的性能,这使得 Spark 非常适合数据理论任务,特别是机器学习。
Evolution of Apache Spark
Spark is one of Hadoop’s sub project developed in 2009 in UC Berkeley’s AMPLab by Matei Zaharia. It was Open Sourced in 2010 under a BSD license. It was donated to Apache software foundation in 2013, and now Apache Spark has become a top level Apache project from Feb-2014.
Spark 由 UC(University of California) Berkeley AMP lab (加州大学伯克利分校的AMP实验室) 开发。
Features of Apache Spark
Apache Spark has following features.
- Speed − Spark helps to run an application in Hadoop cluster, up to 100 times faster in memory, and 10 times faster when running on disk. This is possible by reducing number of read/write operations to disk. It stores the intermediate processing data in memory.
- Supports multiple languages − Spark provides built-in APIs in Java, Scala, or Python. Therefore, you can write applications in different languages. Spark comes up with 80 high-level operators for interactive querying.
- Advanced Analytics − Spark not only supports ‘Map’ and ‘reduce’. It also supports SQL queries, Streaming data, Machine learning (ML), and Graph algorithms.
Spark Built on Hadoop
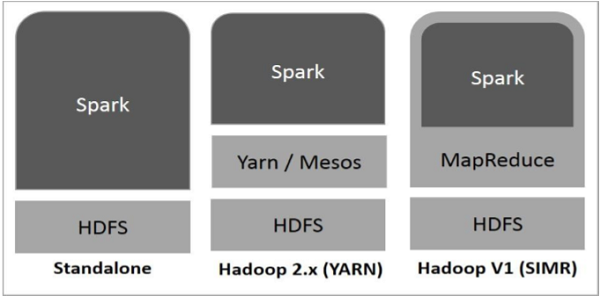
The following diagram shows three ways of how Spark can be built with Hadoop components.
There are three ways of Spark deployment as explained below.
- Standalone − Spark Standalone deployment means Spark occupies the place on top of HDFS(Hadoop Distributed File System) and space is allocated for HDFS, explicitly. Here, Spark and MapReduce will run side by side to cover all spark jobs on cluster.
- Hadoop Yarn − Hadoop Yarn deployment means, simply, spark runs on Yarn without any pre-installation or root access required. It helps to integrate Spark into Hadoop ecosystem or Hadoop stack. It allows other components to run on top of stack.
- Spark in MapReduce (SIMR) − Spark in MapReduce is used to launch spark job in addition to standalone deployment. With SIMR, user can start Spark and uses its shell without any administrative access.
Components of Spark
The following illustration depicts the different components of Spark.
Apache Spark Core
Spark Core is the underlying general execution engine for spark platform that all other functionality is built upon. It provides In-Memory computing and referencing datasets in external storage systems.
包含Spark的基本功能;尤其是定义RDD的API、操作以及这两者上的动作。
Spark SQL
Spark SQL is a component on top of Spark Core that introduces a new data abstraction called SchemaRDD, which provides support for structured and semi-structured data.
Spark Streaming
Spark Streaming leverages Spark Core's fast scheduling capability to perform streaming analytics. It ingests data in mini-batches and performs RDD (Resilient Distributed Datasets) transformations on those mini-batches of data.
MLlib (Machine Learning Library)
MLlib is a distributed machine learning framework above Spark because of the distributed memory-based Spark architecture. It is, according to benchmarks, done by the MLlib developers against the Alternating Least Squares (ALS) implementations. Spark MLlib is nine times as fast as the Hadoop disk-based version of Apache Mahout (before Mahout gained a Spark interface).
一个常用机器学习算法库,算法被实现为对 RDD 的 Spark 操作。
GraphX
GraphX is a distributed graph-processing framework on top of Spark. It provides an API for expressing graph computation that can model the user-defined graphs by using Pregel abstraction API. It also provides an optimized runtime for this abstraction.
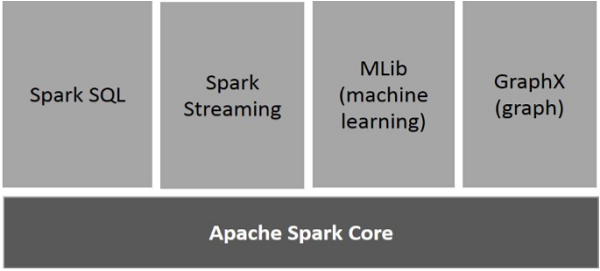
Spark 库本身包含很多应用元素,这些元素可以用到大部分大数据应用中,其中包括对大数据进行类似 SQL 查询的支持,机器学习和图算法,甚至对实时流数据的支持。
参考资料
Apache Spark : Introduction的更多相关文章
- CS100.1x Introduction to Big Data with Apache Spark
CS100.1x简介 这门课主要讲数据科学,也就是data science以及怎么用Apache Spark去分析大数据. Course Software Setup 这门课主要介绍如何编写和调试Py ...
- Apache Spark源码走读之5 -- DStream处理的容错性分析
欢迎转载,转载请注明出处,徽沪一郎,谢谢. 在流数据的处理过程中,为了保证处理结果的可信度(不能多算,也不能漏算),需要做到对所有的输入数据有且仅有一次处理.在Spark Streaming的处理机制 ...
- Spark(1) - Getting Started with Apache Spark
Introduction Apache Spark is a general-purpose cluster computing system to process big data workload ...
- Introducing Apache Spark Datasets(中英双语)
文章标题 Introducing Apache Spark Datasets 作者介绍 Michael Armbrust, Wenchen Fan, Reynold Xin and Matei Zah ...
- .net 开发者尝试Apache Spark™
本文编译自一篇msdn magazine的文章,原文标题和链接为: Test Run - Introduction to Spark for .NET Developers https://msdn. ...
- Apache Spark大数据分析入门(一)
摘要:Apache Spark的出现让普通人也具备了大数据及实时数据分析能力.鉴于此,本文通过动手实战操作演示带领大家快速地入门学习Spark.本文是Apache Spark入门系列教程(共四部分)的 ...
- Apache Spark简单介绍、安装及使用
Apache Spark简介 Apache Spark是一个高速的通用型计算引擎,用来实现分布式的大规模数据的处理任务. 分布式的处理方式可以使以前单台计算机面对大规模数据时处理不了的情况成为可能. ...
- 关于Apache Spark
Apache Spark : https://www.oschina.net/p/spark-project
- Apache Spark源码剖析
Apache Spark源码剖析(全面系统介绍Spark源码,提供分析源码的实用技巧和合理的阅读顺序,充分了解Spark的设计思想和运行机理) 许鹏 著 ISBN 978-7-121-25420- ...
随机推荐
- UVM序列篇之二:sequence和item(上)
无论是自驾item,穿过sequencer交通站,通往终点driver,还是坐上sequence的大巴,一路沿途观光,最终跟随导游停靠到风景点driver,在介绍如何驾驶item和sequence,遵 ...
- 多功能电子通讯录(涉及到了双向链表的使用,Linux文件编程等等)
readme.txt //作为一个程序员,我们咋么能不写用户手册呢!MSP的我觉得用户体验是王道,苹果手机的用户体验的确不错!不过WP加油!我去,扯远了!赶紧看我的程序吧! 歡迎使用多功能電子通訊錄 ...
- 【转】一点一点学ASP.NET之基础概念——HttpModule
概述 HttpHandler是一个HTTP请求的真正处理中心,也正是在这个HttpHandler容器中,ASP.NET Framework才真正地对客户端请求的服务器页面做出编译和执行,并将处理过后的 ...
- Eclipse常用快捷键之代码编辑篇
Eclipse是Java开发常用的IDE工具,熟练使用快捷键可以提高开发效率,使得编码工作事半功倍,下面介绍几种常用的代码编辑和补全工具 重命名快捷键:Alt+Shift+R 可用于类名,方法名,属性 ...
- PL/SQL之存储过程和触发器实例
1.Oracle存储过程实例 /*不带任何参数存储过程(输出系统日期)*/ CREATE OR REPLACE PROCEDURE output_date IS BEGIN DBMS_OUTPUT.P ...
- <深入理解JavaScript>学习笔记(2)_揭秘命名函数表达式
写在前面的话 注:本文是拜读了 深入理解JavaScript 之后深有感悟,故做次笔记方便之后查看. 感觉这章的内容有点深奥....略难懂啊. 先坐下笔记,加深一下印象吧. 我主要记一下自己感觉有用的 ...
- K:双栈法求算术表达式的值
相关介绍: 该算法用于求得一个字符串形式的表达式的结果.例如,计算1+1+(3-1)*3-(21-20)/2所得的表达式的值,该算法利用了两个栈来计算表达式的值,为此,称为双栈法,其实现简单且易于理 ...
- Java与C++区别:重载(Overloading)
Java中一个类的函数重载可以在本类中的函数和来自父类中的函数之间进行,而C++类中的函数重载只能是本类中的(即不包括来自父类的函数),这是他们一个非常重要的区别.在其他方面的要求都是一致的,即要求函 ...
- thinkphp I() 方法
I() 方法用于获取前台提交的表单的value值. <form id="complai_form" method="post" action=" ...
- ADO.NET对象模型之间的关系
ADO.Net支持两种访问数据的模型:无连接模式和连接模式 无连接模式将数据下载到客户机器上,并在客户机上将数据封装到内存中, 可以向访问本地关系数据库一样访问内存中的数据(例如DataSet), 连 ...