
Hadoop源码篇---解读Mapprer源码Input输入
一。前述
上次分析了客户端源码,这次分析mapper源码让大家对hadoop框架有更清晰的认识
二。代码
自定义代码如下:
public class MyMapper extends  Mapper<Object, Text, Text, IntWritable>{

       private final static IntWritable one = new IntWritable(1);

       private Text word = new Text();

       public void map(Object key, Text value, Context context) throws IOException, InterruptedException {

         StringTokenizer itr = new StringTokenizer(value.toString());

         while (itr.hasMoreTokens()) {

           word.set(itr.nextToken());

           context.write(word, one);

         }

       }
继承Mapper源码如下:
public class Mapper<KEYIN, VALUEIN, KEYOUT, VALUEOUT> {

  /**

   * The <code>Context</code> passed on to the {@link Mapper} implementations.

   */

  public abstract class Context

    implements MapContext<KEYIN,VALUEIN,KEYOUT,VALUEOUT> {

  }

  /**

   * Called once at the beginning of the task.

   */

  protected void setup(Context context

                       ) throws IOException, InterruptedException {

    // NOTHING

  }

  /**

   * Called once for each key/value pair in the input split. Most applications

   * should override this, but the default is the identity function.

   */

  @SuppressWarnings("unchecked")

  protected void map(KEYIN key, VALUEIN value,

                     Context context) throws IOException, InterruptedException {

    context.write((KEYOUT) key, (VALUEOUT) value);

  }

  /**

   * Called once at the end of the task.

   */

  protected void cleanup(Context context

                         ) throws IOException, InterruptedException {

    // NOTHING

  }

  /**

   * Expert users can override this method for more complete control over the

   * execution of the Mapper.

   * @param context

   * @throws IOException

   */

  public void run(Context context) throws IOException, InterruptedException {

    setup(context);

    try {

      while (context.nextKeyValue()) {

        map(context.getCurrentKey(), context.getCurrentValue(), context);

      }

    } finally {

      cleanup(context);

    }

  }

}
解析:我们重新了map方法,所以传进run方法中才能不断执行。
MapperTask源码解析:
Container封装了一个脚本命令,通过远程调用启动Yarnchild,如果是MapTask任务,然后把反射城MapTask的对象,启动mapTask的run方法
Maptask中的run方法:
public void run(final JobConf job, final TaskUmbilicalProtocol umbilical)

    throws IOException, ClassNotFoundException, InterruptedException {

    this.umbilical = umbilical;

    if (isMapTask()) {

      // If there are no reducers then there won't be any sort. Hence the map

      // phase will govern the entire attempt's progress.

      if (conf.getNumReduceTasks() == 0) {//假如没有reduce阶段

        mapPhase = getProgress().addPhase("map", 1.0f);

      } else {

        // If there are reducers then the entire attempt's progress will be

        // split between the map phase (67%) and the sort phase (33%).

        mapPhase = getProgress().addPhase("map", 0.667f);

        sortPhase  = getProgress().addPhase("sort", 0.333f);//假如有reduce阶段需要排序,说明没有reduce任务则不需要排序

      }

    }
 if (useNewApi) {
      runNewMapper(job, splitMetaInfo, umbilical, reporter);//用新api
    } else {
      runOldMapper(job, splitMetaInfo, umbilical, reporter);
    }
    done(umbilical, reporter);
  }
runNewMapper解析:
private <INKEY,INVALUE,OUTKEY,OUTVALUE>
  void runNewMapper(final JobConf job,
                    final TaskSplitIndex splitIndex,
                    final TaskUmbilicalProtocol umbilical,
                    TaskReporter reporter
                    ) throws IOException, ClassNotFoundException,
                             InterruptedException {
    // make a task context so we can get the classes
    org.apache.hadoop.mapreduce.TaskAttemptContext taskContext =
      new org.apache.hadoop.mapreduce.task.TaskAttemptContextImpl(job, //我们自定义的job
                                                                  getTaskID(),
                                                                  reporter);//创建上下文
    // make a mapper
    org.apache.hadoop.mapreduce.Mapper<INKEY,INVALUE,OUTKEY,OUTVALUE> mapper =
      (org.apache.hadoop.mapreduce.Mapper<INKEY,INVALUE,OUTKEY,OUTVALUE>)
        ReflectionUtils.newInstance(taskContext.getMapperClass(), job);//反射把自定的Mapper类反射出来  对应解析1
    // make the input format
    org.apache.hadoop.mapreduce.InputFormat<INKEY,INVALUE> inputFormat =
      (org.apache.hadoop.mapreduce.InputFormat<INKEY,INVALUE>)
        ReflectionUtils.newInstance(taskContext.getInputFormatClass(), job);//反射把自定的InputFormat类反射出来 对应解析2
    // rebuild the input split
    org.apache.hadoop.mapreduce.InputSplit split = null;
    split = getSplitDetails(new Path(splitIndex.getSplitLocation()),//每一个切片条目对应的是一个MapTask 每个切片中对应的4个东西(文件归属,偏移量,长度,位置信息)
        splitIndex.getStartOffset());
    LOG.info("Processing split: " + split);

    org.apache.hadoop.mapreduce.RecordReader<INKEY,INVALUE> input =
      new NewTrackingRecordReader<INKEY,INVALUE>//对应解析3
        (split, inputFormat, reporter, taskContext);//上面准备的输入格式化和切片为输入准备,拿到流,怎么读按文本方式读,行级

    job.setBoolean(JobContext.SKIP_RECORDS, isSkipping());
    org.apache.hadoop.mapreduce.RecordWriter output = null;

    // get an output object
    if (job.getNumReduceTasks() == 0) {
      output =
        new NewDirectOutputCollector(taskContext, job, umbilical, reporter);
    } else {
      output = new NewOutputCollector(taskContext, job, umbilical, reporter);
    }

    org.apache.hadoop.mapreduce.MapContext<INKEY, INVALUE, OUTKEY, OUTVALUE>
    mapContext =
      new MapContextImpl<INKEY, INVALUE, OUTKEY, OUTVALUE>(job, getTaskID(), //对应解析4
          input, output, //mapContext即上下文对象封装了输入输出,所以可通过上下文拿到值 则可以得出Mapper类中的content的getCurrentyKey实际上是取得输入对象的LineRecorder
          committer,
          reporter, split);

    org.apache.hadoop.mapreduce.Mapper<INKEY,INVALUE,OUTKEY,OUTVALUE>.Context
        mapperContext =
          new WrappedMapper<INKEY, INVALUE, OUTKEY, OUTVALUE>().getMapContext(
              mapContext);
 try {

      input.initialize(split, mapperContext);//输入 对应解析5

      mapper.run(mapperContext);//run  对应解析6

      mapPhase.complete();

      setPhase(TaskStatus.Phase.SORT);

      statusUpdate(umbilical);

      input.close();

      input = null;

      output.close(mapperContext);//输出

      output = null;

    } finally {

      closeQuietly(input);

      closeQuietly(output, mapperContext);

    }

  }
解析1源码
 @SuppressWarnings("unchecked")

  public Class<? extends Mapper<?,?,?,?>> getMapperClass()

     throws ClassNotFoundException {

    return (Class<? extends Mapper<?,?,?,?>>)

      conf.getClass(MAP_CLASS_ATTR, Mapper.class);//用户配置则从配置中取,如果没设置取默认。

  }
解析2源码
 public Class<? extends InputFormat<?,?>> getInputFormatClass()

     throws ClassNotFoundException {

    return (Class<? extends InputFormat<?,?>>)

      conf.getClass(INPUT_FORMAT_CLASS_ATTR, TextInputFormat.class);//如果用户设置取用户的,没有则取TextinputfRrmat!!!

  }
结论:框架默认使用的是TextInputFormat!!!
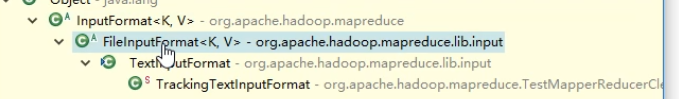
补充:继承关系InputFormat>FileInputformat>textInputformat
解析3源码:
static class NewTrackingRecordReader<K,V>

    extends org.apache.hadoop.mapreduce.RecordReader<K,V> {

    private final org.apache.hadoop.mapreduce.RecordReader<K,V> real;

    private final org.apache.hadoop.mapreduce.Counter inputRecordCounter;

    private final org.apache.hadoop.mapreduce.Counter fileInputByteCounter;

    private final TaskReporter reporter;

    private final List<Statistics> fsStats;

    NewTrackingRecordReader(org.apache.hadoop.mapreduce.InputSplit split,

        org.apache.hadoop.mapreduce.InputFormat<K, V> inputFormat,

        TaskReporter reporter,

        org.apache.hadoop.mapreduce.TaskAttemptContext taskContext)

        throws InterruptedException, IOException {

      this.reporter = reporter;

      this.inputRecordCounter = reporter

          .getCounter(TaskCounter.MAP_INPUT_RECORDS);

      this.fileInputByteCounter = reporter

          .getCounter(FileInputFormatCounter.BYTES_READ);

      List <Statistics> matchedStats = null;

      if (split instanceof org.apache.hadoop.mapreduce.lib.input.FileSplit) {

        matchedStats = getFsStatistics(((org.apache.hadoop.mapreduce.lib.input.FileSplit) split)

            .getPath(), taskContext.getConfiguration());

      }

      fsStats = matchedStats;

      long bytesInPrev = getInputBytes(fsStats);

      this.real = inputFormat.createRecordReader(split, taskContext);解析3.1 源码 real来源Linerecordere

      long bytesInCurr = getInputBytes(fsStats);

      fileInputByteCounter.increment(bytesInCurr - bytesInPrev);

    }
解析3.1 源码
public class TextInputFormat extends FileInputFormat<LongWritable, Text> {

  @Override

  public RecordReader<LongWritable, Text>

    createRecordReader(InputSplit split,

                       TaskAttemptContext context) {

    String delimiter = context.getConfiguration().get(

        "textinputformat.record.delimiter");

    byte[] recordDelimiterBytes = null;

    if (null != delimiter)

      recordDelimiterBytes = delimiter.getBytes(Charsets.UTF_8);

    return new LineRecordReader(recordDelimiterBytes);//返回Linerorder,行读取器

  }
解析4源码:
 public MapContextImpl(Configuration conf, TaskAttemptID taskid,

                        RecordReader<KEYIN,VALUEIN> reader,//reader即输入对象

                        RecordWriter<KEYOUT,VALUEOUT> writer,

                        OutputCommitter committer,

                        StatusReporter reporter,

                        InputSplit split) {

    super(conf, taskid, writer, committer, reporter);

    this.reader = reader;

    this.split = split;

  }
 /**
   * Get the input split for this map.
   */
  public InputSplit getInputSplit() {
    return split;
  }

  @Override
  public KEYIN getCurrentKey() throws IOException, InterruptedException {
    return reader.getCurrentKey();//调用输入的input 包含一个Linerecorder对象
  }

  @Override
  public VALUEIN getCurrentValue() throws IOException, InterruptedException {
    return reader.getCurrentValue();
  }

  @Override
  public boolean nextKeyValue() throws IOException, InterruptedException {
    return reader.nextKeyValue();
  }
解析5源码:
public void initialize(InputSplit genericSplit,

                         TaskAttemptContext context) throws IOException {

    FileSplit split = (FileSplit) genericSplit;

    Configuration job = context.getConfiguration();

    this.maxLineLength = job.getInt(MAX_LINE_LENGTH, Integer.MAX_VALUE);

    start = split.getStart();//切片的起始位置

    end = start + split.getLength();//切片的结束位置

    final Path file = split.getPath();

    // open the file and seek to the start of the split

    final FileSystem fs = file.getFileSystem(job);

    fileIn = fs.open(file);

    CompressionCodec codec = new CompressionCodecFactory(job).getCodec(file);

    if (null!=codec) {

      isCompressedInput = true;

      decompressor = CodecPool.getDecompressor(codec);

      if (codec instanceof SplittableCompressionCodec) {

        final SplitCompressionInputStream cIn =

          ((SplittableCompressionCodec)codec).createInputStream(

            fileIn, decompressor, start, end,

            SplittableCompressionCodec.READ_MODE.BYBLOCK);

        in = new CompressedSplitLineReader(cIn, job,

            this.recordDelimiterBytes);

        start = cIn.getAdjustedStart();

        end = cIn.getAdjustedEnd();

        filePosition = cIn;

      } else {

        in = new SplitLineReader(codec.createInputStream(fileIn,

            decompressor), job, this.recordDelimiterBytes);

        filePosition = fileIn;

      }

    } else {

      fileIn.seek(start);//很多mapper 去读对应的切片数量

      in = new UncompressedSplitLineReader(

          fileIn, job, this.recordDelimiterBytes, split.getLength());

      filePosition = fileIn;

    }

    // If this is not the first split, we always throw away first record

    // because we always (except the last split) read one extra line in

    // next() method.

    if (start != 0) {//除了第一个切片

      start += in.readLine(new Text(), 0, maxBytesToConsume(start));//匿名写法 输入初始化的时候 对于非第一个切片 读一行放空,算出长度,然后更新起始位置为第二行  这样每一个切片处理完的时候再多处理一行,这样就能保证还原。!!!

    }

    this.pos = start;

  }
解析6实际上调用的就是Mapper中的run方法。
public void run(Context context) throws IOException, InterruptedException {

    setup(context);

    try {

      while (context.nextKeyValue()) {/解析6.1

        map(context.getCurrentKey(), context.getCurrentValue(), context);

      }

    } finally {

      cleanup(context);

    }

  }

}
解析6.1追踪后实际上调用的是LineRewcorder中的NextKeyValue方法
public boolean nextKeyValue() throws IOException {

    if (key == null) {

      key = new LongWritable();//Key中要放置偏移量

    }

    key.set(pos);//偏移量

    if (value == null) {

      value = new Text();//默认

    }

    int newSize = 0;

    // We always read one extra line, which lies outside the upper

    // split limit i.e. (end - 1)

    while (getFilePosition() <= end || in.needAdditionalRecordAfterSplit()) {

      if (pos == 0) {

        newSize = skipUtfByteOrderMark();

      } else {

        newSize = in.readLine(value, maxLineLength, maxBytesToConsume(pos));//读到真的值了

        pos += newSize;

      }

      if ((newSize == 0) || (newSize < maxLineLength)) {

        break;

      }

      // line too long. try again

      LOG.info("Skipped line of size " + newSize + " at pos " +

               (pos - newSize));

    }

    if (newSize == 0) {

      key = null;

      value = null;

      return false;

    } else {

      return true;

    }

  }
@Override//由nextkeyValue更新值所以直接取值这块  这种取值方式叫做引用传递!!!
  public LongWritable getCurrentKey() {
    return key;
  }

  @Override
  public Text getCurrentValue() {
    return value;
  }
持续更新中。。。。,欢迎大家关注我的公众号LHWorld.
Hadoop源码篇---解读Mapprer源码Input输入的更多相关文章
- Hadoop源码篇---解读Mapprer源码outPut输出
一.前述 上次讲完MapReduce的输入后,这次开始讲MapReduce的输出.注意MapReduce的原语很重要: "相同"的key为一组,调用一次reduce方法,方法内迭代 ...
- 这篇说的是Unity Input 输入控制器
关于Unity3D是什么.我就不多做解释了.由于工作原因,该系列原创教程不定期更新.每月必然有更新.谢谢各位 Unity Input---输入控制管理器: Edit->Project Setti ...
- 源码篇:SDWebImage
攀登,一步一个脚印,方能知其乐 源码篇:SDWebImage 源码来源:https://github.com/rs/SDWebImage 版本: 3.7 SDWebImage是一个开源的第三方库,它提 ...
- MyBatis 源码篇-MyBatis-Spring 剖析
本章通过分析 mybatis-spring-x.x.x.jar Jar 包中的源码,了解 MyBatis 是如何与 Spring 进行集成的. Spring 配置文件 MyBatis 与 Spring ...
- MyBatis 源码篇-Transaction
本章简单介绍一下 MyBatis 的事务模块,这块内容比较简单,主要为后面介绍 mybatis-spring-1.**.jar(MyBatis 与 Spring 集成)中的事务模块做准备. 类图结构 ...
- MyBatis 源码篇-DataSource
本章介绍 MyBatis 提供的数据源模块,为后面与 Spring 集成做铺垫,从以下三点出发: 描述 MyBatis 数据源模块的类图结构: MyBatis 是如何集成第三方数据源组件的: Pool ...
- MyBatis 源码篇-插件模块
本章主要描述 MyBatis 插件模块的原理,从以下两点出发: MyBatis 是如何加载插件配置的? MyBatis 是如何实现用户使用自定义拦截器对 SQL 语句执行过程中的某一点进行拦截的? 示 ...
- MyBatis 源码篇-日志模块2
上一章的案例,配置日志级别为 debug,执行一个简单的查询操作,会将 JDBC 操作打印出来.本章通过 MyBatis 日志部分源码分析它是如何实现日志打印的. 在 MyBatis 的日志模块中有一 ...
- MyBatis 源码篇-日志模块1
在 Java 开发中常用的日志框架有 Log4j.Log4j2.Apache Common Log.java.util.logging.slf4j 等,这些日志框架对外提供的接口各不相同.本章详细描述 ...
随机推荐
- 如何在Raspberry Pi 3B中安装Windows 10 IoT Core
Windows 10 IoT Core简介 Windows 10 IoT是微软专门为物联网生态打造的操作系统,Windows 10 IoT Core则是Windows 10 IoT 操作系统的核心版本 ...
- 大数据学习系列之六 ----- Hadoop+Spark环境搭建
引言 在上一篇中 大数据学习系列之五 ----- Hive整合HBase图文详解 : http://www.panchengming.com/2017/12/18/pancm62/ 中使用Hive整合 ...
- 》》HTML5 移动页面自适应手机屏幕四类方法
1.使用meta标签:viewport H5移动端页面自适应普遍使用的方法,理论上讲使用这个标签是可以适应所有尺寸的屏幕的,但是各设备对该标签的解释方式及支持程度不同造成了不能兼容所有浏览器或系统. ...
- poj 1797 Heavy Transportation(最大生成树)
poj 1797 Heavy Transportation Description Background Hugo Heavy is happy. After the breakdown of the ...
- HDU_1698 Just a Hook(线段树+lazy标记)
pid=1698">题目请点我 题解: 接触到的第一到区间更新,须要用到lazy标记.典型的区间着色问题. lazy标记详情请參考博客:http://ju.outofmemory.cn ...
- zookeeper web ui-->node-zk-browser安装
眼下公司正在使用zookeeper做配置管理和其它工作,在网上找几个zookeeper管理工具,都不尽人意,要么功能不够强大,要么不能友好的浏览zk树形结构.我的想法是zk管理工具,应该有一个树形结构 ...
- ZOJ 3890 Wumpus
Wumpus Time Limit: 2 Seconds Memory Limit: 65536 KB One day Leon finds a very classic game call ...
- jquery通过数值改变球大小
在业务中遇到一个问题:在页面上显示一个球.且球的大小会应数字的大小而改变. 我们都知道 js是能够画圆(用css样式准备一个圆.假设addClass),但这并非我们想要的. 于是笔者脑洞打开:用样式画 ...
- Iframe简单介绍(一)
Iframe可以用在以下几个场景 1.典型系统结构,左侧是功能树,右侧就是一些常见table或者表单之类的.为了每一个功能,单独分离出来,采用iframe. 2.AJAX上传文件 3.加载别的网站内容 ...
- java集合框架(Collections Framework)
*/ .hljs { display: block; overflow-x: auto; padding: 0.5em; color: #333; background: #f8f8f8; } .hl ...