
Temporal-Difference Learning for Prediction
In Monte Carlo Learning, we've got the estimation of value function:
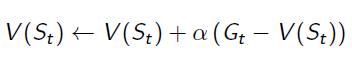
Gt is the episode return from time t, which can be calculated by:
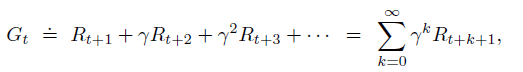
Please recall, Gt can be only calculated at the end of a given episode. This reveals a disadvantage of Monte Carlo Learning: have to wait until the end of episodes.
TD(0) algorithm replace Gt of the equation to the immediate reward and estimated value function of the next state:
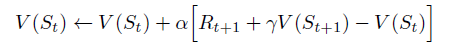
The algorithm updates the Estimated State-Value Function at time t+1, because everything in the equation is determined. This means we will wait until the agent reaching the next state, so that the agent can get the immediate reward Rt+1 and know which state the system will transition to at time t+1.
The equations below are State-Value Function for Dynamic Programming, in which the whole environment is known. Compare to these equations:
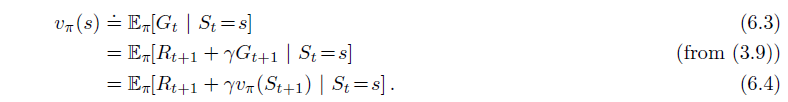
TD algorithm is quite like 6.4 Bellman Equation, but it does not take expectation. Instead, it uses the knowledge till now to estimate how much reward I am going to get from this state. The whole algorithm can be demonstrated as:
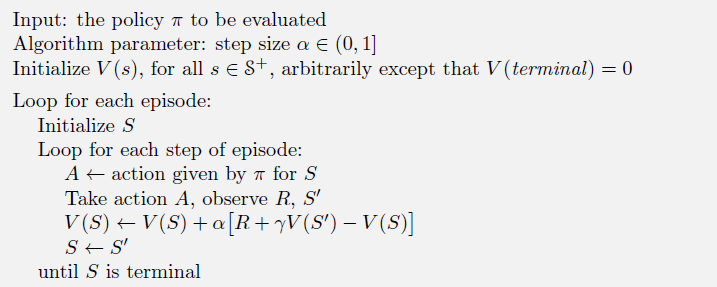
TD Target, TD Error
Bias/ Viriance trade-off
Bootstraping
Temporal-Difference Learning for Prediction的更多相关文章
- 【PPT】 Least squares temporal difference learning
最小二次方时序差分学习 原文地址: https://www.google.com/url?sa=t&rct=j&q=&esrc=s&source=web&cd= ...
- PP: Multi-Horizon Time Series Forecasting with Temporal Attention Learning
Problem: multi-horizon probabilistic forecasting tasks; Propose an end-to-end framework for multi-ho ...
- [Reinforcement Learning] Model-Free Prediction
上篇文章介绍了 Model-based 的通用方法--动态规划,本文内容介绍 Model-Free 情况下 Prediction 问题,即 "Estimate the value funct ...
- [Machine Learning] 机器学习常见算法分类汇总
声明:本篇博文根据http://www.ctocio.com/hotnews/15919.html整理,原作者张萌,尊重原创. 机器学习无疑是当前数据分析领域的一个热点内容.很多人在平时的工作中都或多 ...
- (转) Deep Learning Research Review Week 2: Reinforcement Learning
Deep Learning Research Review Week 2: Reinforcement Learning 转载自: https://adeshpande3.github.io/ad ...
- Awesome Reinforcement Learning
Awesome Reinforcement Learning A curated list of resources dedicated to reinforcement learning. We h ...
- Machine Learning 学习笔记1 - 基本概念以及各分类
What is machine learning? 并没有广泛认可的定义来准确定义机器学习.以下定义均为译文,若以后有时间,将补充原英文...... 定义1.来自Arthur Samuel(上世纪50 ...
- Distributional Reinforcement Learning with Quantile Regression
郑重声明:原文参见标题,如有侵权,请联系作者,将会撤销发布! arXiv:1710.10044v1 [cs.AI] 27 Oct 2017 In AAAI Conference on Artifici ...
- 3. Distributional Reinforcement Learning with Quantile Regression
C51算法理论上用Wasserstein度量衡量两个累积分布函数间的距离证明了价值分布的可行性,但在实际算法中用KL散度对离散支持的概率进行拟合,不能作用于累积分布函数,不能保证Bellman更新收敛 ...
随机推荐
- diff 比较两个文件的不同
1.命令功能 diff 逐行比较文件内容,并输出文件差异. 2.语法格式 diff option file1 file2 diff 选项 文件1 文件2 参数说明 参数 参数说明 ...
- 2019 计蒜之道 复赛 E. 撑起信息安全“保护伞” (贪心,构造,规律)
为了给全球小学员打起信息安全"保护伞",VIPKID 还建立了一套立体化的安全防御体系,7 \times 247×24 小时持续安全监控与应急响应等多项联动,具备业界最高级别的数据 ...
- python基础练习题2
01:python九九乘法表 for i in range(1,10): for j in range(1,i+1): print('{}*{}={}'.format(j,i,i*j),end='\t ...
- 【leetcode】523. Continuous Subarray Sum
题目如下: 解题思路:本题需要用到这么一个数学定理.对于任意三个整数a,b,k(k !=0),如果 a%k = b%k,那么(a-b)%k = 0.利用这个定理,我们可以对数组从头开始进行求和,同时利 ...
- vue中的:is
is string | Object (组件的选项对象) <div id="app"> <span>这是:is的案例</span> <co ...
- HDU 1276 士兵队列训练问题(模拟)
原题代号:HDU 1276 原题链接:http://acm.hdu.edu.cn/showproblem.php?pid=1276 题目原题: 士兵队列训练问题 Time Limit: 2000/10 ...
- 深入理解Spring(一):初识Spring
深入理解Spring(一):初识Spring 一. Spring介绍 Spring是一个开源框架,Spring是于2003 年兴起的一个轻量级的Java 开发框架,由Rod Johnso ...
- idea生成get/set方法
如图:
- SpringBoot学习-第一章
1.SpringBoot入门 开发环境:JDK1.8 开发工具:IDEA2017.3.1 1.简介: Spring Boot让我们的Spring应用变的更轻量化.比如:你可以仅仅依靠一个Java类来运 ...
- Oracle-SQL程序优化案例二
有时候写得不规范的SQL语句真的是占用很多时间 以下是我在工作中发现的规律,如果字段过多的使用函数,尽量不要将这些字段串联在一起做匹配或查询条件,比如红色注释部分,在执行红色部分的时候 这个SQL程序 ...