
Hash Tables and Hash Functions
Reference: Compuer science
Introduction:
This computer science video describes the fundamental principles of the hash table data structure which allows for very fast insertion and retrieval of data. It covers commonly used hash algorithms for numeric and alphanumeric keys and summarises the objectives of a good hash function. Collision resolution is described, including open addressing techniques such as linear and quadratic probing, and closed addressing techniques such as chaining with a linked list.
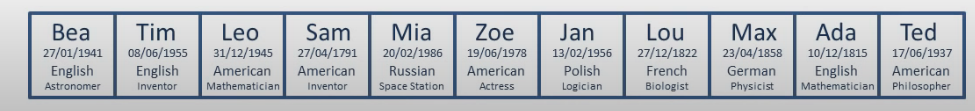
Consider a list:
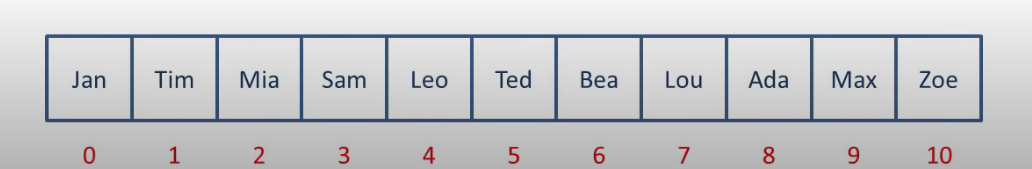
Find Ada
You can use linearly search, which costs the time of O(n)
Or you happend to know the index of ada(8), you can look up the value very quickly.
this costs you the time of O(1)
Can help wondering that what if we encode the name into index would the look-up process become O(1).?
Absolutely!
we can turn the key(i.e. the name) into a number(index) with a hash function.
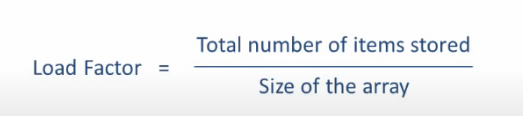
Let's say take each letter of the word get its ascii code,add them up,divided by the length of the array,get the remainder.
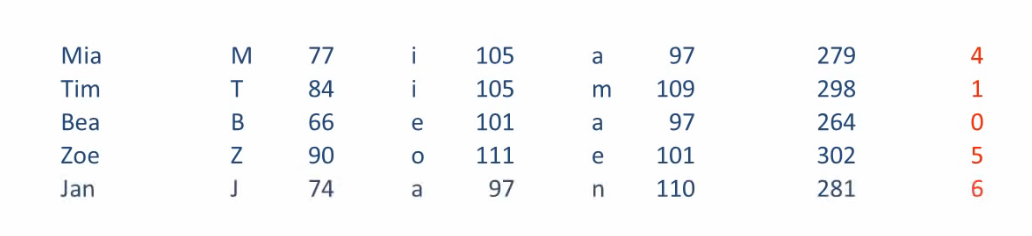
Namely , the hash function here is :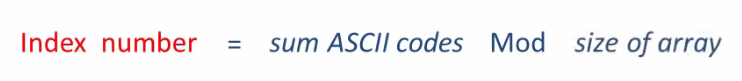
we can serve the properties of a person as the value,the name as key.
So that we can look up the profile of a person by the key(i.e.name)
Notes:
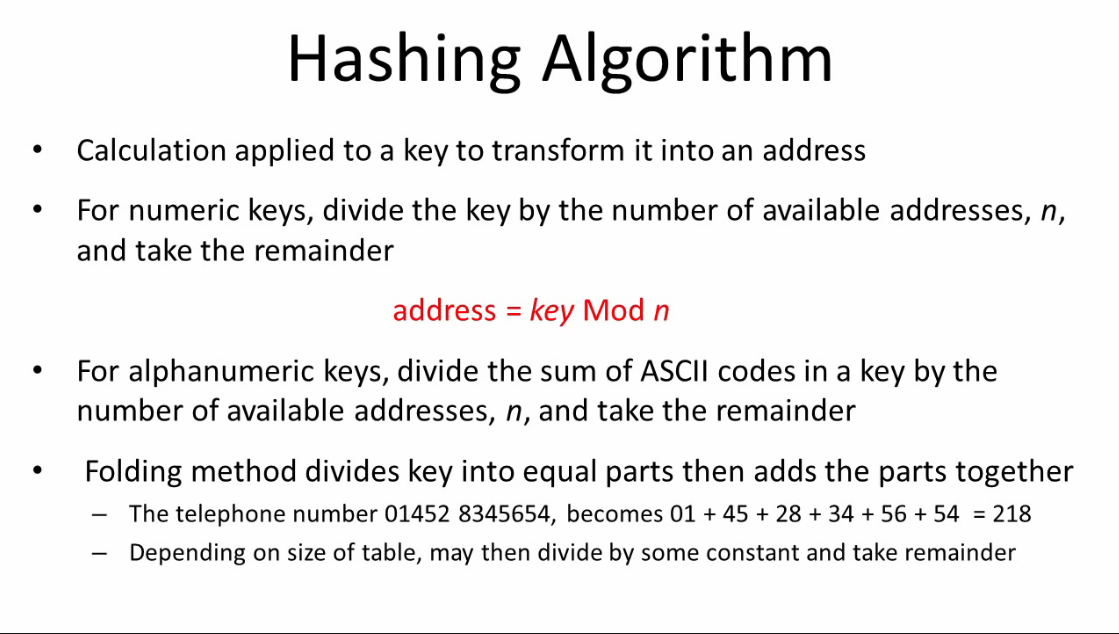
So far you aquire the ability to transform a key into index, you can look up very information by hash table.
Needless to say, that is unrealistic.
Have you ever consider the case that two different key are truned into a same index number?
That is collisions.
Let's look a example.
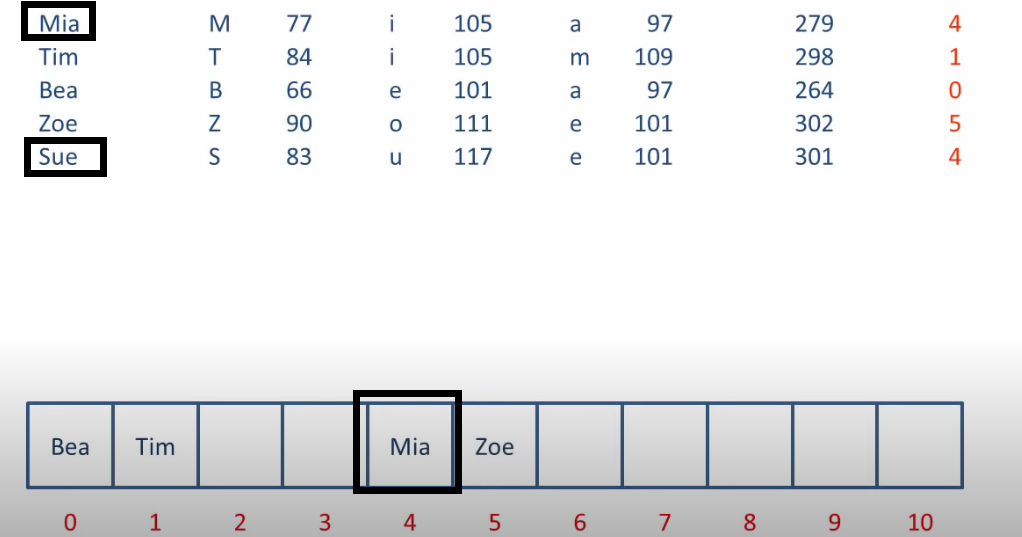
How to solve collisions?
we can put sue into the next place index5 which is empty.
Basically we can put the one that causes collision into the next empty place.
this is linear probing.
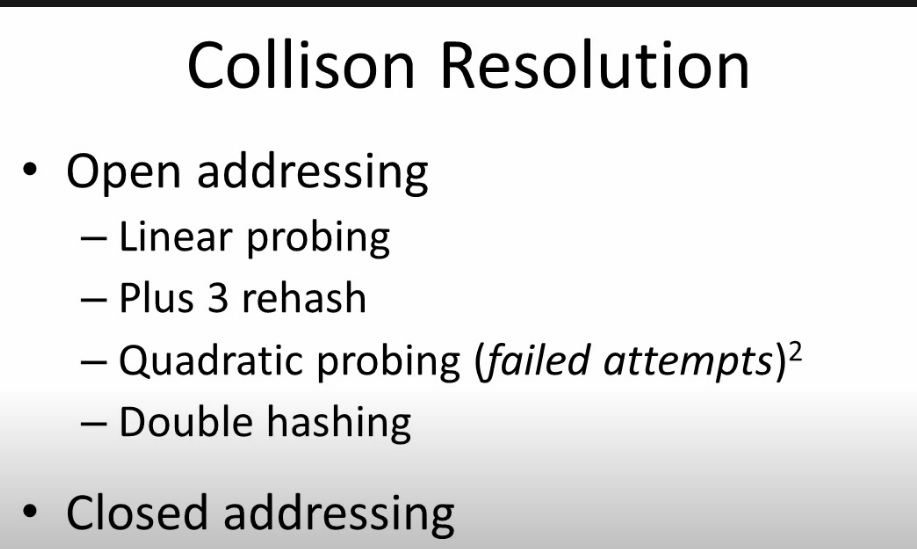
put the element somewhere other than the caculated adress is call open adressing.
because every location is open to every elements.
we can use a varity of techniques to decide where to palce.
If we get to the end of the array still can't find a empty place,
it may cycle around to the start of the array.
As you can image , the indexing process is also involved linear probing.(linear search)
In the worse case scenario, it takes O(n) to store and search a key.
Need to mention:
Another way to deal with collisions is called chaining. (close addressing)
we add a linked list in the collision index.
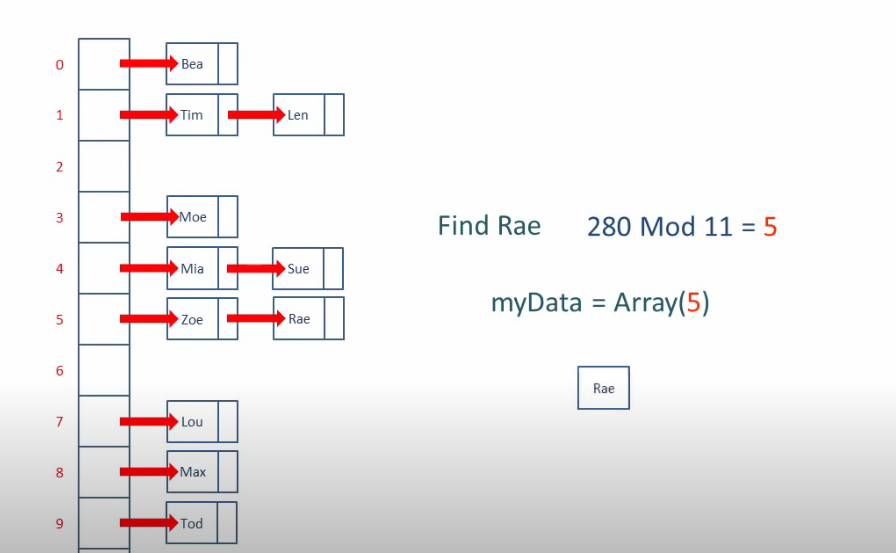
traverse the linked list also takes time.
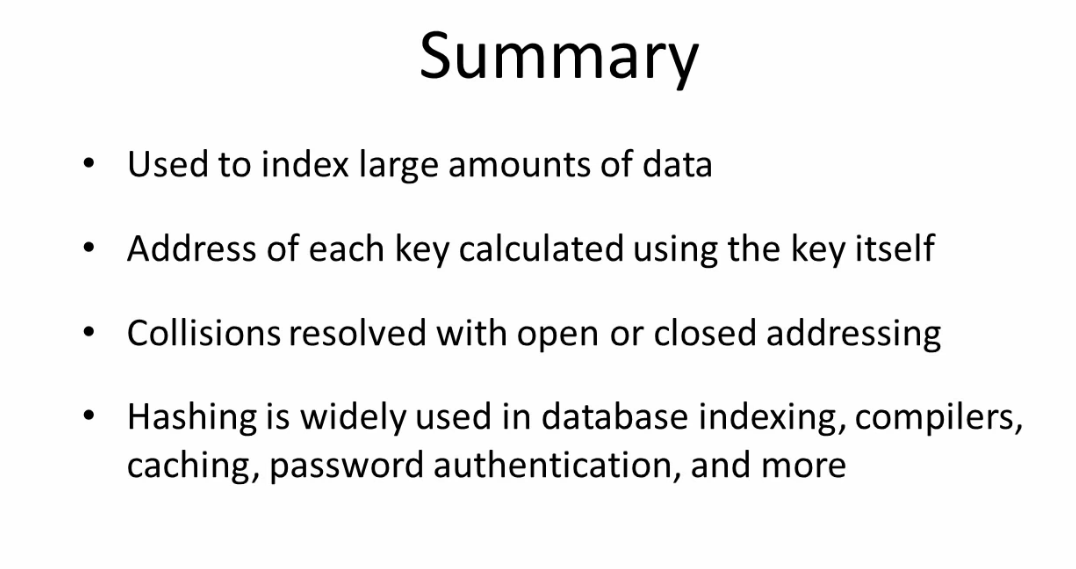
Summary:

Hash Tables and Hash Functions的更多相关文章
- 11 Hash tables
11 Hash tables Many applications require a dynamic set that supports only the dictionary operatio ...
- 查询计划Hash和查询Hash
查询计划hash和查询hash 在SQL Server 2008中引入的围绕执行计划和缓冲的新功能被称为查询计划hash和查询hash.这是使用针对查询或查询计划的算法来生成二进制hash值的二进制对 ...
- 14.4.3 Adaptive Hash Index 自适应hash index
14.4.3 Adaptive Hash Index 自适应hash index 自适应hash index(AHI) 让InnoDB 执行更像内存数据库在系统使用合适的负载组合和足够的内存用于Buf ...
- 14.2.5.6 Adaptive Hash Indexes 自适应Hash Indexes
14.2.5.6 Adaptive Hash Indexes 自适应Hash Indexes adaptive hash index(AHI) 让InnoDB 执行更加像在一个内存数据库里在, 在不牺 ...
- Hash::make与Hash::check
调用方法之前要先去引用: use Illuminate\Support\Facades\Hash; 可以调用 Hash 门面上的 make 方法对存储密码进行哈希: $pwd = Hash::make ...
- 转载:字符串hash总结(hash是一门优雅的暴力!)
转载自:远航休息栈 字符串Hash总结 Hash是什么意思呢?某度翻译告诉我们: hash 英[hæʃ] 美[hæʃ]n. 剁碎的食物; #号; 蔬菜肉丁;vt. 把…弄乱; 切碎; 反复推敲; 搞糟 ...
- cdoj1092-韩爷的梦 (字符串hash)【hash】
http://acm.uestc.edu.cn/#/problem/show/1092 韩爷的梦 Time Limit: 200/100MS (Java/Others) Memory Limi ...
- Hash表及hash算法的分析
Hash表中的一些原理/概念,及根据这些原理/概念: 一. Hash表概念 二. Hash构造函数的方法,及适用范围 三. Hash处理冲突方法,各自特征 四. ...
- Cuckoo Hash和多级Hash的粗浅认识
通过对Cuckoo Hash.多级Hash和BloomFilter的粗浅了解,感觉它们三者存在类似之处,算是近亲(暂且把普通的Hash称作远亲). Cuckoo Hash的思想非常简单,冲突时,重Ha ...
随机推荐
- 一、安装LoadRunner12
今天接到任务最近要进行性能测试(刚开始搞自动化,有要搞性能测试,领导嫌我不忙吧),之前做接口测试用过Jmeter,也可以使用Jmeter做性能测试,但公司要求用LoadRunner,开始学习性能测试和 ...
- mysql 8.0 MGR组复制配置
一.配置组复制的步骤 1.初始化数据目录 2.配置主服务器(primary) 3.配置辅助服务器(secondaries) 4.启动mysql实例 5.安装组复制插件(primary and seco ...
- 【ubuntu-18.04】ubuntu18.04进行Nvidia显卡配置
转自https://blog.csdn.net/qq_37935670/article/details/80377196 2.显卡驱动配置 网上有些攻略非常非常复杂,又要禁用nouveau驱动,又要进 ...
- CI/CD持续集成方案
一,CI/CD流程和持续交付简介 CI(Continuous Integration)持续集成 CD(Continuous Deployment)持续部署 CD(Continuous delive ...
- dataframe的一些用法
pandas中Dataframe的一些用法 pandas读取excel文件 pd.read_excel 前提是安装xlrd库 dataframe,numpy,list之间的互相转换 dataframe ...
- Eureka系列(四) 获取服务Server端具体实现
获取服务 Server端流程 我们先看下面这张图片,这张图片简单描述了下我们EurekaClient在调用EurekaServer 提供的获取服务Http接口,Server端实现接口执行的大致流程 ...
- python监控文件实时批量压缩脚本
# coding:utf-8 from shutil import make_archive import os import time # 指定需要监测的文件夹 image_path = './im ...
- linux中搭建phpmyadmin详细流程
一.phpmyadmin部署流程 1.1介绍 phpMyAdmin是一个以PHP为基础,以Web-Base方式架构在网站主机上的MySQL的数据库管理工具,让管理者可用Web接口管理MySQL数据库. ...
- matplotlib学习日记(二)----图表组成练习
''' 将前面的知识进行练习 plot,scatter,legend等 ''' import matplotlib.pyplot as plt import numpy as np from matp ...
- feig中调用其他微服务接口无反应
1.调用微服务时get请求接口中不能使用@RequestBody注解,不然接口调用无反应.post接口中可以使用@RequestBody注解